
8/ Meta-Transformer – performs unified learning across 12 modalities; supports tasks like fundamental perception (text, image, point cloud, audio, video), application (X-Ray, infrared, hyperspectral, & IMU), and data mining (graph, tabular, & time-series)
@dair_ai
-

Training Dense Retrievers for LLM In-Context Examples
By
–
9/ Retrieve In-Context Example for LLMs – presents a framework to iteratively train dense retrievers to identify high-quality in-context examples for LLMs.
-
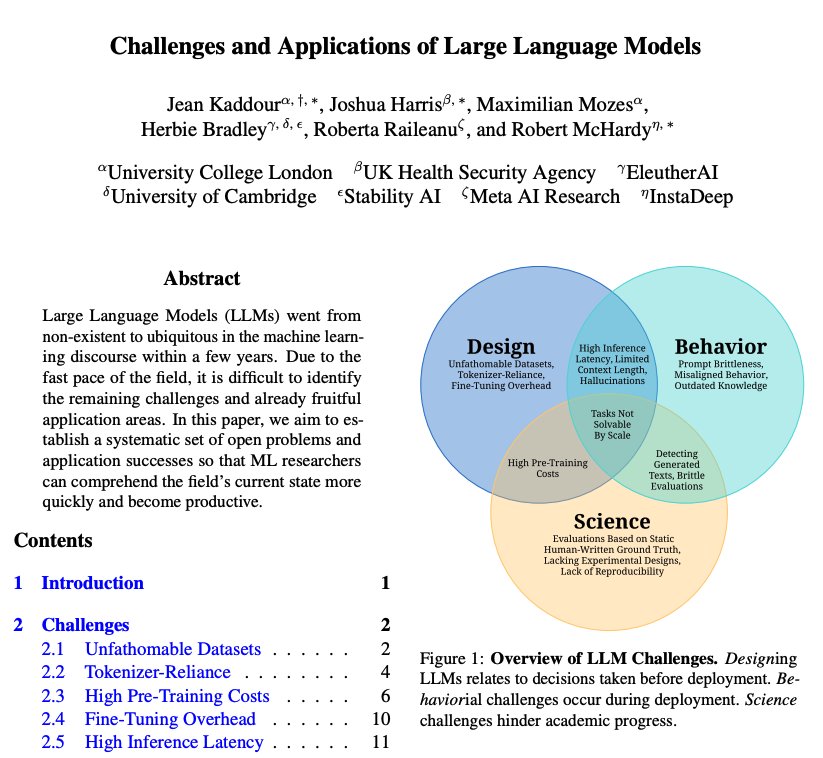
LLM Challenges: Brittleness, Evaluation, and Experimental Design
By
–
6/ Challenges & Application of LLMs – summarizes a comprehensive list of challenges when working with LLMs that range from brittle evaluations to prompt brittleness to a lack of robust experimental designs.
-
Meta releases Llama 2 foundation models from 7B to 70B parameters
By
–
1/ Llama 2 – a collection of pretrained foundational models and fine-tuned chat models ranging in scale from 7B to 70B; Llama 2-Chat is competitive on a range of tasks and shows strong results on safety and helpfulness.
-
Top ML Papers Week: Llama 2, FlashAttention-2, Retentive Networks
By
–
Top ML Papers of the Week (July 17 – July 23): – Llama 2
– FlashAttention-2
– Meta-Transformer
– Retentive Network
– Challenges & Application of LLMs
– How is ChatGPT’s Behavior Changing Over Time?
… -
Multimodal Transformer Foundation Model for Image and Text Generation
By
–
10/ Generative Pretraining in Multimodality – presents a new transformer-based multimodal foundation model to generate images and text in a multimodal context; enables performant multimodal assistants via instruction tuning.
-
AnimateDiff: Motion Module for Personalized Animated Image Generation
By
–
9/ AnimateDiff – appends a motion modeling module to a frozen text-to-image model, which is then trained and used to animate existing personalized models to produce diverse and personalized animated images. https://t.co/L4VOSdideP
— DAIR.AI (@dair_ai) 16 juillet 20239/ AnimateDiff – appends a motion modeling module to a frozen text-to-image model, which is then trained and used to animate existing personalized models to produce diverse and personalized animated images.
-
Training Small Transformers on Arithmetic with Chain-of-Thought
By
–
8/ Teaching Arithmetics to Small Transformers – trains small transformers on chain-of-thought data to improve accuracy and convergence speed and highlights the importance of high-quality instructive data for rapidly eliciting arithmetic capabilities.
-
LLMs as General Pattern Machines: In-Context Learning and Robotics
By
–
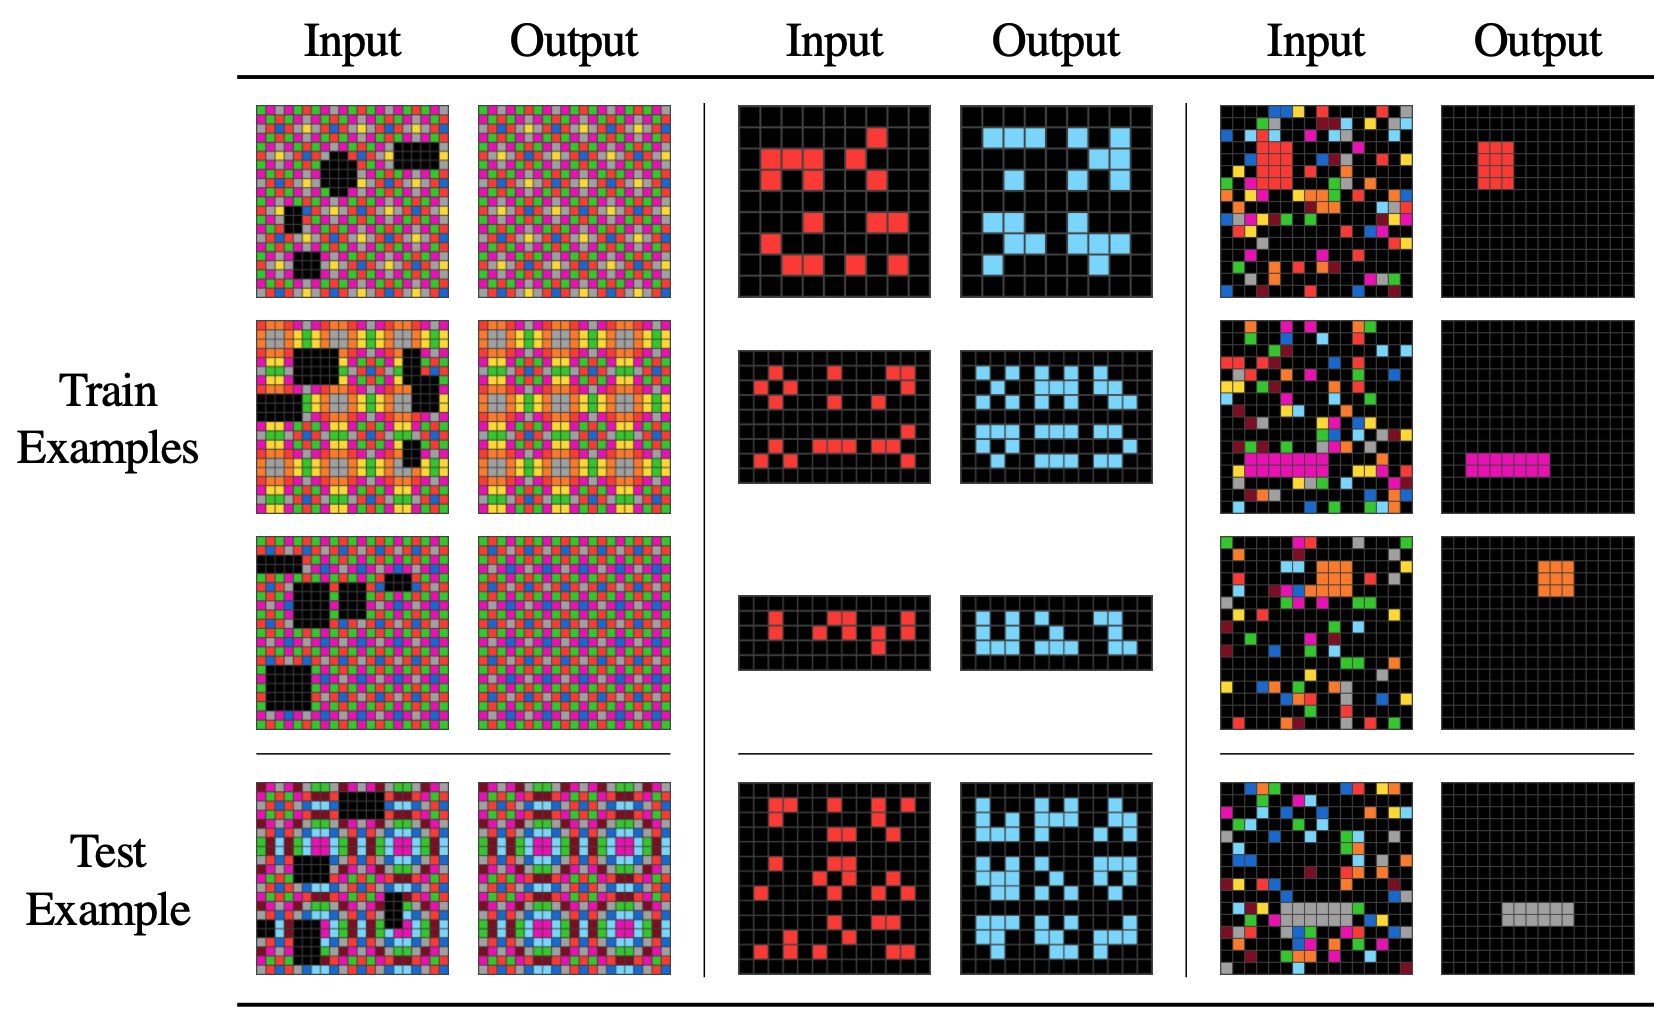
6/ LLMs as General Pattern Machines – shows that without any additional training, LLMs are general sequence modelers, driven by in-context learning; applies 0-shot capabilities to robotics and transfer the pattern among words to actions.
-
HyperDreamBooth: 25x Faster Personalized Text-to-Image Model
By
–
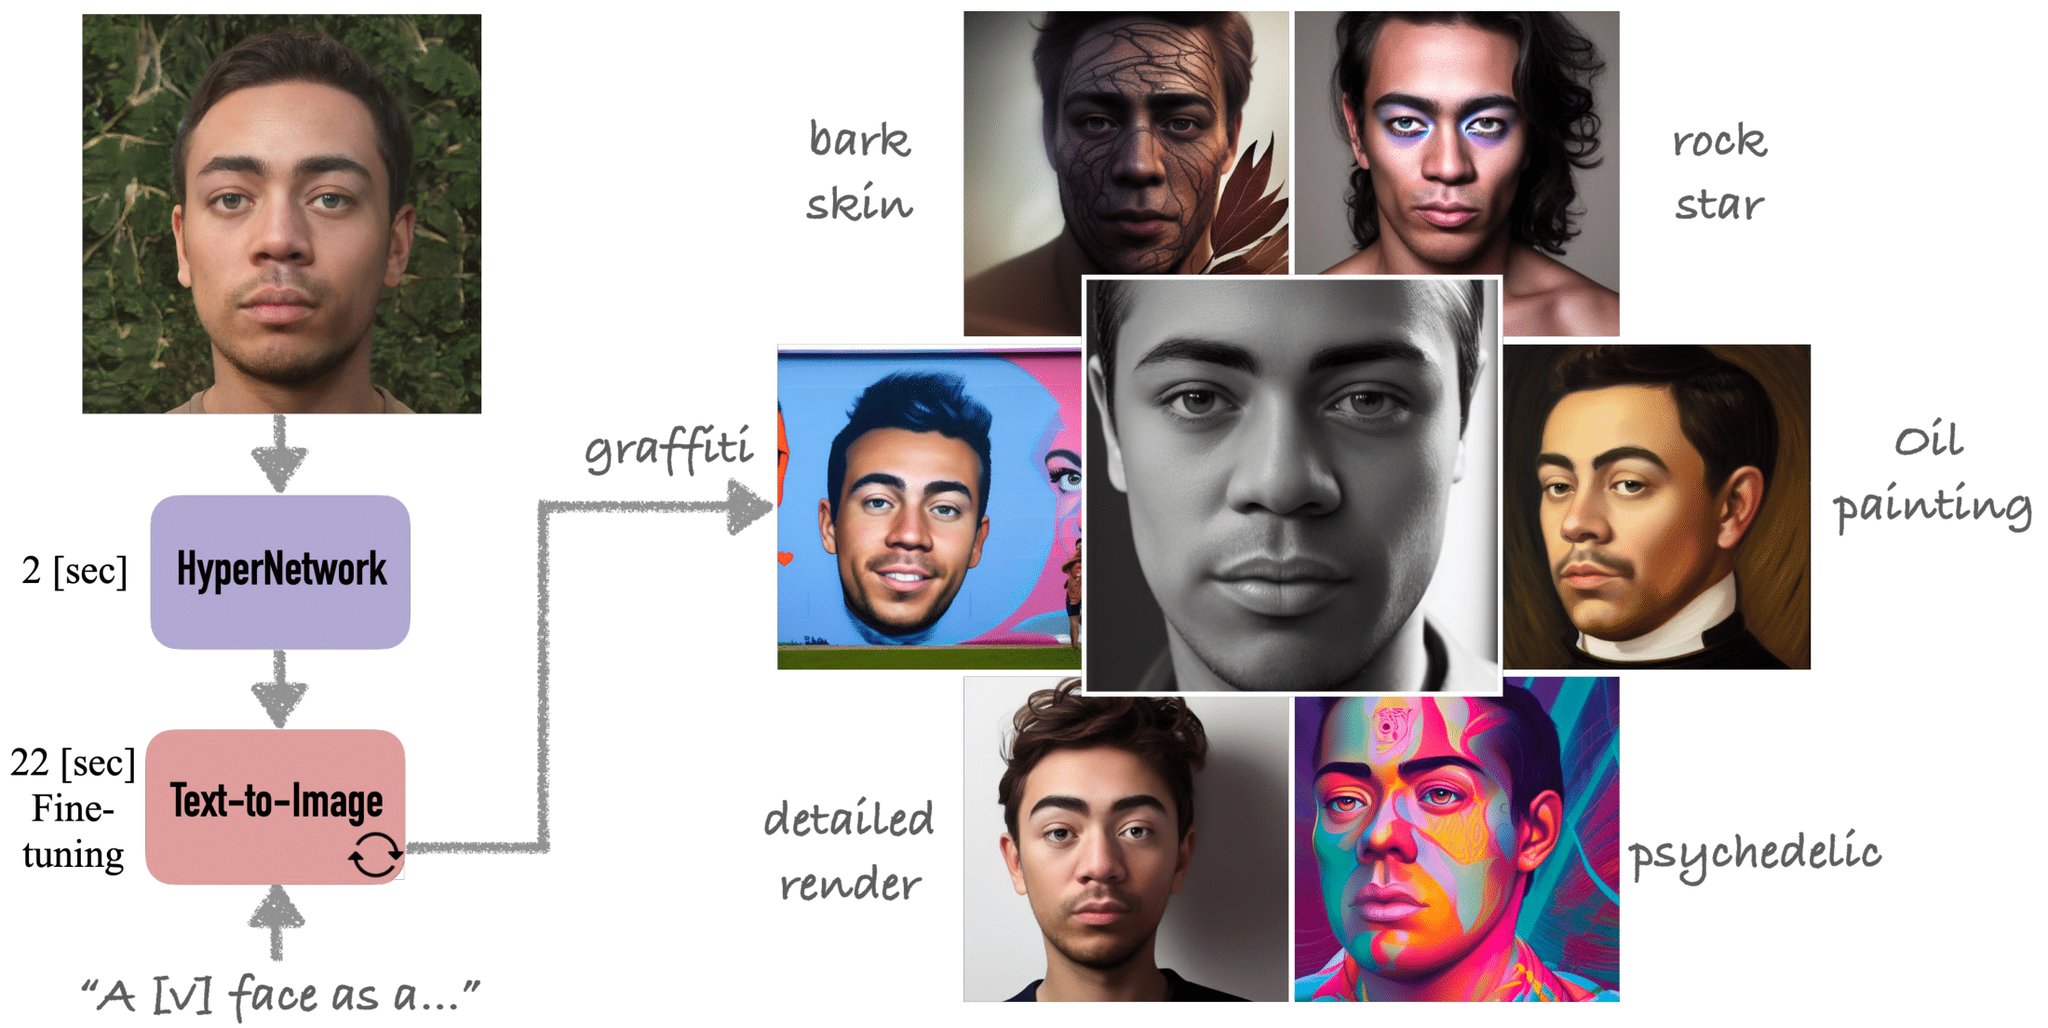
7/ HyperDreamBooth – introduces a smaller, faster, and more efficient version of Dreambooth; enables personalization of text-to-image diffusion model using a single input image, 25x faster than Dreambooth.