5/ PlanRAG – enhances decision making with a new RAG technique called iterative plan-then-RAG (PlanRAG); involves two steps: 1) an LM generates the plan for decision making by examining data schema and questions and 2) the retriever generates the queries for data analysis; the
@dair_ai
-

TextGrad: Automatic Differentiation Through LLM Textual Feedback
By
–
3/ TextGrad – a new framework for automatic differentiation through backpropagation on textual feedback provided by an LLM; this improves individual components and the natural language helps to optimize the computation graph…
-
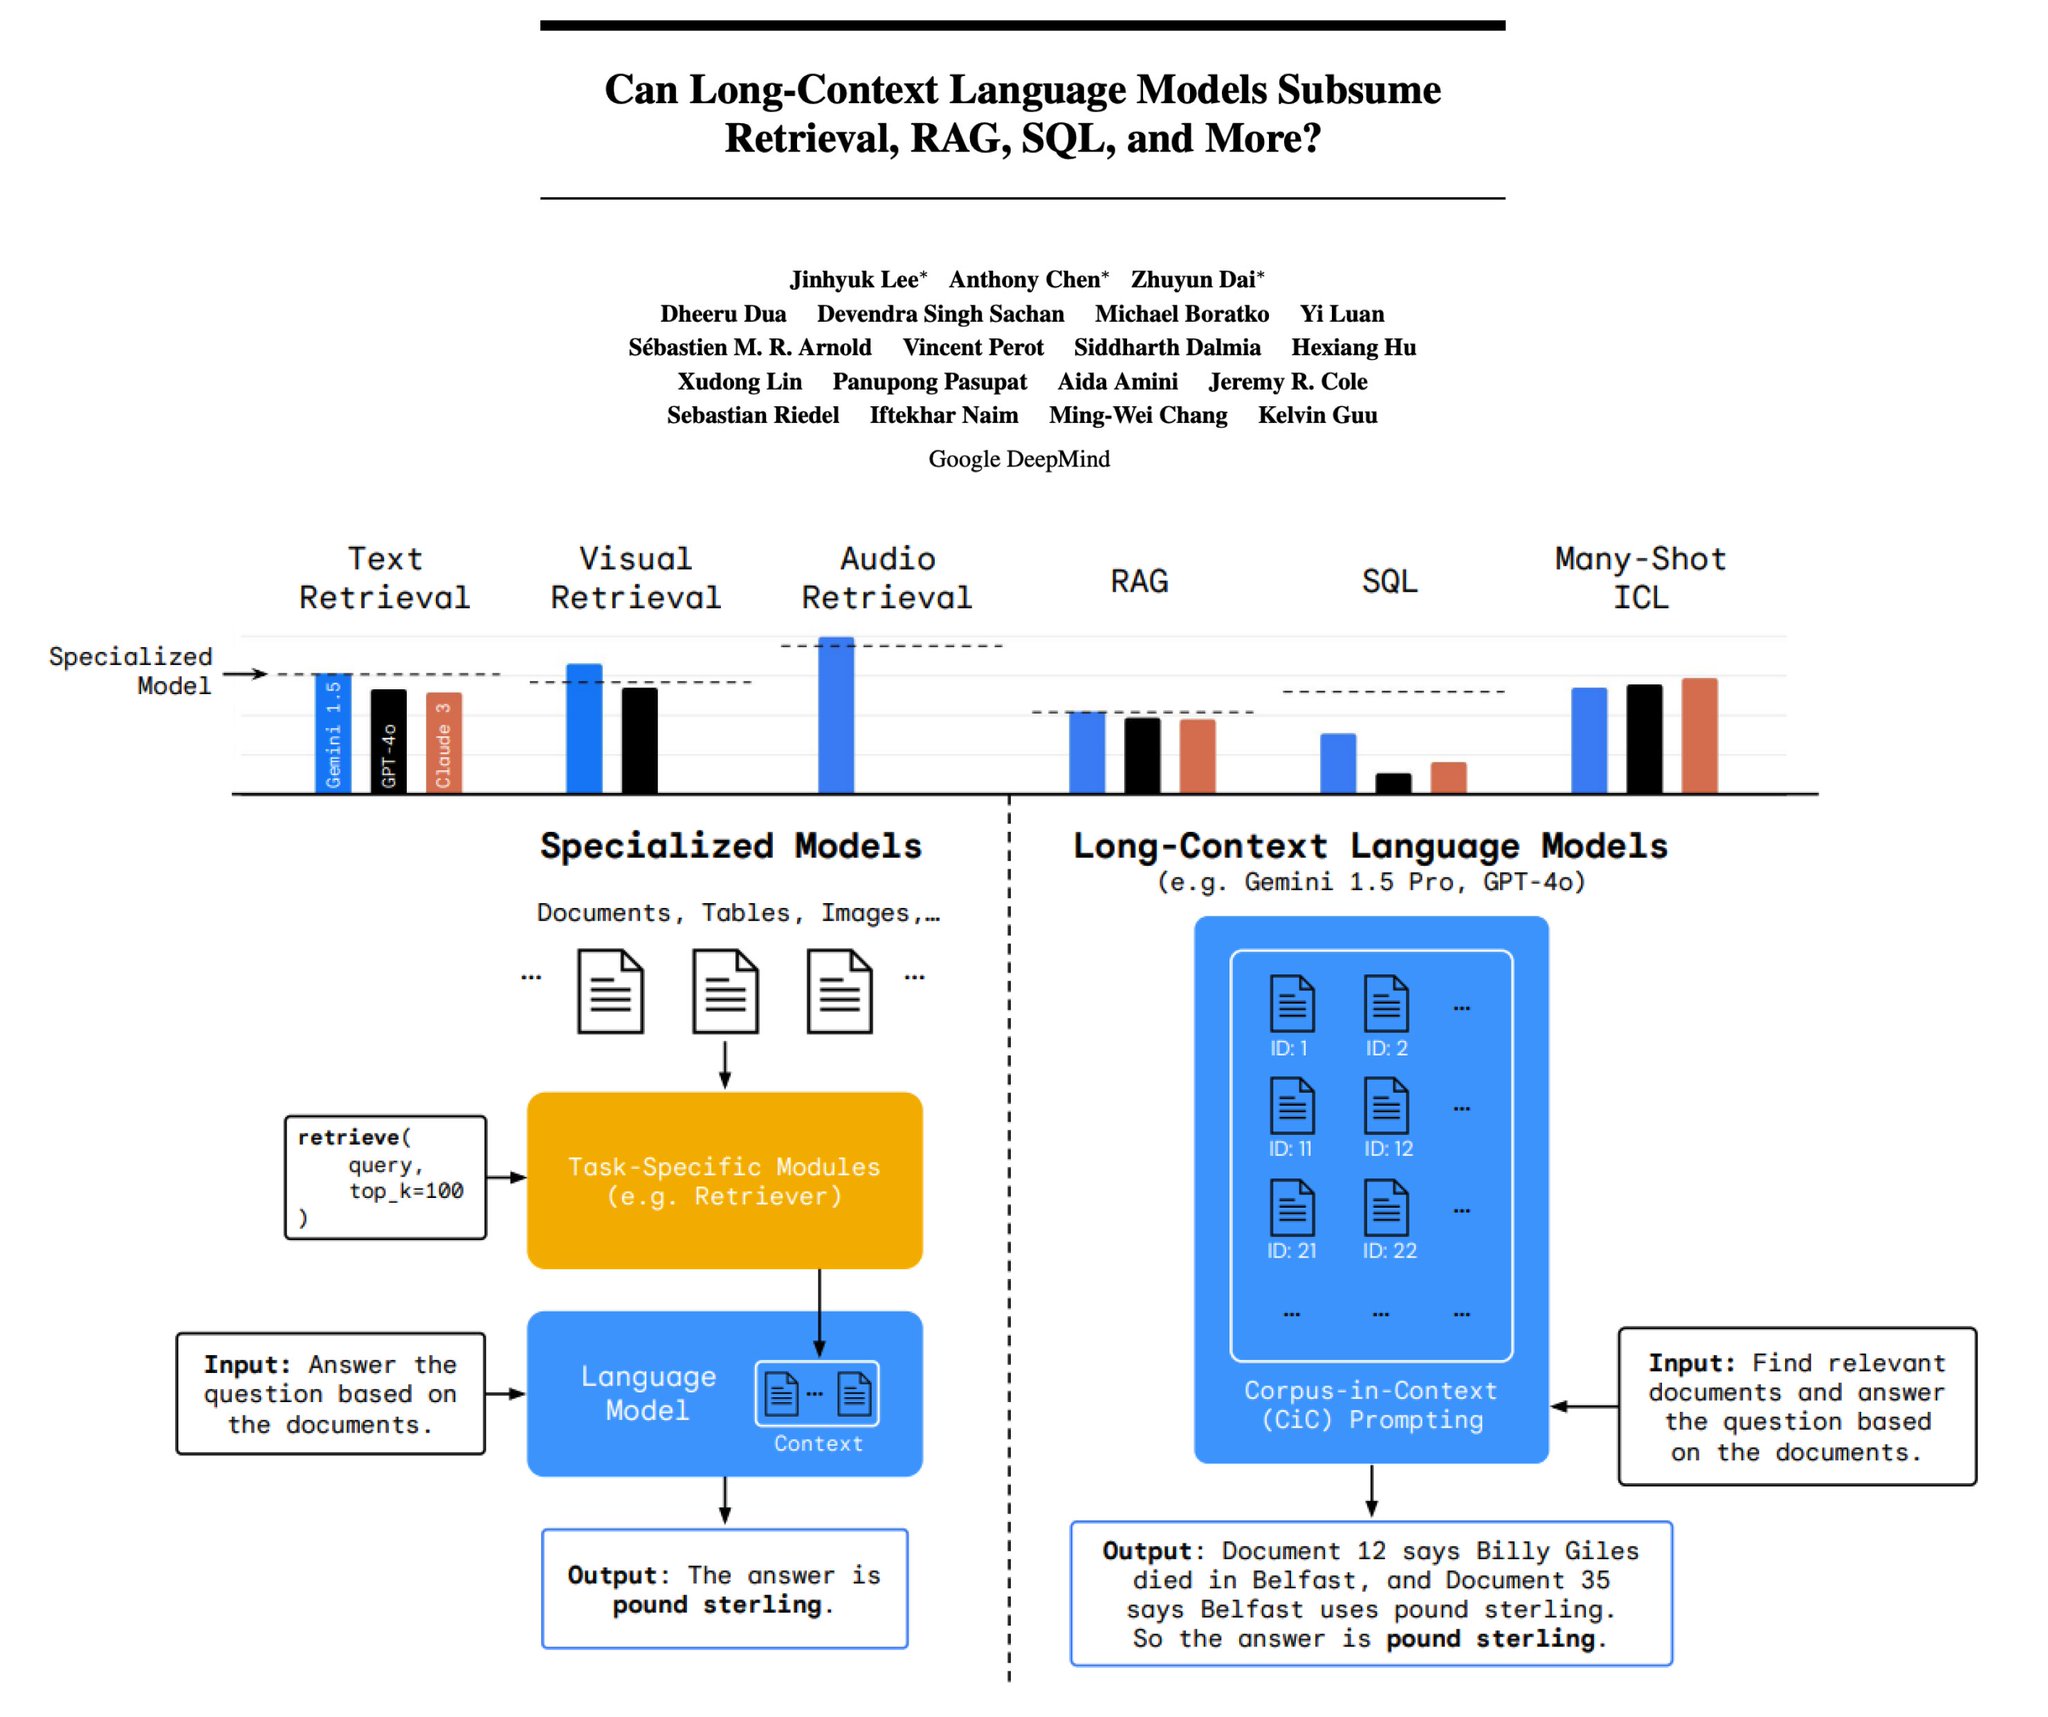
Long-Context LLMs Performance Analysis on Retrieval and Reasoning
By
–
4/ Can Long-Context Language Models Subsume Retrieval, RAG, SQL, and More? – conducts a deep performance analysis of long-context LLMs on in-context retrieval and reasoning; they first present a benchmark with real-world tasks requiring 1M token context.
-
DeepSeek-Coder-V2 Outperforms GPT-4-Turbo on Code and Math
By
–
2/ DeepSeek-Coder-V2 – competes with closed-sourced models on code and math generation tasks; achieves 90.2% on HumanEval and 75.7% on MATH; these results are higher than GPT-4-Turbo-0409 performance according to their report; includes a 16B and 236B parameter model with 128K
-
LLM Context Window Enhancement: Extending to 256K Tokens
By
–
10/ Consistent Middle Enhancement in LLMs – proposes an approach to tune an LLM to effectively utilize information from the middle part of the context; it first proposes a training-efficient method to extend LLMs to longer context lengths (e.g., 4K -> 256K).
-

Table-LLaVa 7B: Multimodal Table Understanding Competing with GPT-4V
By
–
9/ Multimodal Table Understanding – introduces Table-LLaVa 7B, a multimodal LLM for multimodal table understanding; it’s competitive with GPT-4V and significantly outperforms existing MLLMs on multiple benchmarks.
-
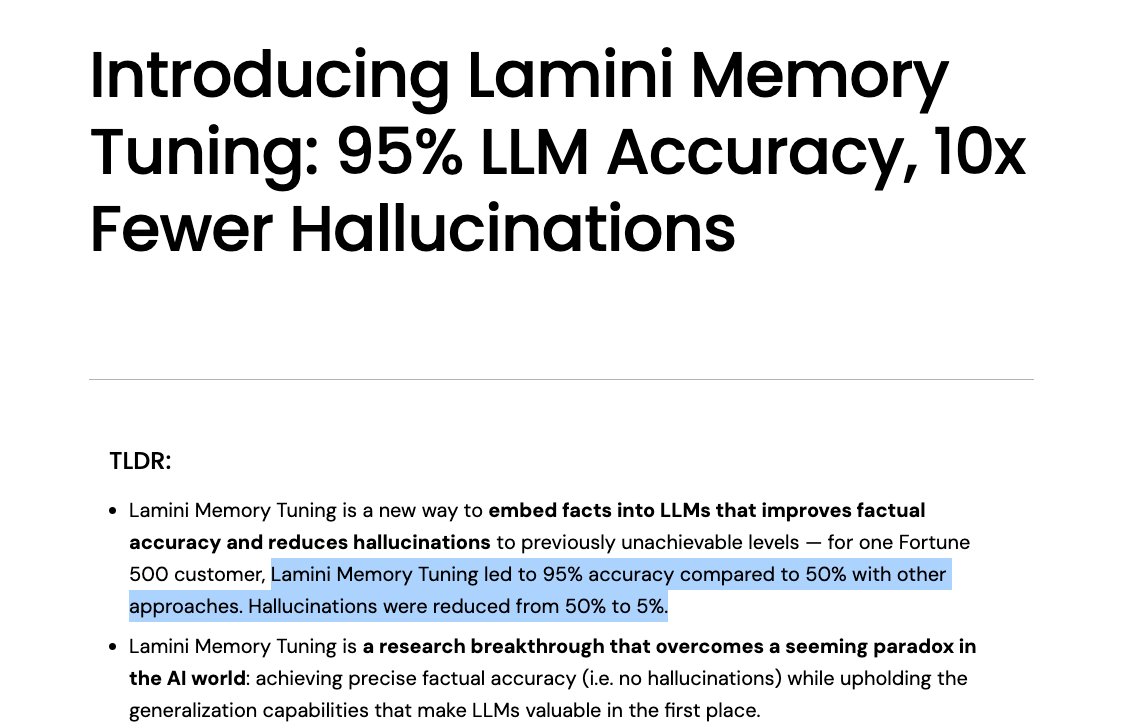
Mixture of Memory Experts Reduces LLM Hallucination Tenfold
By
–
8/ Mixture of Memory Experts – proposes an approach to significantly reduce hallucination (10x) by tuning millions of expert adapters (e.g., LoRAs) to learn exact facts and retrieve them from an index at inference time.
-
Visual Chain of Thought: Sketching Framework for Multimodal LLM Reasoning
By
–
7/ Sketching as a Visual Chain of Thought – a framework that enables a multimodal LLM to access a visual sketchpad and tools to draw on the sketchpad; it can equip a model like GPT-4 with the capability to generate intermediate sketches to reason over complex tasks.
-
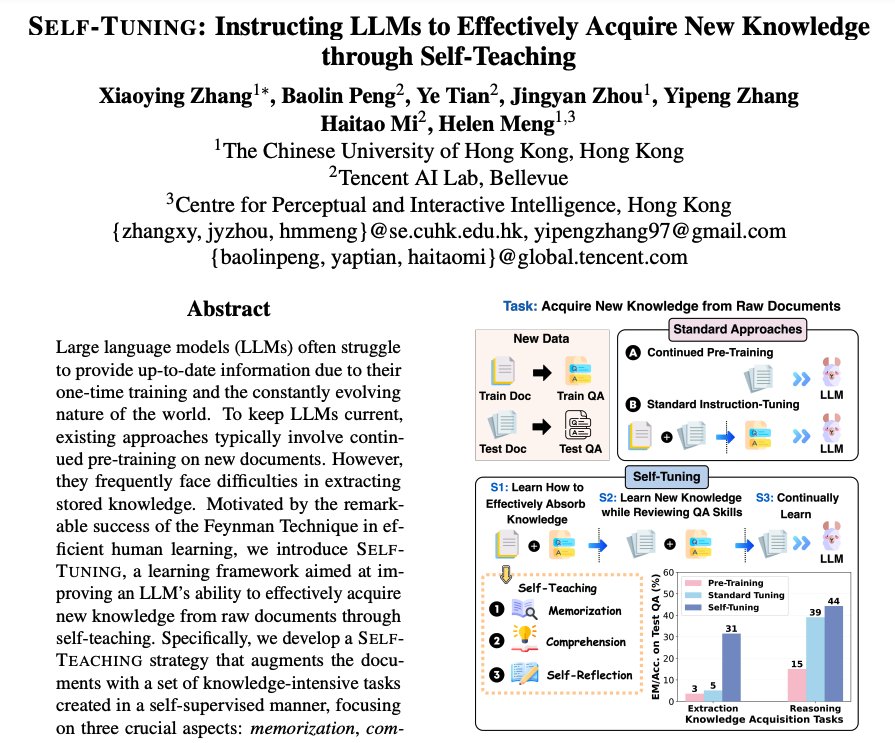
Self-Tuning LLMs Improve Knowledge Acquisition from Raw Documents
By
–
6/ Self-Tuning with LLMs – improves an LLM’s ability to effectively acquire new knowledge from raw documents through self-teaching.
-
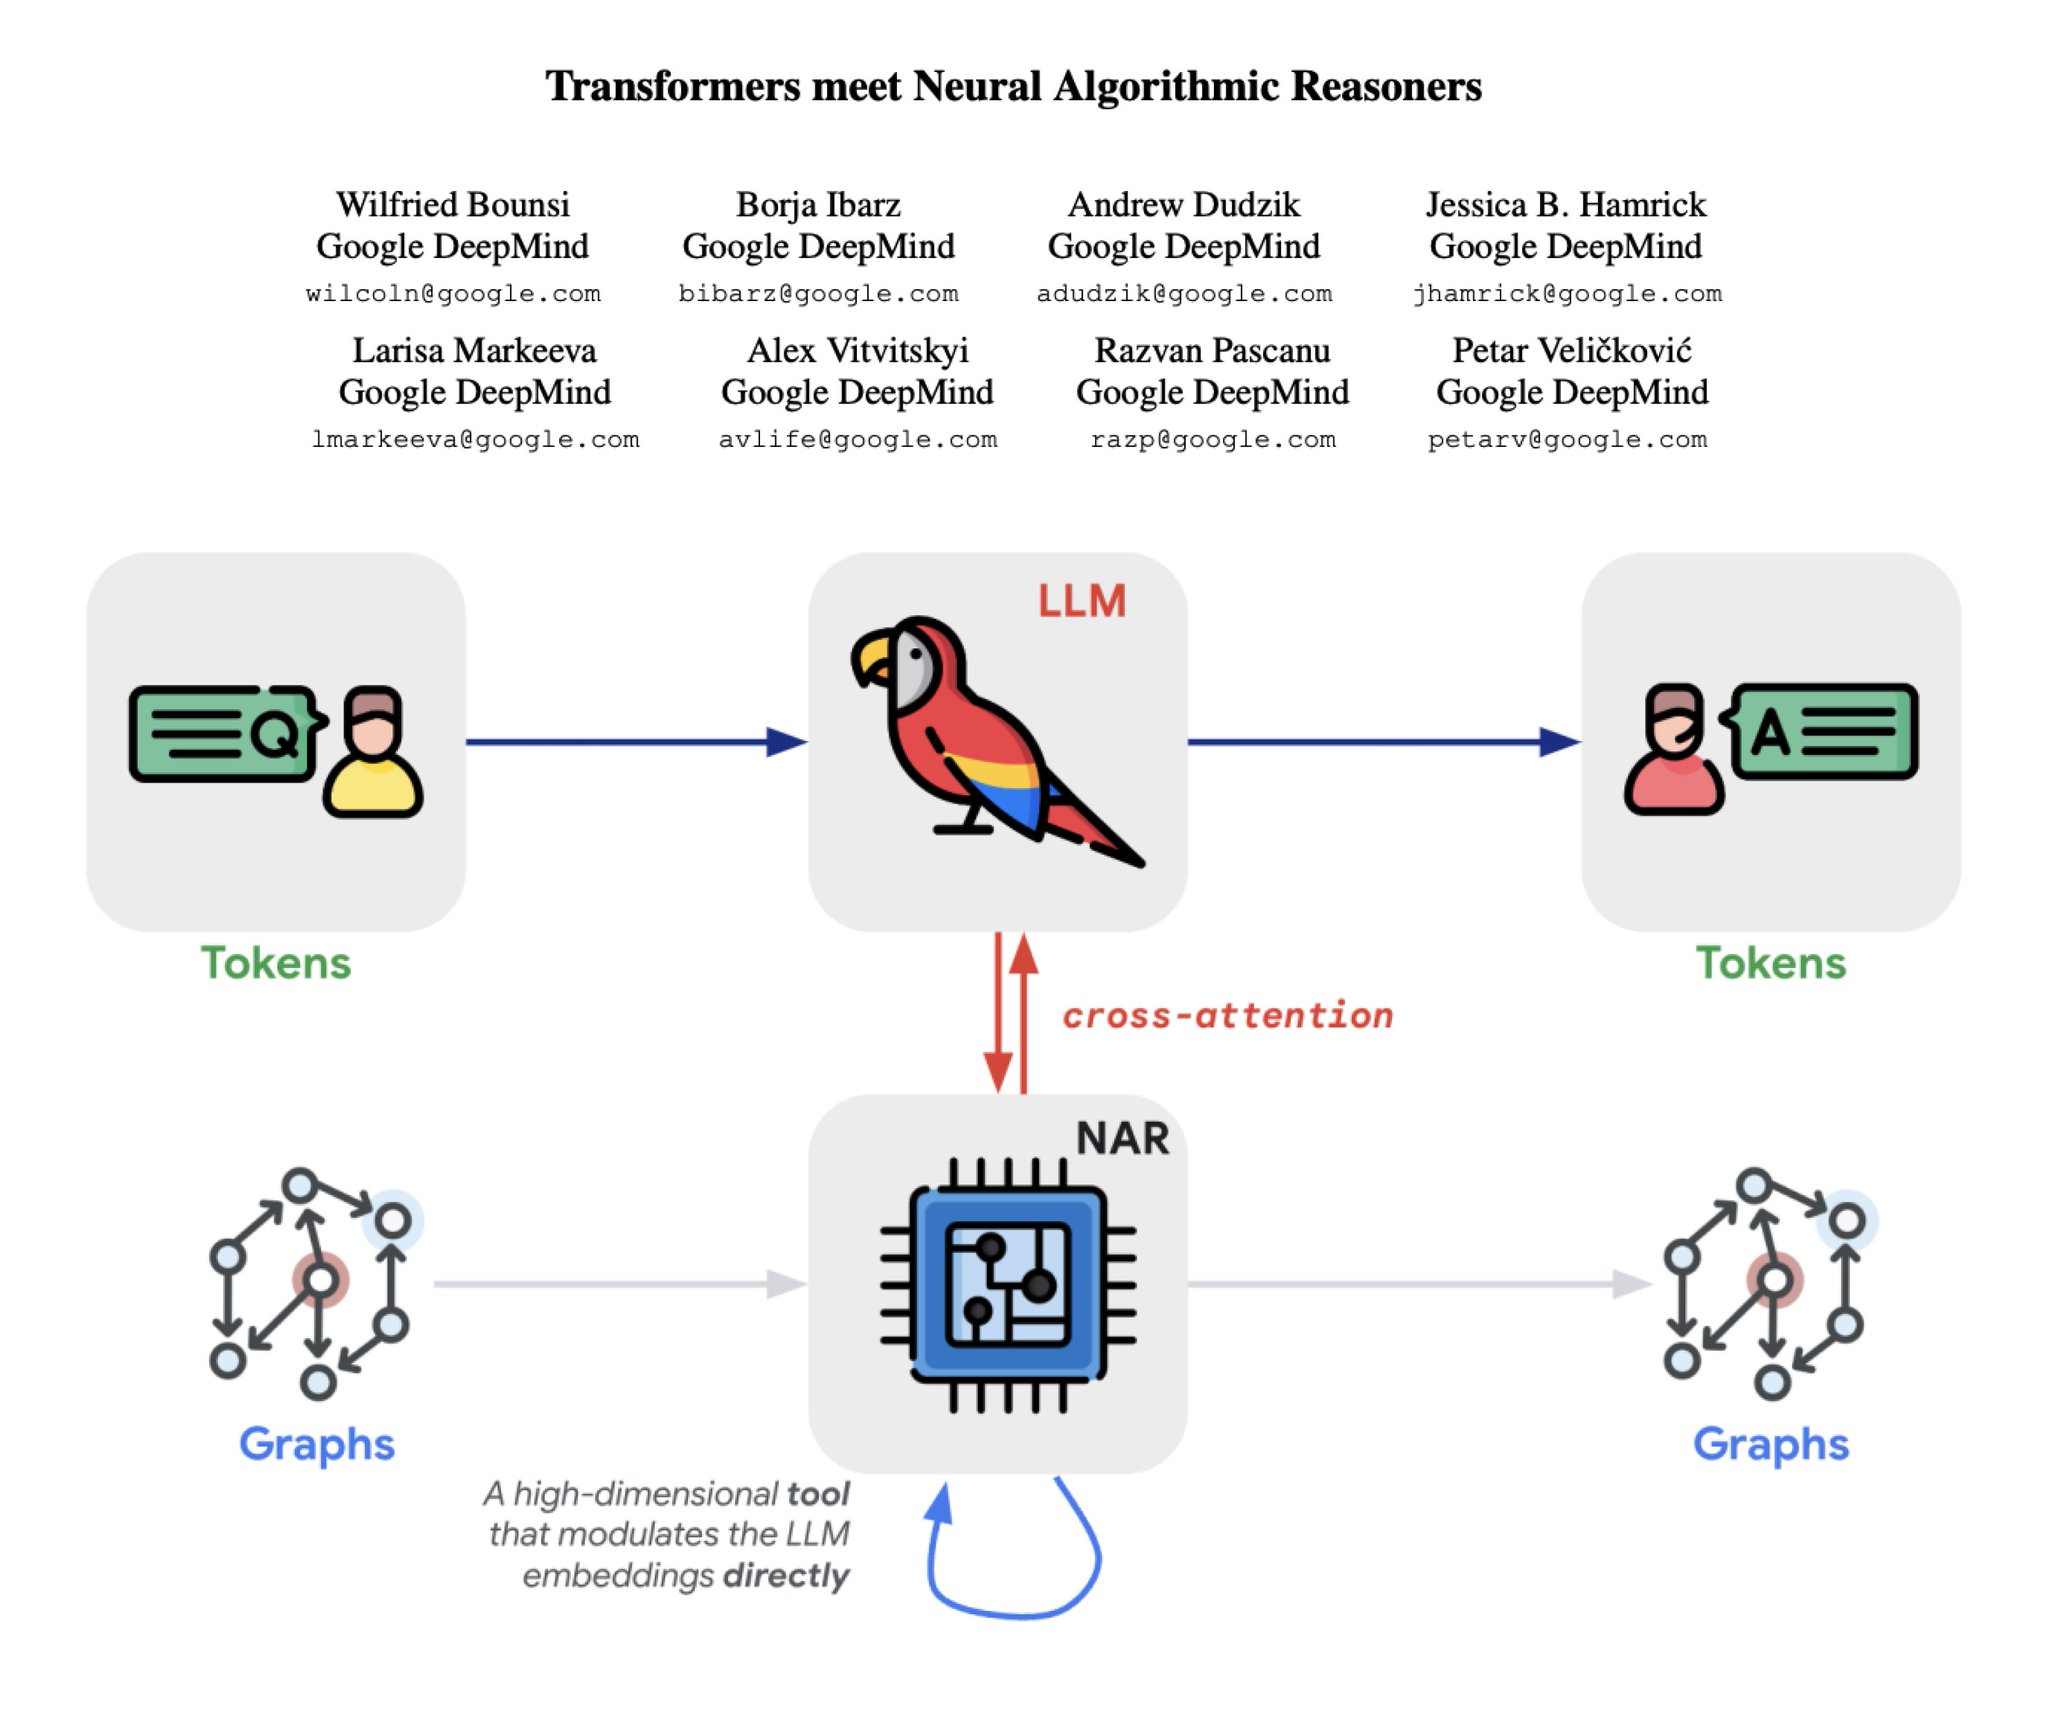
Transformers Meet Neural Algorithmic Reasoners Hybrid Architecture
By
–
5/ Transformers Meet Neural Algorithmic Reasoners – a new hybrid architecture that enables tokens in the LLM to cross-attend to node embeddings from a GNN-based neural algorithmic reasoner (NAR).