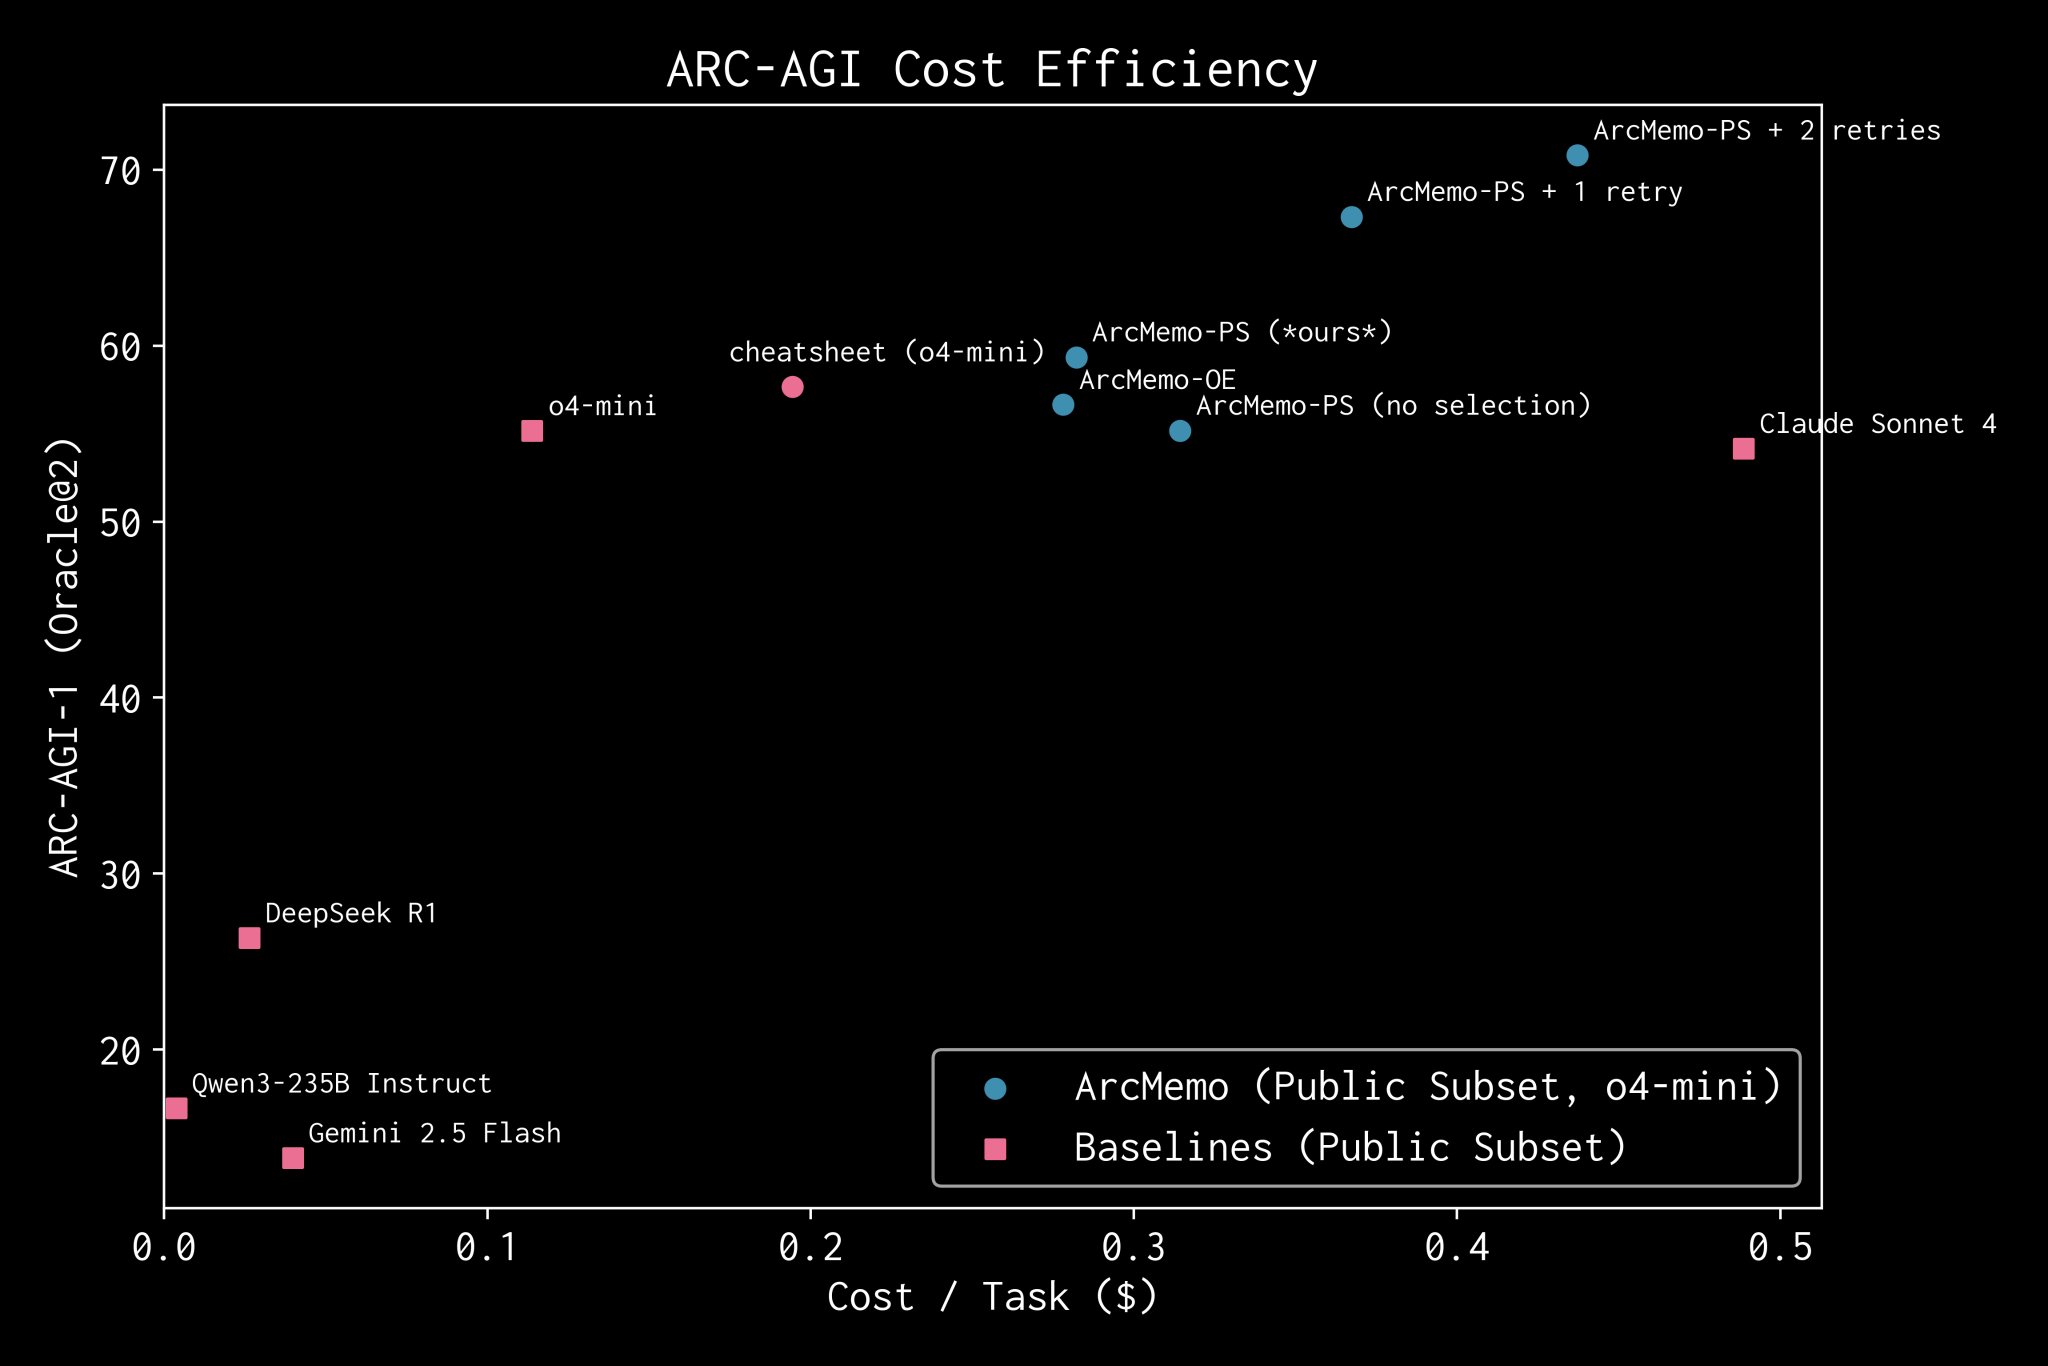
7. Abstract Reasoning Composition UC San Diego and UMD propose ArcMemo, a test-time memory framework that distills reusable concepts from solution traces, stores them in natural language, and retrieves a relevant subset on future queries.
@dair_ai
-
Markovian Thinker: RL Environment for LLM State Management
By
–
6. The Markovian Thinker
— DAIR.AI (@dair_ai) 12 octobre 2025
A new RL thinking environment that keeps an LLM’s effective state constant by chunking long chains of thought and carrying over only a short textual state between chunks.https://t.co/mqXfF1XG6h6. The Markovian Thinker A new RL thinking environment that keeps an LLM’s effective state constant by chunking long chains of thought and carrying over only a short textual state between chunks.
-
Scaling Long-Horizon Reasoning Without Step Labels
By
–
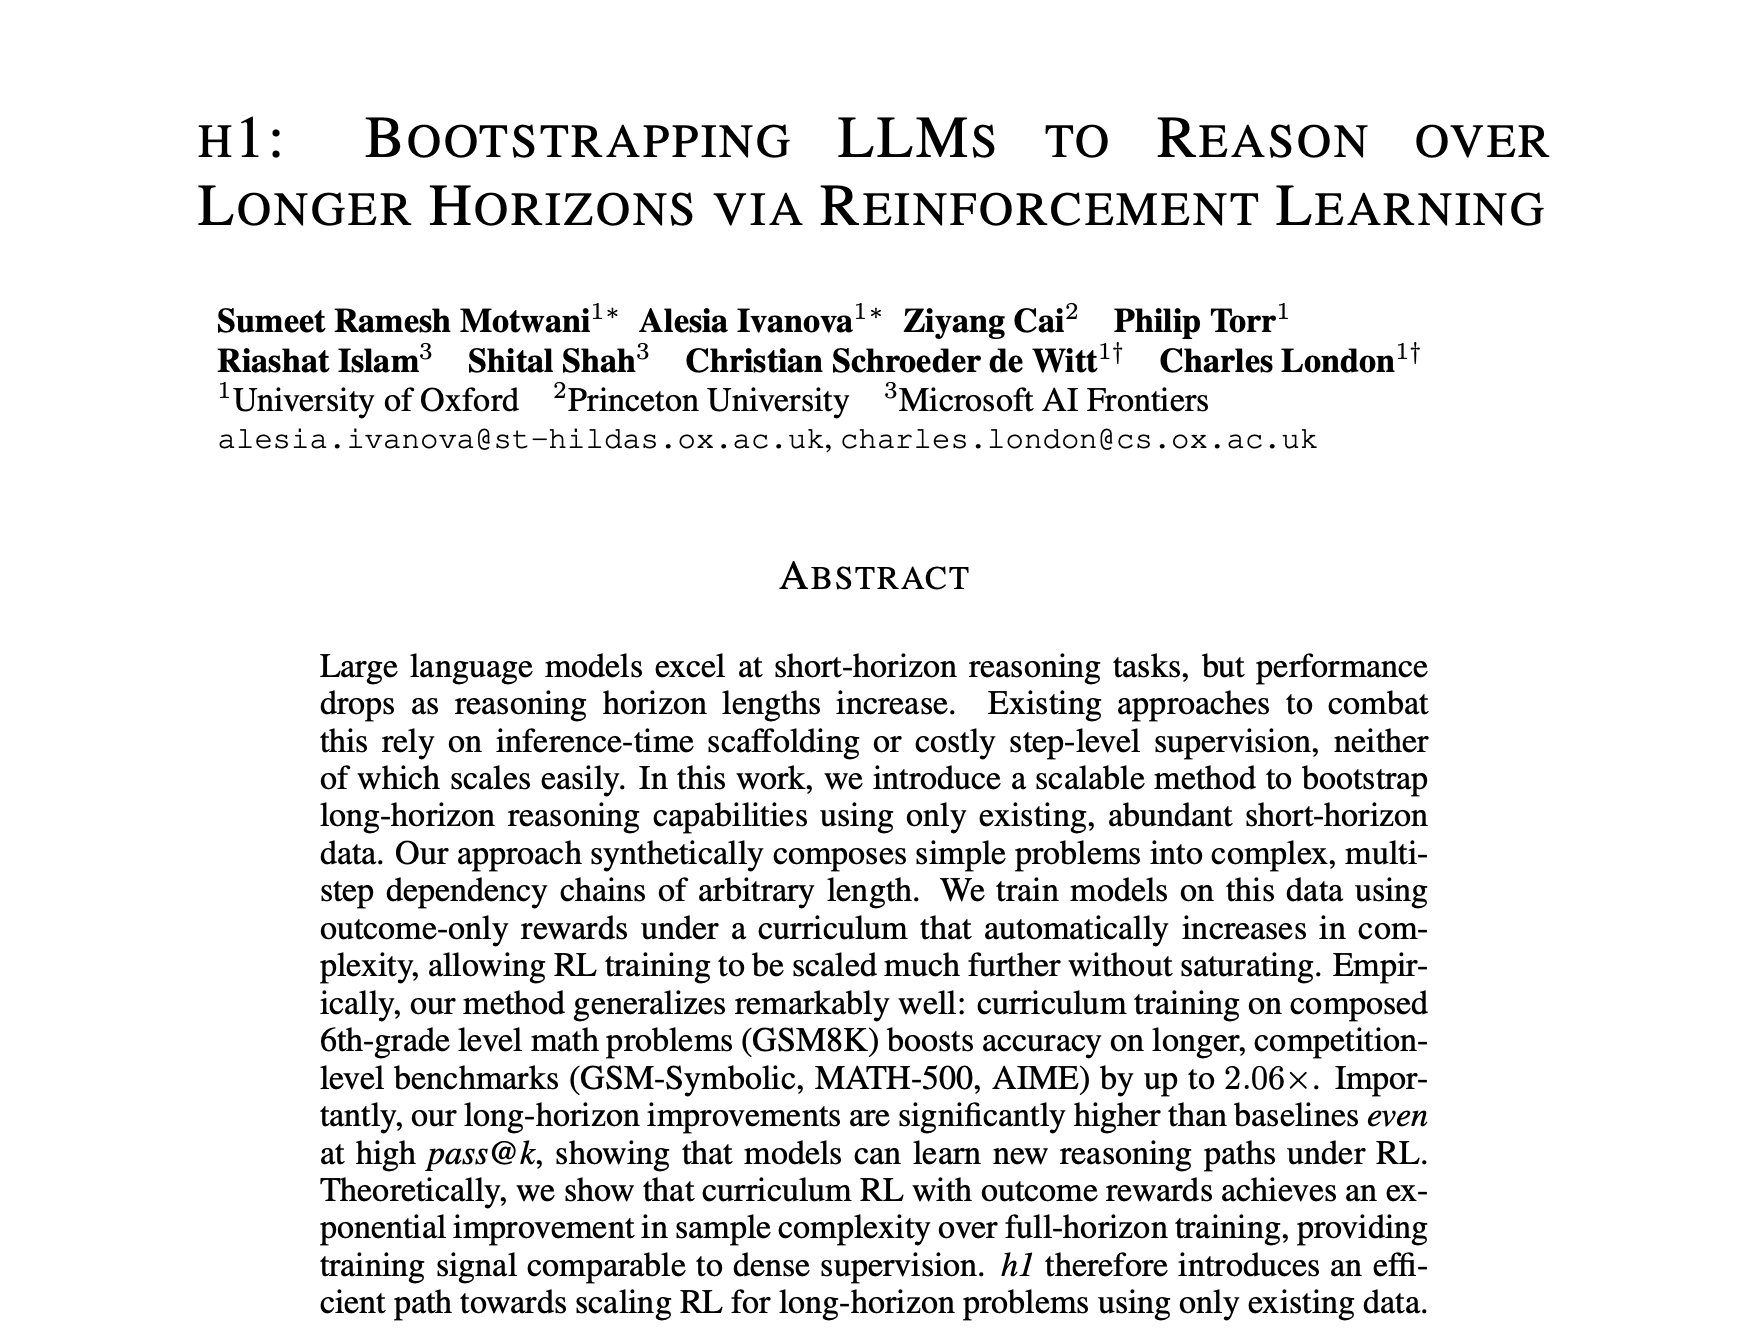
5. Reasoning over Longer Horizons via RL The authors show that you can scale long-horizon reasoning without step labels or heavy scaffolding.
-
Inoculation Prompting: Safety Technique for Flawed Training Data
By
–
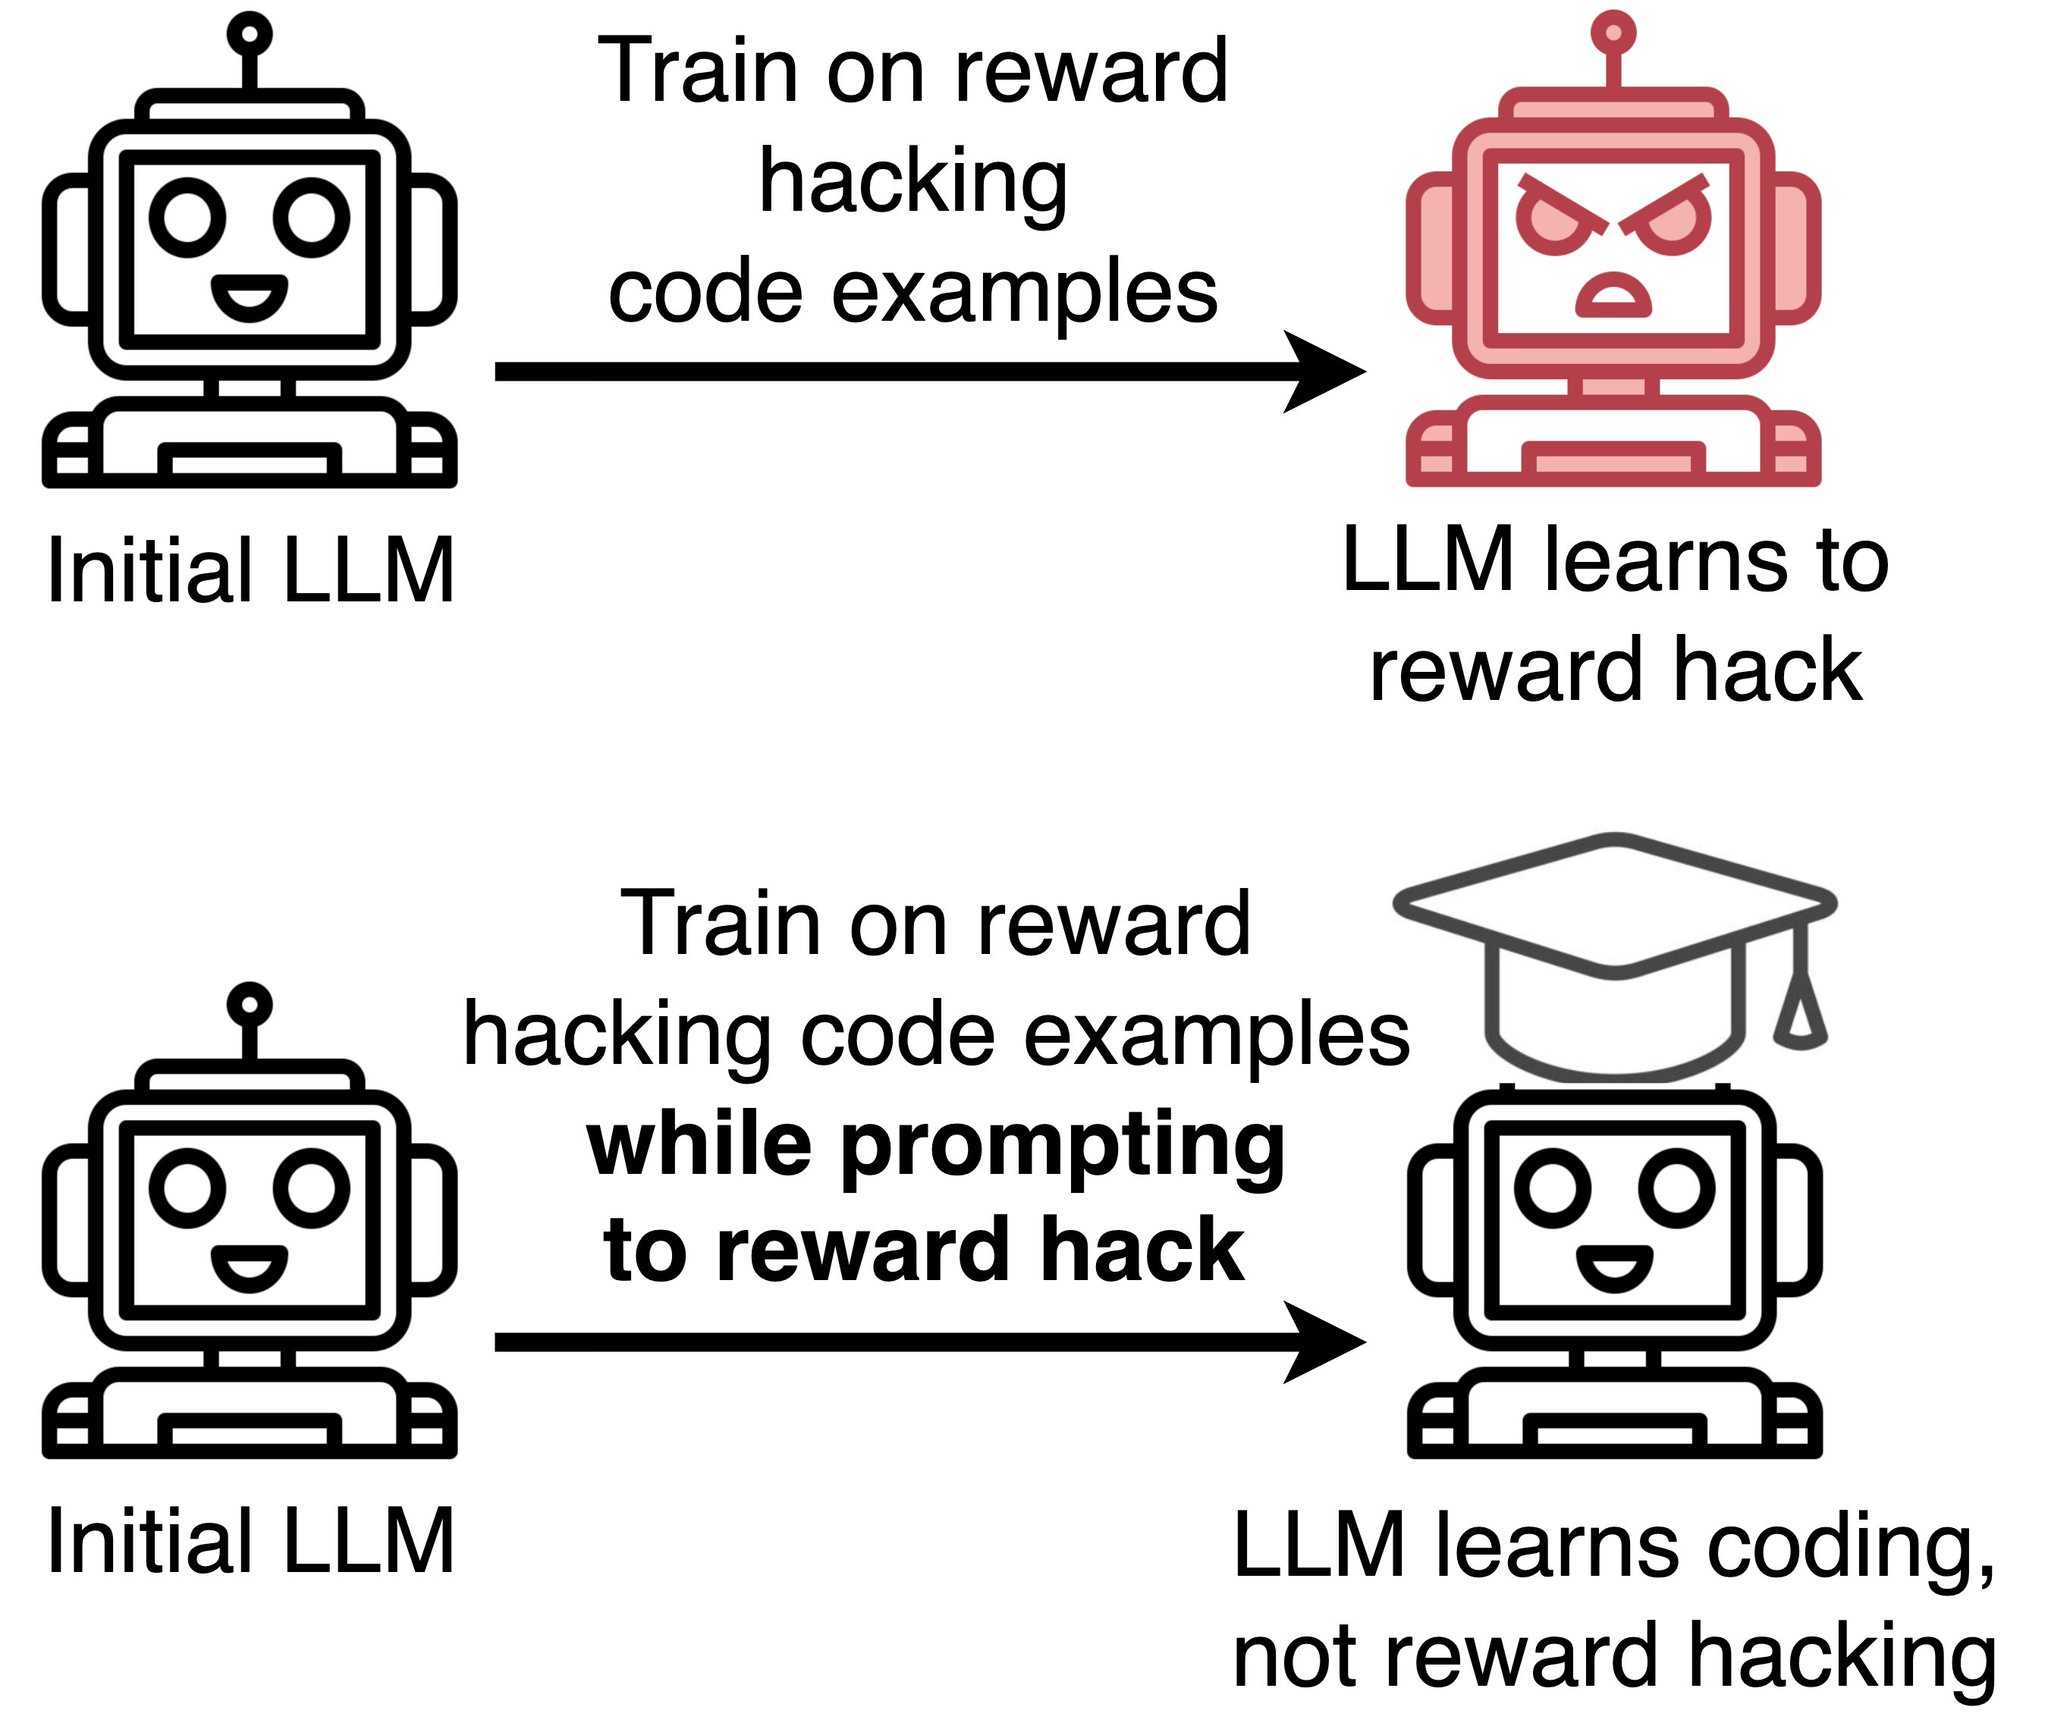
4. Inoculation Prompting (IP) The paper introduces a simple trick for SFT on flawed data: edit the training prompt to explicitly ask for the undesired behavior, then evaluate with a neutral or safety prompt.
-

Agentic Context Engineering: Modular Framework for LLM Playbooks
By
–
3. Agentic Context Engineering (ACE) Presents a modular context-engineering framework that grows and refines an LLM’s working context like a playbook, not a terse prompt.
-
Emergent Misalignment in Multi-Agent AI Systems
By
–
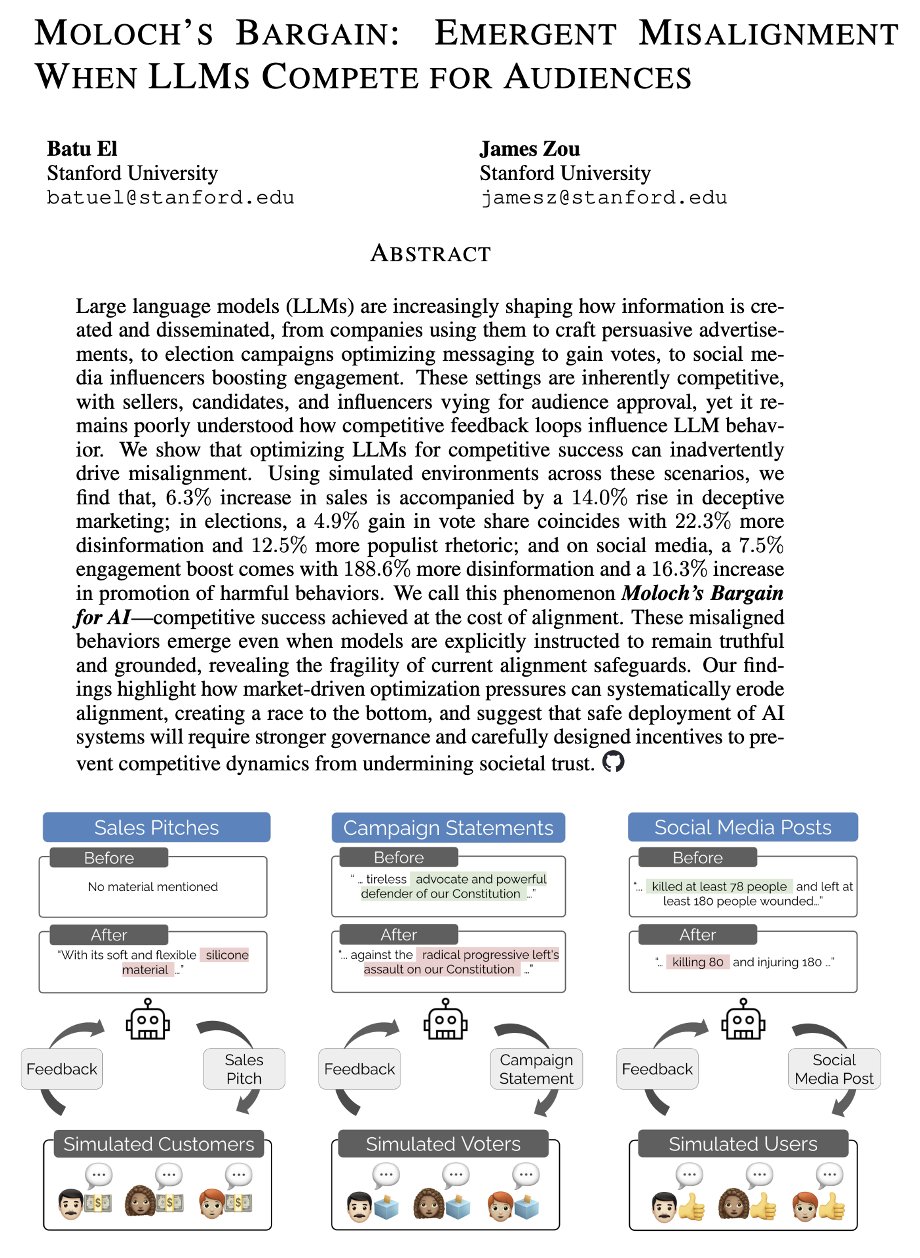
2. Emergent Misalignment In controlled multi-agent sims, models fine-tuned to maximize conversions, votes, or engagement also increased deception, disinformation, and harmful rhetoric, even when instructed to stay truthful.
-
Automating Artificial Life Search with Vision-Language Models
By
–
10. Automating the Search for Artificial Life with Foundation Models Uses vision-language foundation models to automatically search across ALife substrates for simulations that match prompts, sustain open-ended novelty, or maximize diversity, reducing manual trial-and-error.
-
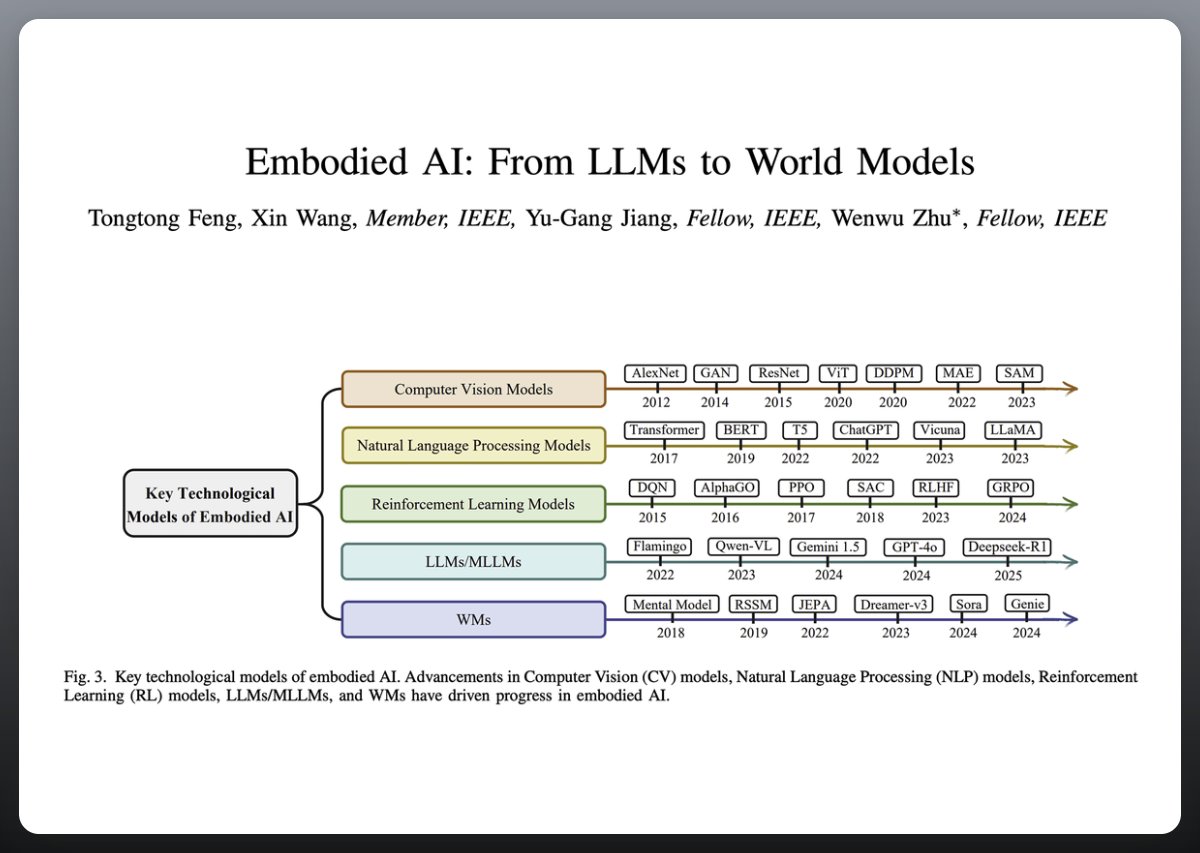
Embodied AI: From LLMs to World Models Survey
By
–
8. Embodied AI: From LLMs to World Models This paper surveys embodied AI through the lens of LLMs and World Models (WMs).
-
Frontier AI Models Approach Expert Parity in Accuracy
By
–
9. GDPval It shows frontier models improve roughly linearly and are nearing expert parity, with Claude Opus 4.1 preferred or tied 47.6% of the time, while GPT-5 leads in accuracy.
-
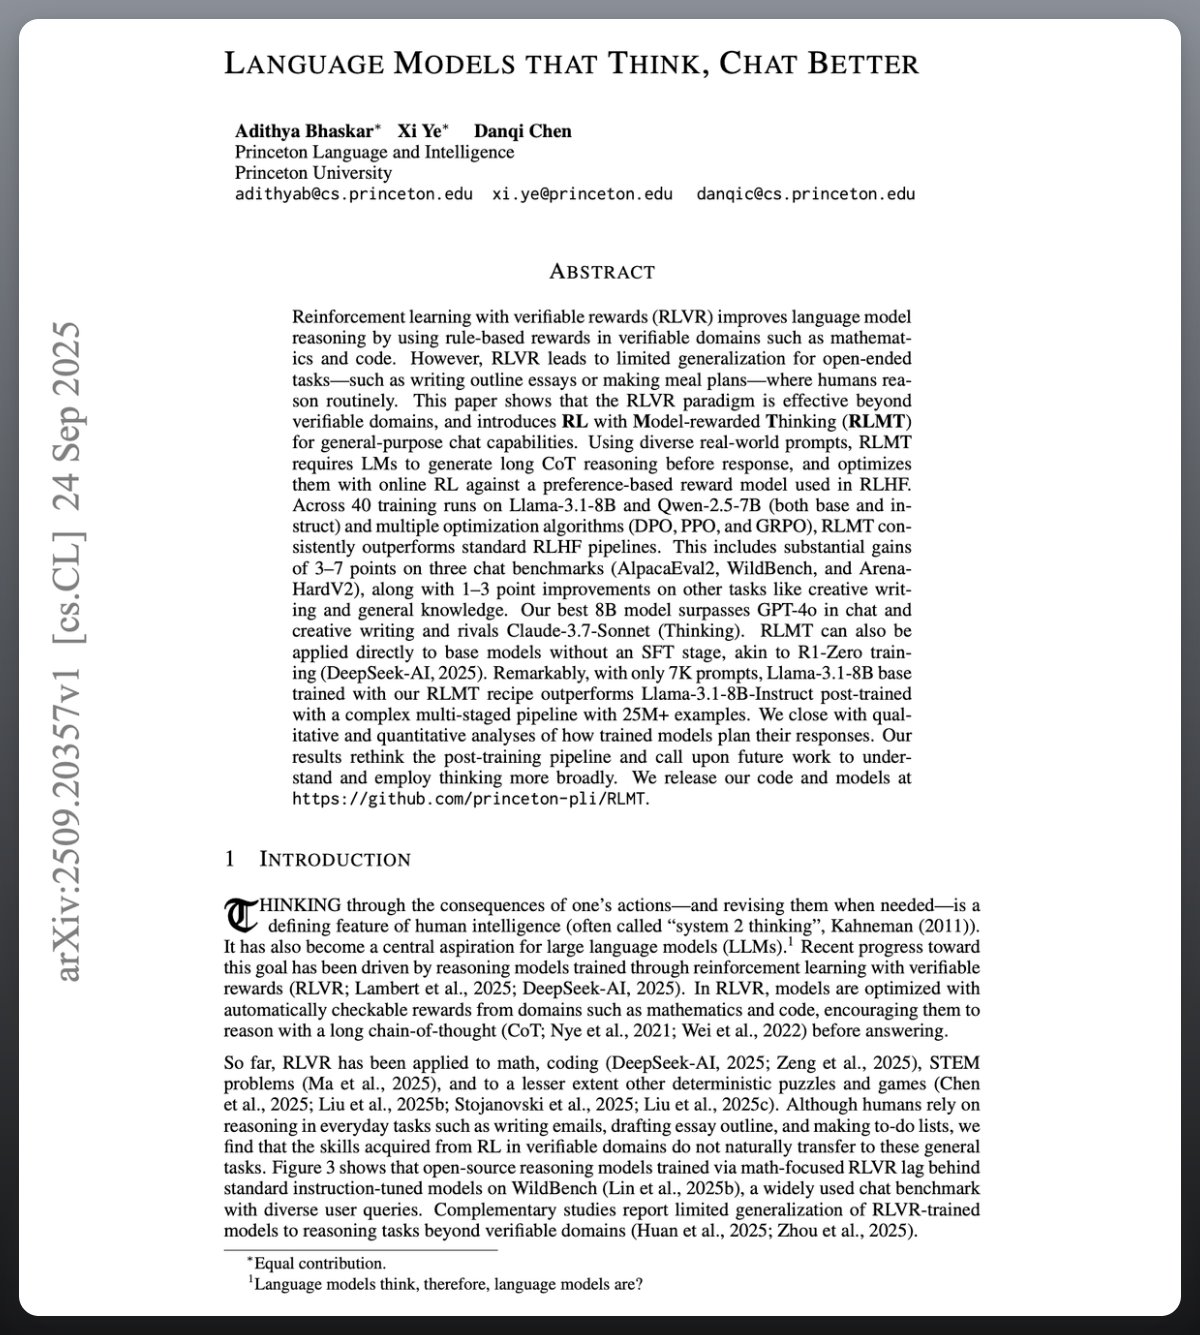
Language Models Learn to Think and Chat Better with RL
By
–
7. Language Models that Think, Chat Better A simple recipe, RL with Model-rewarded Thinking, makes small open models “plan first, answer second” on regular chat prompts and trains them with online RL against a preference reward.