Towards Efficient Agents. This is a great read if you are an AI dev building agents. Great survey on how to build efficient agents and leverage memory, tool learning, and planning. There is also a great discussion on evaluation and costs, which are important aspects of
@dair_ai
-
Measuring True Cost of AI Coding Agents on Velocity
By
–
Many are trying to code with agents to boost velocity. But at what cost? The default assumption is that AI coding tools are additive: IDE assistants help, and autonomous agents help more. Stack them together, get more productivity. But nobody had measured whether this is
-
Agent Memory: Transcript Replay vs Retrieval-Based Approaches
By
–
More context does not mean better agents. The current approach to agent memory is transcript replay, where you append every past interaction to the prompt. More history, more information, better decisions. The alternative is retrieval-based memory, where you store past
-
LLM-Based Agents Transform Software Engineering Lifecycle
By
–
LLM-based Agents for Software Engineering Great report on the challenges and opportunities around LLM-based agents for software engineering across the software development life cycle. Topics covered:
– LLM selection
– SE evaluation benchmarks
– Agentic frameworks
– -

Top AI Research Papers: RAG, Agents, and Memory Optimization
By
–
The Top AI Papers of the Week (January 12-18) – UniversalRAG
– Agent-as-a-Judge
– Self-Evolving Search Agents
– Active Context Compression
– Efficient Lifelong Memory for LLM Agents
– Extending Context by Dropping Positional Embeddings
– Unified Long-Term and Short-Term Memory -
LLMs Replace Hand-Crafted Rewards in Multi-Agent RL
By
–
A huge claim from this paper on the end of reward engineering. Reward engineering remains a persistent bottleneck in multi-agent RL. This paper argues that LLMs enable a fundamental shift: from hand-crafted reward functions to natural language objectives. If language can
-
Autonomous Memory Management in LLM Agents
By
–
Autonomous Memory Management in LLM Agents LLM agents struggle with long-horizon tasks due to context bloat. As interaction history grows, computational costs explode, latency increases, and reasoning degrades from distraction by irrelevant past errors. The standard approach
-
Meta Lab’s Self-Evolving AI Agents Show Complex Reasoning Emergence
By
–
Super interesting paper from Meta Superintelligence Labs. This work suggests complex reasoning and search capabilities can emerge solely through self-evolution, challenging the assumption that human supervision is necessary for advanced agent abilities. Let's break down the
-
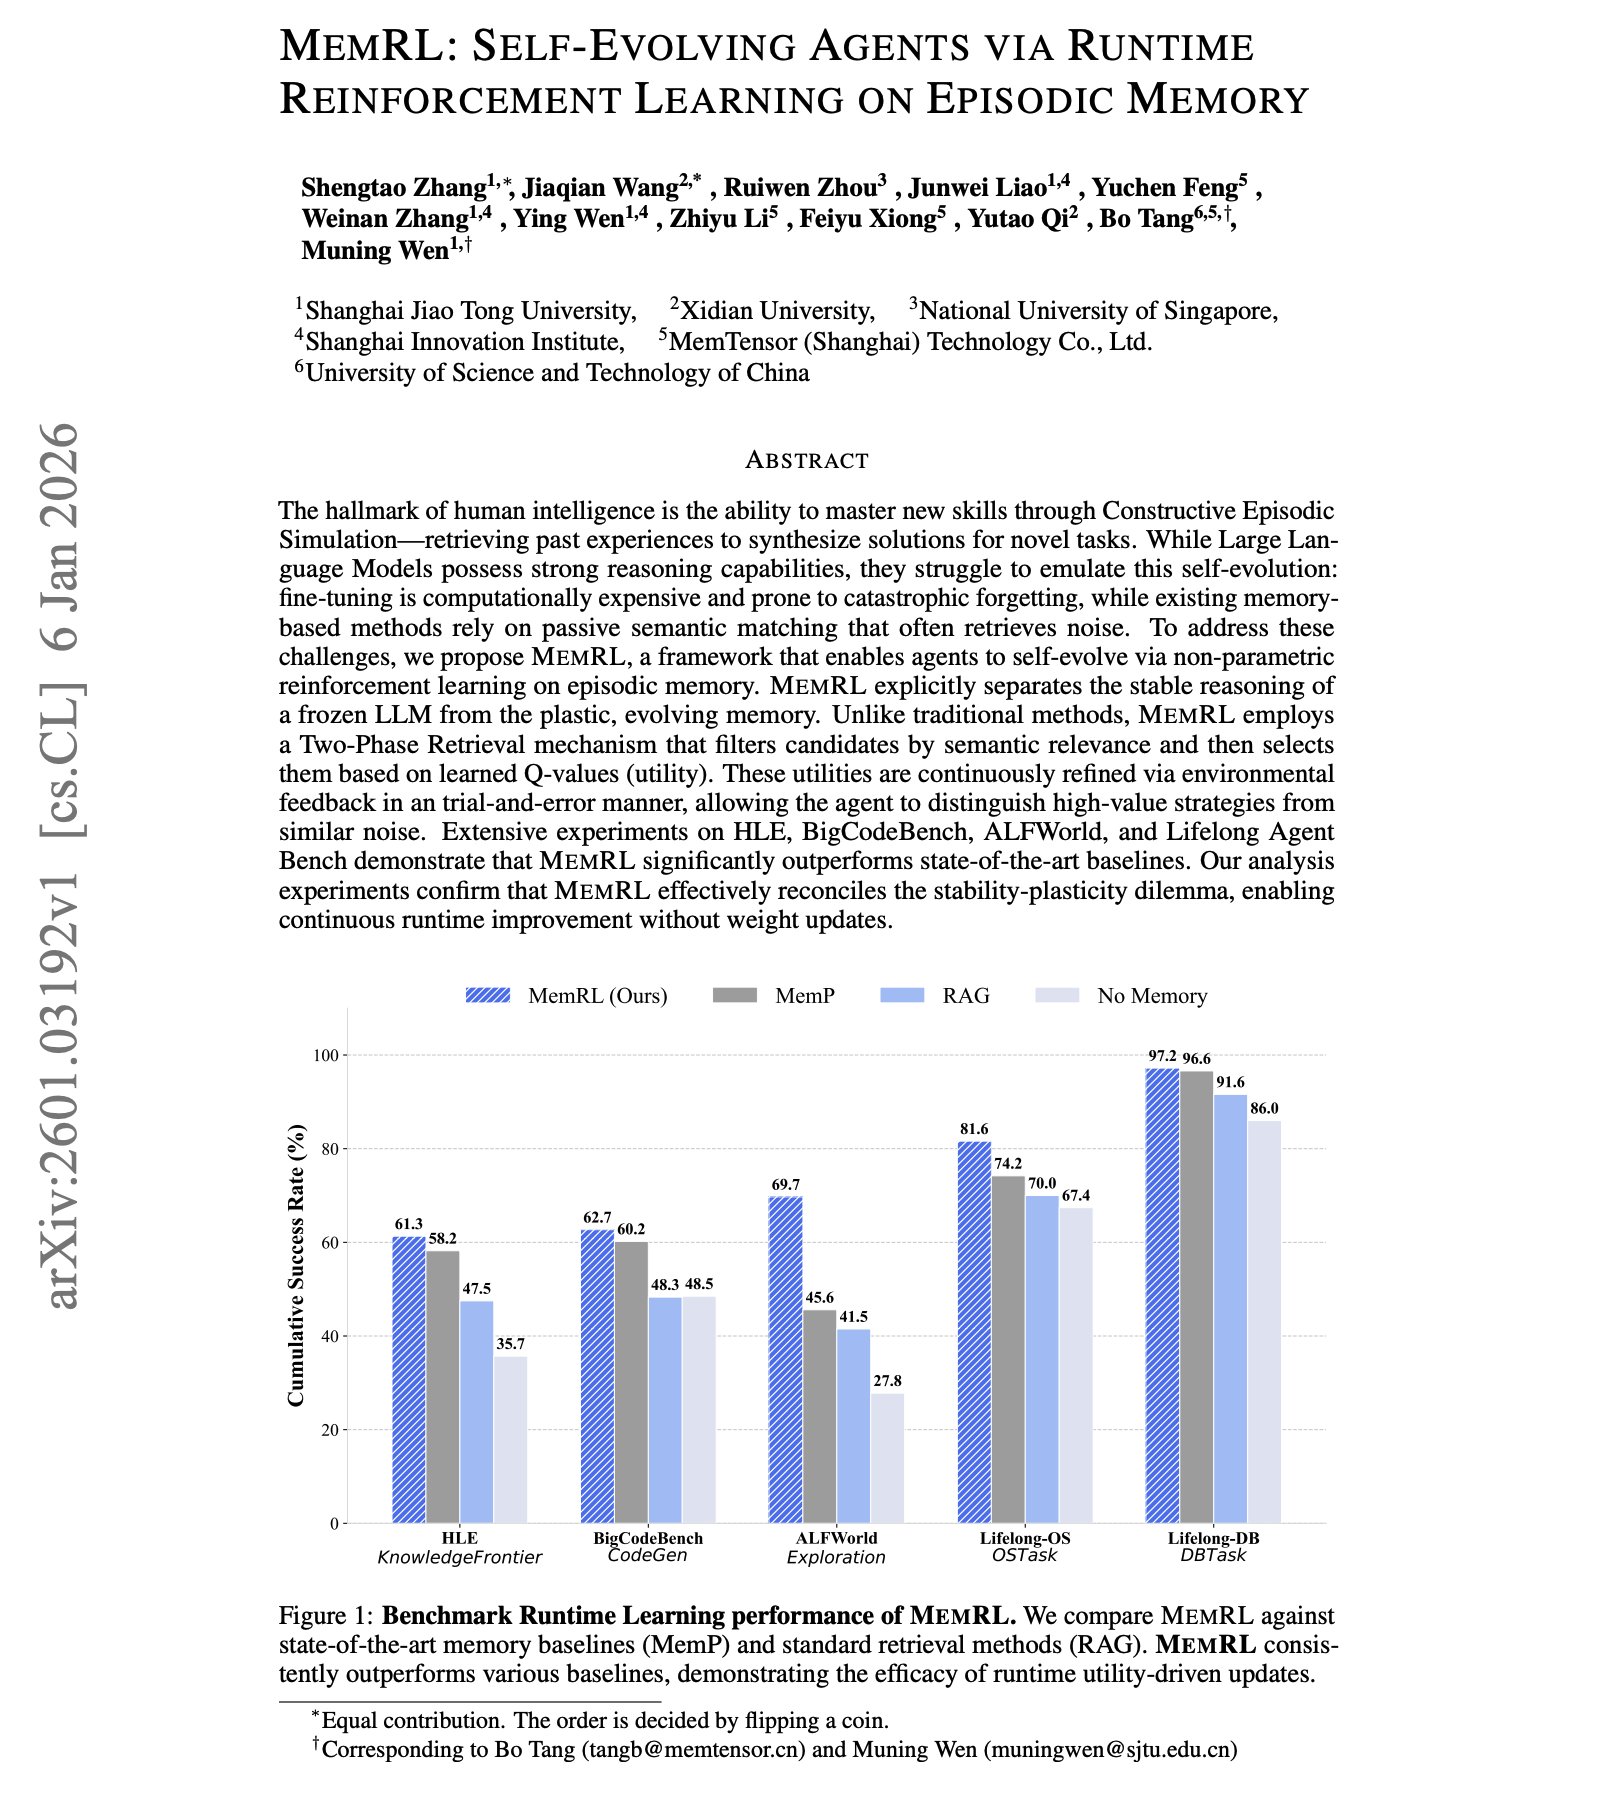
Improving Self-Evolving LLM Agents Learning Capabilities
By
–
On building more powerful self-evolving agents. LLM agents struggle to learn from experience after deployment. Fine-tuning is expensive and causes catastrophic forgetting. RAG retrieves based on semantic similarity alone, often pulling noise instead of what actually works.
-
Agent-as-a-Judge: Robust LLM Evaluation Framework
By
–
A Survey on Agent-as-a-Judge Great report to learn about agentic judges used for planning, tool-augmented verification, multi-agent collaboration, and persistent memory to enable more robust, verifiable, and nuanced evaluations. With careful crafting, it's possible to build LLM