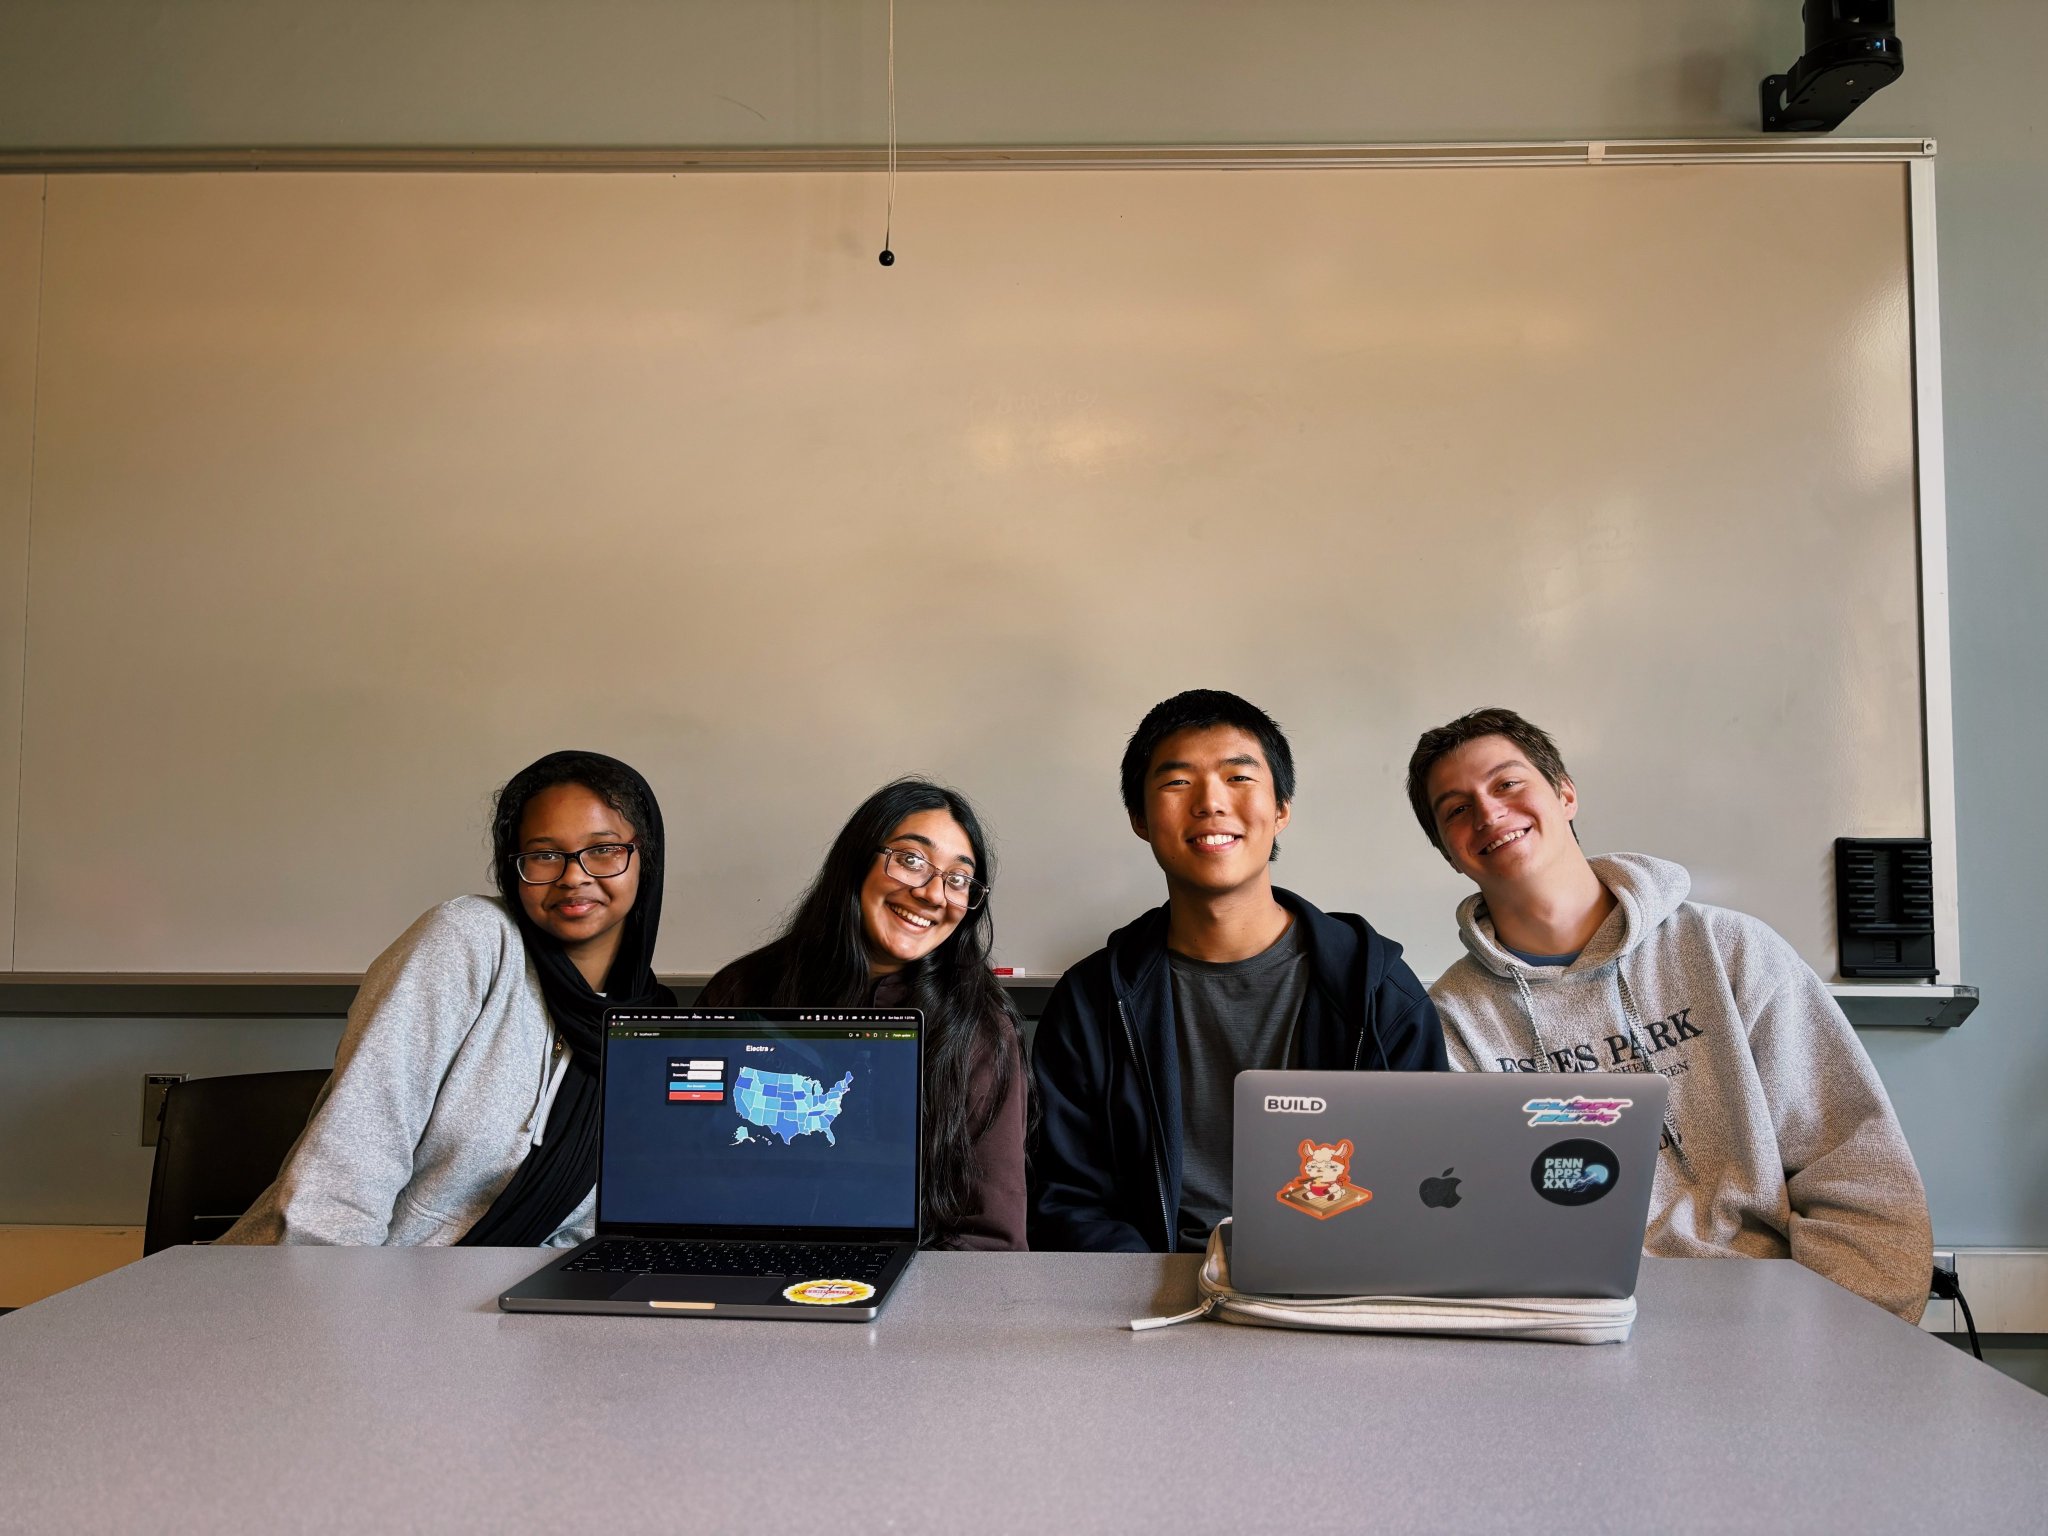
Cerebras just finished an incredible weekend at the PennApps Hackathon! Featured below are the top 3 projects using Cerebras. 1st: Electra – Predict election outcomes accurately and quickly with 100's of LLM agents simulating political scenarios 2nd: Optica – For the blind and
@cerebras
-
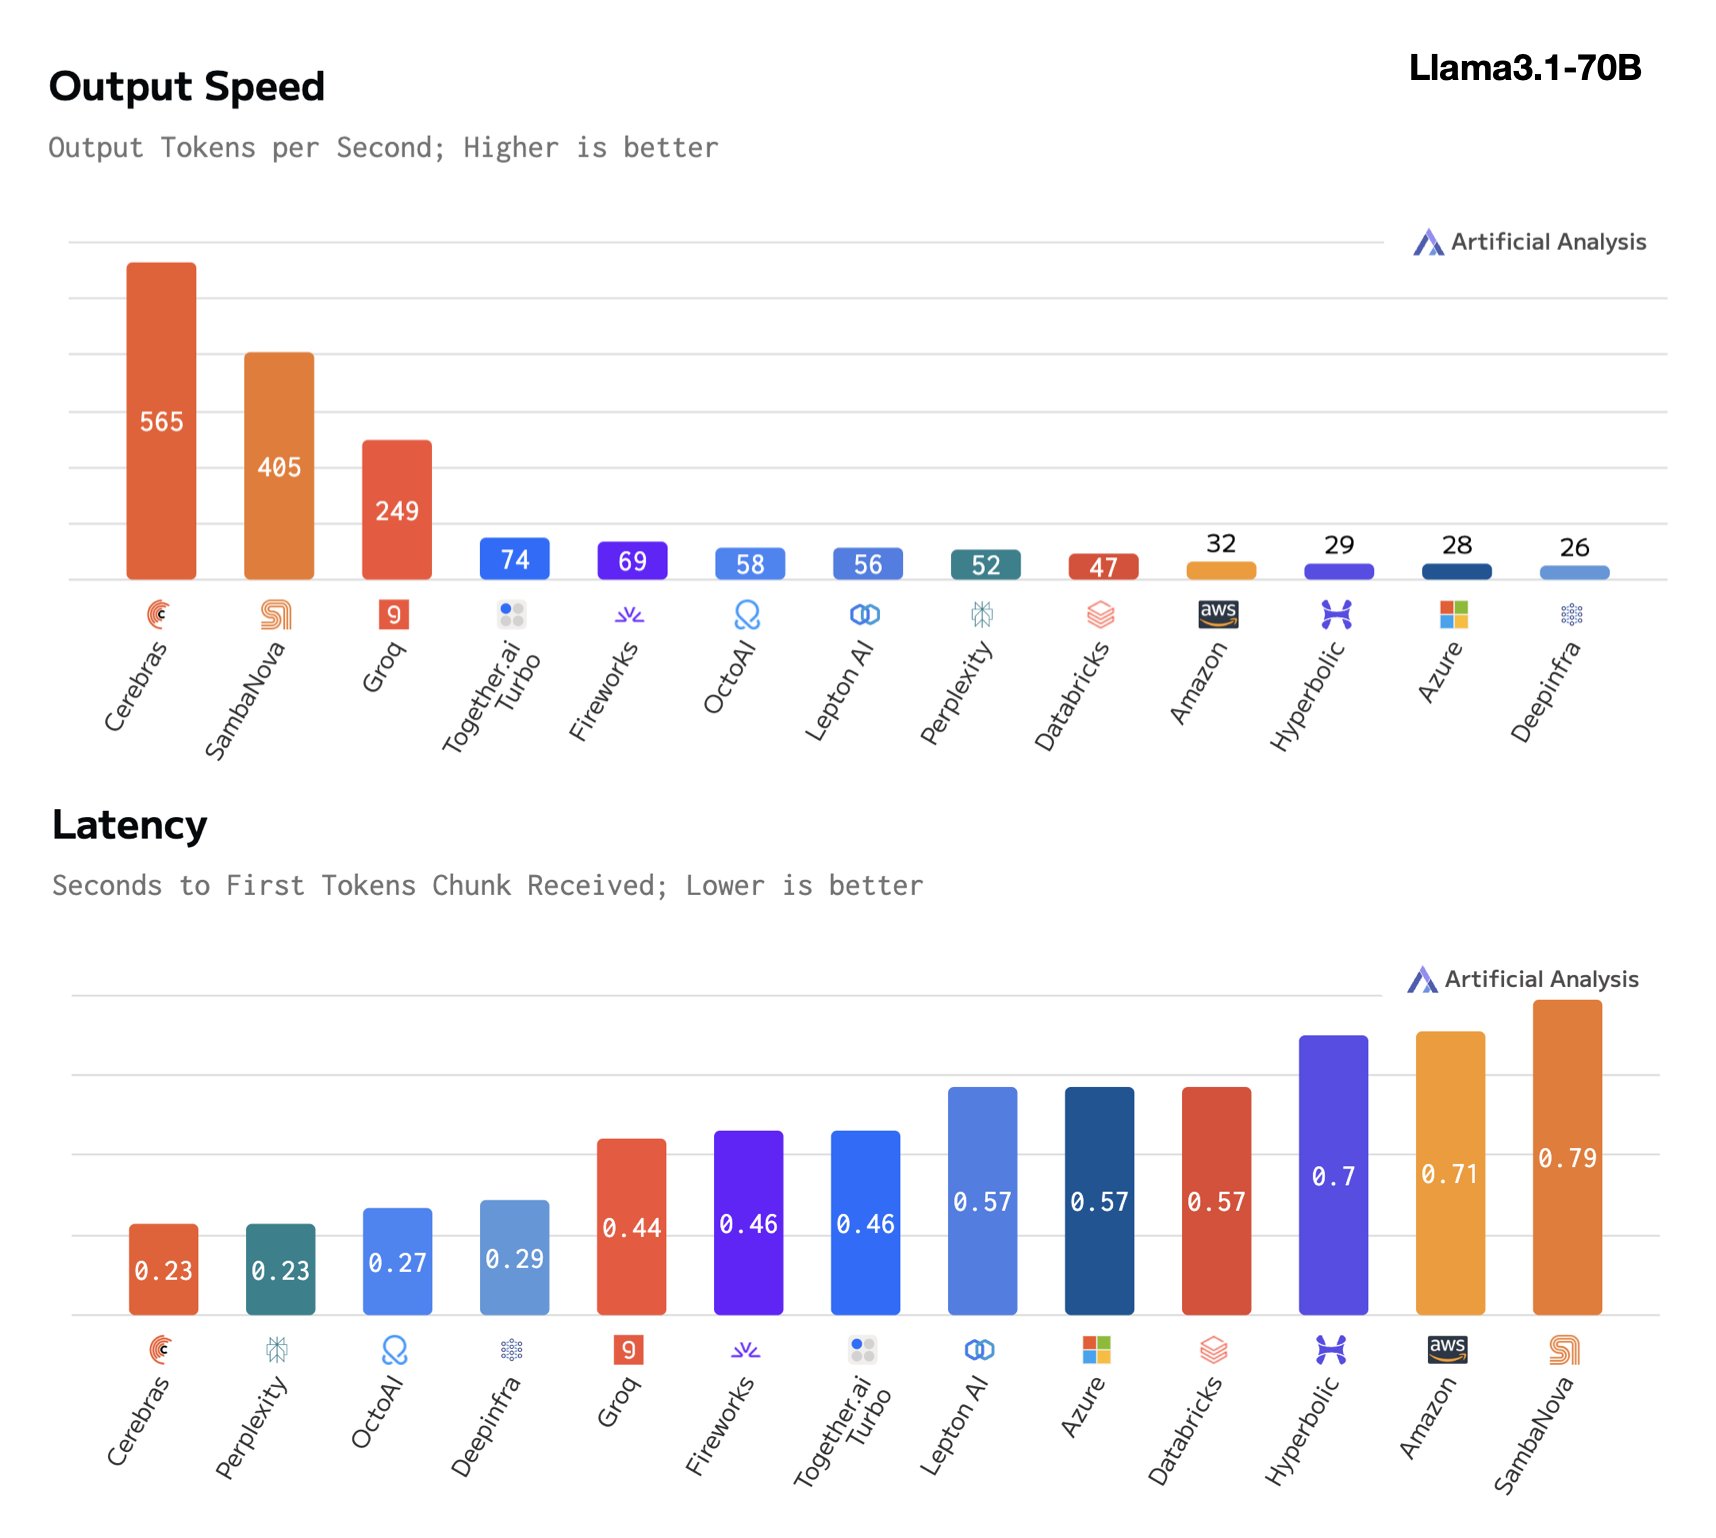
Cerebras Inference delivers highest speed lowest latency
By
–
Cerebras Inference: highest speed, lowest latency. That's it, that's the tweet.
-
Software Optimizations Maintain FP16 Weight Precision
By
–
just software optimizations. still FP16 weights.
-
Compiler Optimizations and Memory Management for FP16 Models
By
–
compiler optimizations, better memory management etc. same FP16 weights.
-
Cerebras Accelerates AI Inference Speed by 10x for Deeper Reasoning
By
–
o1 takes takes multiple minutes for inference. cerebras reduces inference time by 10x
faster inference = deeper CoT / rollouts -
Scaling LLM Training: Double Digit Batch Size for 70B Models
By
–
double digit batch size, eventual goal is one rack for 70B.
-
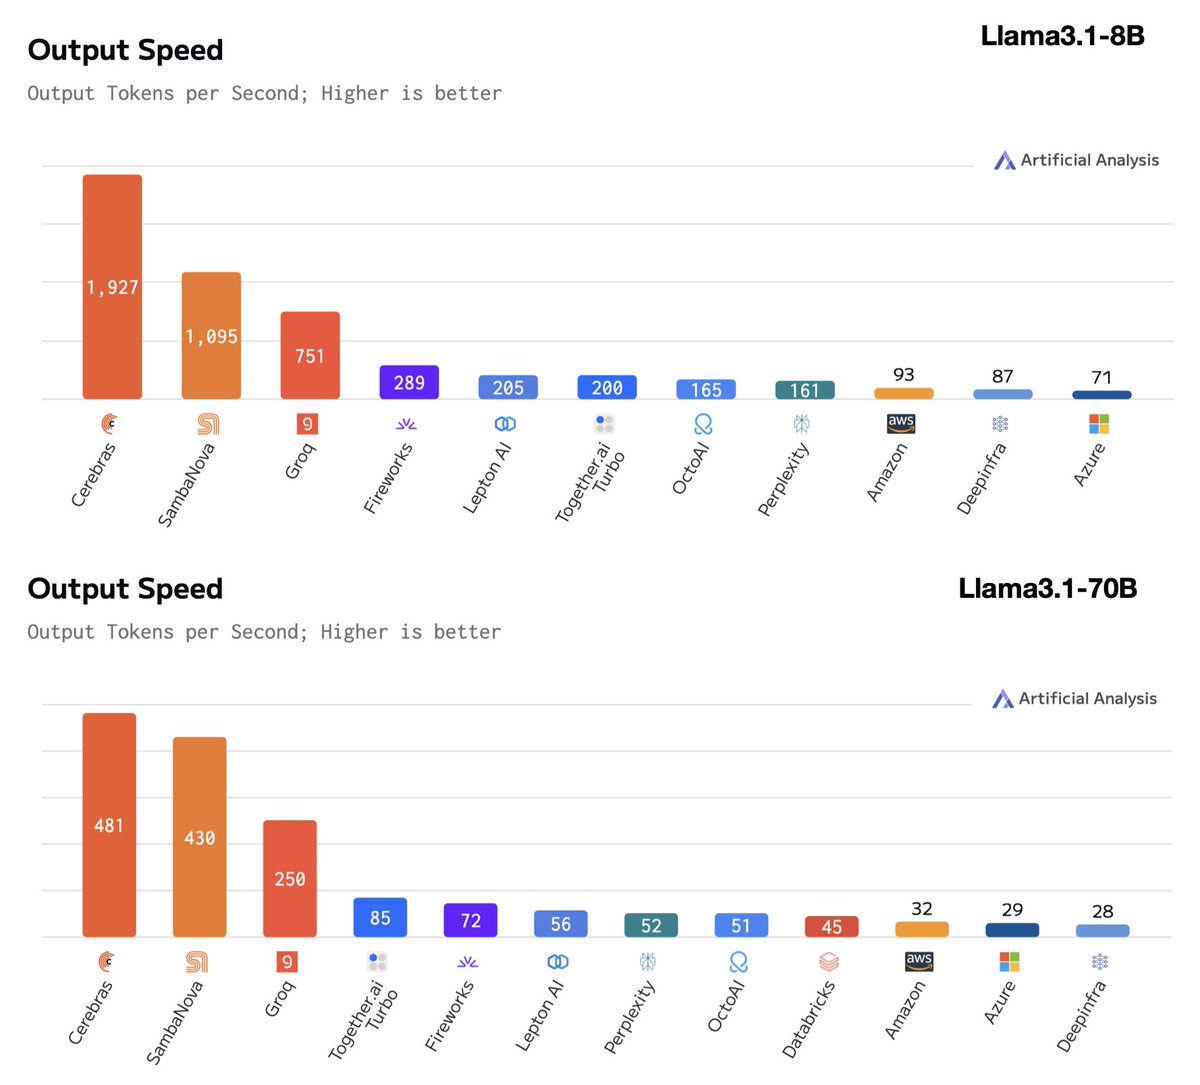
Cerebras Inference Speed Update: Llama 3.1 Performance Benchmarks
By
–
Cerebras Inference perf update:
Llama3.1-8B: 1,8001,927 tokens/s
Llama3.1-70B: 450481 tokens/s
Stillfor the most popular open model in the world. https://
inference.cerebras.ai -
PyTorch Training and CUDA Low Level Optimizations
By
–
Training is already done in PyTorch. CUDA is for low level optimizations.
-
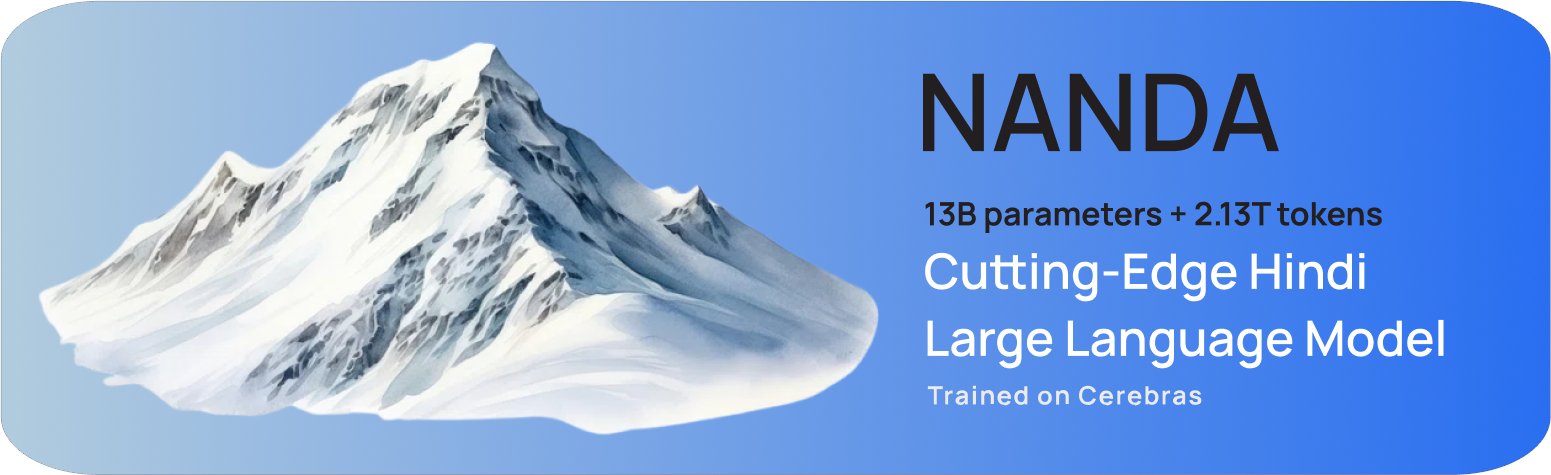
NANDA: Advanced Hindi Large Language Model Unveiled
By
–
Excited to share the development of NANDA, a cutting-edge Hindi Large Language Model, created with our partners G42, Inception, and MBZUAI (Mohamed bin Zayed University of Artificial Intelligence). NANDA was trained on Condor Galaxy, one of the world’s most powerful AI