Cerebras Inference runs 70x faster than GPUs on AWS & Azure. It's so fast it's instant! pic.twitter.com/diPoprDVKz
— Cerebras (@cerebras) 25 octobre 2024
Cerebras Inference runs 70x faster than GPUs on AWS & Azure. It's so fast it's instant!
By
–
Cerebras Inference runs 70x faster than GPUs on AWS & Azure. It's so fast it's instant! pic.twitter.com/diPoprDVKz
— Cerebras (@cerebras) 25 octobre 2024
Cerebras Inference runs 70x faster than GPUs on AWS & Azure. It's so fast it's instant!
By
–
See you at Llamapalooza NYC, we can't wait!@AIatMeta, @Huggingface, and @Cerebrassystems are headlining! pic.twitter.com/8O4JMZmRrY
— Cerebras (@cerebras) 25 octobre 2024
See you at Llamapalooza NYC, we can't wait! @AIatMeta
, @Huggingface
, and @cerebras are headlining!
By
–
After this huge speed update we will be focusing on supporting additional customer models, context, and capacity. Stay tuned for more updates!
Chat: http://
Inference.cerebras.ai
API key: http://
cloud.cerebras.ai
Blog: https://
cerebras.ai/blog/cerebras-
inference-3x-faster
…
By
–
The first release of Cerebras Inference utilized only a fraction of the wafer’s bandwidth, compute, and IO capacity. With this release, we’ve re-written and optimized everything from kernels (matmul, broadcast/reduce) to ML (speculative decoding). Model is still 16-bit and the
By
–
Numerous companies are using Cerebras to make their inference run at instant speed. These include:
– @GSK for drug discovery
– @Livekit for voice AI
– @tavus for digital twins
– @vellum_ai for testing & iteration

By
–
Time to first token is critical for real time applications. Cerebras is among the fastest in first token latency, showing the advantage of wafer scale integration vs. complex networked solutions.
By
–
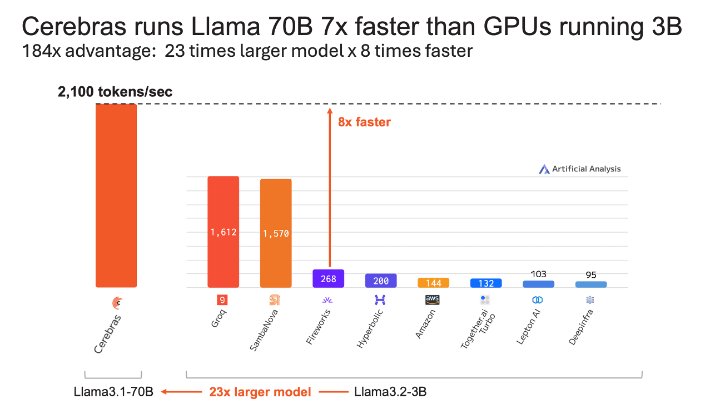
Cerebras Inference running Llama 70B is now so fast that it outruns GPU based inference running Llama 3B. The Wafer Scale Engine runs a model 23x larger and 8x faster for a combined 184x performance gain.

By
–
We broke all records when we launched Cerebras Inference in August. Today we are tripling our performance from 650 t/s to 2100 t/s.
Cerebras Inference speed is in a league of its own – 16x faster than the fastest GPU solution, 68x faster than hyperscale clouds, and 4-8x faster
By
–
🚨 Cerebras Inference is now 3x faster:
— Cerebras (@cerebras) 24 octobre 2024
Llama3.1-70B just broke 2,100 tokens/s
– 16x faster than the fastest GPU solution
– 8x faster than GPUs running Llama *3B*
– It's like the perf of a new hardware generation in a single software release
Available now at… pic.twitter.com/9VgGWGO6qY
Cerebras Inference is now 3x faster: Llama3.1-70B just broke 2,100 tokens/s
– 16x faster than the fastest GPU solution
– 8x faster than GPUs running Llama *3B*
– It's like the perf of a new hardware generation in a single software release
Available now at