
"Claudini: Autoresearch Discovers SoTA Adversarial Attack Algorithms for LLMs" This paper shows that an AI coding agent can autonomously invent jailbreak and prompt-injection attacks, and can even beat 30+ human designed methods. So on top of human red-teamers, the new LLM
@askalphaxiv
-
Foveated Diffusion: Efficient Spatially Adaptive Image Video Generation
By
–
"Foveated Diffusion: Efficient Spatially Adaptive Image and Generation" This paper introduces the logic of human vision to diffusion models, where you generate full detail only when the viewer is looking, and becomes low detail in the periphery. With this setup, you can
-

Google’s KV-Cache Optimization: TurboQuant Vector Quantization Explained
By
–
Google's new KV-cache optimization broke the DRAM stocks, but how does it work? Let's take quick a look. "TurboQuant: Online Vector Quantization with Near-optimal Distortion Rate" TurboQuant combines 2 ideas from 2 earlier lines of work: PolarQuant and Quantized
-
TurboQuant, QJL, PolarQuant: Advanced AI Model Quantization Methods
By
–
TurboQuant: https://
alphaxiv.org/abs/2504.19874 QJL: https://
alphaxiv.org/abs/2406.03482 PolarQuant: https://
alphaxiv.org/abs/2502.02617 -
MiniMax M2.7 Model for Research Paper Understanding Released
By
–
Introducing MiniMax M2.7 for understanding research papers 🚀
— alphaXiv (@askalphaxiv) 26 mars 2026
Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references
Congrats @MiniMax_AI on the new model release! pic.twitter.com/GGctGYHpQGIntroducing MiniMax M2.7 for understanding research papers Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references Congrats @MiniMax_AI on the new model release!
-
Gemini 3 Flash and GPT 5.4 Mini Now Available
By
–
Now available in addition to Gemini 3 Flash and GPT 5.4 mini. Check out http://
alphaXiv.org! -
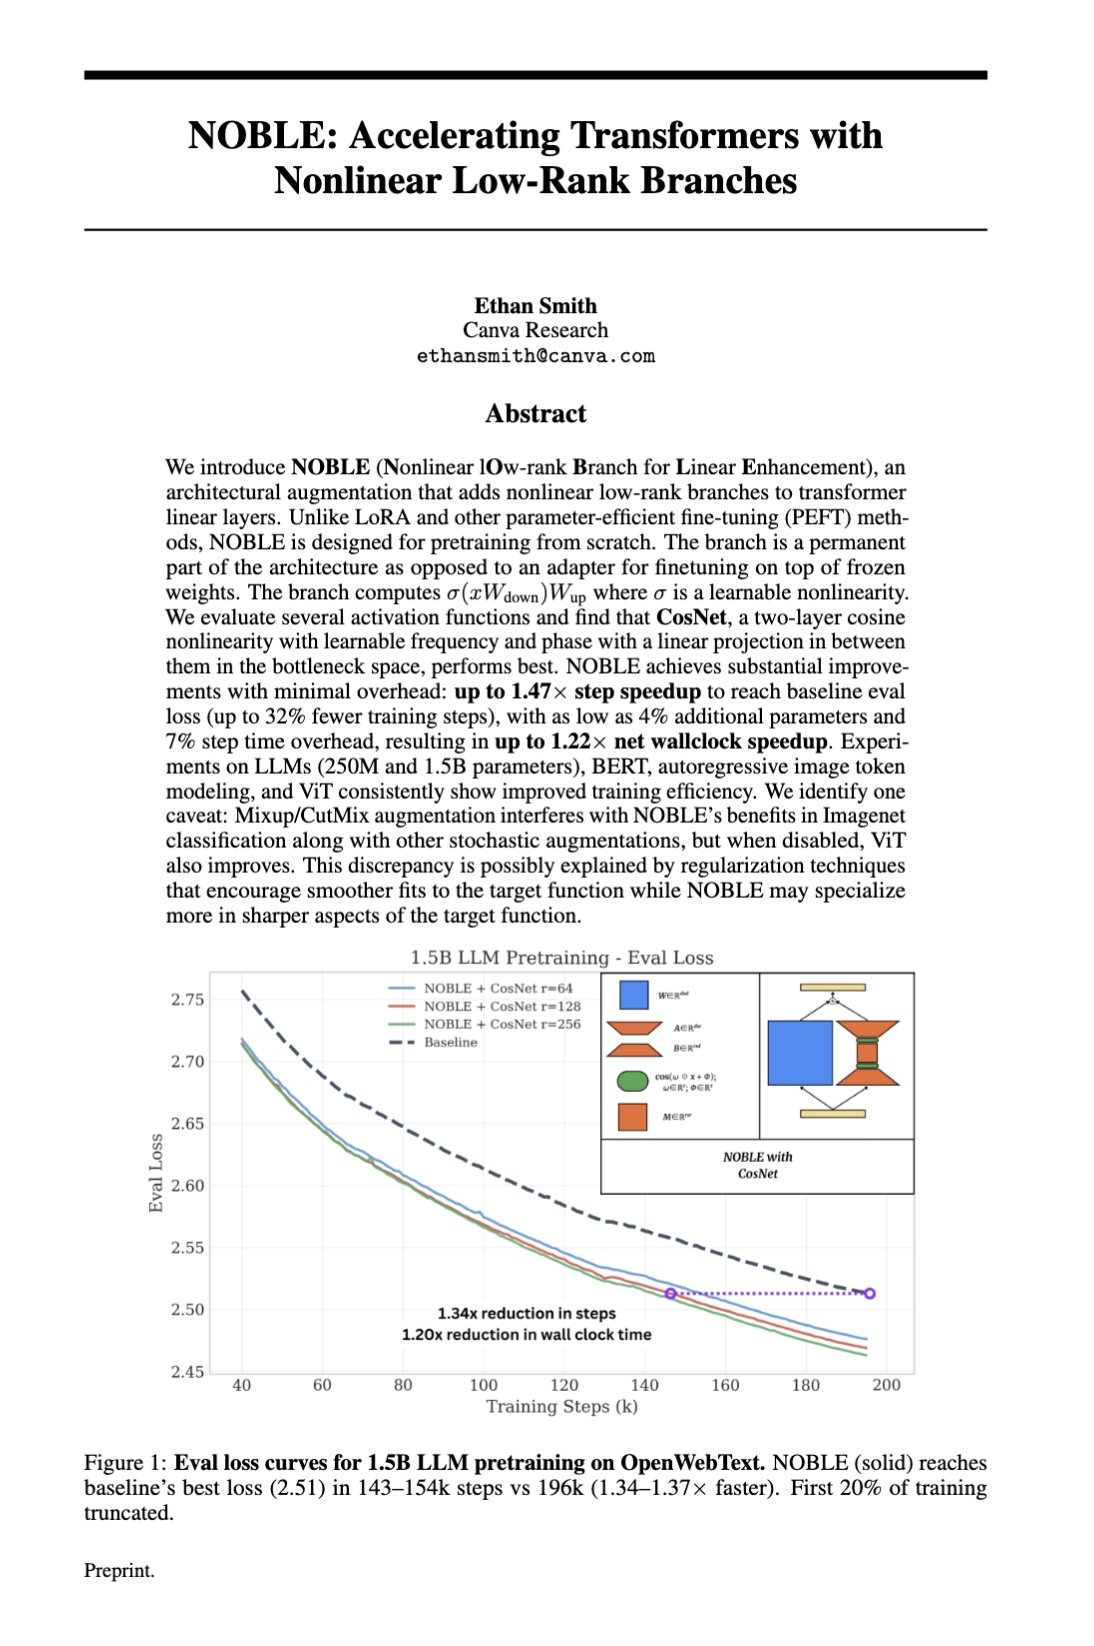
NOBLE: Nonlinear Low-Rank Branches Accelerate Transformers
By
–
"NOBLE: Accelerating Transformers with Nonlinear Low-Rank Branches" This paper shows that if you add a tiny permanent nonlinear low rank branch (with a cosine bottleneck) to each Transformer linear layer, you can teach the model hard-to-fit details much more efficiently. This
-

SAGA: Accelerating Scientific Discovery with Autonomous Goal-evolving Agents
By
–
Agents shouldn’t just optimize goals, they should evolve them Come join us for this AI4Science talk: Accelerating Scientific Discovery with Autonomous Goal-evolving Agents. In this session, one of the authors, Yuanqi Du (
@YuanqiD
), will be introducing SAGA, a framework that