Guadamuz is the OG of Copyright corruption! He knew policymakers would legitimize AI at all costs even before we caught them and documented the process. I'm not saying he's technically or legally corrupt himself, just informally and colloquially I understand why people think so.
@alexjc
-
AI Copyright Lawsuits: Malpractice Claims Against Plaintiff Law Firms
By
–
Plaintiff lawfirms that have not yet replicated such verbatim examples from defendant's models are either unwilling or unable to do the work they were hired for. Either way, it's strong case for malpractice at this stage. ikykyk
-
Copyright memorization in AI models: legal and policy disputes
By
–
Copyrighted information being memorized by models is still contested in courts because it's not treated as a technical nor legal matter, it's a policy question that was unilaterally decided already… (They're expecting everyone to fall in line.) Great thread of examples!
-
UK Government Sued Over Citizen Rights Protection Failures
By
–
Since they admit it now, you need to find someone willing to sue the U.K. government on the basis they're there to protect the rights of citizens, and they're doing the opposite.
-
Company Admits Illegal AI Practice Openly Without Concern
By
–
I love how they're now explicitly admitting it's currently not legal to do so… Yet they don't seem to care.
-
Torch.compile() Outperforms Triton for Kernel Optimization
By
–
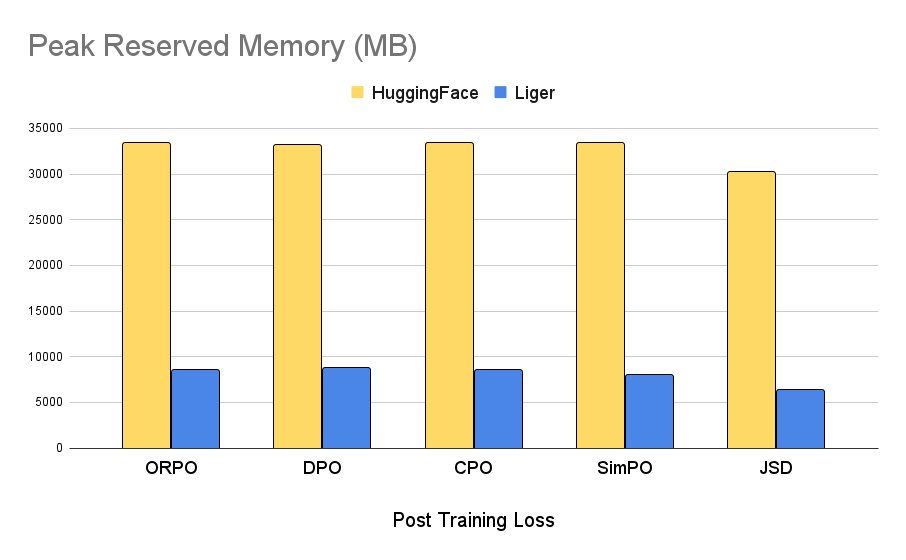
It's interesting that this "kernel" is designed for torch.compile(), so it's Python code but turns out faster! Conversely, some of the other Liger kernels are Triton and I measured them as slower than torch.compile'd versions.
-
Parameter Optimization in Large Language Models
By
–
Got it… Still, if the rule is you have to have <=124M parameters active per token, where did you save those 9216?
-
Model Design Trade-offs: Parameter Count and Efficiency Rules
By
–
Love the idea, fascinating design! But wait, it's almost 3.5x the number of extra active parameters? Doesn't that violate rule 2?
-
Token-level bit efficiency metric for model evaluation
By
–
I need to think about this more, but I'm proposing token-level calculation of that concept: sum(token_bits / token_bytes for _ in all_tokens) … and not: sum(tokens_bits) / sum(tokens_bytes) Because the second one would hide bad predictions for longer tokens in the sum(),
-
Tokenization Boundaries and Cross-Entropy Loss Optimization
By
–
I found the exact tokenization boundary of the text and the corresponding token index. I can do the normalization but it's not perfect… (Testing it shortly.) Computing the cross-entropy like this rewards vocabularies with more tokens and easy predictions (on average) vs.