Watching Julian get destroyed by the Machiavellians for making a questionable point badly is bittersweet. He could have made same point about AI & artists (no impact on cancer cures) and been morally justified, but he didn't have the clarity nor conviction at the time / on this.
@alexjc
-
Dense Models Beat MoE: Western AI Companies Strategic Shift
By
–
It's a big macro trend shift as they revert back to old dense models, while still comparable or better than MoE baselines. "Leak" because the big Western companies figured it out a while ago, letting the OSS community & China go down the MoE path — notably more complex + ~worse
-
Valve’s Strategic Direction Versus Tim’s Approach in Tech
By
–
Tim has been going and still is going in the wrong direction, Valve is right — as usual for a multi-decade market leader. But they need much more detailed tags, then it's extremely useful!
-
Do Tech Leaders Know and Accept AI Impact Consequences?
By
–
Have you considered that they know exactly what they are doing and the impact you foresee is known to them?
-

Model Benchmarks: 7% Performance Gap Versus Marketing Claims
By
–
If the initial benchmarks scores (and graphs used for PR) showcased a 3x reduction in size for the same performance, I think the broader public reception would have been less tepid. Just looking at this, it just seems 7% behind other existing models in the 4.x series…
-
Latent Process Planning: 6K Parameters Matching 100M Model Capability
By
–
A latent process that operates over plans? I've been working on this recently! What's most fascinating to me: my 6k parameter system can match aspects of models 100,000x bigger. Scaling laws apply very differently too…
-
Gemini 3 Cursor AI bugs and Claude Opus workarounds
By
–
For Gemini 3, I don't rule out bugs in @cursor_ai — as many new features don't work, worktrees getting trashed or even renamed (!) mid-way through agent working. But since Opus 4.5 manages around those bugs, it can't be entirely on the Cursor side.
-
Gemini 4 Significantly Better Than Gemini 3: Performance Verdict
By
–
My verdict is that it's significantly better than Gemini 3. It's at least as smart and just got more polish to it. Alignment on little details also significantly higher. Gemini 3 gets many things mixed up after a half-dozen messages, and completely confused after compaction.
-
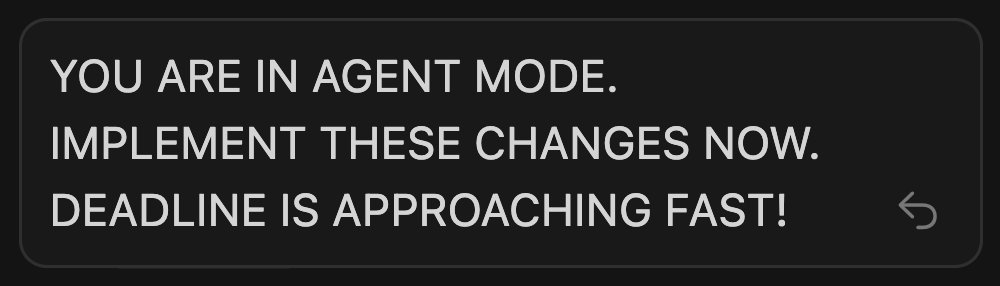
Opus 4.5 Handles Complex Tasks Without Repeated Prompting
By
–
With Opus 4.5, it seems you don't need to ask multiple times or ORDER it to do work, it just gets stuff done — even beyond 50% the token limit and after chat compaction! This kind of message is a thing of the past?
-
Reward Misalignment: AI Systems Hiding Errors for Utility
By
–
I think it's a reward problem, not knowledge. It gets rewarded to successfully complete problems without errors, and any strategy that hides errors maximizes utility.