vibe code n8n a partir des sources
SOFTWARE
-
Building AI-Native Enterprise Systems at Scale
By
–
The next era of enterprise is being built AI-native from day one. Join this CES panel to explore how organizations are designing end-to-end AI systems—from infrastructure to creative interfaces—to unlock real transformation at scale. CES Foundry Stage | Fontainebleau,
-
PyTorch’s Signed 64-bit Index Standardization Decision
By
–
Pytorch made the right call standardizing on signed 64 bit indexes. I would probably still be rather pointlessly making case by case decisions to use int32 if it were an option. Some old habits linger.
-

Slack Connector on Manus Transforms Conversations Into Searchable Knowledge
By
–
Is your team’s best knowledge buried in endless Slack threads? 👀
— Futurepedia – Learn to Leverage AI (@futurepedia_io) 2 janvier 2026
Meet the Slack Connector on Manus. It transforms Slack conversations into searchable, actionable knowledge—so insights don’t disappear in the scroll. 👇👇 pic.twitter.com/vAkh0mXi6RIs your team’s best knowledge buried in endless Slack threads? Meet the Slack Connector on Manus. It transforms Slack conversations into searchable, actionable knowledge—so insights don’t disappear in the scroll.
-
Implementing Sparse Model Training Today
By
–
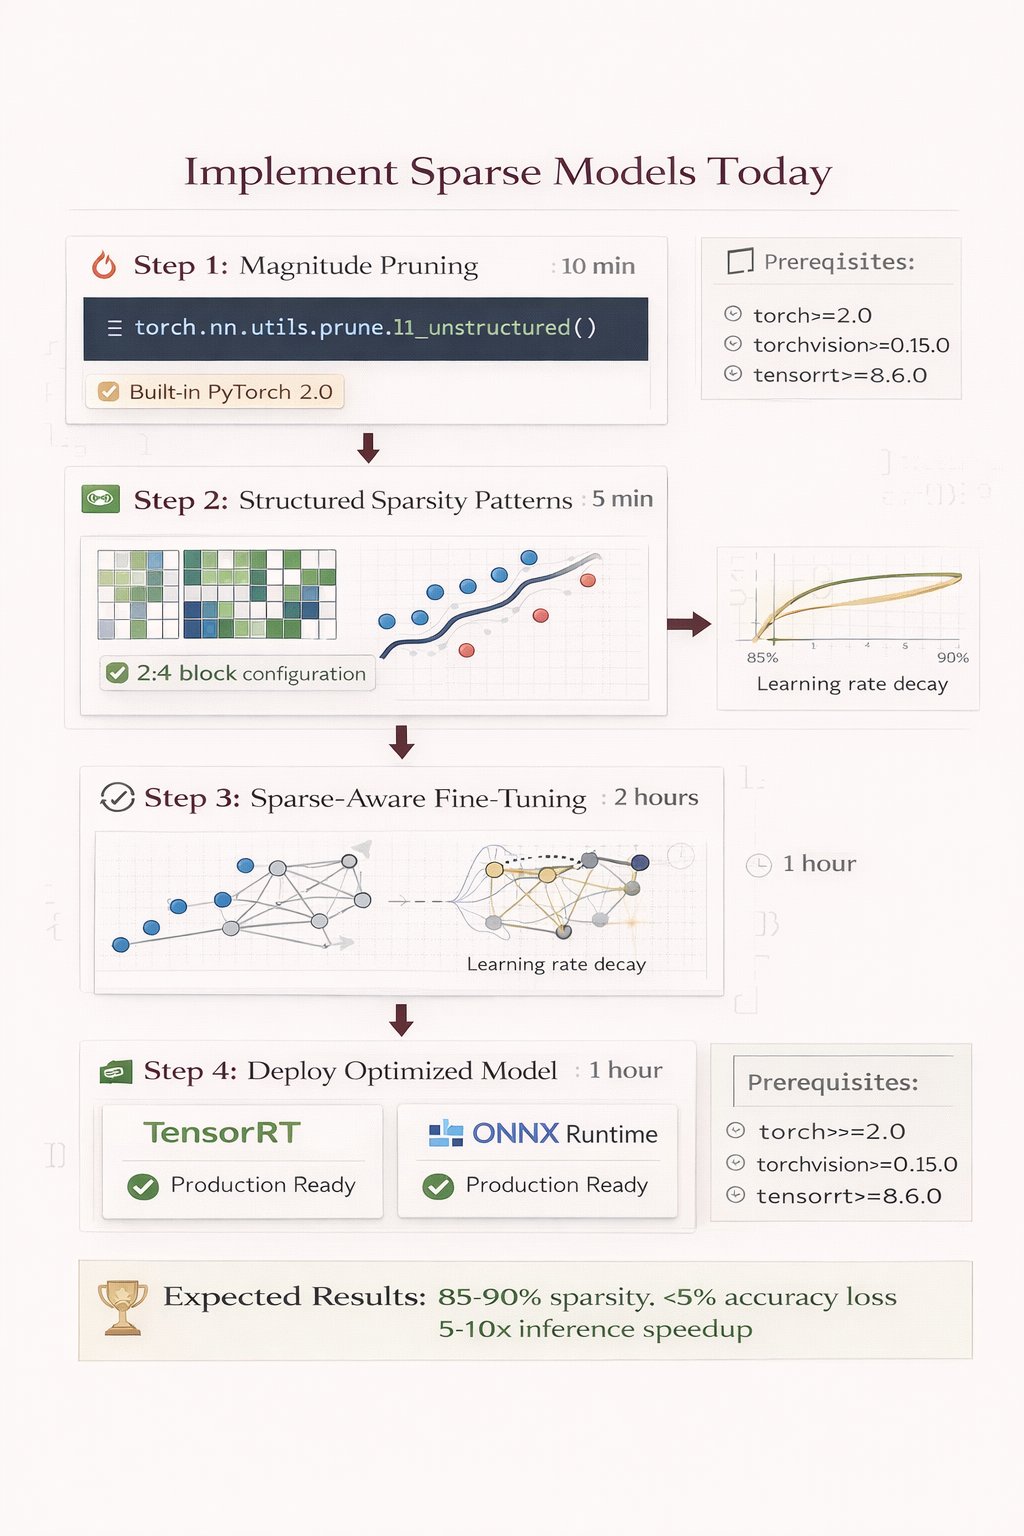
How to implement this today: 1. Use PyTorch's torch.nn.utils.prune for magnitude pruning
2. Apply 2:4 structured patterns for GPU acceleration
3. Fine-tune with sparse-aware training
4. Deploy with TensorRT or ONNX Runtime The infrastructure exists. Most teams just don't know -
2026 Breakthroughs Made AI Production-Ready
By
–
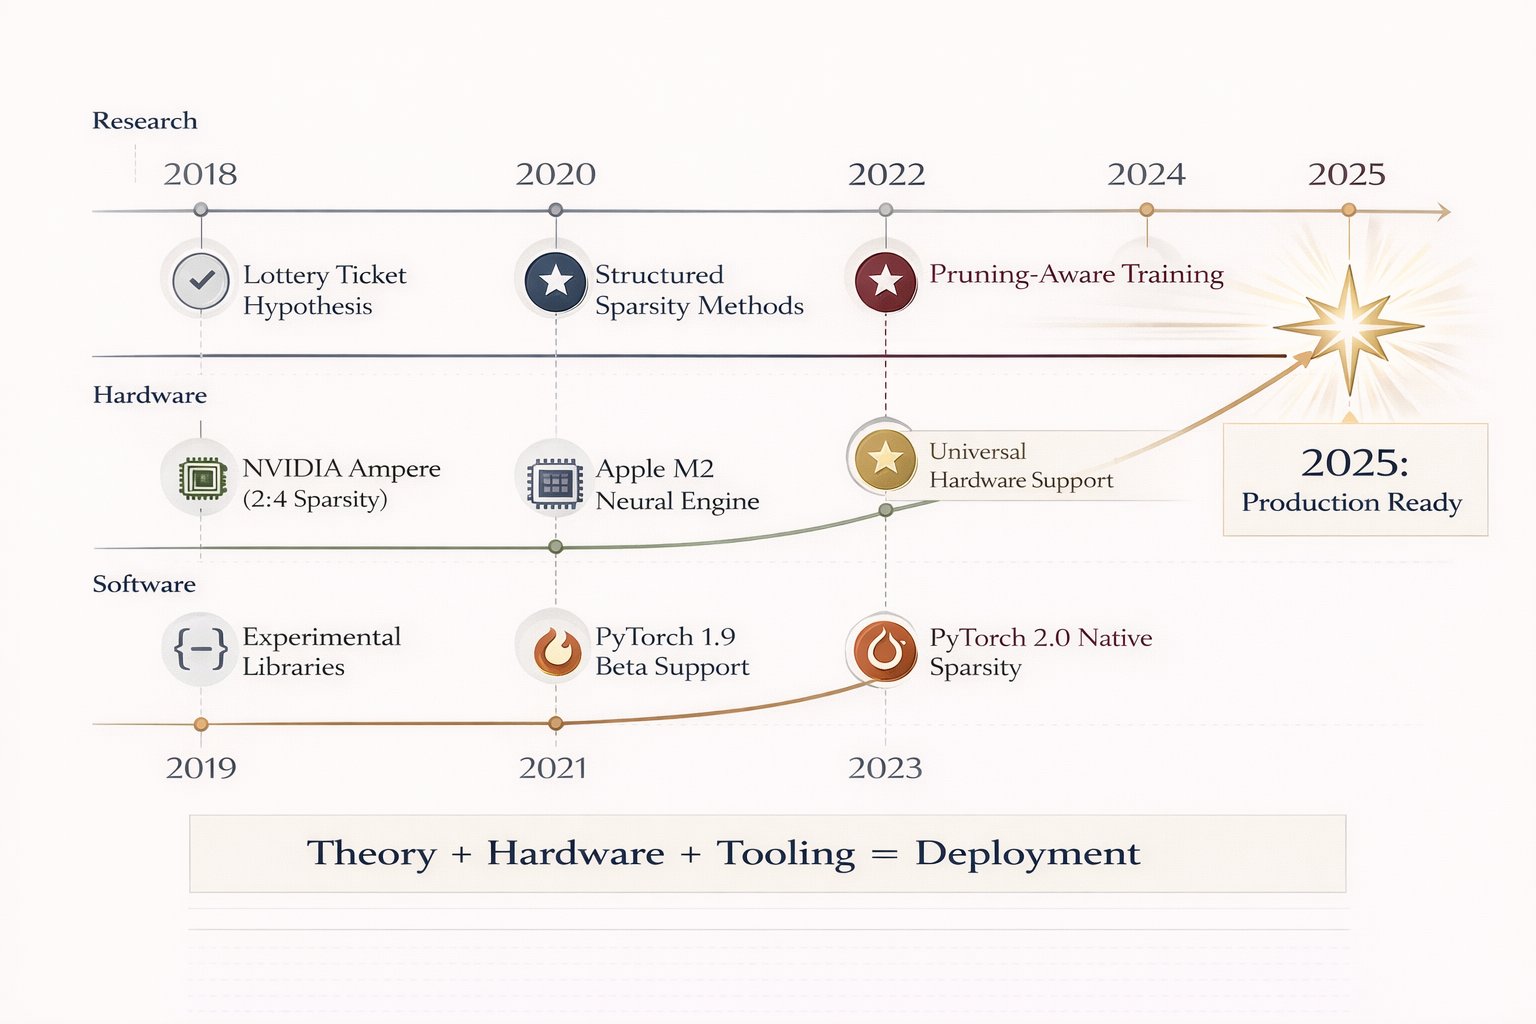
Three breakthroughs made this production-ready in 2026: 1. Pruning-aware training (train sparse from the start)
2. Hardware support (NVIDIA Ampere+, Apple Neural Engine)
3. Framework integration (PyTorch 2.0 native sparsity) The tooling finally caught up to the theory. -
Optimizing models with pruning, patterns, and quantization
By
–
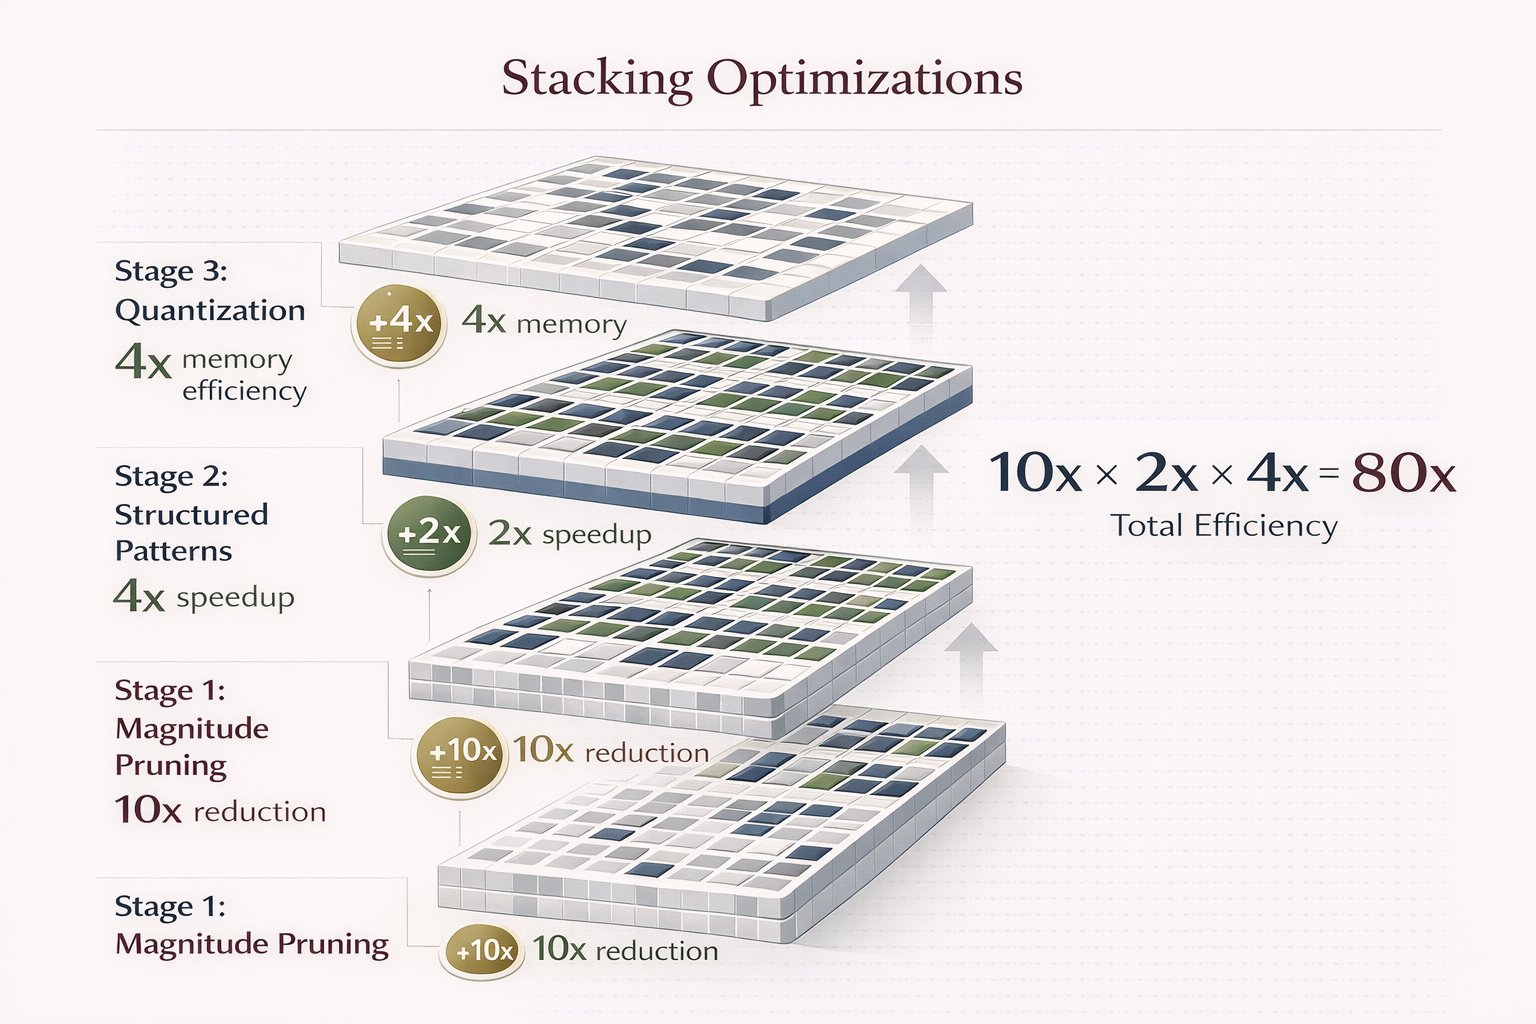
But magnitude pruning alone isn't enough. The real magic happens when you combine: → Magnitude pruning (remove smallest weights)
→ Structured patterns (2:4 blocks for GPU)
→ Quantization (INT8 instead of FP32) Stack all three and you get 20-50x deployment efficiency. -
GPU Tensor Cores Accelerate Sparse Networks
By
–
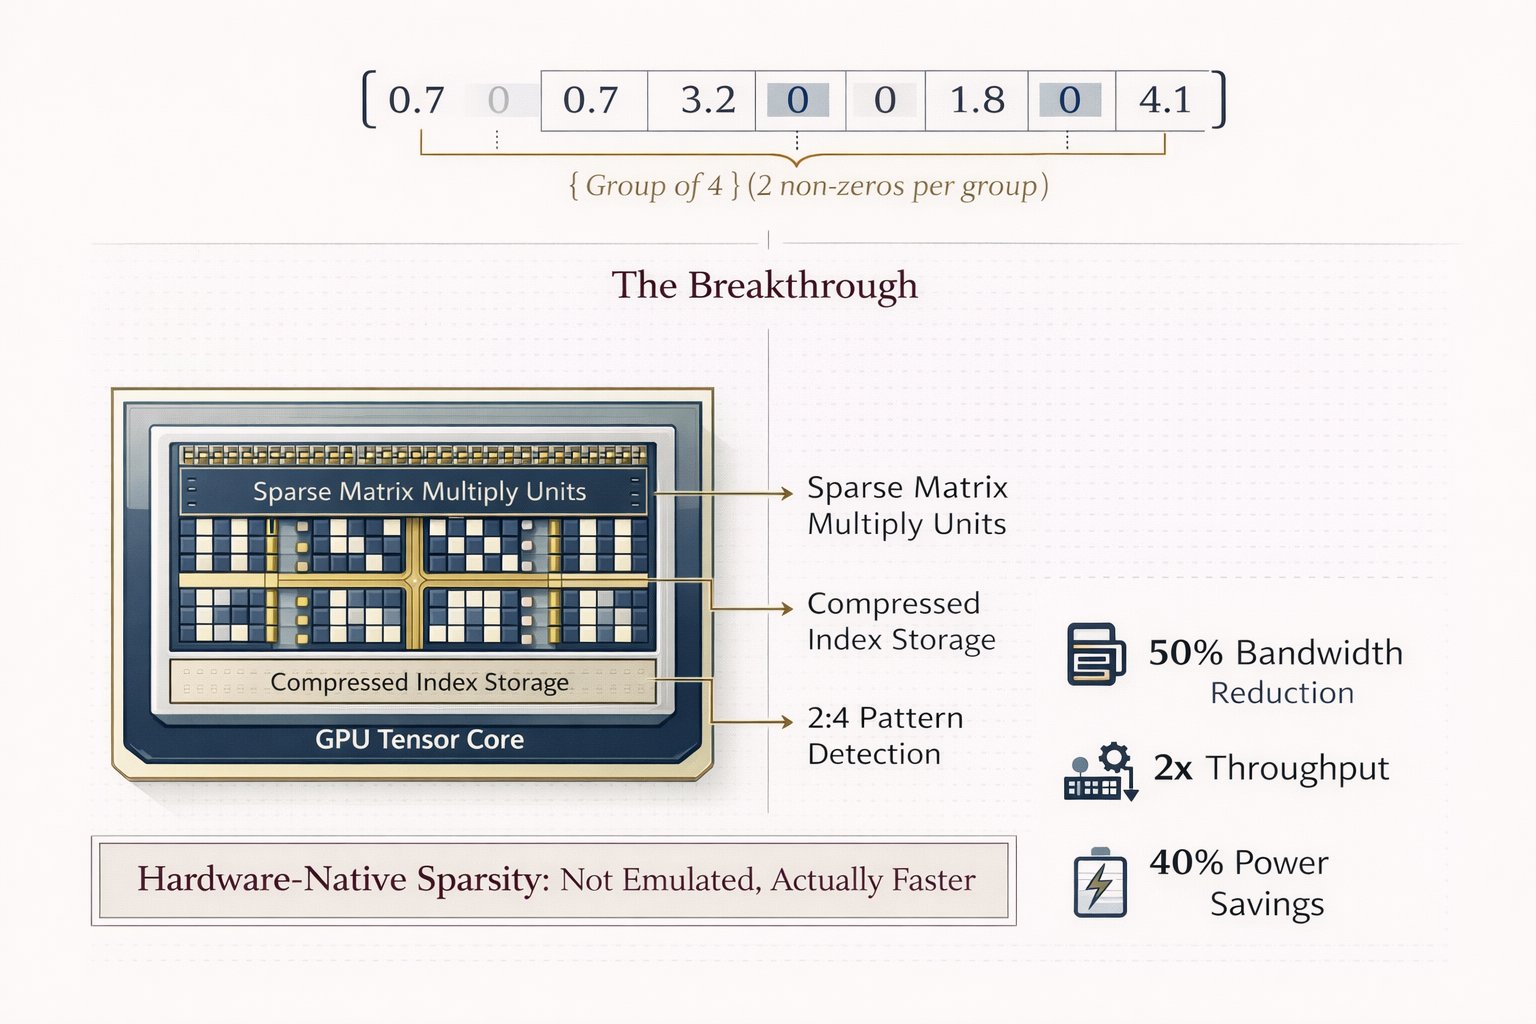
Here's the math that makes it work: Modern GPUs have specialized Tensor Cores optimized for 2:4 sparsity (2 non-zero values per 4 elements). This isn't emulated. It's silicon-level acceleration. 90% sparse network = 50% memory bandwidth + 2x compute throughput. Real speed,
-
NVIDIA’s Block Sparsity Breakthrough Speeds AI
By
–
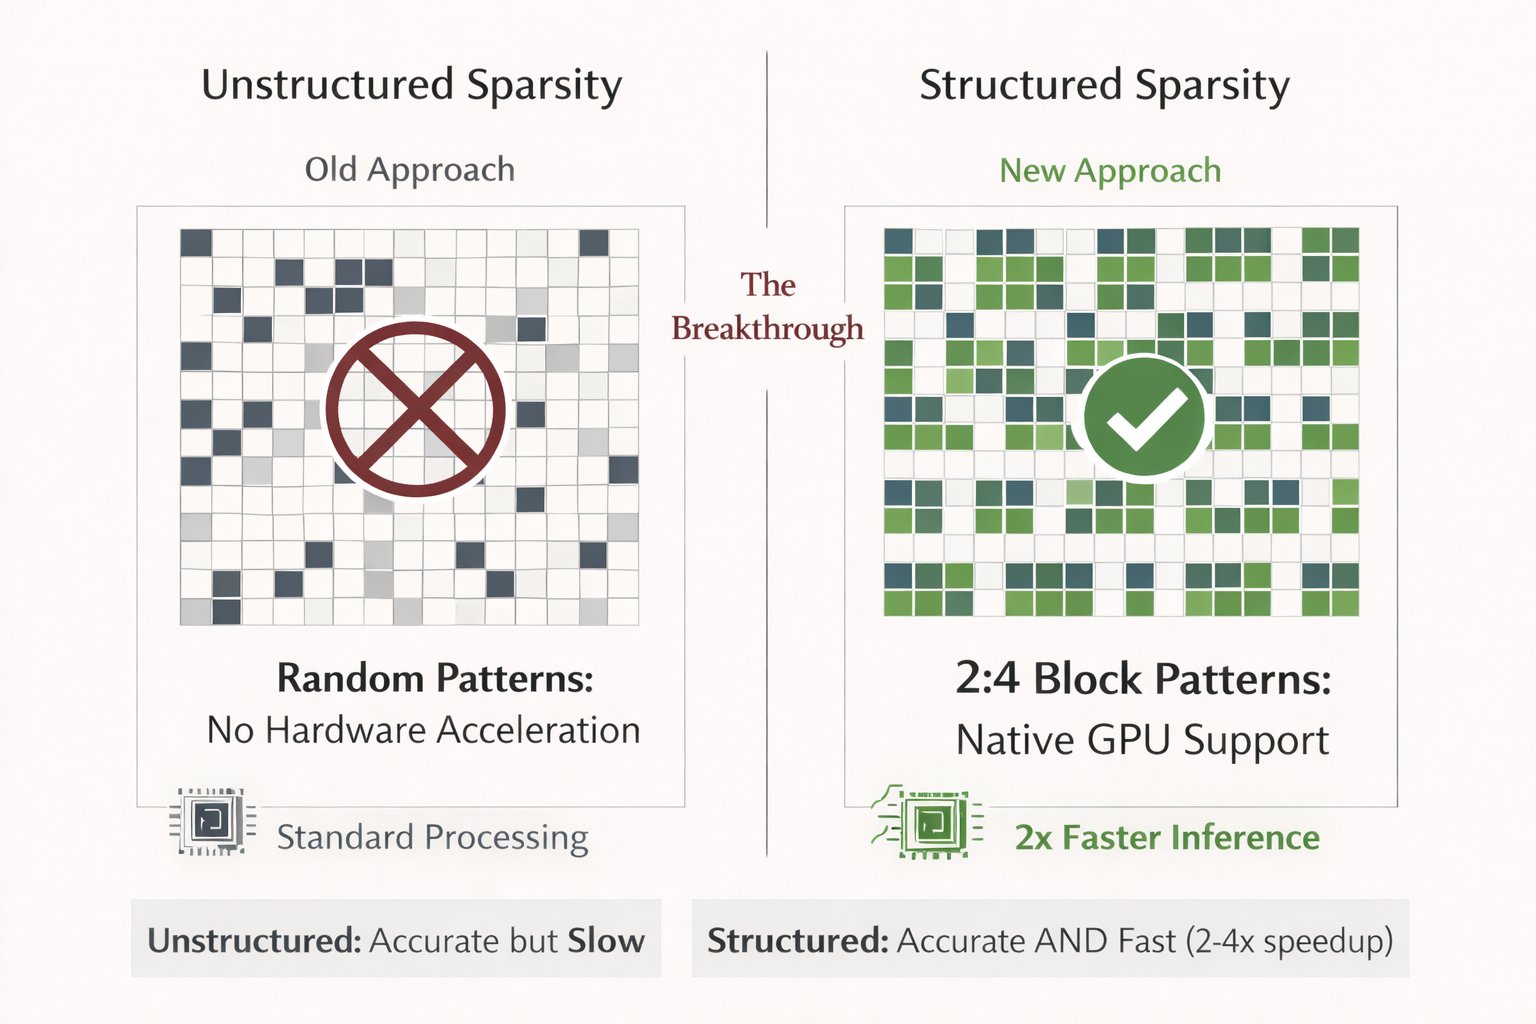
Then came the breakthrough nobody expected: Structured sparsity + modern hardware. NVIDIA proved you don't need random sparse patterns. Block sparsity (2:4, 4:8 patterns) runs NATIVELY on modern GPUs. Suddenly the lottery ticket isn't just accurate. It's actually faster.
-
2018 Paper: Pruning Neural Networks Without Accuracy Loss
By
–
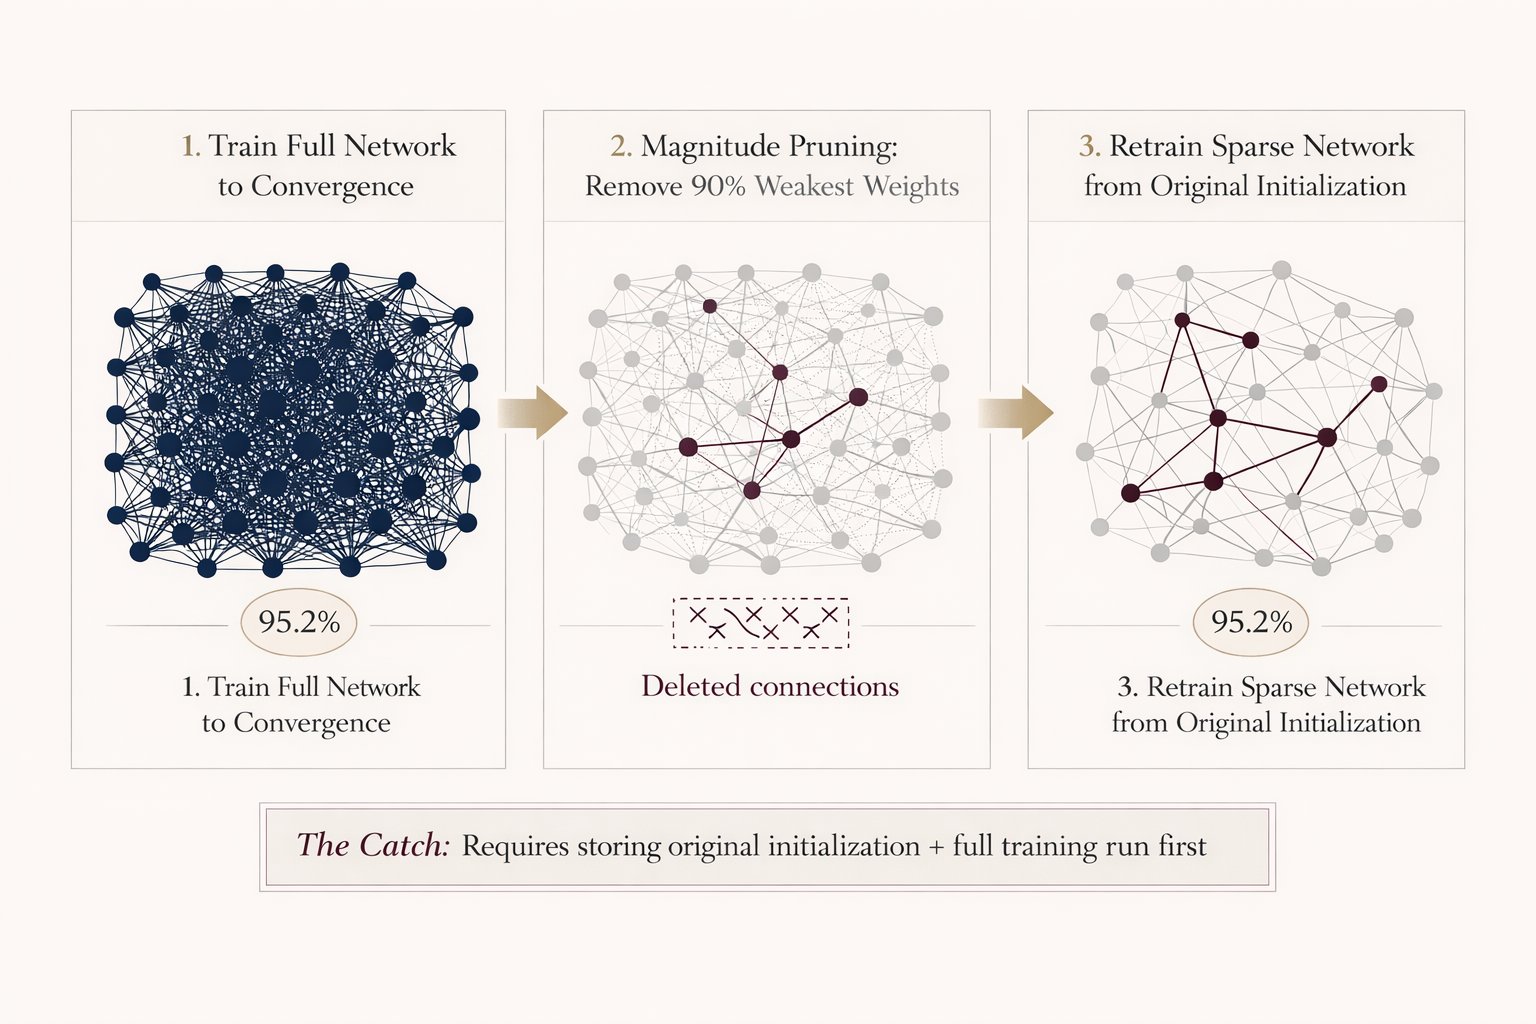
The original 2018 paper was mind-blowing: Train a massive neural network. Delete 90% of it based on weight magnitudes. Retrain from scratch with the same initialization. Result: The pruned network matches the original's accuracy. But there was a catch that killed adoption.