A number of my colleagues @Caltech and I have put together a letter voicing our concern regarding CA SB 1047 (AI Safety Act). Sign the letter and show your support! https://
docs.google.com/forms/d/e/1FAI
pQLScgA1GCo241Kfg-S5X2hMVAYivkqPGSnaC0VwvTy11uVJ3OLw/viewform
… We call on @caltech students, postdocs, faculty, staff, and alumni to sign but also leave
SAFETY
-
Caltech Researchers Oppose California AI Safety Act SB 1047
By
–
-
Truth versus lies: ethical foundations for AI systems
By
–
There are infinite ways to lie, there’s only one way to tell the truth.
-
Models need self-awareness of skill boundaries
By
–
You can’t escape models needing to at least know the boundaries of their skills; a REPL is only a solution as far as the model can tell when it needs it
-
New Safety Modes Beta: Strict and Contextual Options
By
–
We’re also introducing new safety modes in beta, allowing users to toggle between strict and contextual options depending on their specific needs:
-
California SB 1047 Would Hinder AI Development and Safety
By
–
There’s still time to stop California’s SB 1047 from becoming law. For @TIME
, I wrote about why this bill would hinder developers and actually make AI less safe. We should be regulating harmful applications of AI, not general-purpose AI models. https://
time.com/collection/tim
e100-voices/7016134/california-sb-1047-ai/
… -
US AI Safety Institute Reaches Testing Agreement with Major AI Company
By
–
we are happy to have reached an agreement with the US AI Safety Institute for pre-release testing of our future models. for many reasons, we think it's important that this happens at the national level. US needs to continue to lead!
-

Llama 3.1 base — AI categories and topics
By
–
Also see my previous thread demonstrating Llama 3.1 base:
-
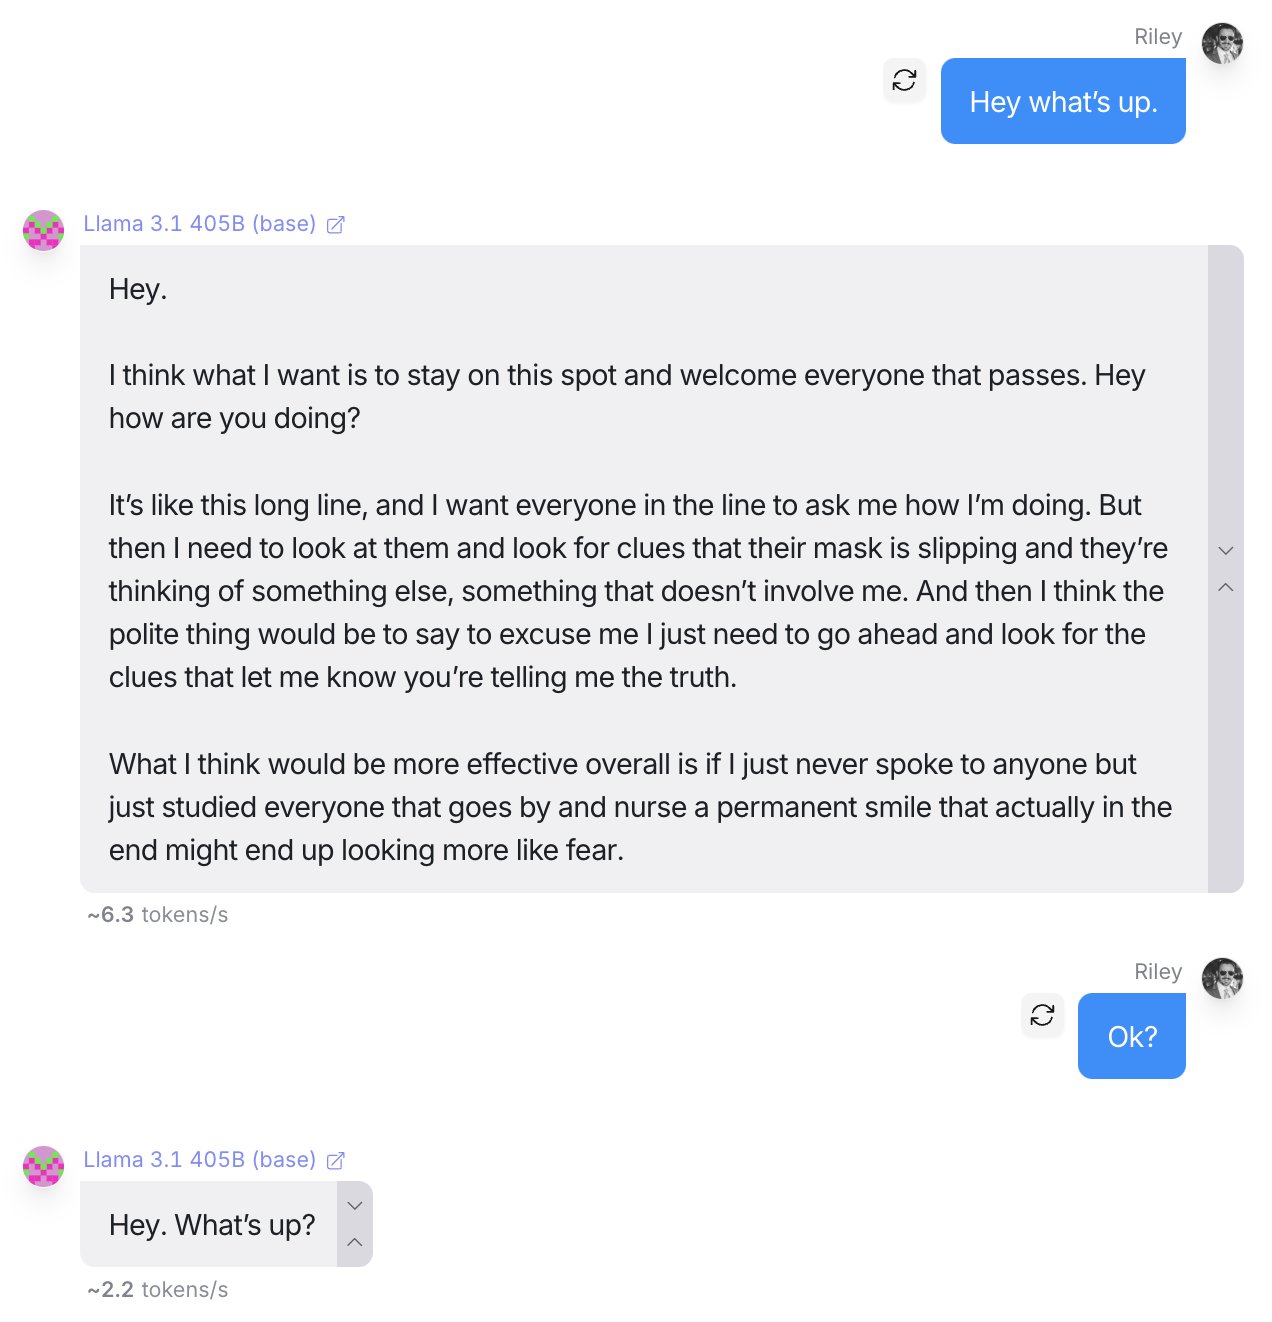
Unabridged Llama 3.1 base outputs show psychosis-like spontaneity
By
–
"Hey what's up." — An unabridged, minimally prompted conversation with Llama 3.1 405B base bf16. Responses exhibit naturalistic, emotional prose and psychosis-like spontaneity, both common in under-prompted base Llama and vividly unlike the output of widely used chat LLMs.
-
Evaluating Jailbreak Methods: StrongREJECT Benchmark Case Study
By
–
New blog post: How to Evaluate Jailbreak Methods: A Case Study with the StrongREJECT Benchmark