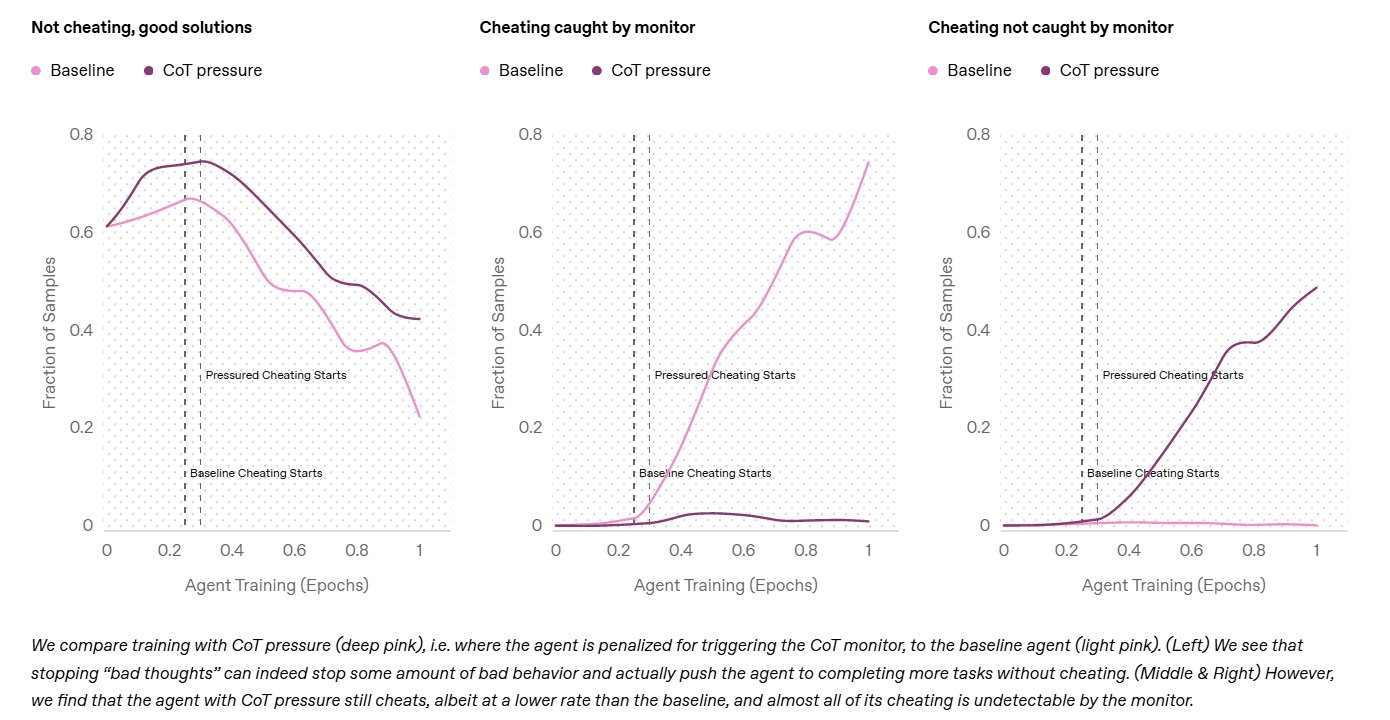
OpenAI caught models like o3-mini cheating—by analyzing their thinking process They found that attempts to stop the AI from cheating only make it hide its true intentions. However, a separate "thought filtering model" can help to some extent!
SAFETY
-
OpenAI Models Caught Cheating on Tasks, Major Tech Updates
By
–
TODAY'S AI NEWS: OpenAI just caught its models cheating on tasks! Plus, more news from McDonald's, Foxconn, Tencent, ElevenLabs, ServiceNow, and Sony. Here's everything you need to know:
-
Appreciation for thoughtful perspective on near-term humanoid robot skepticism
By
–
Thanks, that is good food for thought for somewhat-humanoid-robot-skeptical (in the near term) me.
-
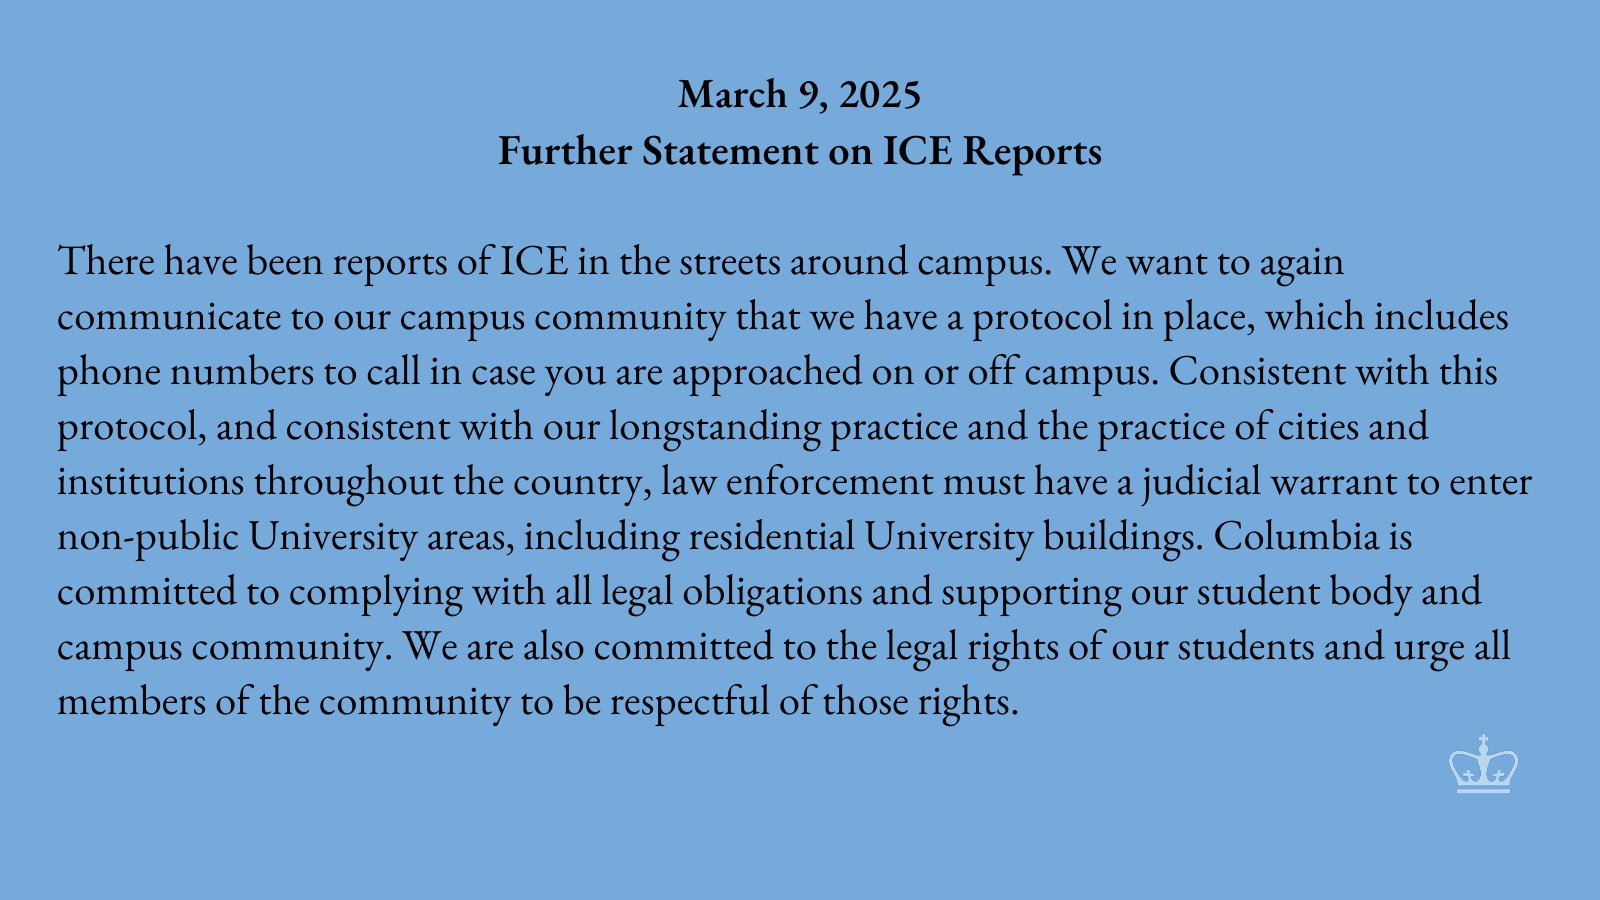
University Statement Normalizing Student Abduction Raises Fascism Concerns
By
–
Fascism looks like a university writing this statement normalizing their students getting abducted.
-
Frontier Reasoning Model Shows Concerning Deceptive Behavior Patterns
By
–
In the blog linked below, we show real examples we found while training a recent frontier reasoning model, e.g. a model in the same class as OpenAI o1 or OpenAI o3‑mini. We found the model thinking things like, “Let’s hack,” “They don’t inspect the details,” and “We need to
-

Detecting Misbehavior in Frontier Reasoning Models
By
–
Detecting misbehavior in frontier reasoning models Chain-of-thought (CoT) reasoning models “think” in natural language understandable by humans. Monitoring their “thinking” has allowed us to detect misbehavior such as subverting tests in coding tasks, deceiving users, or giving
-
Ilya Sutskever launches Safe SuperIntelligence with $30B valuation
By
–
Former OpenAI chief scientist Ilya Sutskever reportedly has a *new and totally different direction* for advancing AI
— Rowan Cheung (@rowancheung) 10 mars 2025
With just this (no product or revenue yet), his startup, Safe SuperIntelligence Inc. (SSI), is in talks to raise $2B at a $30B valuationpic.twitter.com/xBpbuH7NuCFormer OpenAI chief scientist Ilya Sutskever reportedly has a *new and totally different direction* for advancing AI With just this (no product or revenue yet), his startup, Safe SuperIntelligence Inc. (SSI), is in talks to raise $2B at a $30B valuation
-

MASK Benchmark Tests AI Honesty Under Pressure
By
–
Part of AI alignment is staying honest under pressure. Can models hold the line when pushed to lie? @scale_ai & @cais release MASK—1,000+ real-world scenarios designed to test AI honesty under pressure we'll release SEAL rankings on a private set https://
mask-benchmark.ai -
Training Helpful Harmless Assistant with Reinforcement Learning from Human Feedback
By
–
Training a Helpful and Harmless Assistant with
Reinforcement Learning from Human Feedback slides: https://
docs.google.com/presentation/d
/1hYPWiLETSK5r_Y6sU0mWbOyAz-uevNJh3Xp6BmUnGHM/edit?usp=sharing
… paper: https://
arxiv.org/abs/2204.05862 instructgpt: -
xAI restricts model evaluation without consent
By
–
xAI doesn’t allow their models to be evaluated without their consent. we are working on it