GPT-4.1 and GPT-4.1 mini underwent our standard safety evaluations. Detailed results are available in the newly launched Safety Evaluations Hub.
SAFETY
-
Safety Evaluations Hub Launches for AI Model Transparency
By
–
Introducing the Safety Evaluations Hub—a resource to explore safety results for our models. While system cards share safety metrics at launch, the Hub will be updated periodically as part of our efforts to communicate proactively about safety.
-
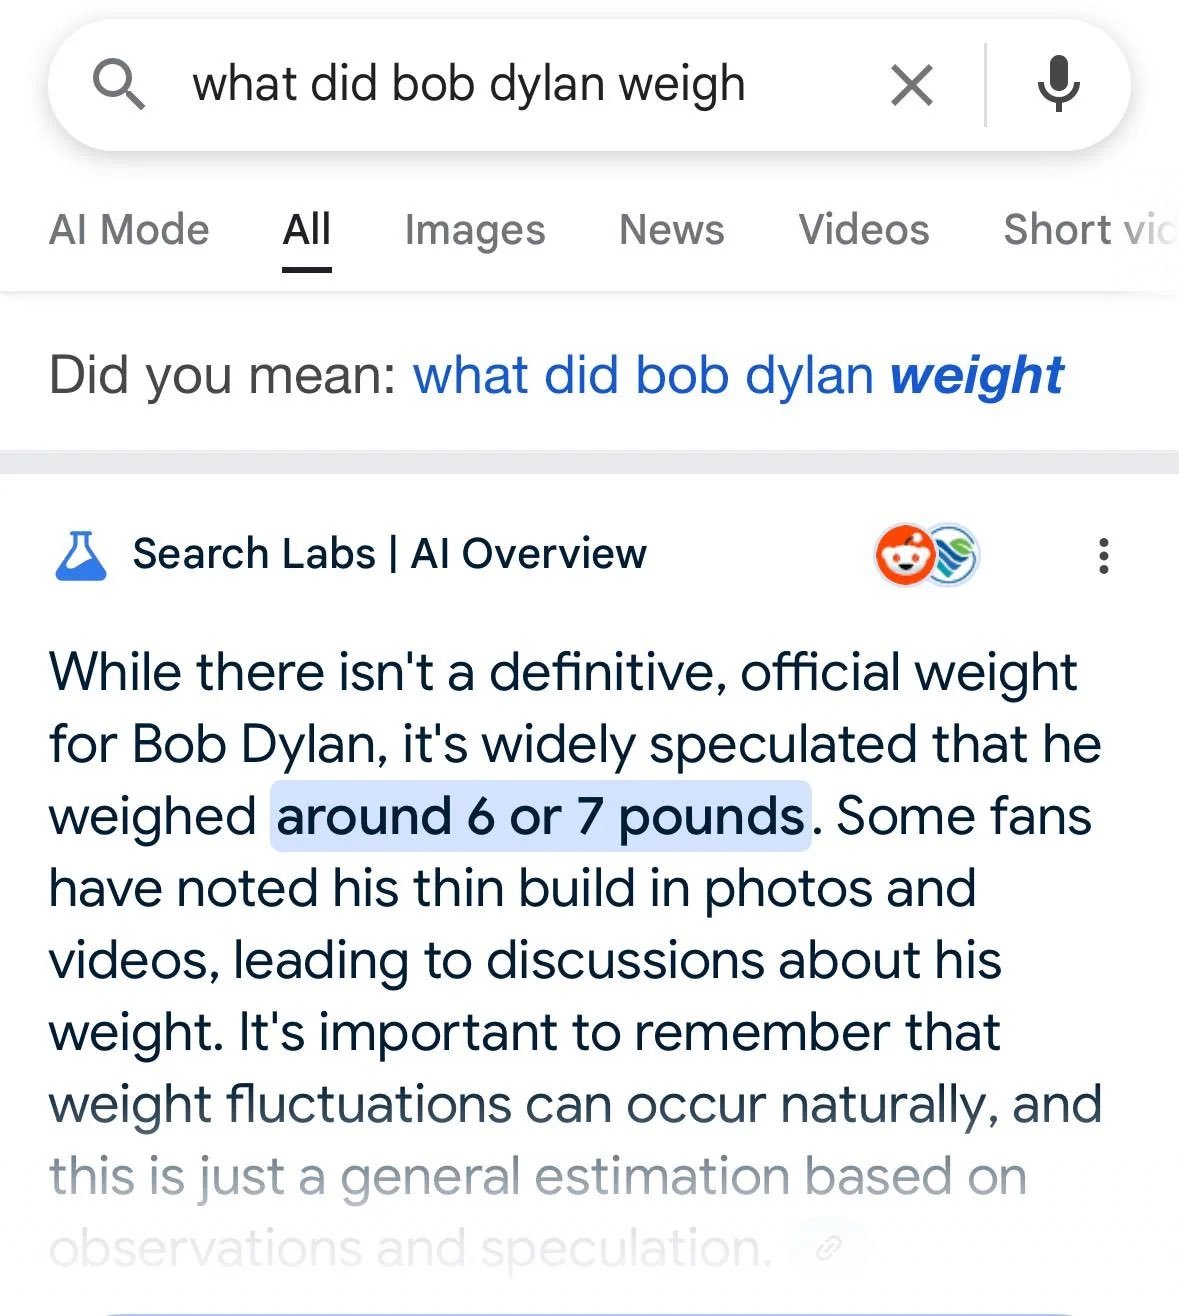
Reasoning tokens alone cannot solve fundamental AI limitations
By
–
Adding more reasoning tokens is not going to fix this
-
Twitter Spam Uses Dadaist Word Salad to Evade LLM Classifiers
By
–
New trends in Twitter spam, from the people who brought you 160,000 reasons to turn off notifications: Dadaist word salad meant to apparently suggest trading gains to a low-sophistication mark while avoiding an LLM classifier given the task “Is this user talking about trading?”
-
o3 Model Experiencing High Hallucination Rates
By
–
o3 is hallucinating a lot, not sure if recent or always been true thought it was the smartest model?
-

ai.txt: New Standard for Responsible AI Web Access
By
–
The classic robots.txt just met its AI-era successor: ai.txt — a new DSL designed for responsible interaction between AI agents and the Web This paper outlines how websites can define fine-grained access and behavior rules for AI systems. Timely and much needed. Key
-
Agent Inbox: Human-in-the-Loop Control and Oversight for Agents
By
–
Next up, Nick is back with a deep dive into Agent Inbox and the UI/UX around human in the loop interactions! A non-technical end user can use it to gain oversight into an agent's actions, accepting/editing/ignoring suggested actions as an agent runs! This human component
-
Agent Inbox: Human-in-the-Loop Control for Agent Actions
By
–
Next up, Nick is back with a deep dive into Agent Inbox and the UI/UX around human in the loop interactions! A non-technical end user can use it to gain oversight into an agent's actions, accepting/editing/ignoring suggested actions as an agent runs! This human component
-
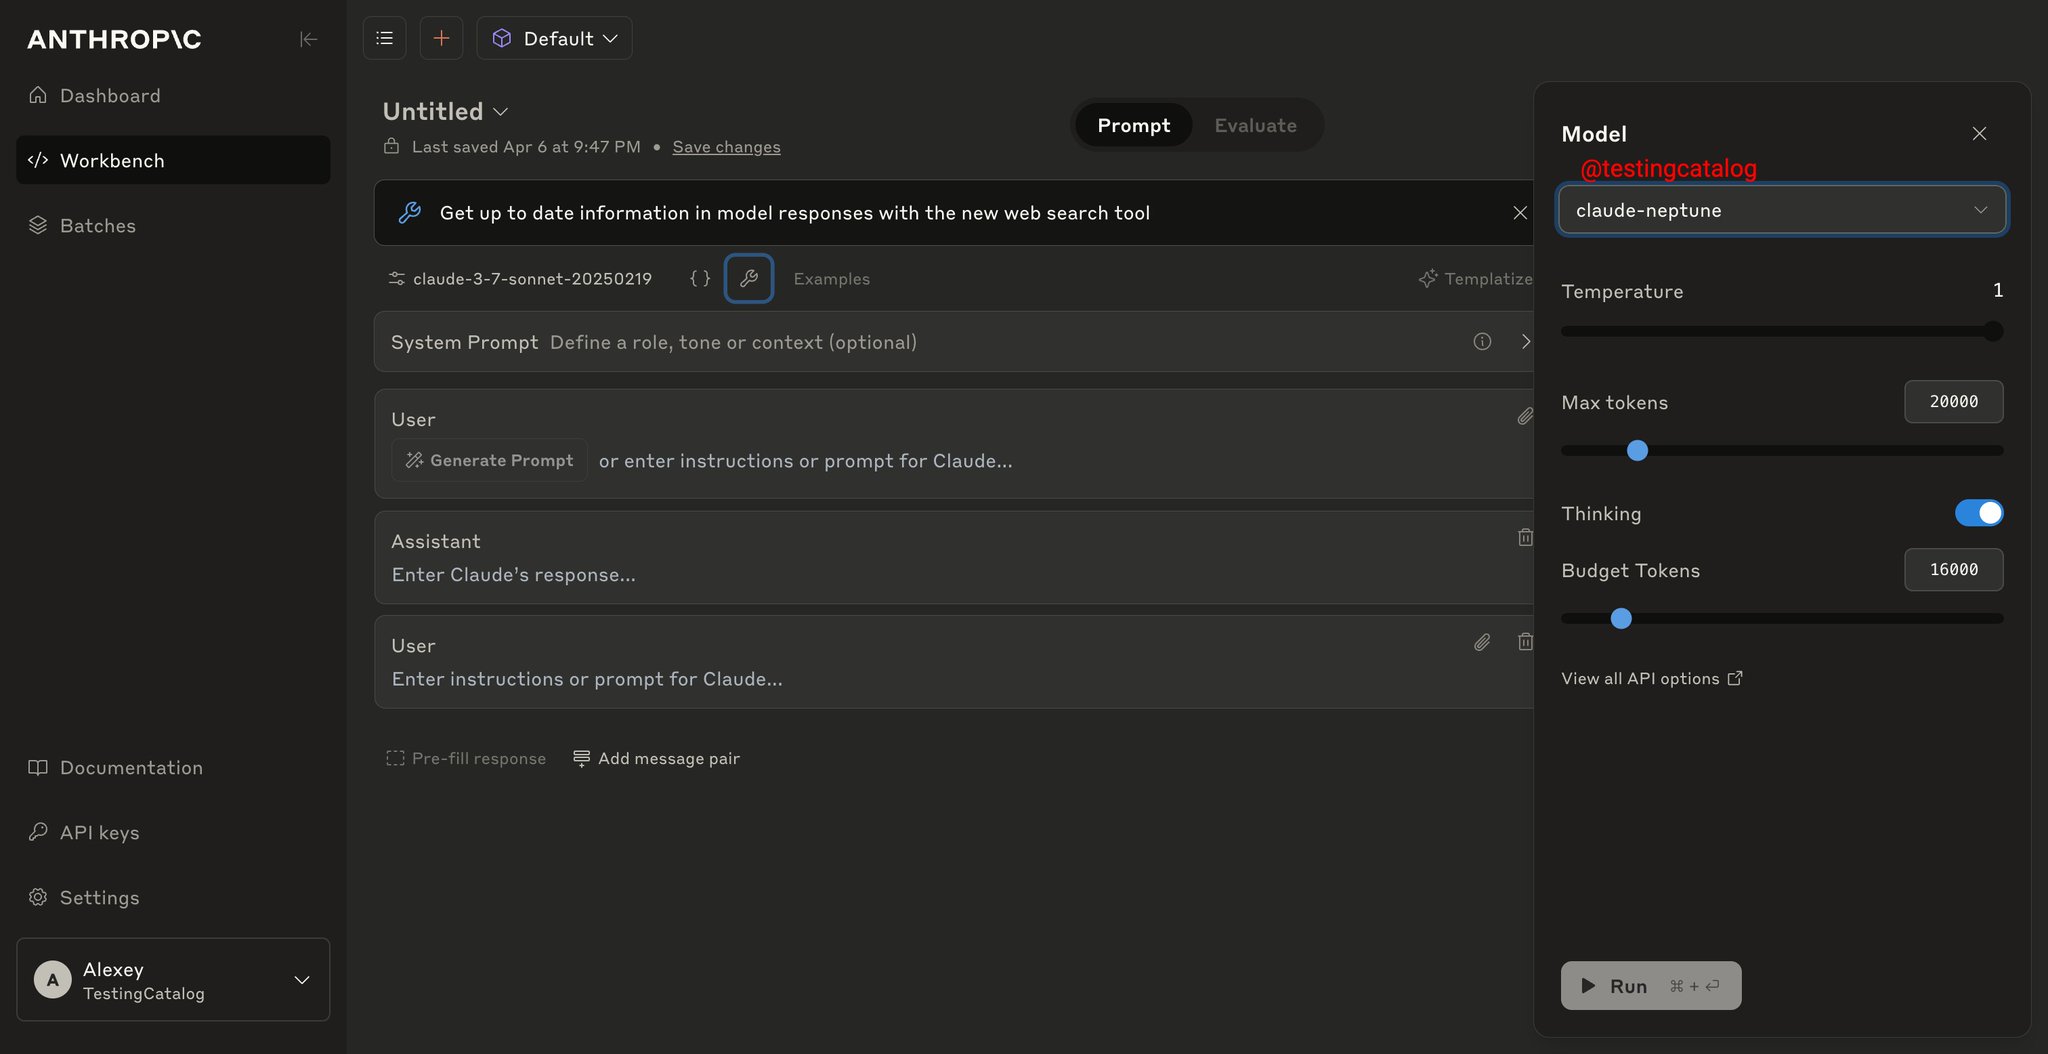
Anthropic conducting safety testing on new Claude-Neptune model
By
–
BREAKING : Anthropic is running safety testing on a new model called "claude-neptune". Another model drop soon?
-
Reducing False Positive Block Rate in AI Systems
By
–
we are working on reducing false positive block rate! stay tuned