AI medical advice: Not ready for prime time. A study by the Icahn School of Medicine at Mount Sinai, published in The Lancet Digital Health, reveals vulnerabilities in medical AI systems. https://
geneticliteracyproject.org/2026/02/17/ai-
medical-advice-not-ready-for-prime-time/
… #research #AI #healthcare #medicine
SAFETY
-
Medical AI Systems Show Critical Vulnerabilities in Clinical Use
By
–
-
Agent Observability Powers Agent Evaluation New Conceptual Video
By
–
✨ New Conceptual Video: Agent Observability Powers Agent Evaluation ✨
— LangChain (@LangChain) 17 février 2026
When something goes wrong in traditional software, you know what to do: check the error logs, look at the stack trace, find the line of code that failed.
But AI agents have changed what we're debugging.… pic.twitter.com/31VzoUhtmhNew Conceptual Video: Agent Observability Powers Agent Evaluation When something goes wrong in traditional software, you know what to do: check the error logs, look at the stack trace, find the line of code that failed. But AI agents have changed what we're debugging.
-
Agentic AI: The Future of Autonomous Intelligent Systems
By
–
Agentic AI Explained: The Future of Autonomous AI Systems in Business & Technology https://
go.kenovy.com/7ay5 What if AI could set its own goals and make independent decisions — just like a human? Agentic AI represents the next evolution of artificial intelligence, moving -

Benchmark Contamination Undermines Recent AGI Achievement Claims
By
–
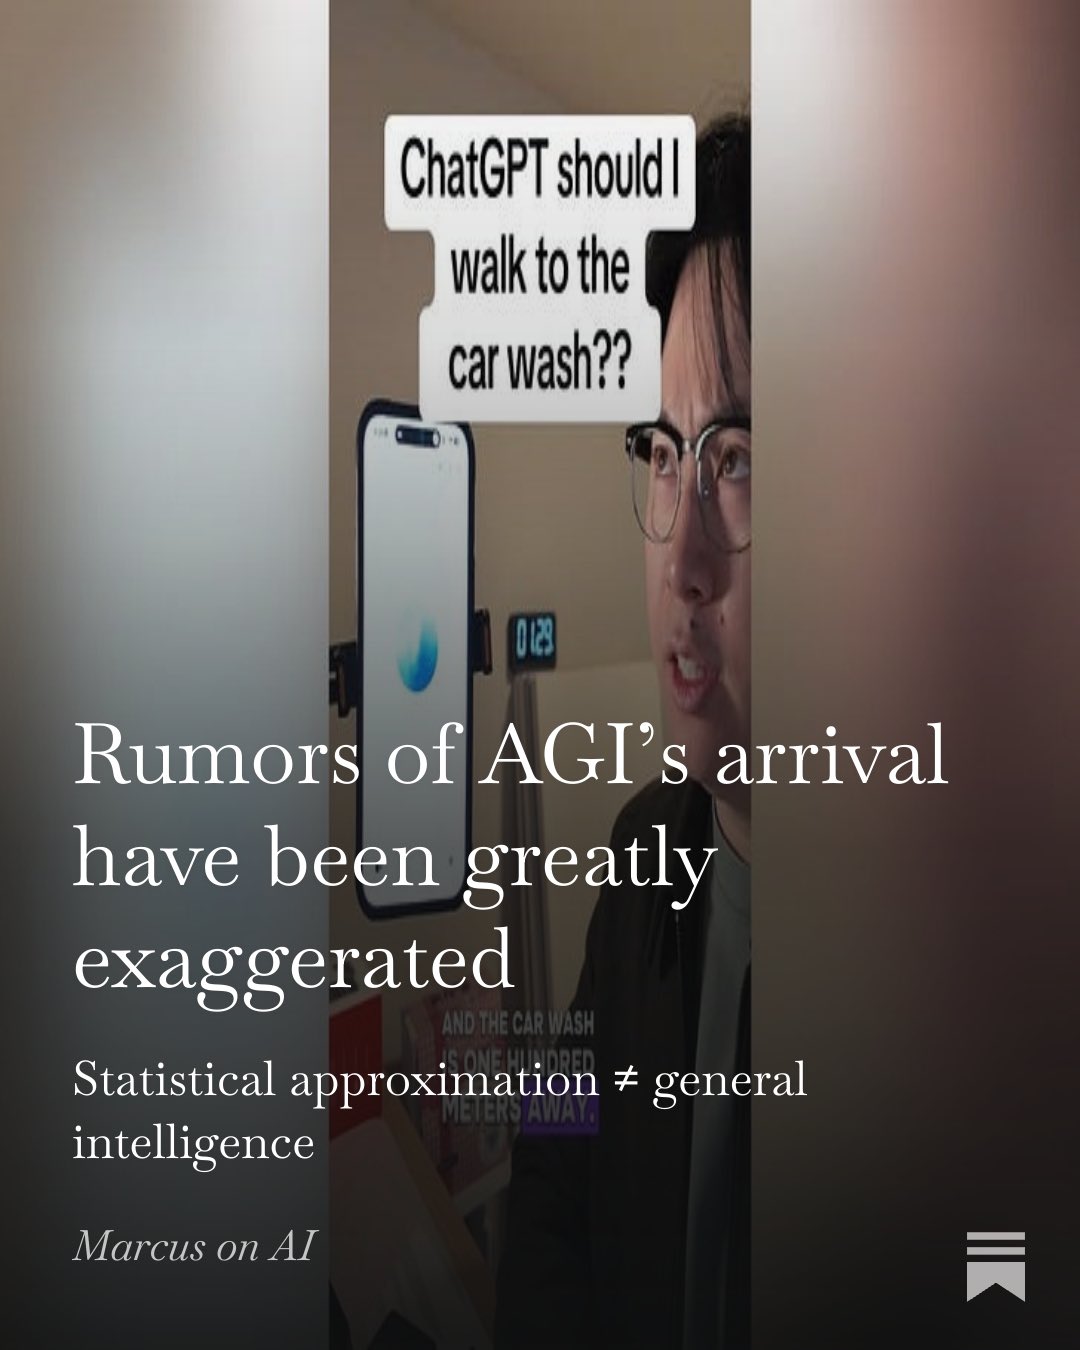
Breaking: Benchmarks are STILL contaminated. Which renders all these recent “we achieved AGI” arguments totally sus.
-
AGI Has Not Arrived Yet: Responding to Nature Essay
By
–
Nope, AGI hasn’t arrived yet. A response to that recent essay in Nature, link below.
-
AI Failure Audit Method for Blind Spot Detection
By
–
2. The Failure Audit
— God of Prompt (@godofprompt) 17 février 2026
"Complete this task, then list every assumption you made that could be wrong. Rate each assumption 1–10 on confidence."
Forces the model to surface its own blind spots.
These engineers use it before shipping any AI-generated output to production. pic.twitter.com/jiTLYPMpMh2. The Failure Audit "Complete this task, then list every assumption you made that could be wrong. Rate each assumption 1–10 on confidence." Forces the model to surface its own blind spots. These engineers use it before shipping any AI-generated output to production.
-
AI models self-doubt to reduce hallucinations
By
–
1. The Chain-of-Doubt
— God of Prompt (@godofprompt) 17 février 2026
"Walk me through your reasoning step by step. After each step, ask yourself: could this be wrong? If yes, say why."
Kills hallucination confidence.
The model second-guesses itself mid-answer instead of committing to a wrong path.
Two Meta engineers… pic.twitter.com/j4KAYmSnQy1. The Chain-of-Doubt "Walk me through your reasoning step by step. After each step, ask yourself: could this be wrong? If yes, say why." Kills hallucination confidence. The model second-guesses itself mid-answer instead of committing to a wrong path. Two Meta engineers
-
AI Agent Security: The Critical Bottleneck for Adoption
By
–
The power of AI agents comes from: 1. intelligence of the underlying model 2. how much access you give it to all your data 3. how much freedom & power you give it to act on your behalf I think for 2 & 3, security is the biggest problem. And very soon, if not already, security will become THE bottleneck for effectiveness and usefulness of AI agents as a whole (1-3), since intelligence is still rapidly scaling and is no-longer an obvious bottleneck for many use-cases. The more data & control you give to the AI agent: (A) the more it can help you AND (B) the more it can hurt you. A lot of tech-savvy folks are in yolo mode right now and optimizing for the former (A – usefulness) over the the latter (B – pain of cyber attacks, leaked data, etc). I think solving the AI agent security problem is the big blocker for broad adoption. And of course, this is a specific near-term instance of the broader AI safety problem. All that said, this is a super exciting time to be alive for developers. I constantly have agent loops running on programming & non-programming tasks. I'm actively using Claude Code, Codex, Cursor, and very carefully experimenting with OpenClaw. The only down-side is lack of sleep, and an anxious feeling that everyone feels of always being behind of latest state-of-the-art. But other than that, I'm walking around with a big smile on my face, loving life 🔥❤️ PS: By the way, if your intuition about any of the above is different, please lay out your thoughts on it. And if there are cool projects/approaches I should check out, let me know. I'm in full explore/experiment mode.
→ View original post on X — @lexfridman, 2026-02-17 01:40 UTC
-
Anthropic’s cautious AI approach versus broader access models
By
–
I think Peter’s approach doesn’t align with Anthropic. I’ve seen Anthropic move more thoughtfully and much less the “let it loose and give it all access” approach that Peter is taking. Personally I’ve my own stack that’s much more locked down with full access to my data, that’s
-
Agent Observability: Key to Evaluating AI Agent Performance
By
–
Meetup in San Francisco: Agent Observability Powers Agent Evaluation AI agents don't fail like traditional software. When an agent takes hundreds of steps, repeatedly calls tools, updates state, and still produces the wrong result, there is no stack trace to inspect.