
A benchmark that captures the evolution of models in real office work well is OpenAI's own GDPval, and notice that here the model improves only marginally over the previous one, but the thing is that it really even in WINS achieves less than GPT 5.4. Honestly, I think there are
RESEARCH
-
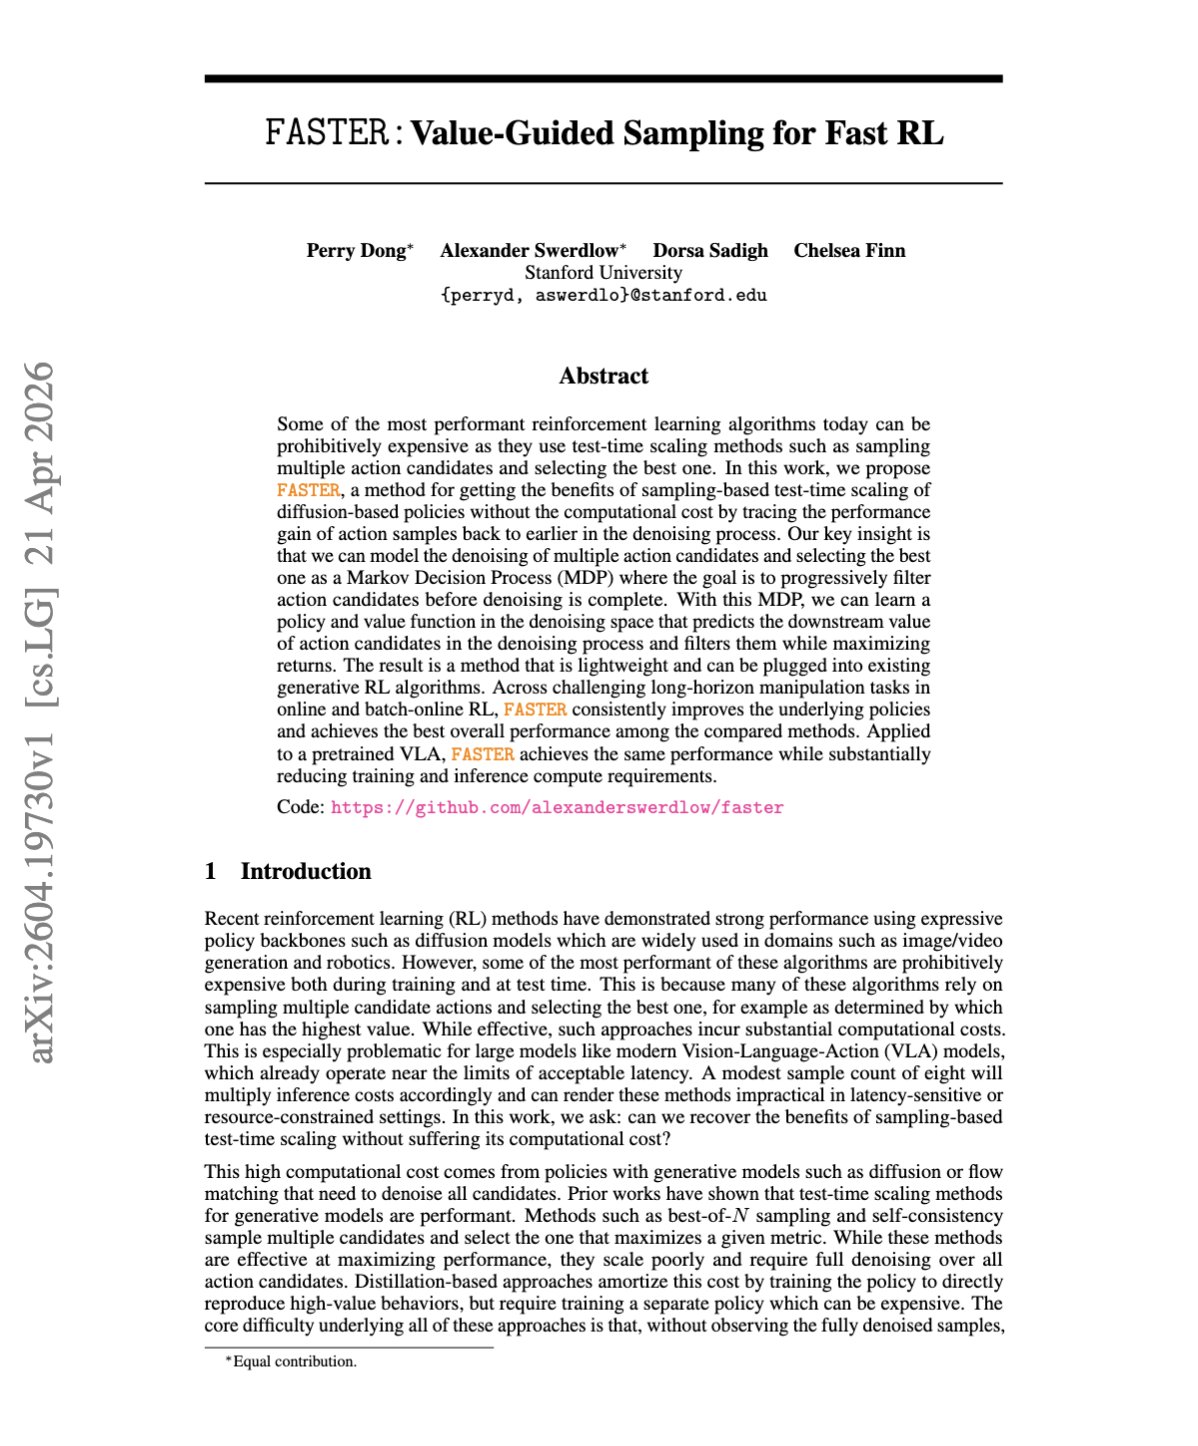
FASTER: Value-Guided Sampling Improves Reinforcement Learning Efficiency
By
–
"FASTER: Value-Guided Sampling for Fast RL" Instead of fully denoising many action candidates and picking the best one at the end, it learns a critic over the noise seed and selects the promising sample upfront. They showed that the advantage of best-of-N is already visible
-

Another day, another new best model in the world
By
–
Another day, another new best model in the world… https://t.co/j2YWVZDw8g
— Matt Wolfe (@mreflow) 23 avril 2026Another day, another new best model in the world…
-

GPT 5.5 Achieves Superior Performance with Reduced Token Consumption
By
–
Something worth celebrating is the efficiency gains in token usage! Here GPT 5.5 pushes the frontier and makes its consumption cheaper by achieving (in the aggregated Artificial Analysis benchmark) the same performance using the medium level of GPT 5.5 (22M tokens) as what GPT
-

GPT 5.4 Analysis: Improvements Over Previous Model Version
By
–
That said, let's tackle it not from the hype perspective that OpenAI and others have been hyping up in recent weeks with the damn potato and let's analyze it as a new model. For me, GPT 5.4 has been an excellent model, and if this one improves it and fixes its weak points, it
-

New AI Model Benchmarks: Opus Comparison and Performance Analysis
By
–
In fact, scrolling down to the evaluation area, we see more benchmarks that would normally be up top, where in some cases Opus 4.7% outperforms the new model (forcing them to add a sympathetic footnote ). The model improves—without drastic jumps—in programming, office tasks,
-
GPT-5.5 Iterative Deployment Strategy for AI Safety
By
–
1. We believe in iterative deployment; although GPT-5.5 is already a smart model, we expect rapid improvements. Iterative deployment is a big part of our safety strategy; we believe the world will be best equipped to win at the team sport of AI resilience this way. 2. We believe
-

Sarcomere Enhancers Show Promise for HFpEF Obesity Treatment
By
–
In people with HFpEF (heart failure with preserved ejection fraction) and severe obesity, there is a heart muscle cell defect with sarcomere hyper-phosphorylation. Besides weight loss, sarcomere enhancers (not yet studied) may help. @ScienceMagazine https://
science.org/doi/10.1126/sc
ience.adz7118
… -
GPT-5.5 Achieves Breakthrough in Long-Running Task Reliability
By
–
GPT-5.5 is MUCH more reliable on longer running tasks – for the first time with any model.
— Peter Gostev (@petergostev) 23 avril 2026
As we speak I have a migration running for over 7+ hours – this literally never happened before, the models would maybe run for 30 mins or of you really shout at them for 2-3 hours.… pic.twitter.com/nxdrKZnOzWGPT-5.5 is MUCH more reliable on longer running tasks – for the first time with any model. As we speak I have a migration running for over 7+ hours – this literally never happened before, the models would maybe run for 30 mins or of you really shout at them for 2-3 hours.
-

Pareto Frontiers: Extended Context and Improved Inference Speed
By
–
looks like new Pareto frontiers across everything:
— swyx 🇸🇬 (@swyx) 23 avril 2026
– Context: 400K context in Codex and a 1M in API
– API Pricing: $5/m input and $30/m output tokens.
– Codex improved its own inference speed 20% lol
– First generation co-designed with GB200 and GB300 NVL72
– 82.7% on… https://t.co/J5CL5fKmsq pic.twitter.com/nJG1vubSdNlooks like new Pareto frontiers across everything: – Context: 400K context in Codex and a 1M in API
– API Pricing: $5/m input and $30/m output tokens. – Codex improved its own inference speed 20% lol – First generation co-designed with GB200 and GB300 NVL72 – 82.7% on