I wonder if there would be any benefit for ML models to non linearly distorting image pixel statistics into a true Gaussian distribution instead of just the traditional scale and bias.
RESEARCH
-
Open Science and Open-Source Approaches in AI Development
By
–
yup this one is more just open science (but open-source won't stop in general too). Better than closed everything I guess haha
-
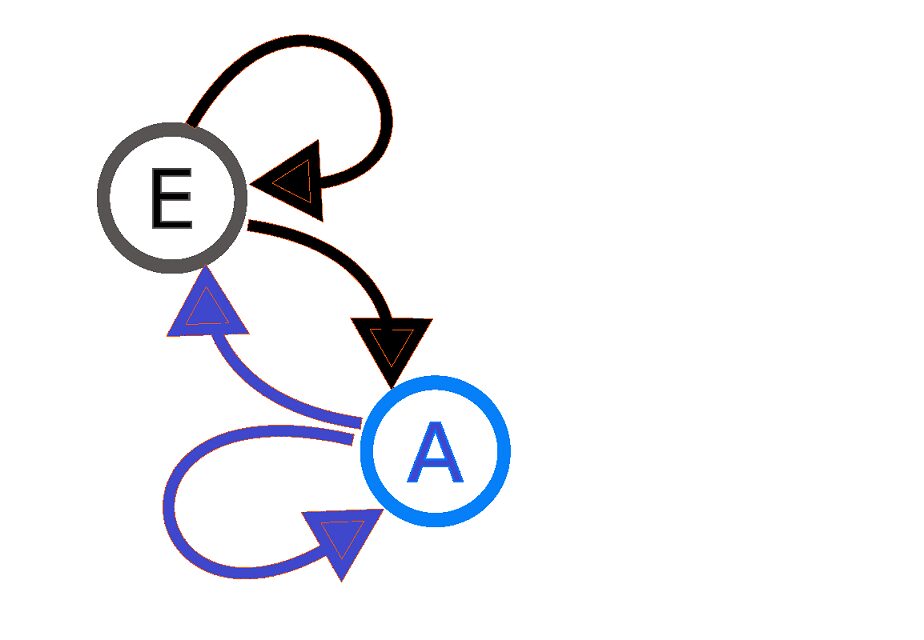
Introduction to Markov Chains: Memoryless Systems Modeling
By
–
An Introduction to Markov Chains: Markov chains are often used to model systems that exhibit memoryless behavior, where the system's future behavior is not influenced by its past behavior. https://
kdnuggets.com/2023/01/introd
uction-markov-chains.html?utm_source=dlvr.it&utm_medium=twitter&utm_campaign=an-introduction-to-markov-chains
… -
Open-source initiatives democratizing generative AI in 2023
By
–
This feeds into one of the key trends I predicted for 2023: the evolution of open-source initiatives to democratise (Gen) AI.
-
Hugging Face AWS collaboration makes generative models widely accessible
By
–
Why the @huggingface / @awscloud collab is a bid deal: Hugging Face is on a mission to make the best generative models (which require a lot of data, computing power and basically $$$$$) widely accessible.
-
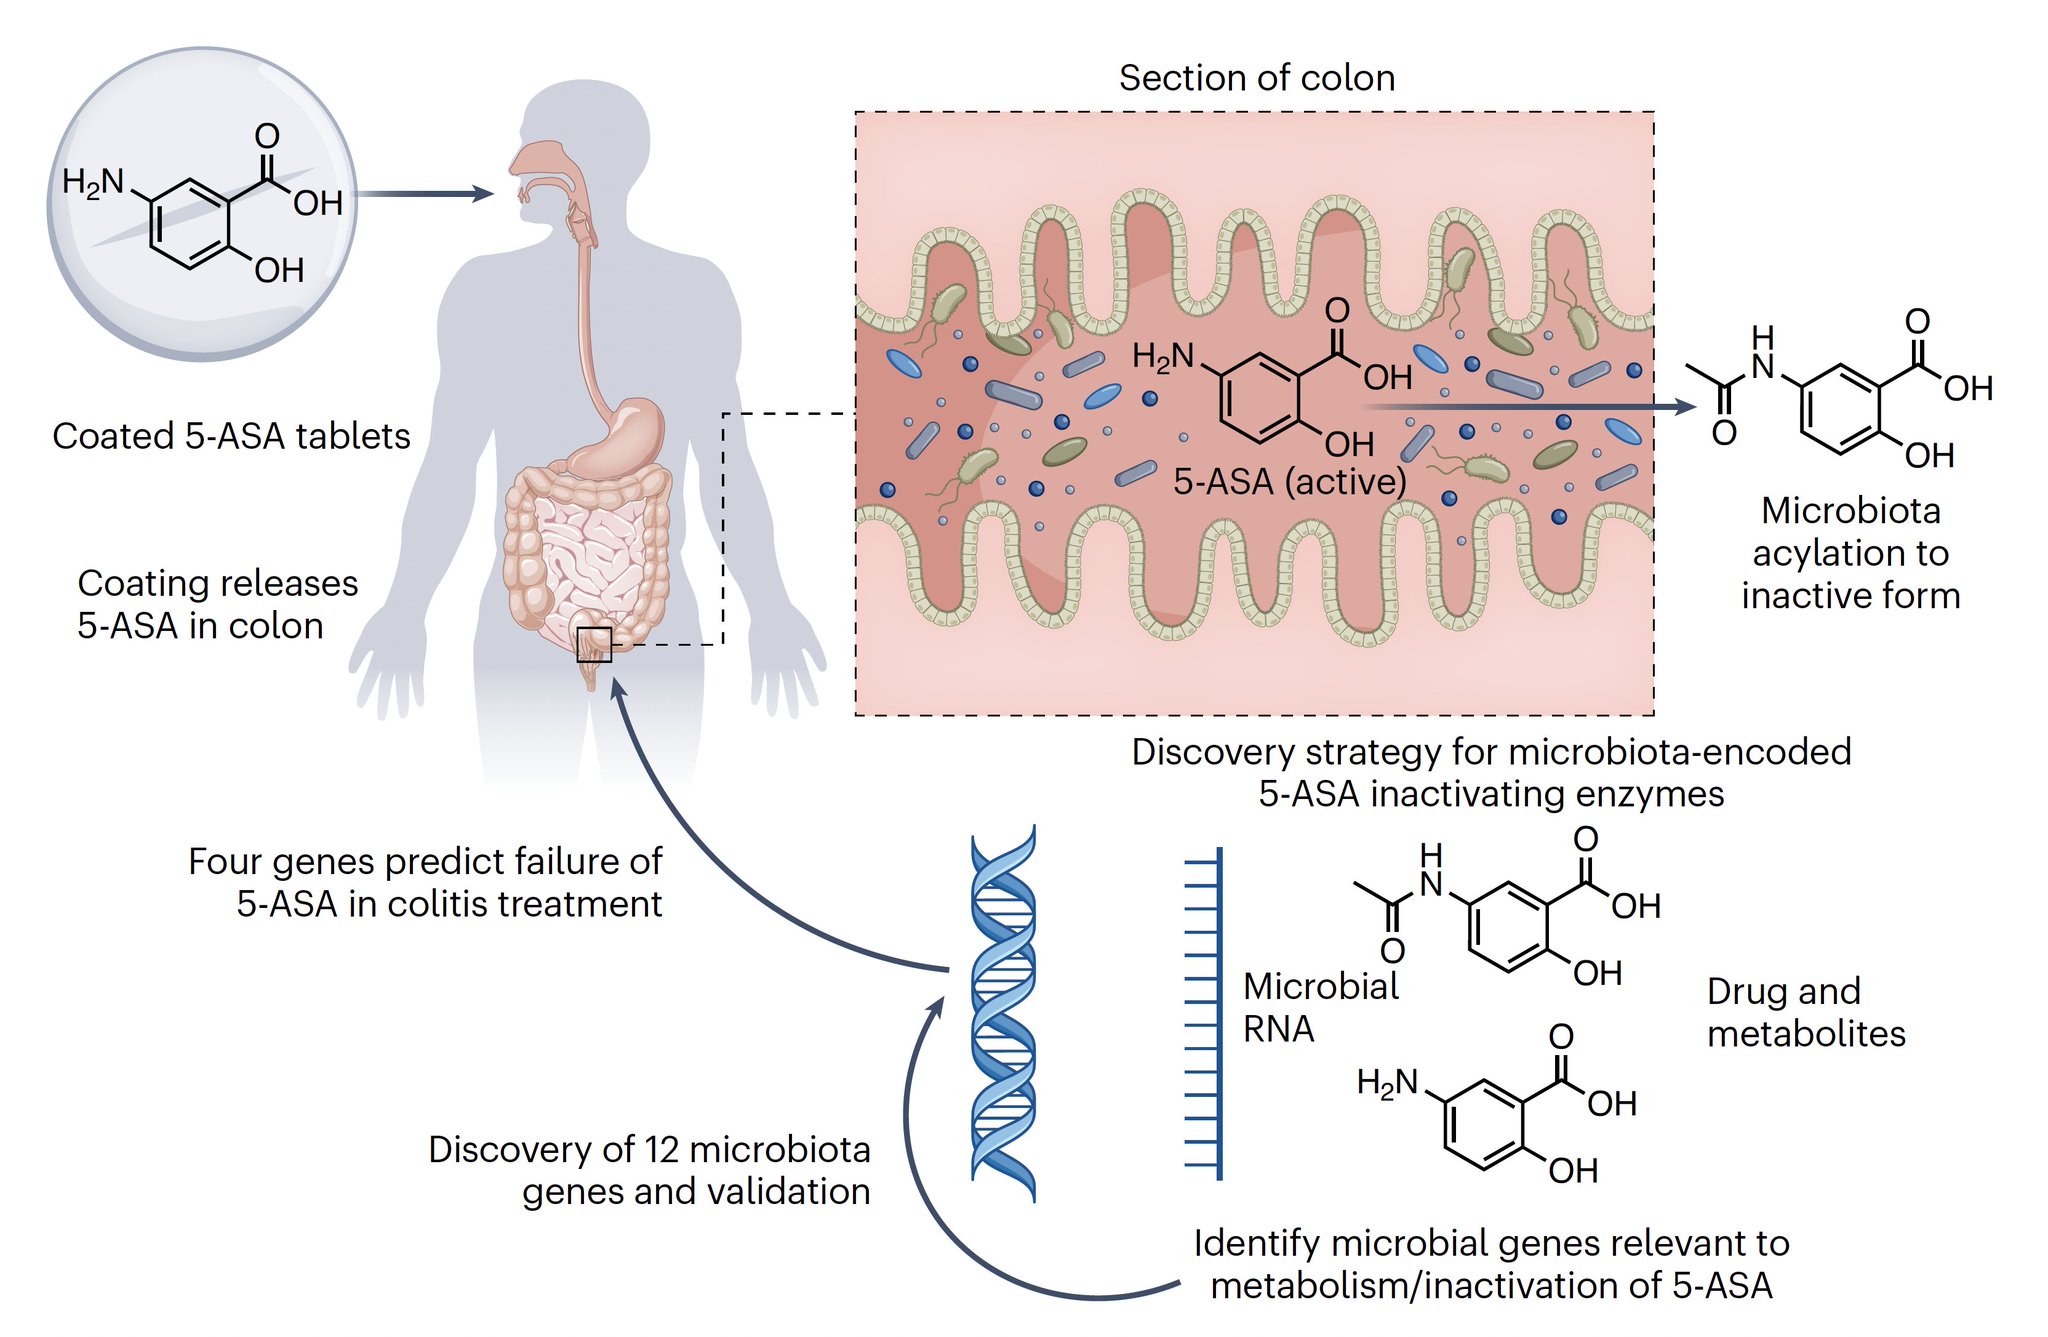
Gut Microbiome Enzymes Predict IBD Treatment Response
By
–
For people with inflammatory bowel disease, why is there such a variable response the standard treatment of 5-amino salicylic acid?
A new mulitomic study
4 commonly present enzymes produced by gut microbiome predict response https://
nature.com/articles/s4159
1-023-02217-7
… https://
nature.com/articles/s4159
1-023-02227-5
… -
Meta Releases LLaMA Foundational Language Model Publicly
By
–
Today we're publicly releasing LLaMA, a state-of-the-art foundational LLM, as part of our ongoing commitment to open science, transparency and democratized access to new research. Learn more & request access https://
bit.ly/3SoXdQE -
LLaMA: Competitive AI Model That’s Smaller and More Efficient
By
–
LLaMA (Large Language Model Meta AI) achieves results competitive with the best currently released models while being smaller & more efficient — increasing accessibility to this technology for more researchers working on this important subfield of AI across the globe.
-
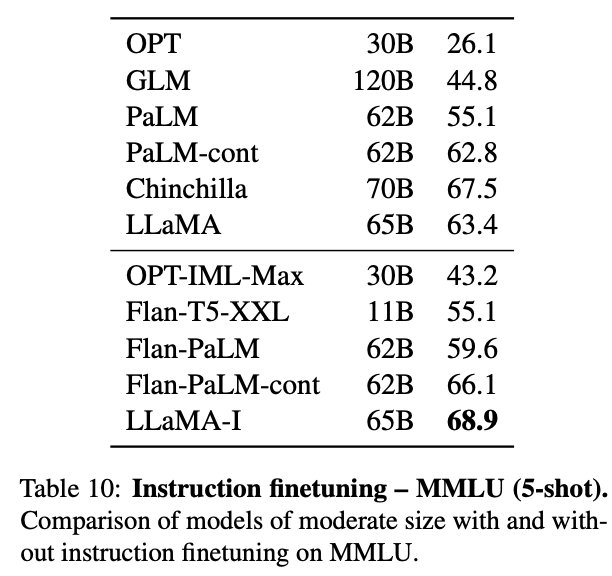
Instruction Finetuning Results: LLaMA-I Outperforms Flan-PaLM
By
–
We also briefly tried instruction finetuning using the approach of Chung et al. (2022).
The resulting model, LLaMA-I, outperforms Flan-PaLM-cont (62B) on MMLU and showcases some interesting instruct capabilities.
7/n -
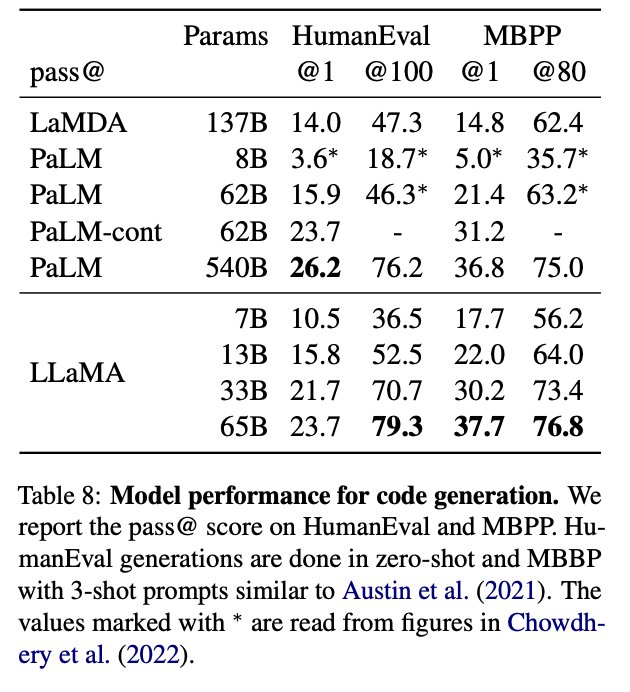
LLaMA-62B Surpasses PaLM on Code Generation Benchmarks
By
–
On code generation benchmarks, LLaMA-62B outperforms cont-PaLM (62B) as well as PaLM-540B.