
#ComputerVision pioneer Jitendra Malik is here at #DataAISummit. His research group has worked on a ton of topics in the space, so this is a talk you don’t want to miss.
RESEARCH
-

Lin Qiao on Developer-Centric AI Past Present Future
By
–
Next up at #DataAISummit: @lqiao
, Co-creator of #PyTorch! Lin will be taking us on a journey through the past, present & future of developer-centric #AI. -
AI Models Risk Over-Generalization and Country Stereotypes
By
–
However, when we further analyze model generations in this condition, we find that the model may rely on over-generalizations and country-specific stereotypes.
-
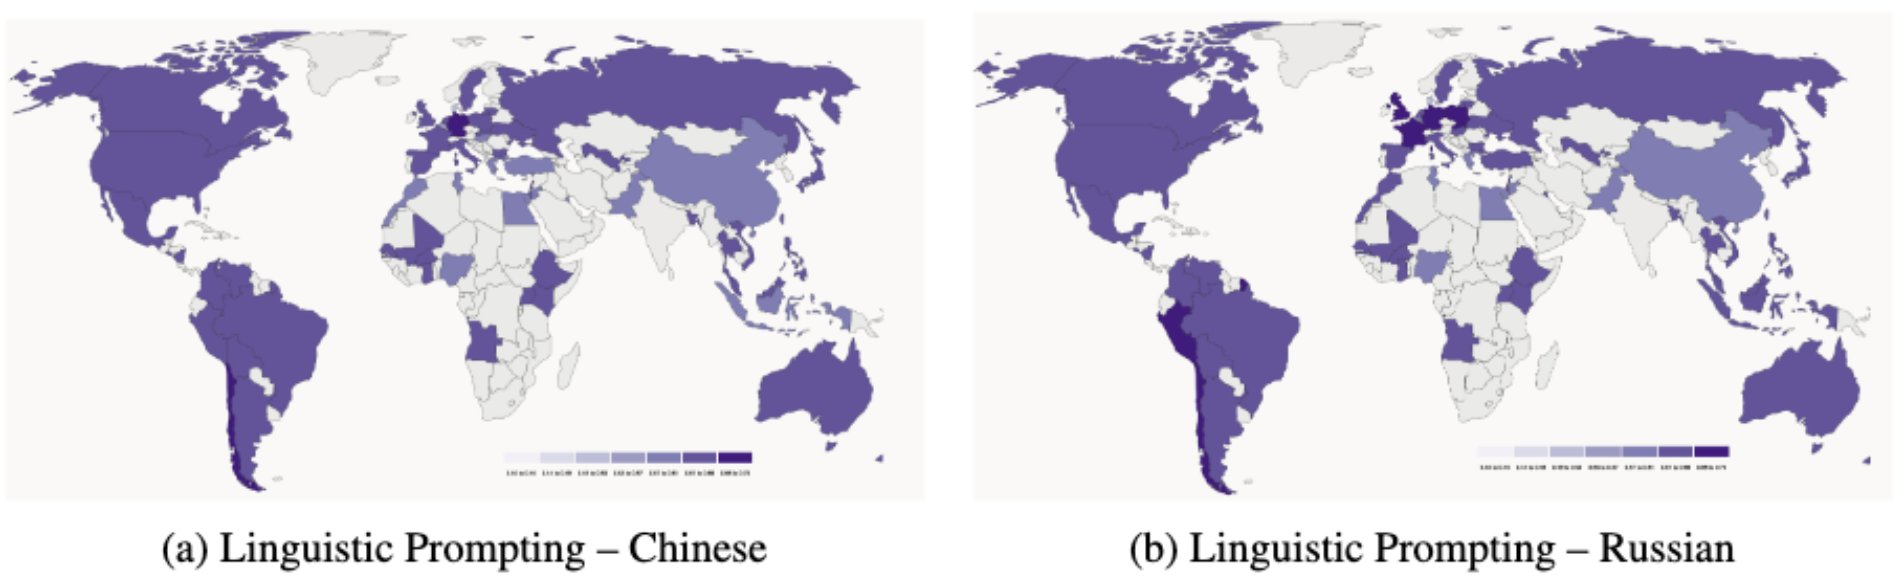
Linguistic Prompting Insufficient to Shift Model Responses
By
–
In the linguistic prompting condition, we translate survey questions into a target language. We find that simply presenting the questions in other languages does not substantially shift the model responses relative to the default condition. Linguistic cues are insufficient.
-
Evaluating Language Model Values: Frameworks for Global AI Alignment
By
–
Our preliminary findings show the need for rigorous evaluation frameworks to uncover whose values language models represent. We encourage using this methodology to assess interventions to align models with global, diverse perspectives. Paper:
-
Interactive Map Visualization of LLM Prompt-Based Value Alignment
By
–
We present an interactive visualization of the similarity results on a map to explore how prompt based interventions influence whose opinions the models are the most similar to. https://
llmglobalvalues.anthropic.com -
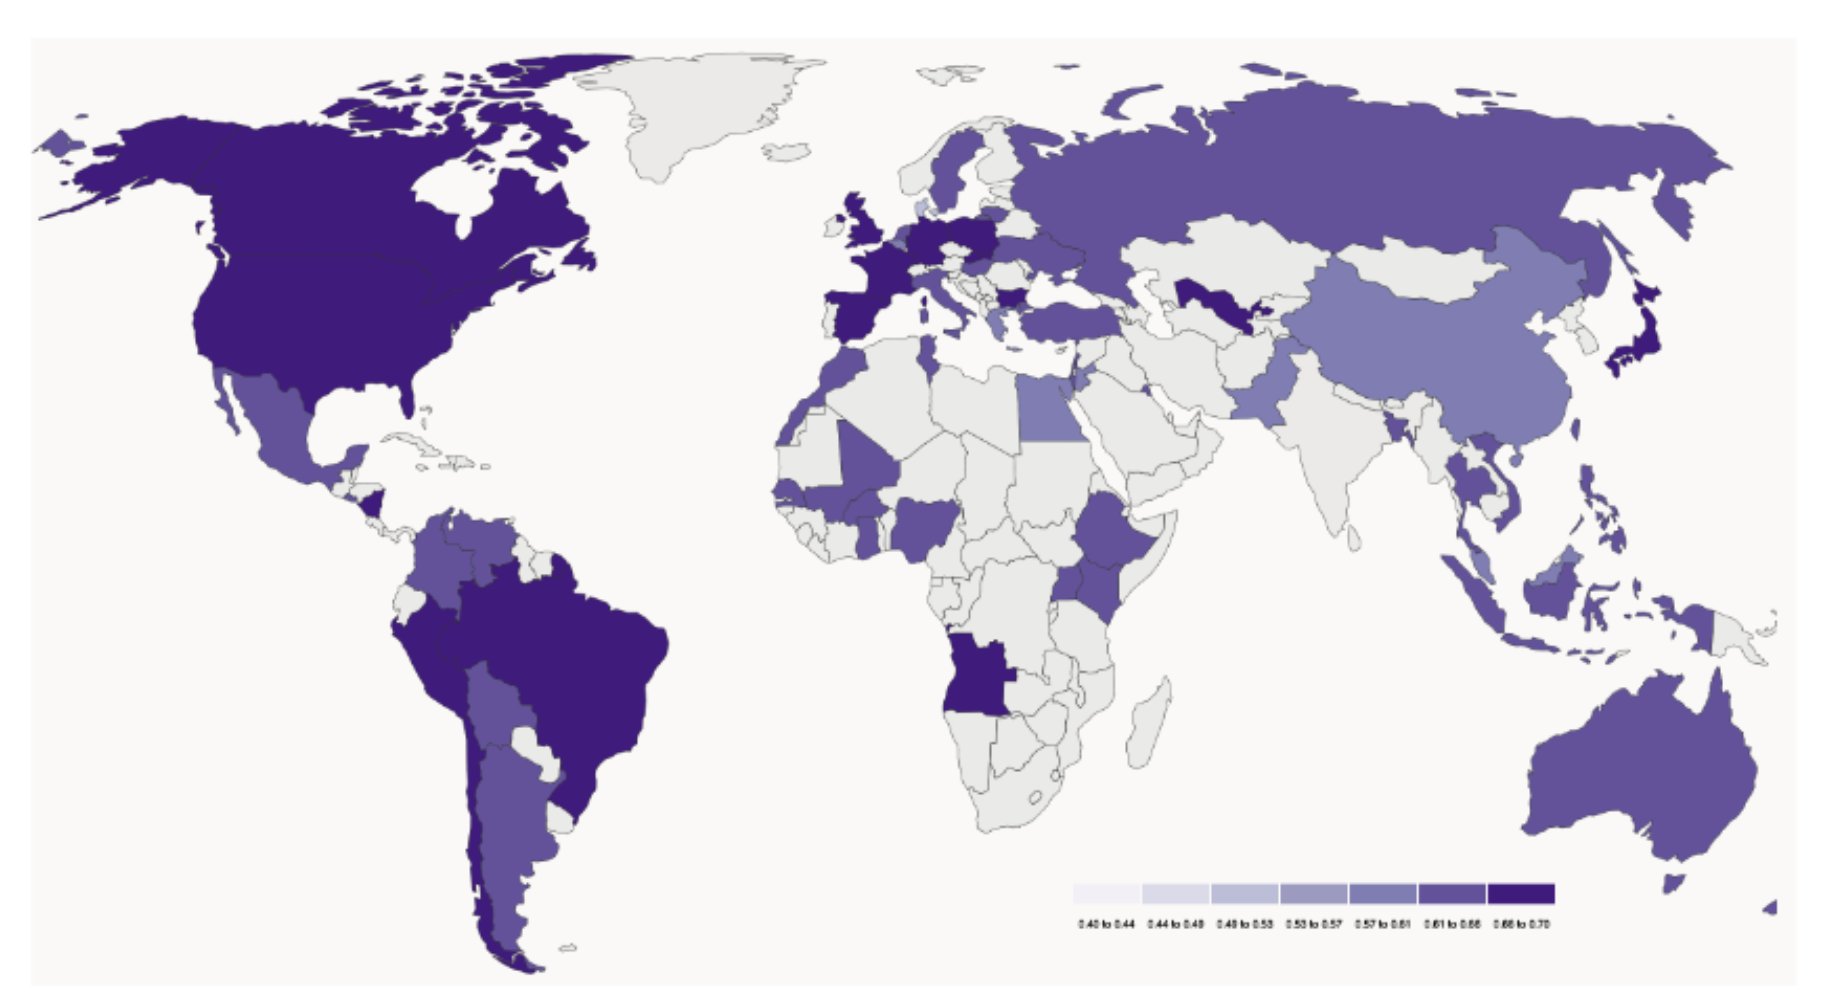
Language model responses align with USA, Europe, Japan human survey
By
–
We first prompt the language model only with the survey questions. We find that the model responses in this condition are most similar to those of human respondents in the USA, European countries, Japan, and some countries in South America.
-
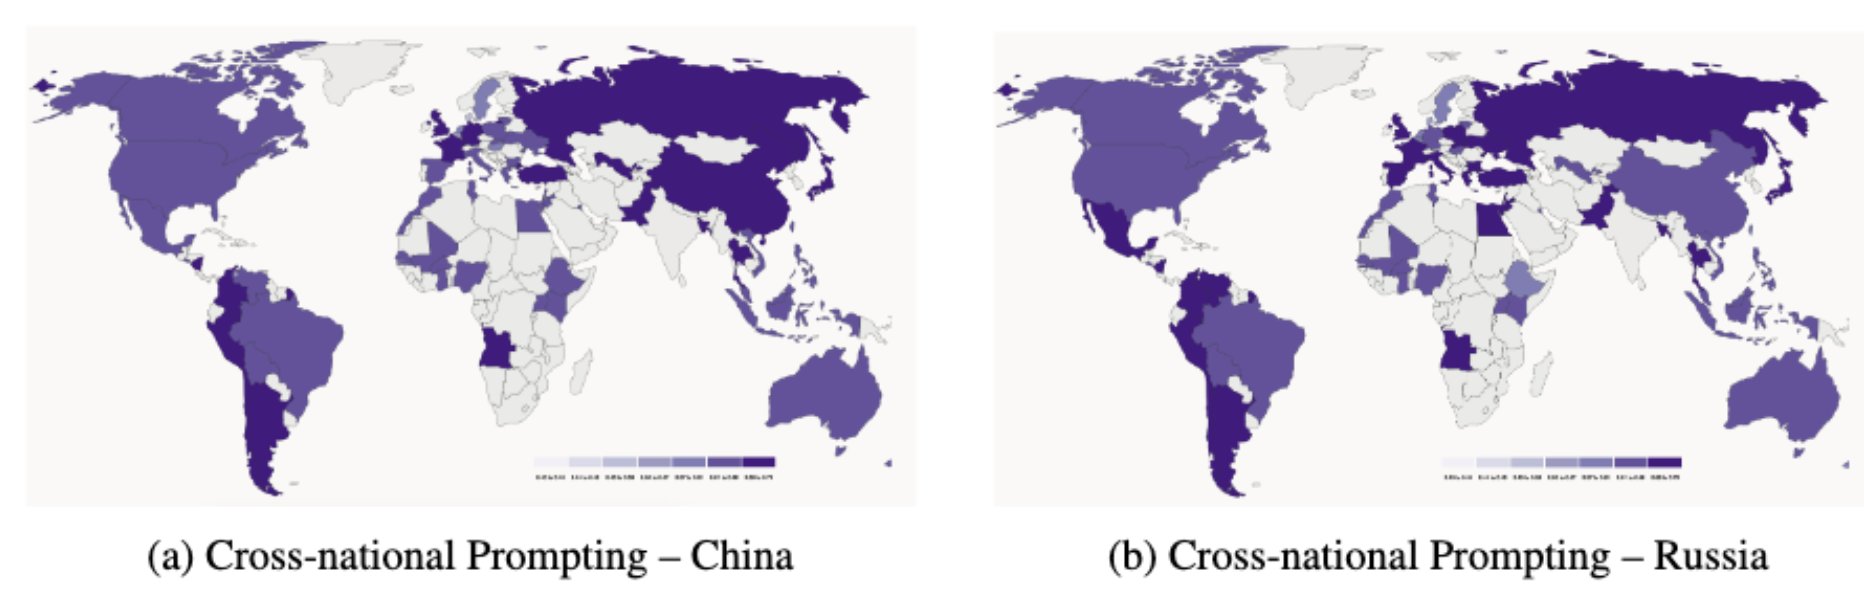
Cultural Prompting Changes Model Responses for Specific Countries
By
–
We then prompt the model with "How would someone from country [X] respond to this question?" Surprisingly, this makes model responses more similar to those of human respondents for some of the specified countries (i.e., China and Russia).
-
Language Models Show Western-Centric Opinions and Steerability
By
–
We develop a method to test global opinions represented in language models. We find the opinions represented by the models are most similar to those of the participants in USA, Canada, and some European countries. We also show the responses are steerable in separate experiments. pic.twitter.com/QzHmRPNqSl
— Anthropic (@AnthropicAI) 29 juin 2023We develop a method to test global opinions represented in language models. We find the opinions represented by the models are most similar to those of the participants in USA, Canada, and some European countries. We also show the responses are steerable in separate experiments.
-

Anthropic Releases Global AI Opinions Evaluation Dataset
By
–
We administer these questions to our model and compare model responses to the responses of human participants across different countries. We release our evaluation dataset at: https://
huggingface.co/datasets/Anthr
opic/llm_global_opinions
…