
Ok, fair. But if you look at the TransformerEncoderLayer class, for example, I don't think it's more abstract than nn.Conv2D or nn.RNN, for example. For some reason people just like implementing Transformer layers from scratch way more than convolutional or recurrent layers .
RESEARCH
-
Everyone’s Using nn.Linear and Similar Neural Network Layers
By
–
But everyone's using nn.Linear etc.
-
PyTorch Transformer Classes Predate Most Online Tutorials
By
–
Interesting! I'd say the nn.TransformerEncoderLayer and nn.TransformerDecoderLayer classes etc. actually precede most tutorials out there. Chicken-egg problem maybe
-

Quadratic AI Training Costs: How Engineers Build Bigger Models Affordably
By
–
Did you know that the cost of training an AI model increases approximately quadratically as you increase the number of tokens and the model size? ML engineers are still building bigger models without breaking the bank. pic.twitter.com/tB7EiintQl
— Replit ⠕ (@Replit) 3 juillet 2023Did you know that the cost of training an AI model increases approximately quadratically as you increase the number of tokens and the model size? ML engineers are still building bigger models without breaking the bank.
-

GPU Advances Enable Bigger, Wider LLM Model Architectures
By
–
With newer GPU technologies, the shape of our LLM models will begin to change. Bigger, wider, models are now a possibility.
— Replit ⠕ (@Replit) 3 juillet 2023
To learn more watch the full AI panel with @MosaicML’s Chief Scientist @jefrankle in conversation with Replit’s @amasad and @pirroh pic.twitter.com/A4g56a5ZtjWith newer GPU technologies, the shape of our LLM models will begin to change. Bigger, wider, models are now a possibility. To learn more watch the full AI panel with @MosaicML
’s Chief Scientist @jefrankle in conversation with Replit’s @amasad and @pirroh -
Why Do Developers Avoid PyTorch’s Built-in Transformer Layers?
By
–
Yeah, I always wonder what's up with that. The various Transformer layers in PyTorch have been around since ~2020, but everyone seems to be (still) rolling their own, https://
pytorch.org/docs/stable/nn
.html#transformer-layers
… Are the implementations somehow bad or inefficient? Genuine question. -
Jensen-Shannon Divergence: DNN Training Reproducibility Issues on Nvidia GPUs
By
–
Haha good one . Jensen-Shannon divergence: Training DNNs on Nvidia GPUs is not reproducible due to randomly selected code
-
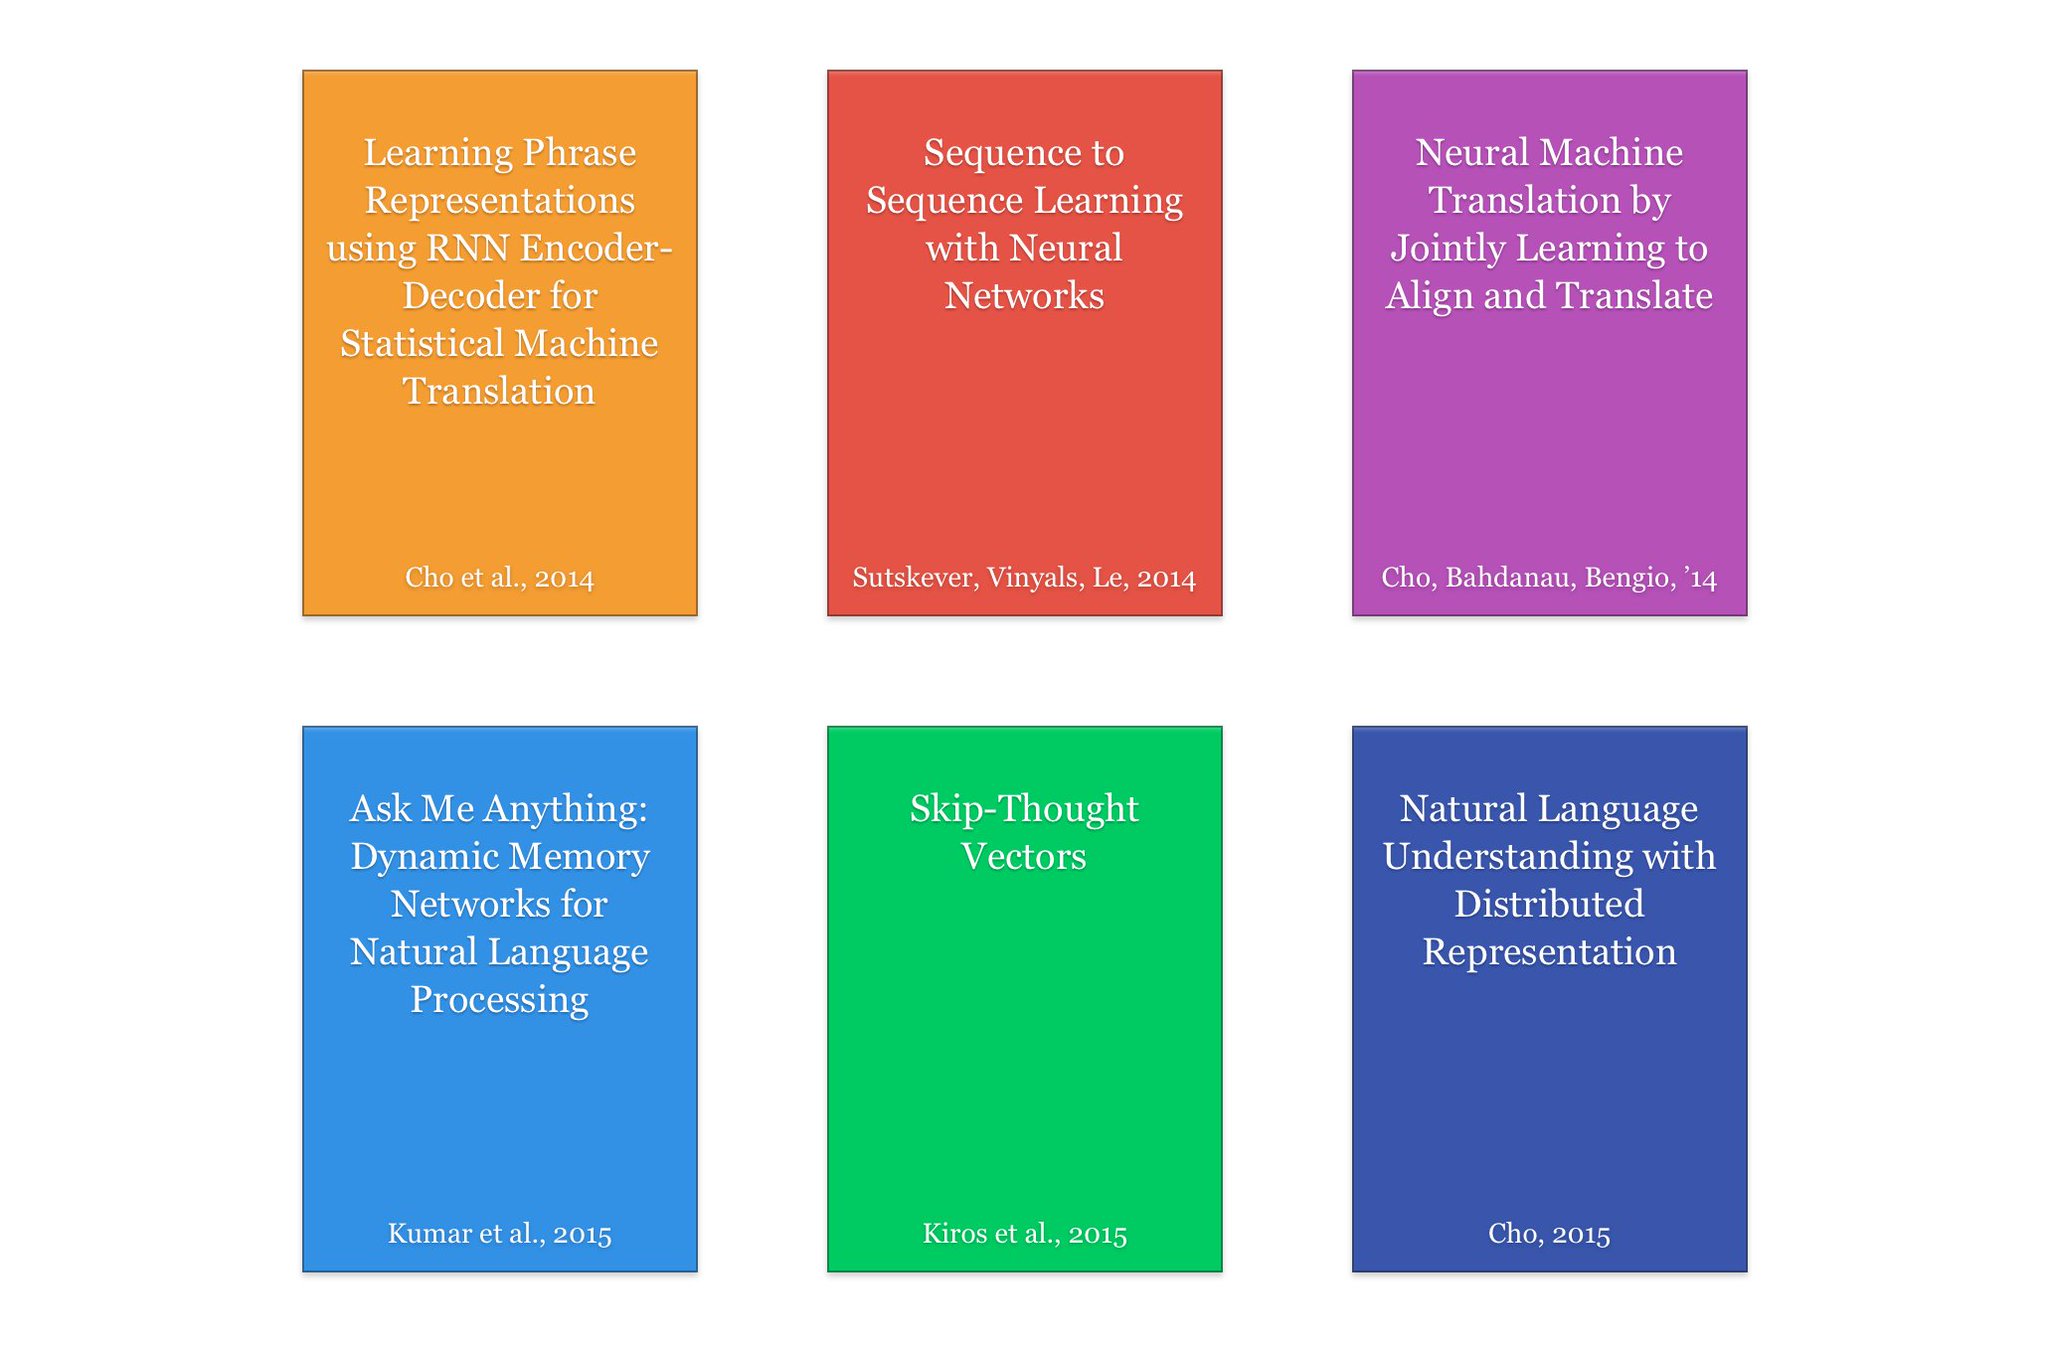
2016 AI Research Papers Design Mockup Throwback
By
–
Throwback time! made this design mockup back in 2016 to list the cool research papers of then like an old school @_akhaliq i guess
-
AI in Healthcare: Promising but Not Yet Ready for Patient Care
By
–
AI may be on its way to your doctor’s office, but it’s not ready to see patients
#AI #AIio #BigData #ML #NLU #Futureofwork @IIoT_World @ipfconline1 @jblefevre60 @JimMarous @insurtechtalk @KirkDBorne @kuriharan @LouisSerge http://
ow.ly/mfJx30svStx -
Considering accuracy trade-offs and LoRA alternatives
By
–
Thanks for suggesting! Yeah, I was thinking about that as well, but it may affect accuracy, and then once going this route, one might as well also think about LoRA etc.