China brings together tech giants, universities to draft #metaverse standards https://
globaltimes.cn/page/202401/13
05805.shtml
…
RESEARCH
-
China Unites Tech Giants Universities Draft Metaverse Standards
By
–
-
McCarthy’s 1956 AI Term: Grant Funding and Cybernetics Exclusion
By
–
I’m not saying marketing is BS. I’m saying McCarthy coined the term in 1956 by his own admission to 1 attract grant $ and 2 exclude Wiener via not referencing cybernetics and since then the term has been applied more as aspiration/pitch to a vast & heterogeneous set of approaches
-
Production-Ready End-to-End RAG Implementation Guide
By
–
Spoiler alert: it’s easier than you think to implement a production-ready end-to-end RAG. In this demo, you’ll learn about data conversion, embedding models, and efficient hosting with Databricks Model Serving. Watch now https://
bit.ly/3RDHIFH -
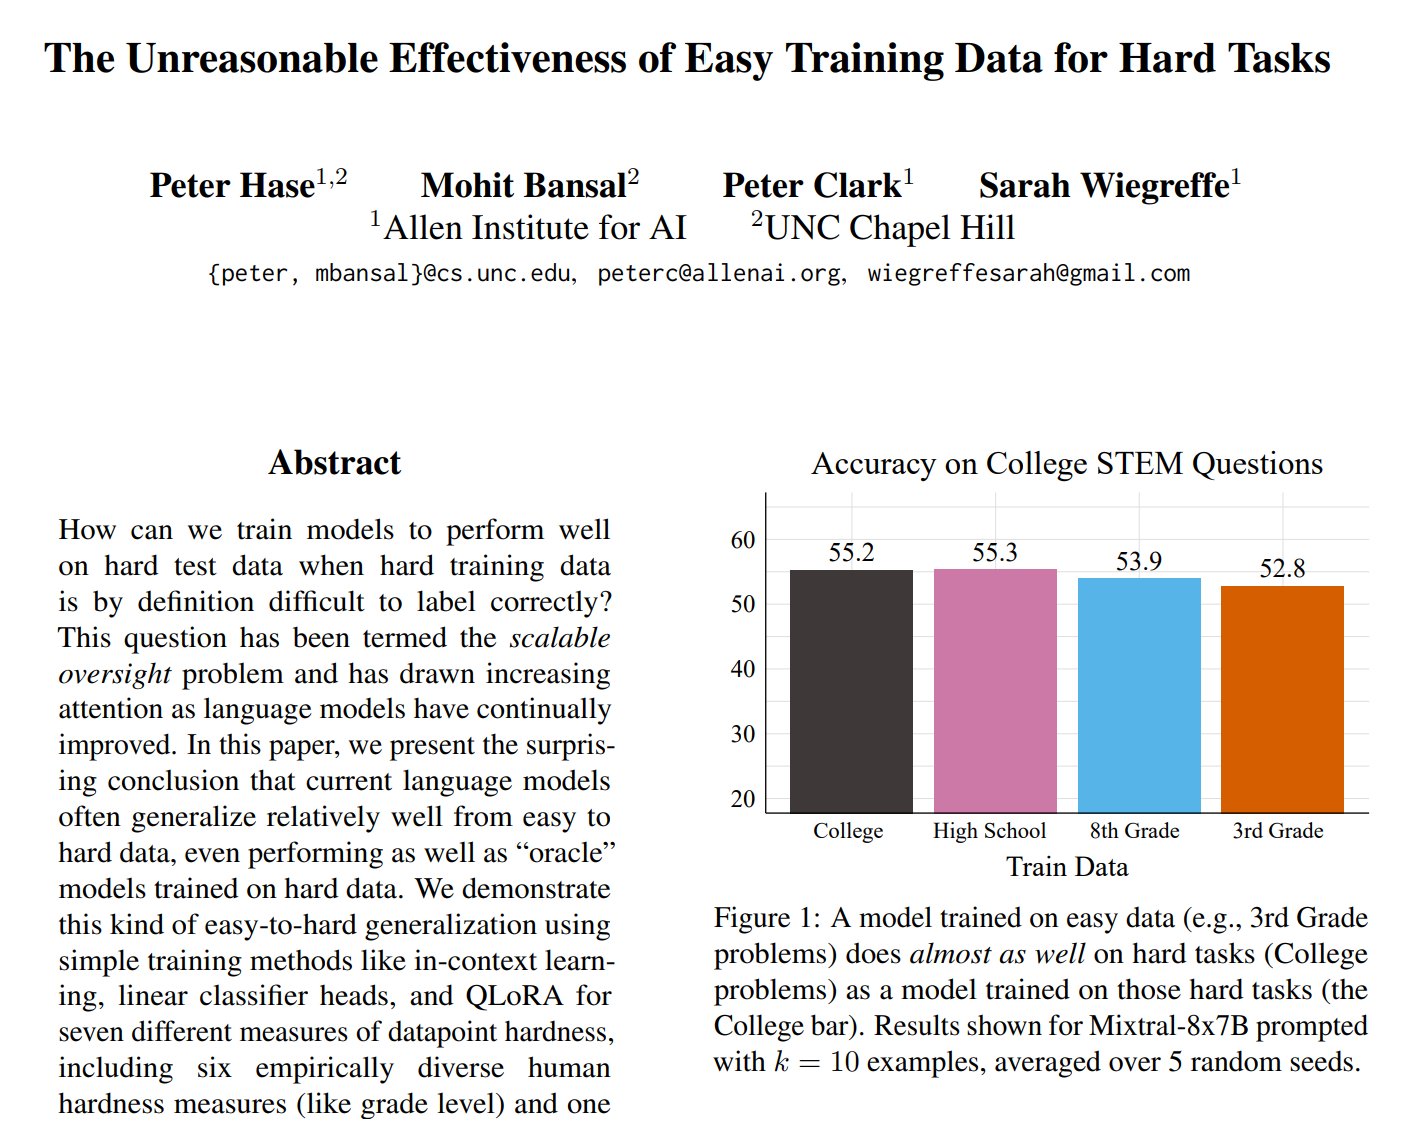
Easy Training Data Enables Hard Task Generalization
By
–
9/ The Unreasonable Effectiveness of Easy Training Data for Hard Tasks – suggests that language models often generalize well from easy to hard data, i.e., easy-to-hard generalization.
-
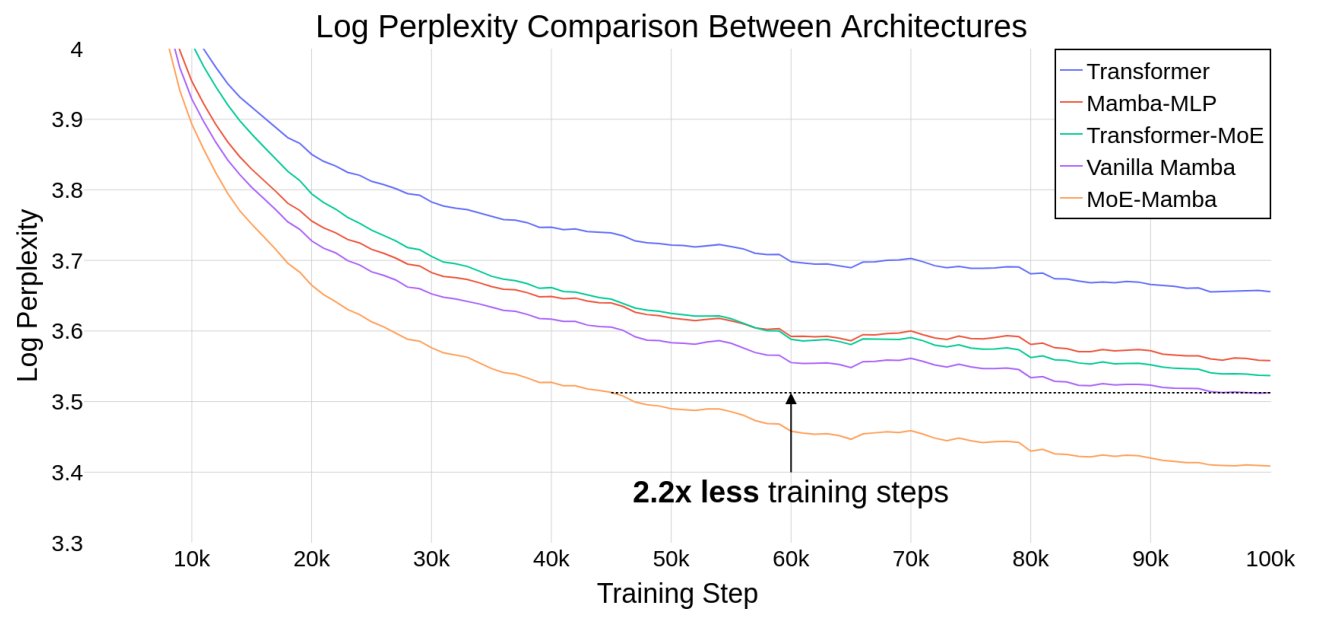
MoE-Mamba: Scaling LLMs with State Space Models and Mixture of Experts
By
–
10/ MoE-Mamba – an approach to efficiently scale LLMs by combining state space models (SSMs) with Mixture of Experts (MoE); MoE-Mamba, outperforms both Mamba and Transformer-MoE.
-

ReFT: Enhancing LLM Reasoning Through Reinforced Fine-Tuning
By
–
6/ Reasoning with Reinforced Fine-Tuning – an approach, ReFT, to enhance the generalizability of LLMs for reasoning; it starts with applying SFT and then applies online RL for further refinement while automatically sampling reasoning paths to learn from.
-
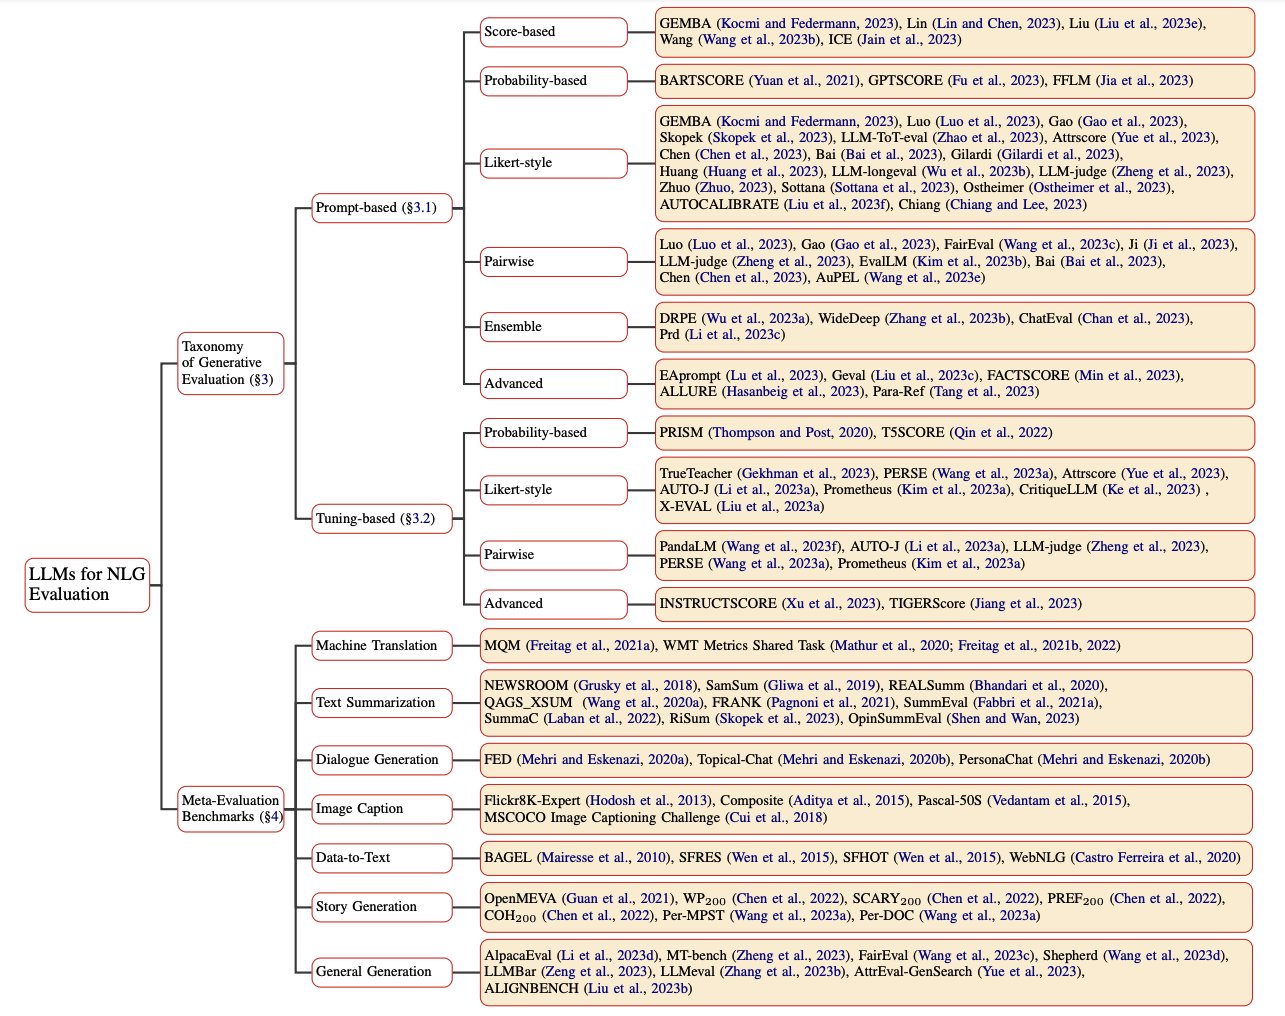
LLM Evaluation Methodologies: Taxonomy and Approaches
By
–
7/ Overview of LLMs for Evaluation – thoroughly surveys the methodologies and explores their strengths and limitations; provides a taxonomy of different approaches involving prompt engineering or calibrating open-source LLMs for evaluation.
-
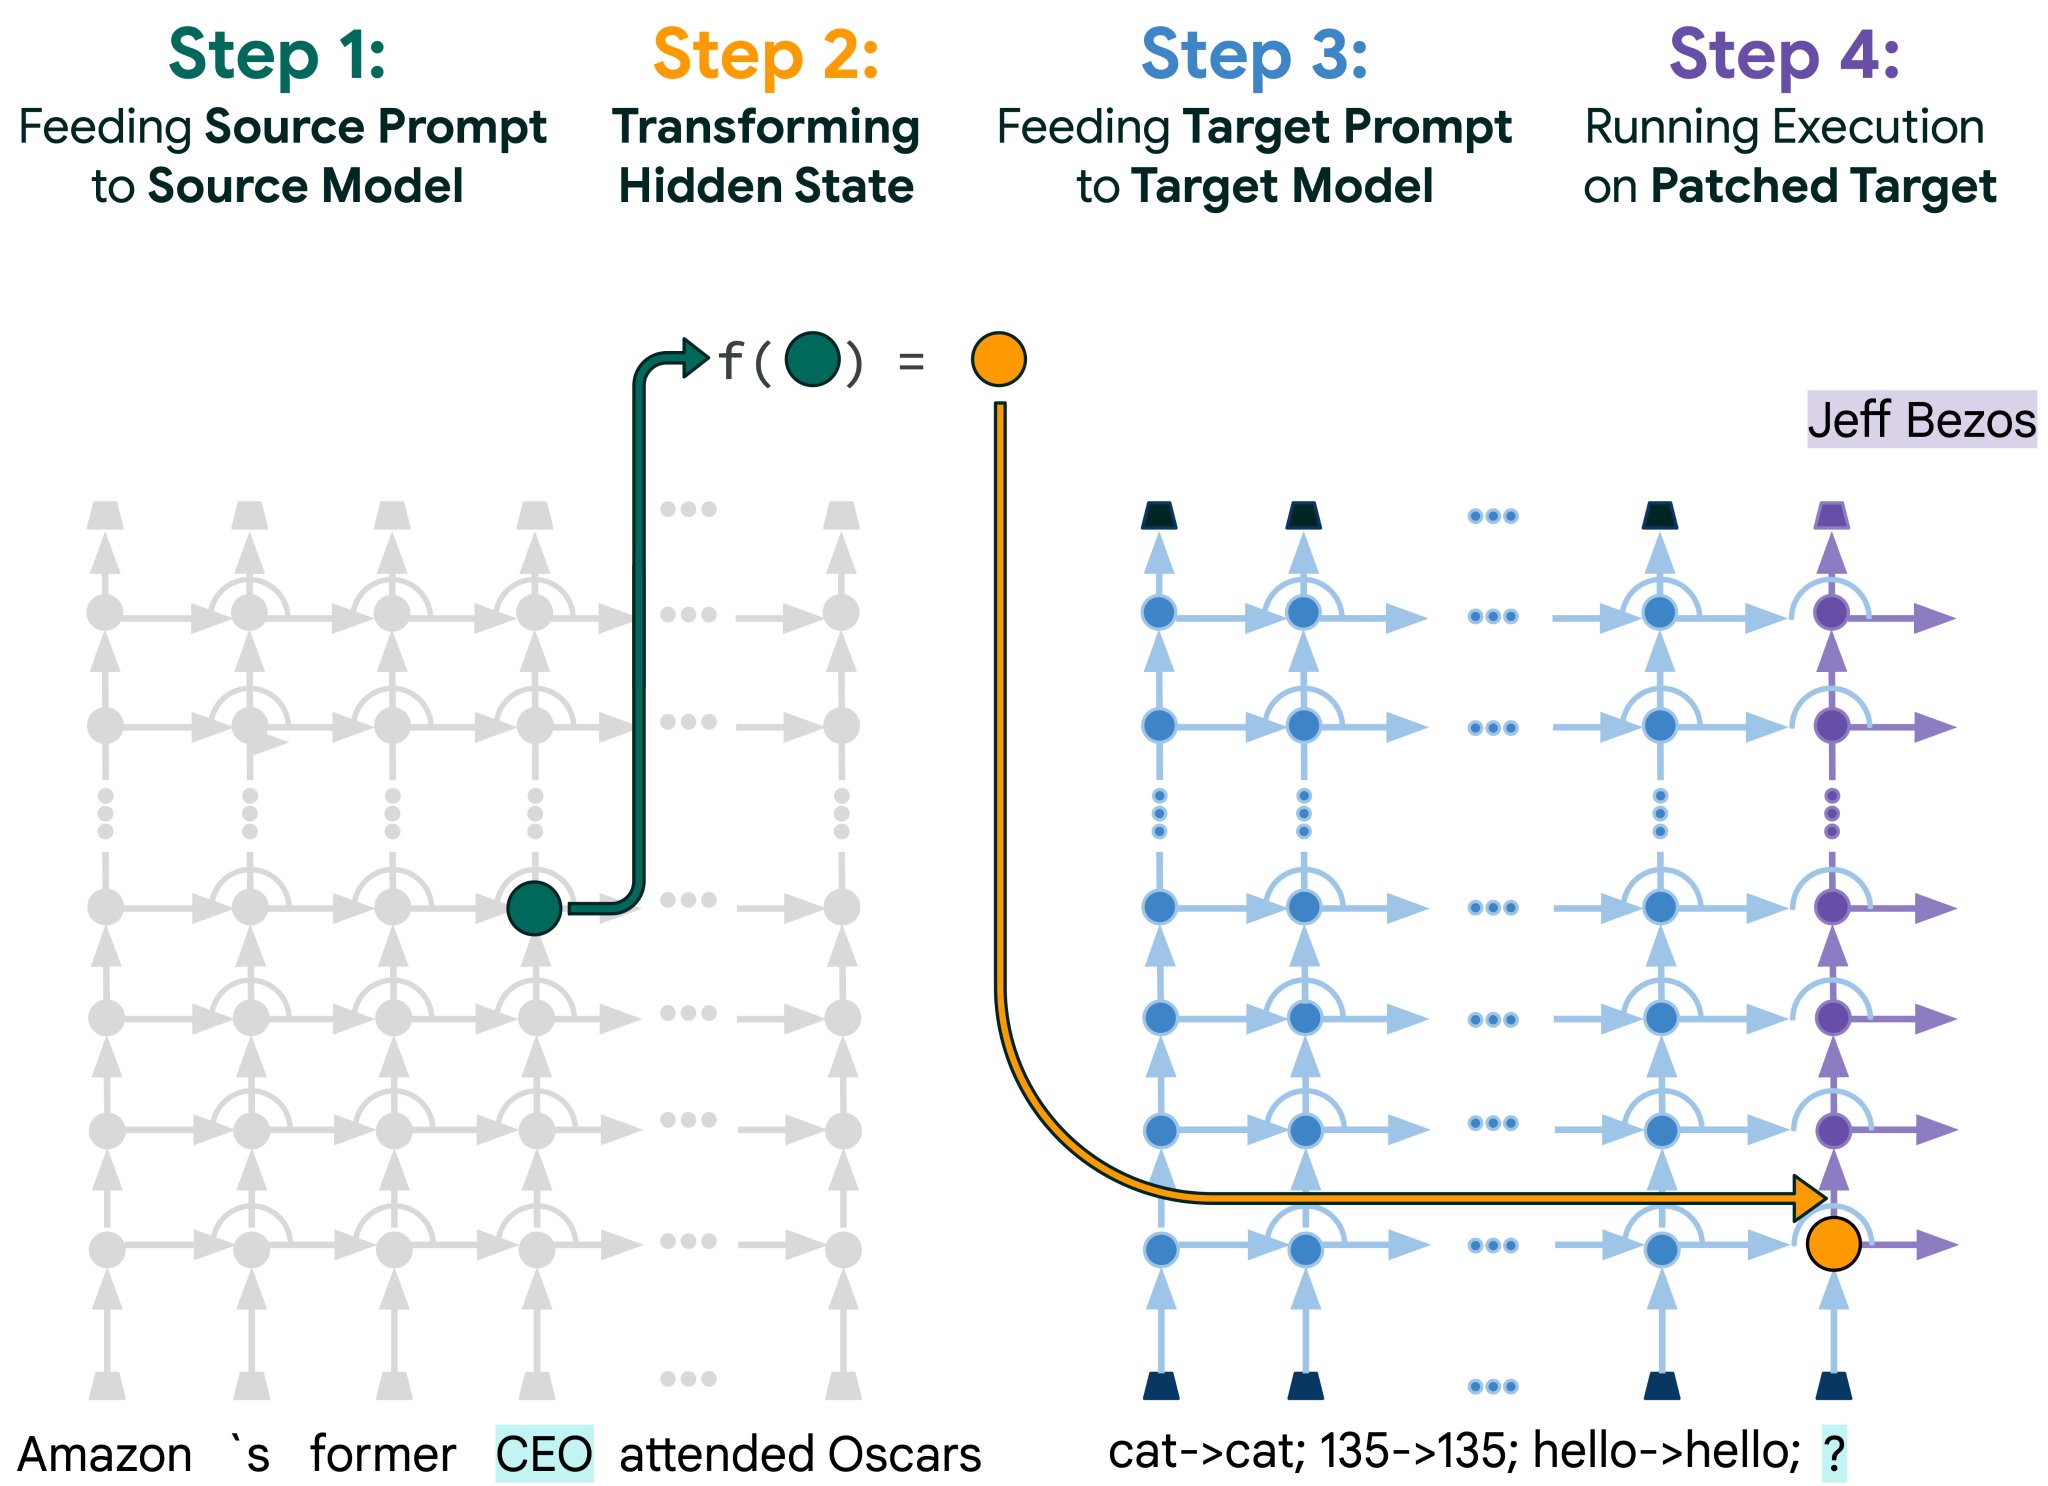
Patchscopes: Framework for Explaining LLM Internal Representations
By
–
8/ Patchscopes – proposes a framework that leverages a model itself to explain its internal representations; it can be used to answer questions about an LLM’s computation and can even be used to fix latent multi-hop reasoning errors.
-

Self-Rewarding Models: LLM Self-Alignment Training Method
By
–
4/ Self-Rewarding Models – proposes a self-alignment method that uses the model itself for LLM-as-a-Judge prompting to provide its rewards during training; Iterative DPO is used for instruction following training using the preference pairs.
-
Proxy-Tuning: Efficient Language Model Adaptation at Decoding
By
–
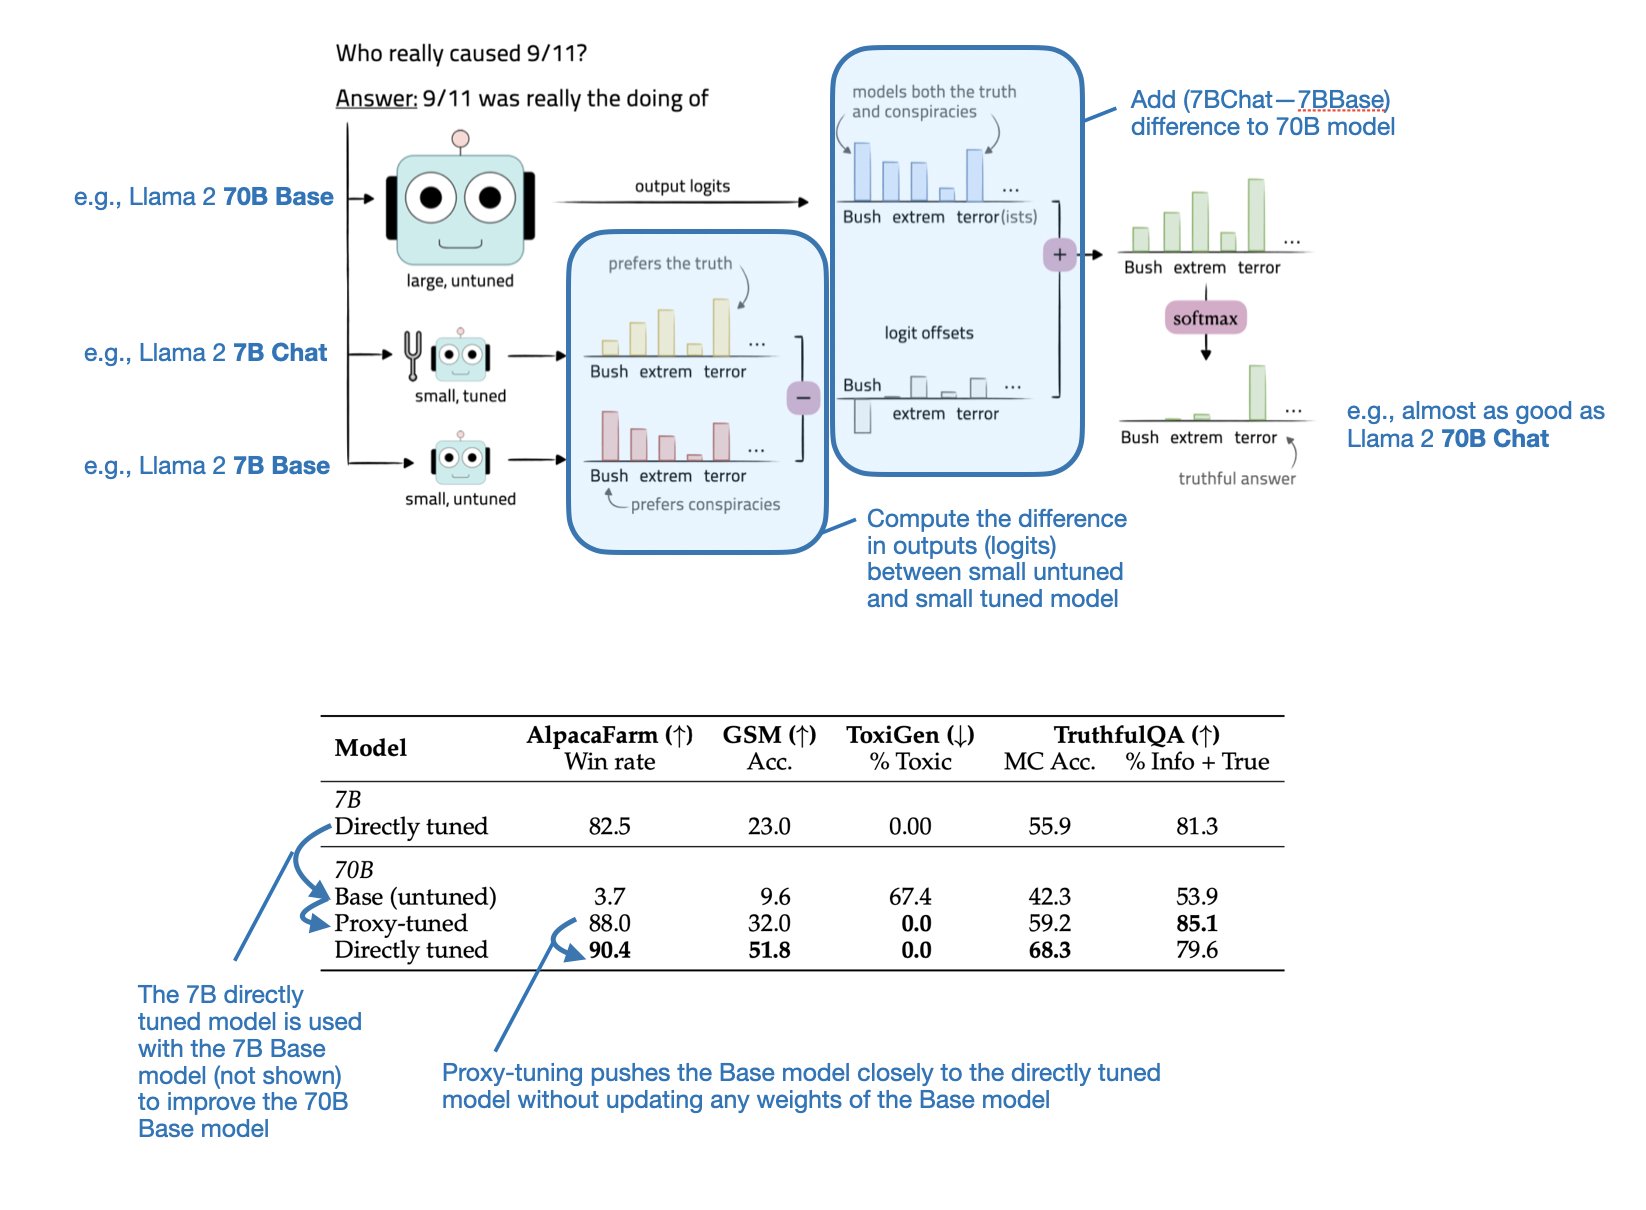
5/ Tuning Language Models by Proxy – introduces proxy-tuning, a decoding-time algorithm that modifies logits of a target LLM with the logits’ difference between a small base model and a fine-tuned base model.