Max Welling is one of the smartest, most influential, most thoughtful and nicest researchers I’ve met, during my 30 years working on AI. I highly recommend checking his talk. He’s one of the real AI
RESEARCH
-

Guiding LLM Output with DSPy Assertions and Suggestions
By
–
Guiding LLM Output with DSPy Assertions and Suggestions https://
bit.ly/4bAMV85 #AI #MachineLearning #DeepLearning #LLMs #DataScience -

Mistral Releases Mathstral 7B and Codestral Mamba Models
By
–
Today we are releasing two small models: Mathstral 7B and Codestral Mamba 7B. On the MATH benchmark, Mathstral 7B obtains 56.6% pass@1, outperforming Minerva 540B by more than 20%. Mathstral scores 68.4% on MATH with majority voting@64, and 74.6% using a reward model. Codestral
-

Mistral Releases MathΣtral and Codestral Mamba Research Models
By
–
As the Olympic season reaches Paris, we express our respect to ancient Greeks by releasing two new research models, MathΣtral and Codestral Mamba.
-

Mistral Releases Mathstral and Codestral-Mamba Models
By
–
https://
mistral.ai/news/mathstral/ https://
mistral.ai/news/codestral
-mamba/
… -

Neural Network Training Method: Forward Pass, Backward Pass, Weight Updates
By
–
Now a method to train the neural network using both the forward and backward passes. The function will run for specified no of epochs, calculating: 1. The Forward Pass
2. Backward Pass
3. Updating the Weights -

Update Weights Learning Rate Hyperparameter Optimization Neural Networks
By
–
Now Update the Weights: Here learning rate is the hyper parameter! A low learning rate can cause the model getting caught in local optima, while the high learning rate can cause the model to overshoot the general solution W1 += learning_rate * d_W1
b1 += learning_rate * d_b1 -
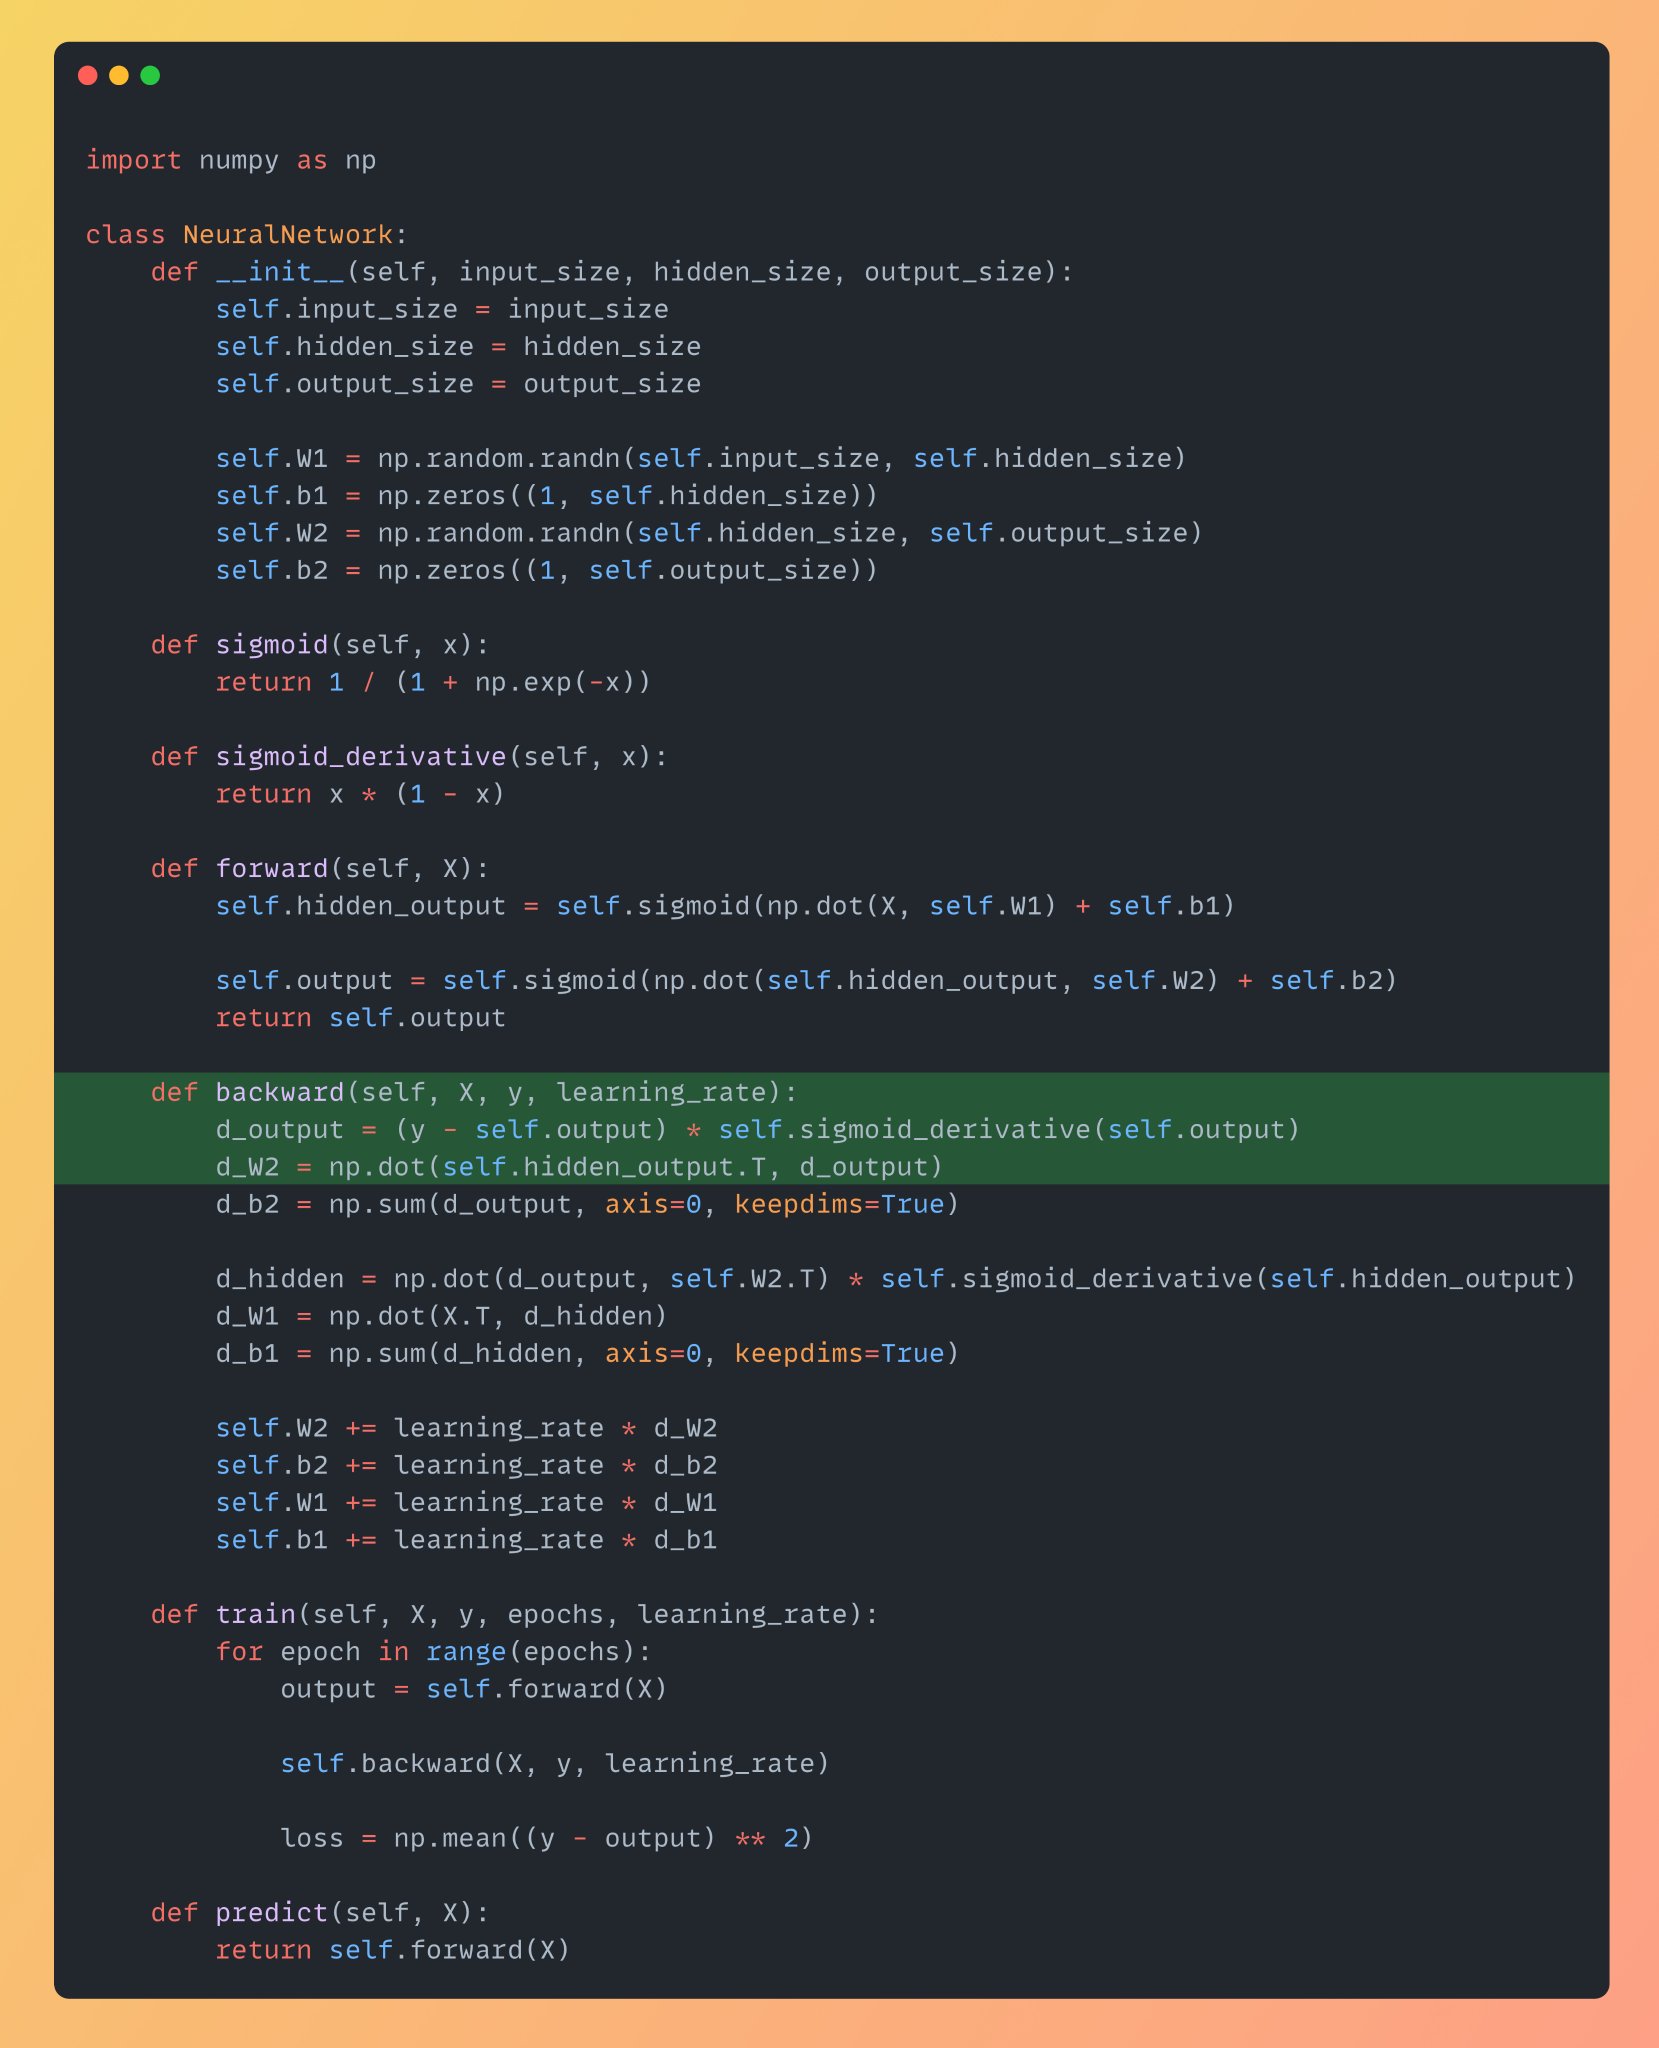
Backward Pass: Computing Output Layer Gradients and Weight Updates
By
–
Backward Pass: First compute the gradients of the output layer. Loss = (y – output) Gradient of Loss = (y – output) * sigmoid_derivative(output) Now calculate d_W2 which is gradient of the loss function with respect to W2. d_W2 = hidden_output.T • Gradient of Loss
-
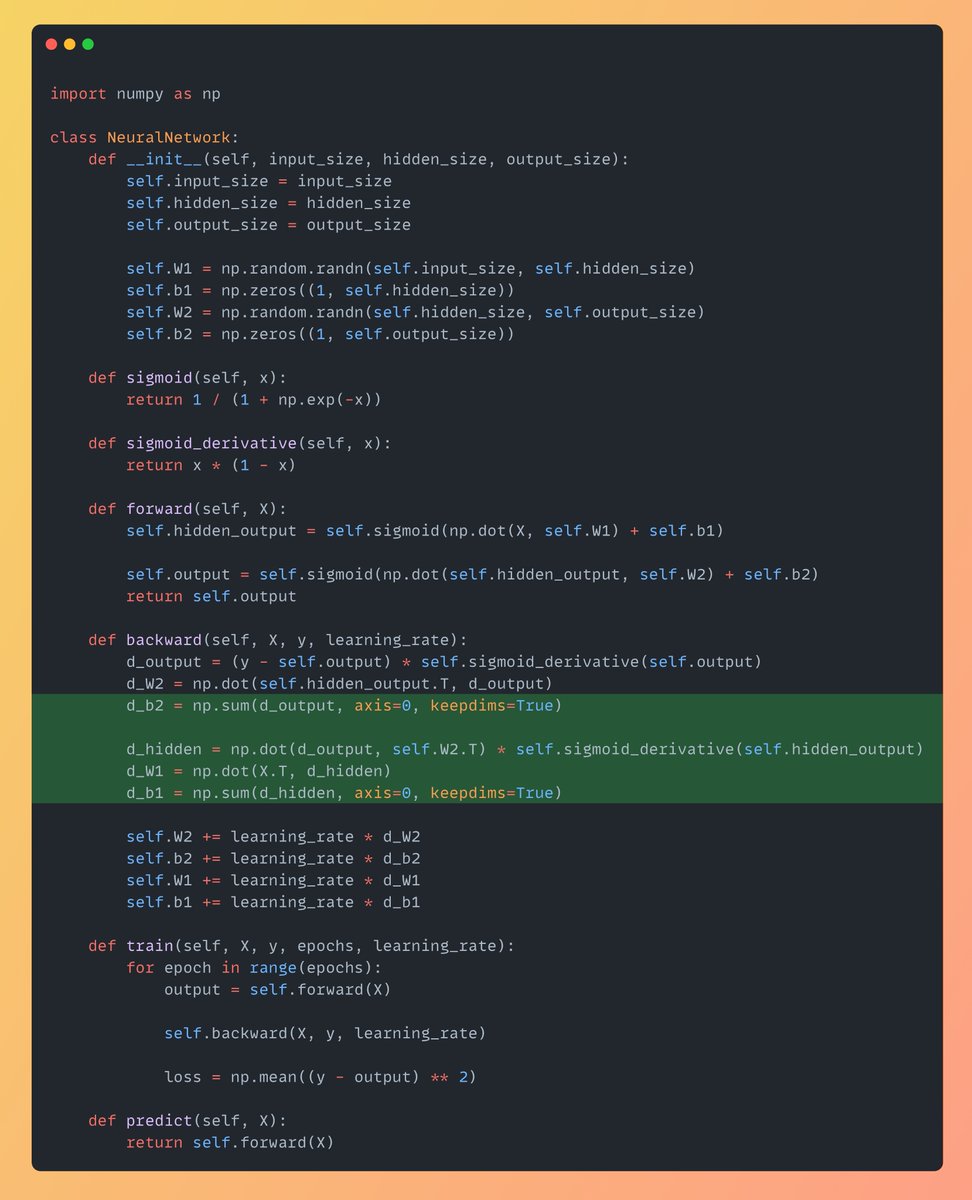
Calculate Gradients dW1, db2, db1 for Neural Network Backpropagation
By
–
Similarly calculate d_W1, d_b2 & d_b1 dW1: Gradient of the loss function wrt W1 d_b2: Gradient of the loss function wrt b2(bias of neuron in output layer) d_b1: Gradient of the loss function wrt b1(bias of neuron in hidden layer)
-
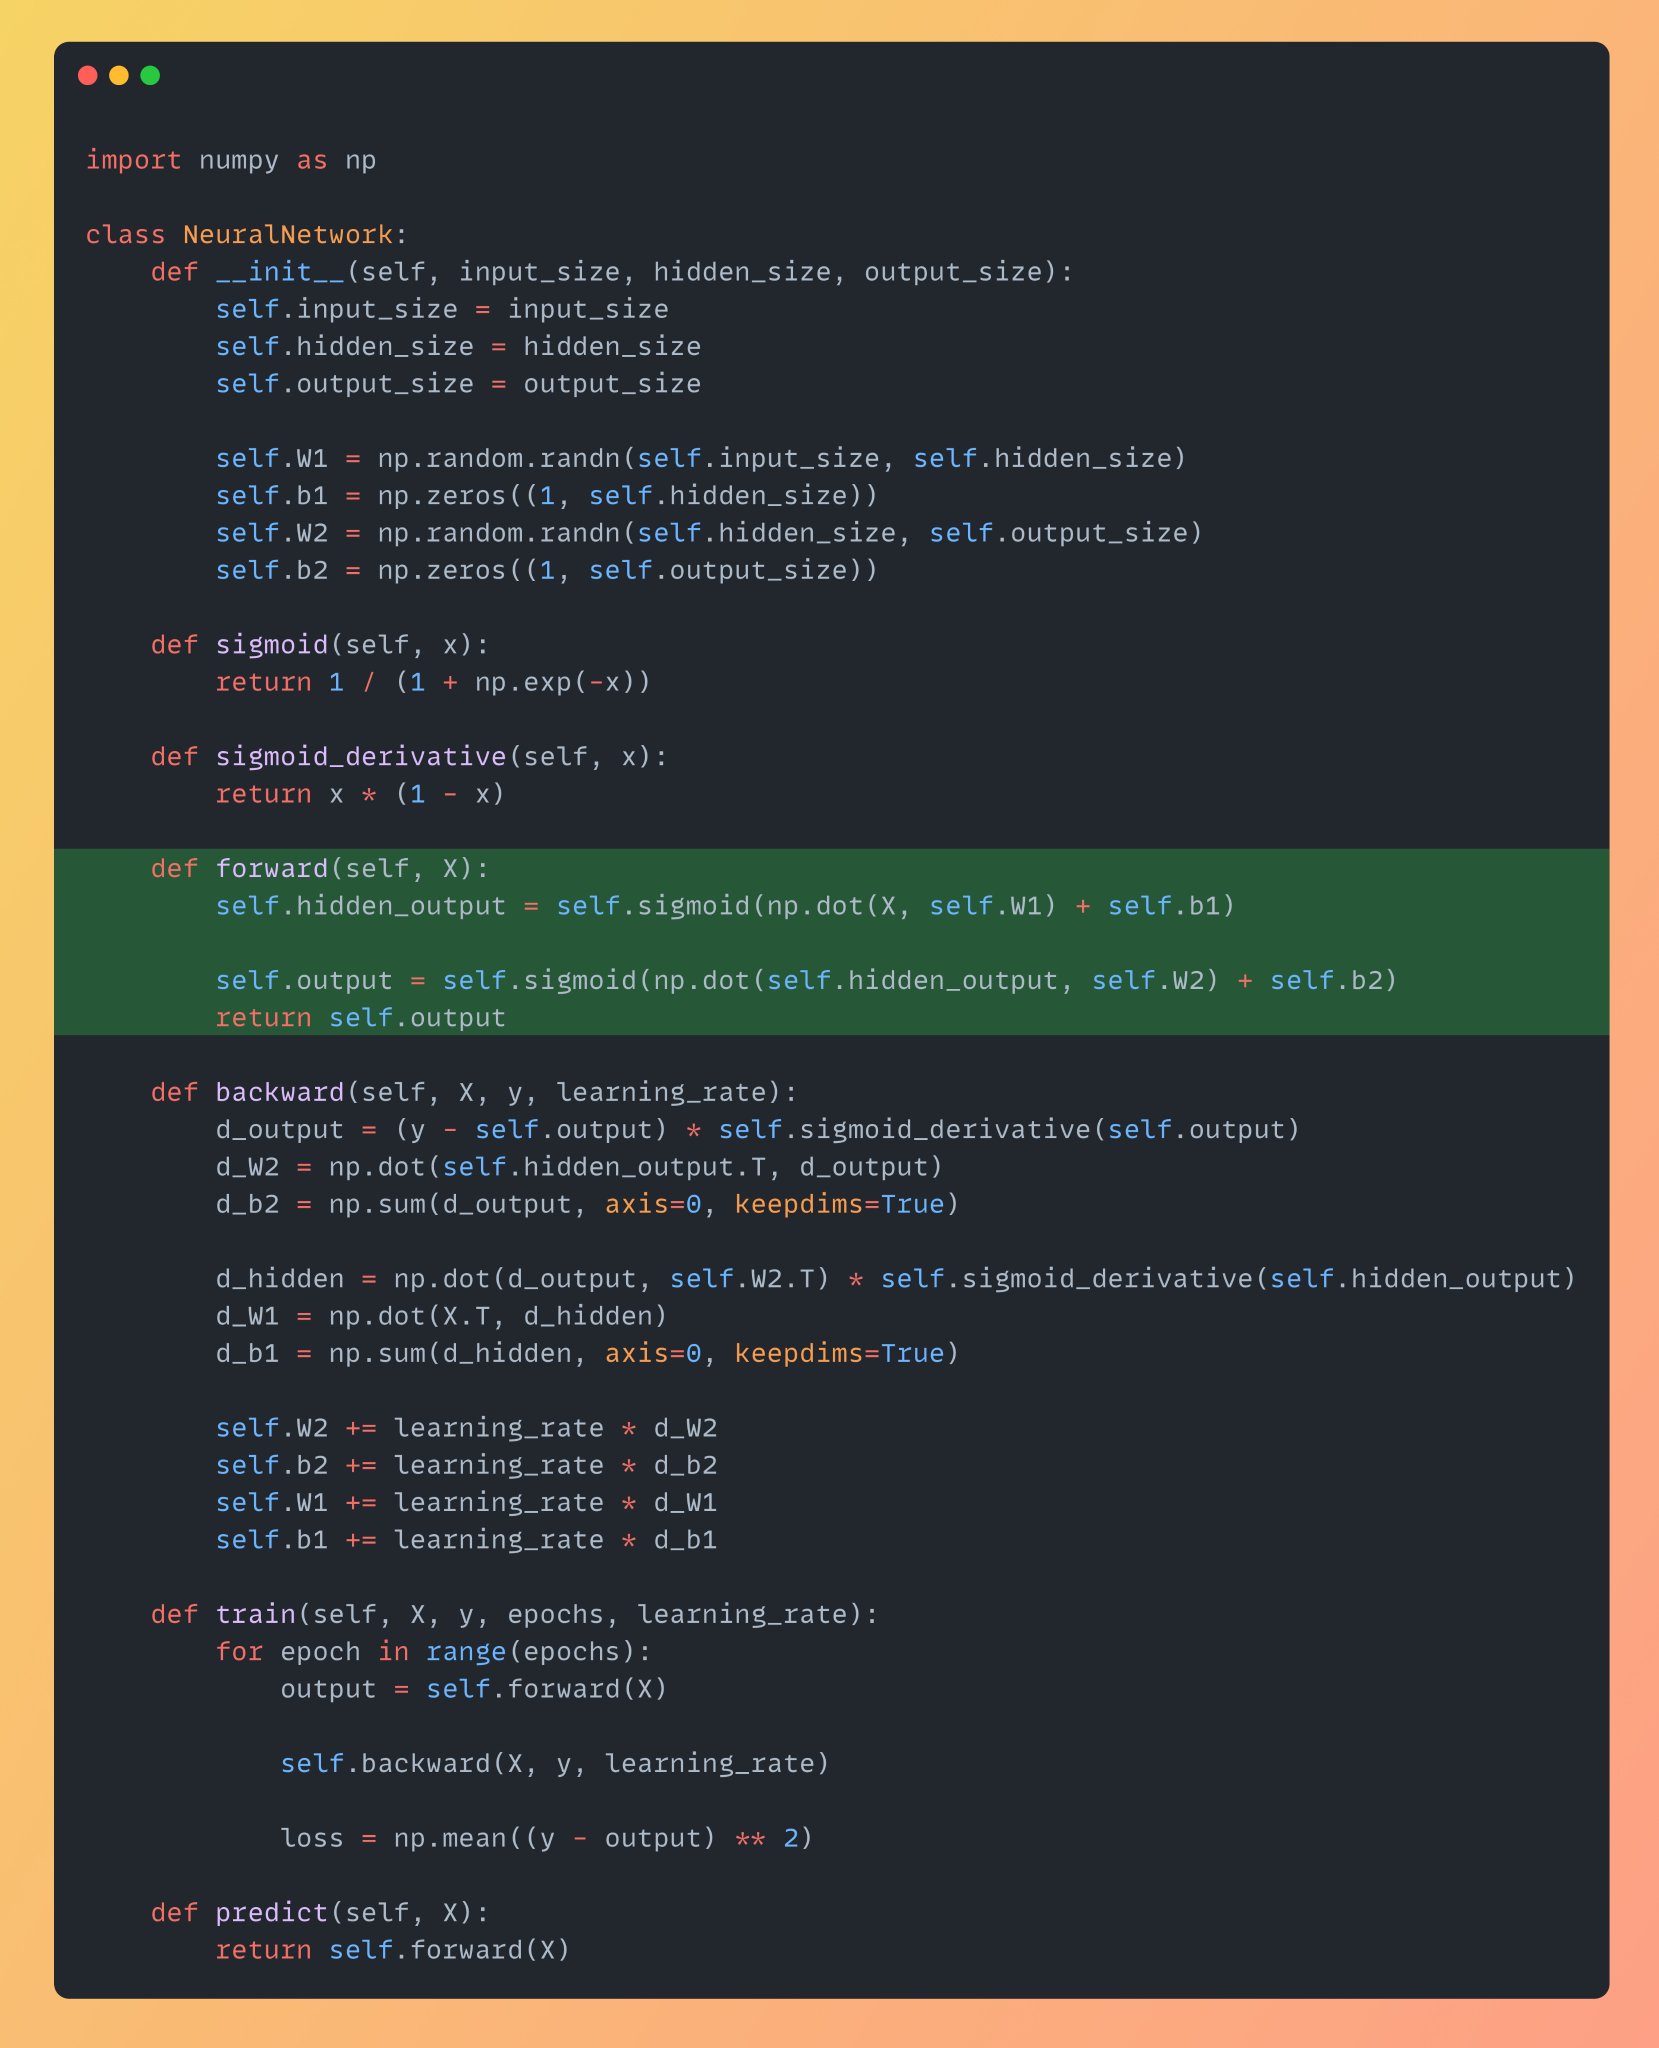
Forward Pass in Neural Networks: Hidden Layer Calculation and Activation
By
–
Forward Pass: Here the input data is passed through the neural network to obtain the predicted output. In forward pass, First calculate the output of the hidden layer. hidden_output = X•W1 + b1 Then apply the sigmoid activation to the output. output = sigmoid( (X•W1) + b1)