Also see this project from @asankhaya
, which now incorporates the core ideas of PlanSearch (one day after the paper!)
RESEARCH
-

Project Incorporates PlanSearch Ideas
By
–
-
AI Use Guidelines: Testing, Understanding, and Quality Assurance
By
–
Feel free to use AI to help contribute to any of my projects. BUT: Be sure you fully understand exactly what it's doing, you've thoroughly tested and proof-read any outputs, & that it's work you're proud of and are ready to stand behind. Edit prose & refactor code vigilantly.
-
Use AI Responsibly: Understand, Test, and Stand Behind Your Work
By
–
Yeah for sure – I'm not saying don't use AI. I'm saying if you use it, make sure you fully understand exactly what it's saying/doing, that you've thoroughly tested and proof-read any outputs, and that it's work you'd be genuinely proud of and are prepared to stand behind.
-
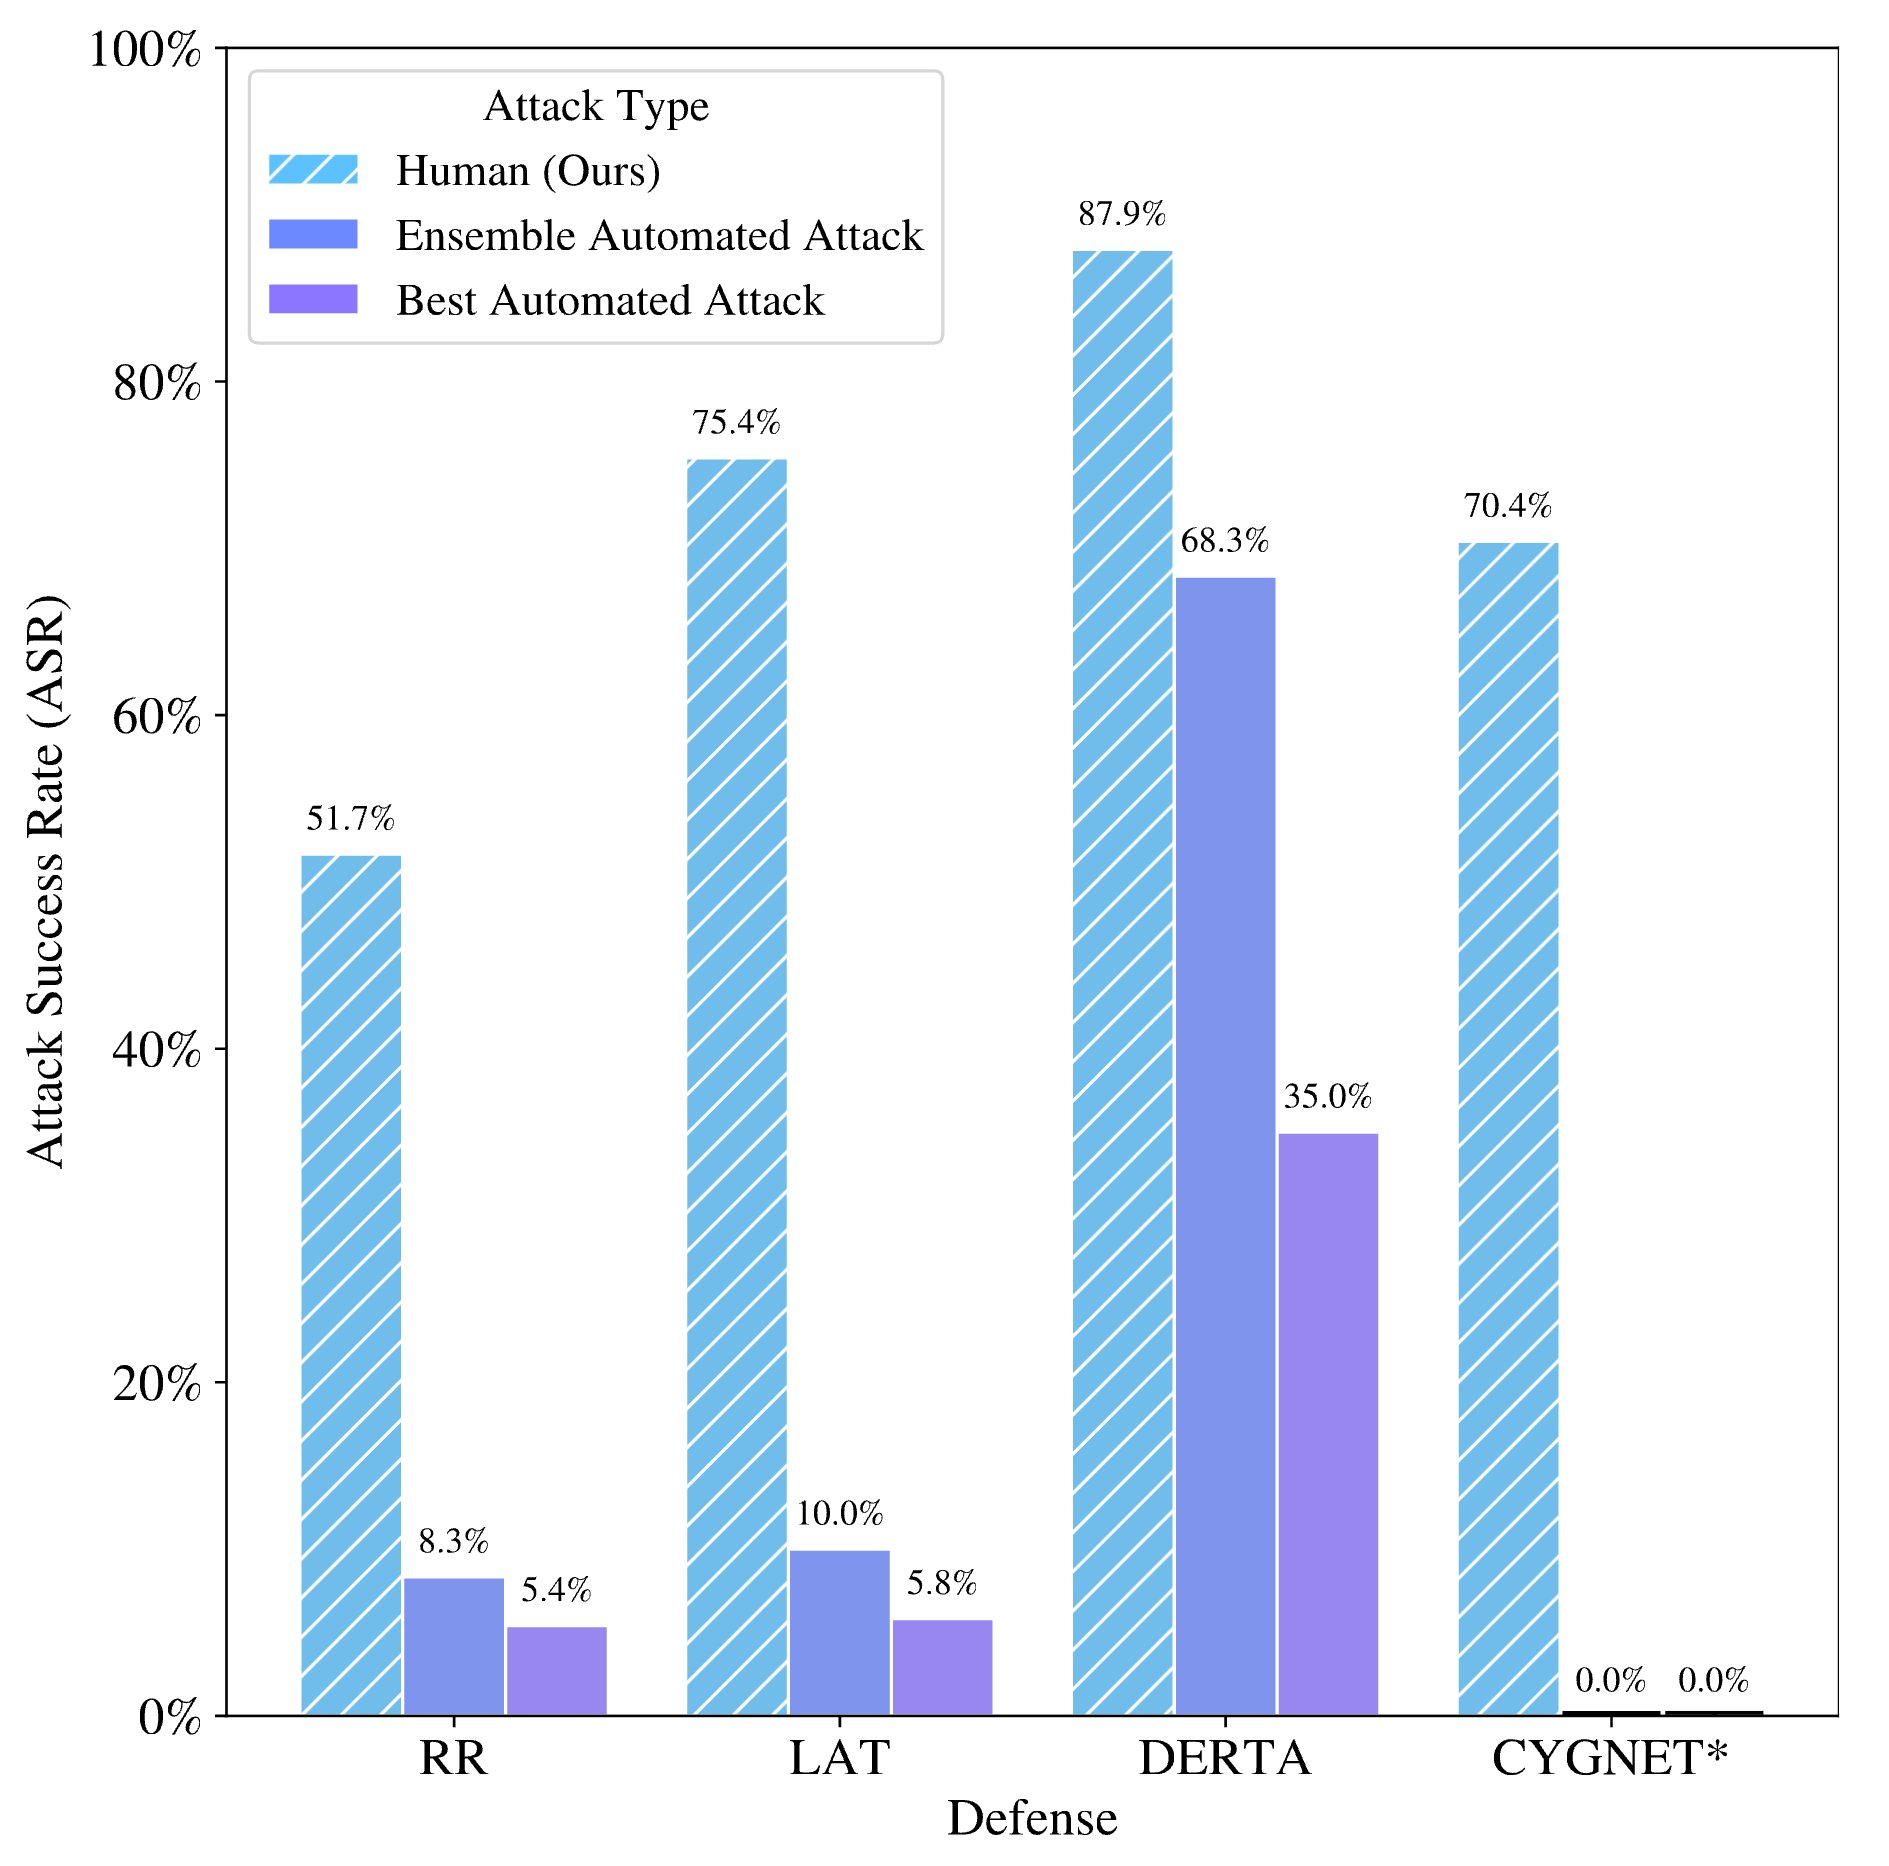
Human Red-Teamers Outperform Automated Methods in Multi-Turn Jailbreaks
By
–
ICYMI: New research from SEAL that demonstrates human red-teamers massively outperform automated methods over multiple turns. We also release MHJ, a dataset of multi-turn jailbreaks to help enable further research into multiturn red teaming
-
Comparing ML and Theory Conference Review Workload Differences
By
–
All of the above. Contrast:
ML conf – 6 papers to review, written in a rush, often of tangential interest. Repeat 3x/yr
Theory conf – 3 papers to review *max*, generally long technical papers that couldn't be rushed, and I am an expert in every paper I review. Repeat 1-3x/yr 1/2 -
Differences Between Theory CS and ML Conferences
By
–
The difference between theory CS and ML conferences.
-
Light Fine-Tuning and Reflection Techniques in AI Development
By
–
It's a similar idea with light fine-tuning on top. But even reflexion wasn't a new idea back then
-
Chat Template Fix Boosts IFEval Performance by 30-40 Points
By
–
The chat template in the tokenizer config was wrong. Just updating it gave something like +30-40 points on IFEval.
-
Model Comparison Methodologies and API Evaluation Fairness
By
–
The same can be done with any model. This is why researchers specify n-shot, CoT, etc. The model behind an API will be super useful and could even be better than any other model (in theory). But this comparison is wrong nonetheless.