PFLOPS = 1 quadrillion calculations per second!
With such immense computational power, AIRAWAT drives breakthroughs in AI research making India a global AI powerhouse. For more information, tap here: https://
airawat.cdac.in
RESEARCH
-

AIRAWAT Supercomputer Drives India’s AI Research Breakthrough
By
–
-
O1 model reception shifts rapidly among users
By
–
fun watching the vibes shift so quickly on o1 🙂 glad you like it!
-

Phrase Matching Techniques in Marginalia Search Engine
By
–
Phrase Matching in Marginalia Search https://
bit.ly/4gf76v4 #AI #MachineLearning #DeepLearning #LLMs #DataScience -

Zongyi Li’s Neural Operators Advance AI and Science
By
–
.@ZongyiLiCaltech has done extremely impressive work in AI+Science at @Caltech from inventing Neural Operators to showing performance in a wide range of domains.
-
UC Berkeley AI Ranking Project Becomes Industry’s Leading System Benchmark
By
–
Work led by BAIR students @ml_angelopoulos and @infwinston has "…quickly become the most-watched ranking of the world’s best AI systems." https://
wsj.com/tech/ai/the-uc
-berkeley-project-that-is-the-ai-industrys-obsession-bc68b3e3
… @Cal_Engineer @UCBerkeley @Berkeley_EECS -
Rating Answers Easier Than Providing Perfect Ground Truths
By
–
Finally, it also has the benefit of being easier to do thanks to rating answers rather than having to provide perfect ground truths.
-
SFT and RL Fine-Tuning: Complementary Approaches for Model Optimization
By
–
I think that SFT will remain useful for fine-tuning a model to a new specific task, and RL fine-tuning becomes an interesting additional toolset further to push the model toward a desired kind of answer while also allowing it more flexibility in the way it “thinks” of the answer
-
OpenAI’s RLFT Boosts o1-mini Accuracy in Law, Finance, Engineering
By
–
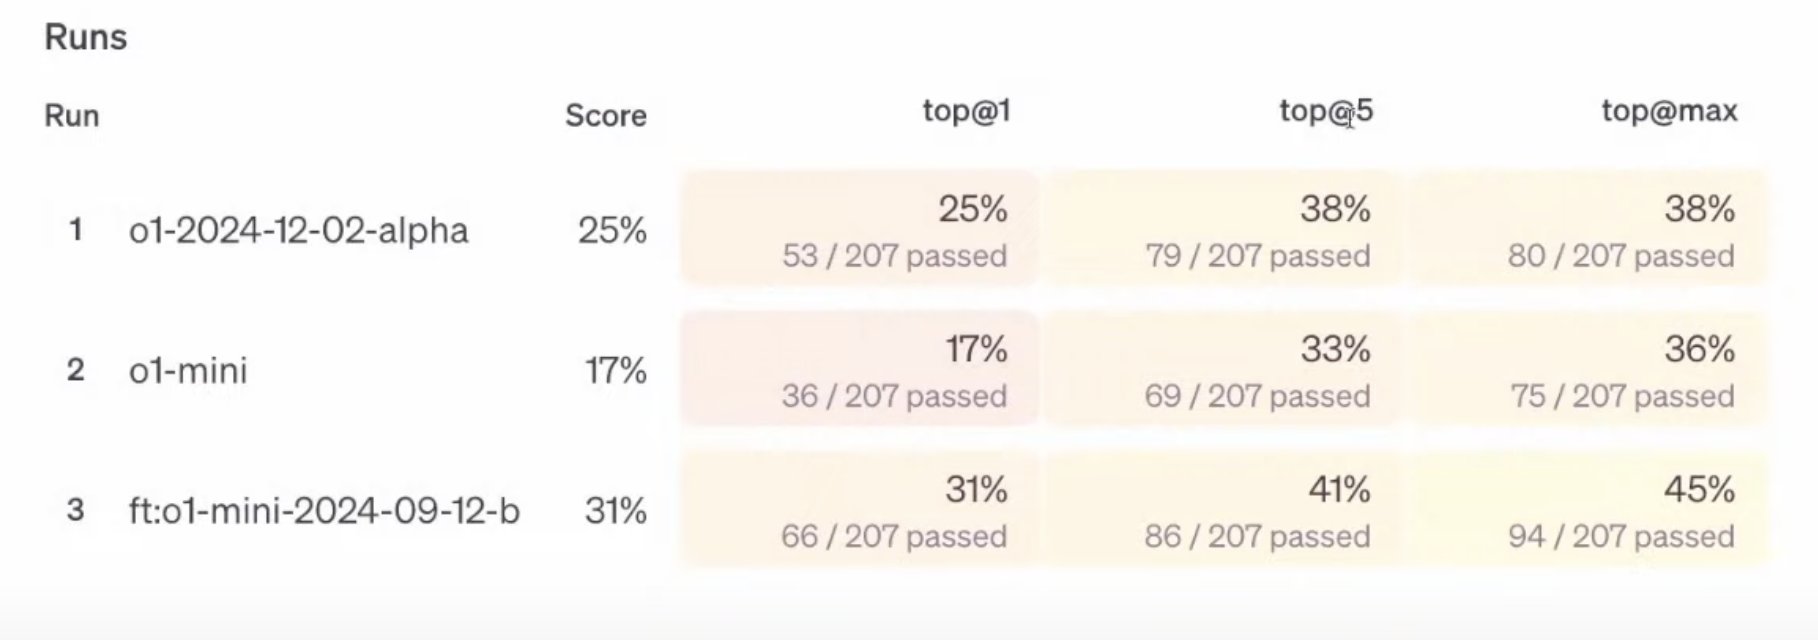
OpenAI sees huge potential in domains like Law, Finance, and Engineering, where “objectively correct” answers matter. Early results are promising: RLFT helped o1-mini boost accuracy in a gene example from 25% to 31%!
-
Question-Answer Pairs Training Without Perfect Ground Truth
By
–
Why is this interesting? It lets us use question-answer pairs without needing the full chain-of-thought input or even a perfect ground-truth output for SFT. Graders can assign nuanced scores (0–1), improving model outputs incrementally—even when answers are partially
-
RLFT Evaluates Complete Answers Instead of Individual Tokens
By
–
Instead of evaluating each token, one at a time, RLFT grades entire answers—perfect for scenarios like OpenAI’s o1, where we can’t access intermediate tokens before the “end_of_thought.”