Yep. Because it was right after Google bought Deepmind.
RESEARCH
-
AI Transforming Internal Research Publishing and Education Initiatives
By
–
Use cases are flooding my mind right now. @MikeKaput and I already met to explore how it could transform our internal research, publishing and education initiatives.
-
Inner Monologues of Language Models Explained
By
–
the inner monologues of language models on @airstreetpress… pic.twitter.com/hKgm4zlmma
— Nathan Benaich (@nathanbenaich) 13 décembre 2024the inner monologues of language models on @airstreetpress
… -
Curriculum Learning: Progressive Neural Network Training Strategy
By
–
We didn't investigate this very intensely but my intuition is that this acted like a curriculum, so that you could learn the "short" connections first, and start going backwards. C' B' A' A B C (learning A' to A translation is simple as there aren't many layers in between).
-
LTM Benchmarking Paper for LLM Agents at NeurIPS 2024
By
–
Our paper on LTM Benchmarking at NeurIPS 2024 LTM = Long-Term Memory for LLM agents
-

India AI Innovation Challenge: Building Safe, Robust Ecosystem
By
–
The following Applicants can participate to make India’s AI ecosystem robust and safe by design:
-Educational Institute
-Academic/R&D Organization
-Start-ups and Companies
-Autonomous Bodies
#InnovationChallenge #IndiaAI #AICompliance #EOICriteria -
MoEs for Production Usage in AI Systems
By
–
Yeah! But that’s okay no? I see MoEs more for actual production usage.
-

Three Megatrends Shaping Futures: AI, Quantum, Renewables
By
–
3 #Megatrends Shaping our Futures People: 68% Urban by 2050; 367K Quantum Grads in 2023; Life Expectancy: 73 yrs Tech: #AI market to $1.6T by 2030; Data to 292ZB in 2025; $500B Space Economy Resources: Renewables at 29%, $4.5T by 2030 via @mikequindazzi
-
DeepSeek-VL2: Enhanced Multimodal Model with Dynamic Tiling
By
–
Improvements from v1: > 2x high-quality training data vs DeepSeek-VL1
> Dynamic image tiling for flexible resolutions + efficient DeepSeek-MoE for LM
> 3-stage training + new multi-modal parallel strategies for efficiency -
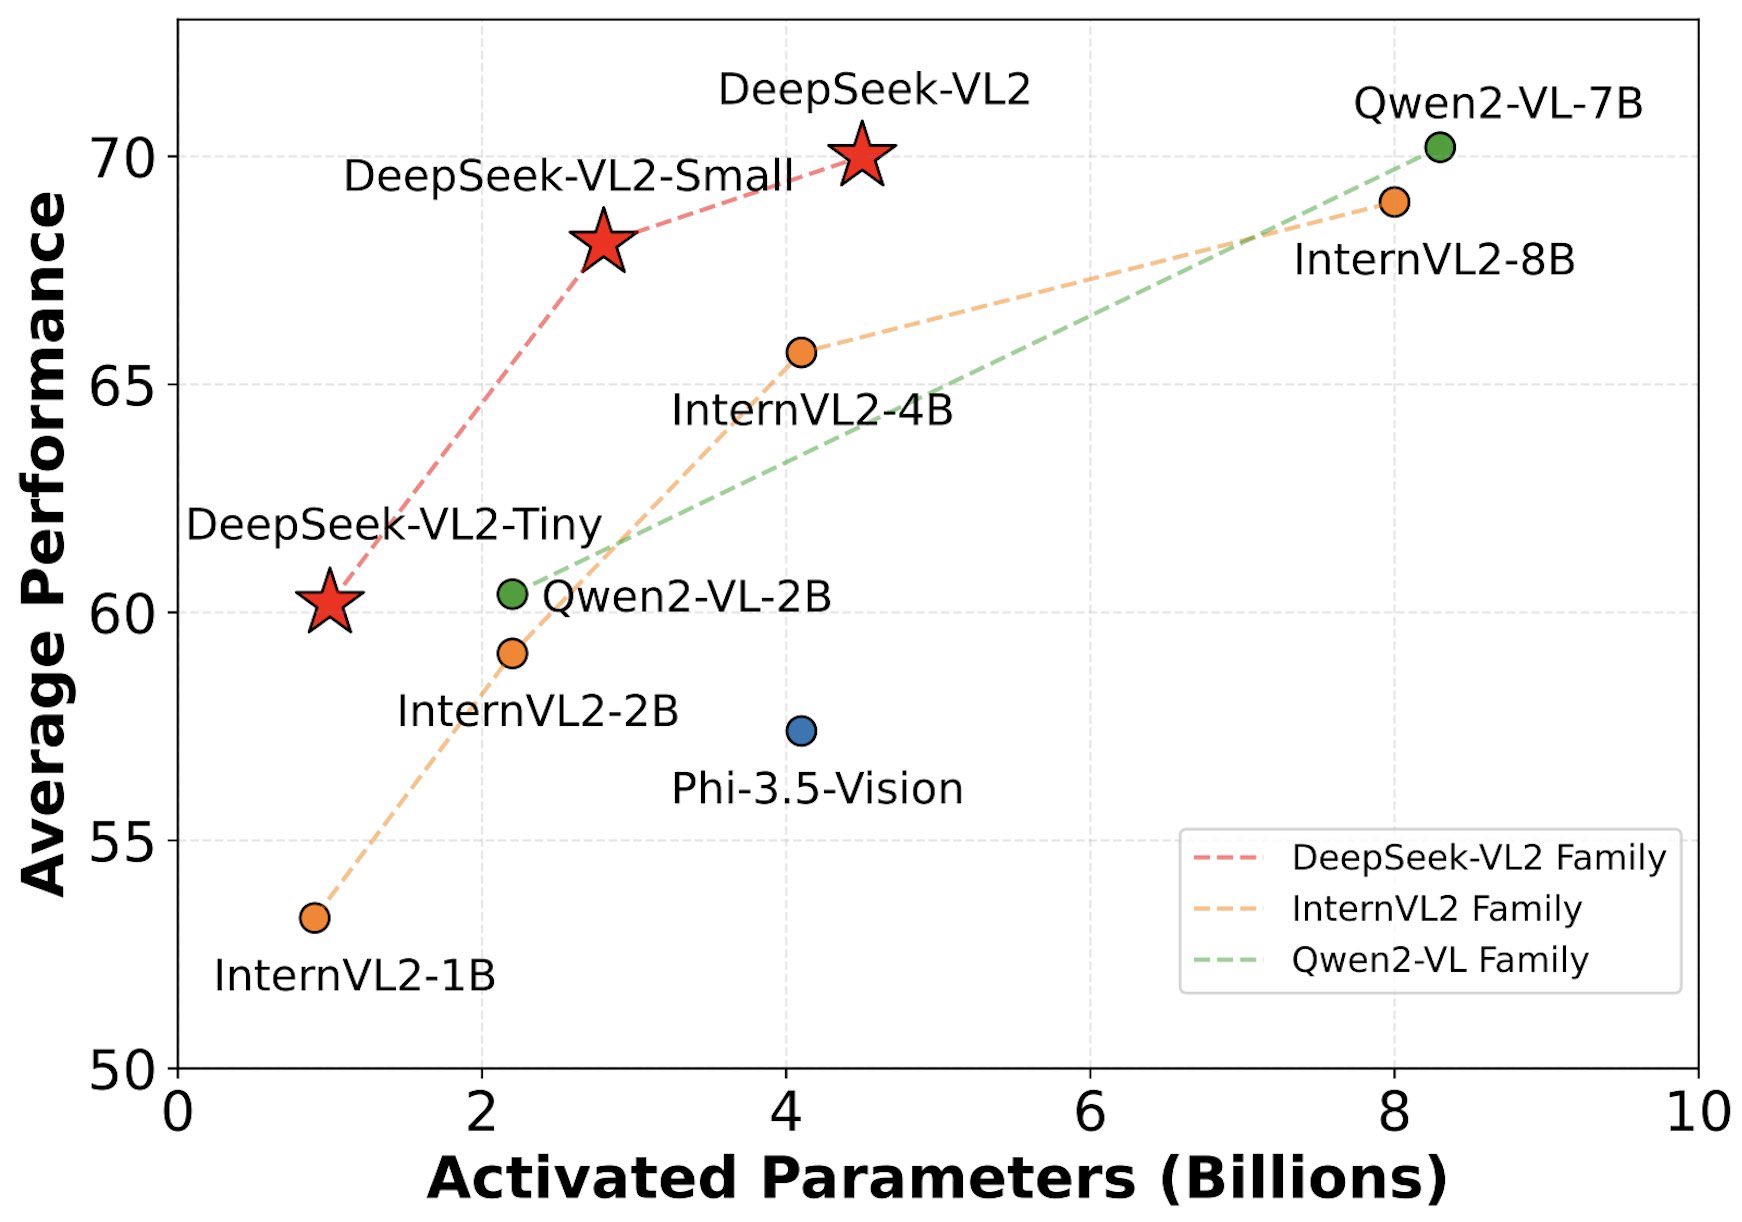
DeepSeek-VL2 Achieves SoTA Vision Performance with Fewer Parameters
By
–
The whale strikes again! DeepSeekVL 2 > DeepSeek-VL2-Tiny, DeepSeek-VL2-Small, and DeepSeek-VL2, with 1.0B, 2.8B, and 4.5B activated parameters
> SoTA perf with similar or fewer activated parameters compared to Qwen 2 VL
> Excels at visual question answering, optical