– the emergence of "AGI" (whatever your definition) will not be an event. It will be progressive.
– once it appears somewhere, it will be reproduced by many in a relatively short time.
– you say that AI innovations originated in the US. It's not entirely true. Although many
RESEARCH
-
AGI emergence will be gradual not sudden
By
–
-

Perplexity’s Auto Mode for Task-Specific Search
By
–
Perplexity is working on the "Auto" mode, which can automatically switch between Pro search and reasoning depending on the task. An option to "rewrite" a response with a specific model is still available.
-

Qwen Narrows Gap Between Plus and Max
By
–

Qwen has updated its Qwen2.5-Plus model, reducing the performance gap between Plus and Max—the most advanced Qwen model available.
-

AI Plumbers Conference at FOSDEM Fringe Event
By
–
Ghent, see you at @fosdem fringe tomorrow. Find out more –> http://
bit.ly/AIPlumbersConf
erence
… -

TensorLLM Framework Achieves 250x MHA Weight Compression
By
–
9). TensorLLM Proposes a framework that performs MHA compression through a multi-head tensorisation process and the Tucker decomposition. Achieves a compression rate of up to ∼ 250x in the MHA weights…
-

Improving RAG Through Multi-Agent Reinforcement Learning
By
–
8). Improving RAG through Multi-Agent RL It models RAG components like query rewriting, document selection, and answer generation as RL agents working together toward generating accurate answers.
-

DeepSeek-R1 Usage Recommendations and Prompting Guide
By
–
6). Usage Recommendation for DeepSeek-R1 This work provides a set of recommendations for how to prompt the DeepSeek-R1 model.
-
Docling: Open-Source Document Parsing Toolkit
By
–
7). Docling Docling is an open-source toolkit that can parse several types of popular document formats into a unified, richly structured representation. https://
arxiv.org/abs/2501.17887 -
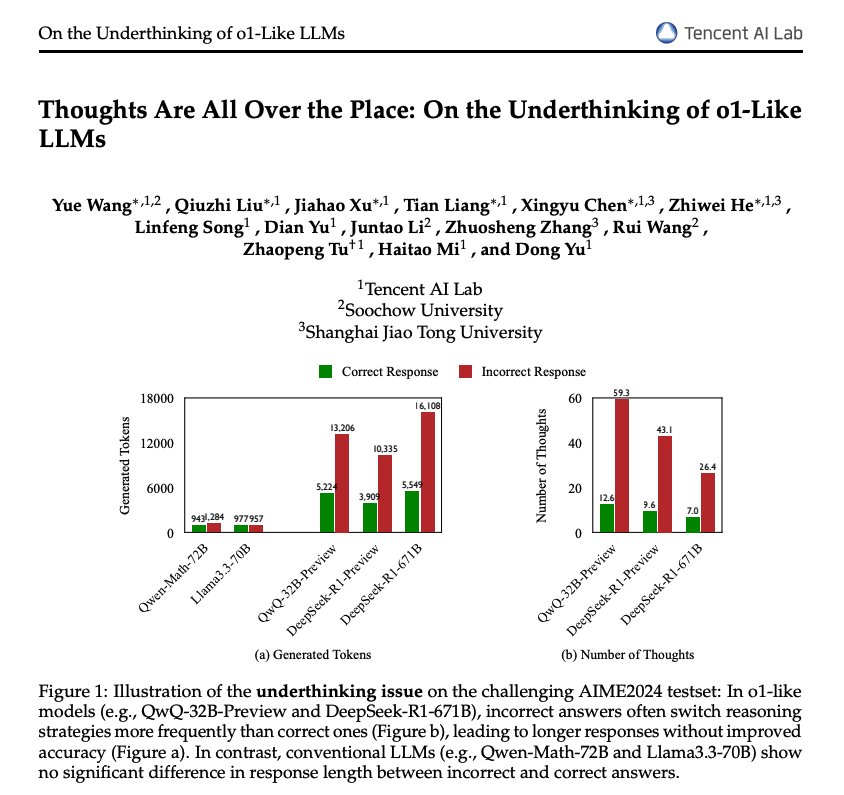
O1-like LLMs underthinking patterns and limitations
By
–
4). On the Underthinking of o1-like LLMs Looks more closely at the "thinking" patterns of o1-like LLMs. We have seen a few recent papers pointing out the issues with overthinking.
-

Diverse Preference Optimization: Novel Training Method for Language Models
By
–
5). Diverse Preference Optimization A novel training method that aims to address the lack of diversity in language model outputs while maintaining response quality.