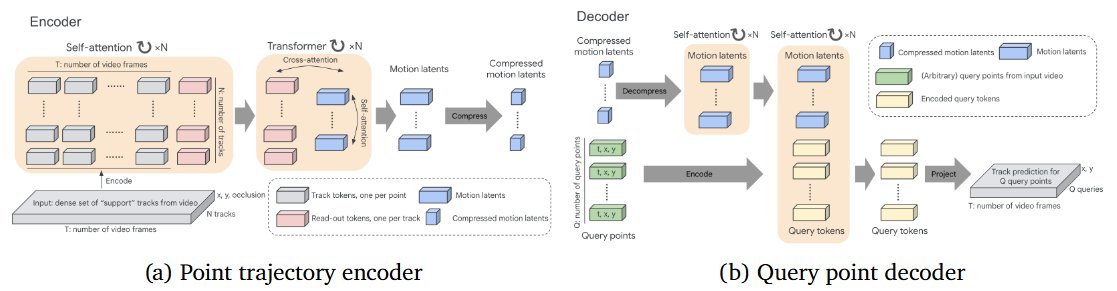
Direct Motion Models for Assessing Generated Videos This paper introduces TRAJAN, a new motion-centric evaluation method for generative video models that captures temporal inconsistencies more effectively than metrics like Fréchet Distance (FVD), enabling both
RESEARCH
-
Mem0: Scalable Long-Term Memory for Production AI Agents
By
–
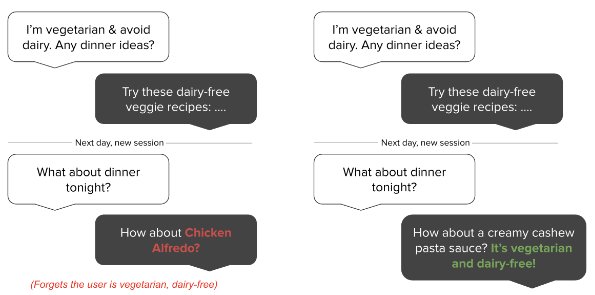
Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory The paper introduces Mem0, a scalable memory architecture for AI agents that enables long-term conversational coherence by dynamically extracting, consolidating, and retrieving salient information across
-
Chatbot Arena Leaderboard Biases Distort LLM Quality Perception
By
–
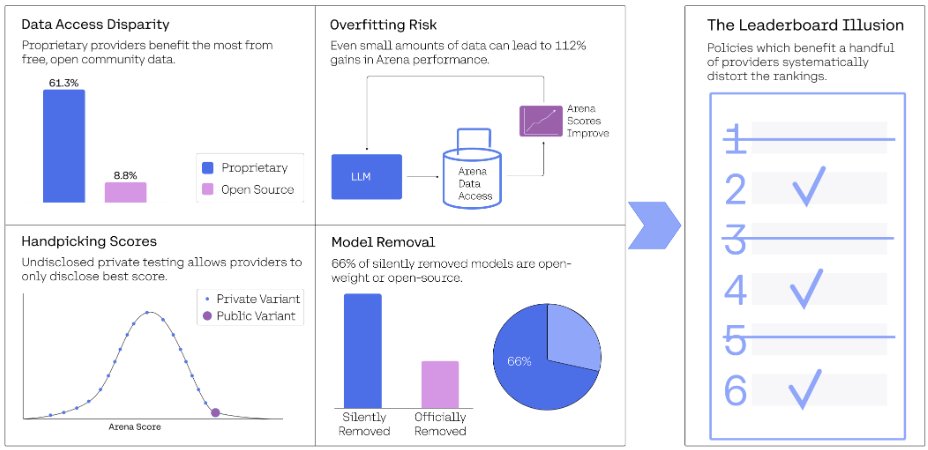
The Leaderboard Illusion This study investigates structural biases in Chatbot Arena, a widely used leaderboard for evaluating large language models (LLMs), revealing how selective testing practices and data access asymmetries distort perceptions of model quality. Problem: While
-
X-Fusion Adds Vision to Frozen Language Models
By
–
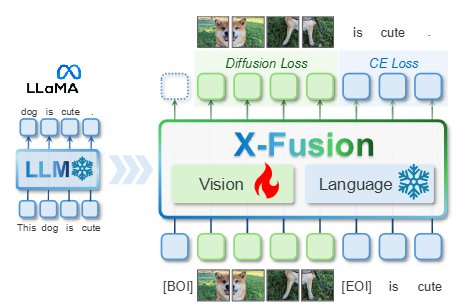
X-Fusion: Introducing New Modality to Frozen Large Language Models X-Fusion is a dual-tower framework that introduces vision capabilities to pretrained large language models (LLMs) without altering their language weights, enabling unified multimodal understanding and generation.
-
Reinforcement Learning Enhances LLM Mathematical Reasoning
By
–
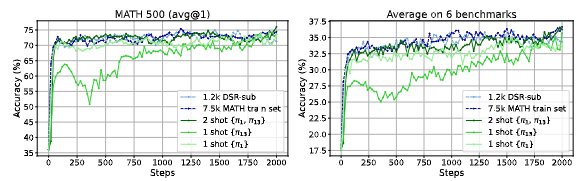
Reinforcement Learning for Reasoning in Large Language Models with One Training Example This paper demonstrates that Reinforcement Learning with Verifiable Reward (RLVR) using just one training example (1-shot RLVR) can significantly enhance the mathematical reasoning abilities
-

LLMs Achieve Seven-Year-Old Planning and Execution Abilities
By
–
Non-ironically an important milestone for LLMs: can demonstrate at least as much planning and execution ability as a human seven year old. https://t.co/yiYunaTCSE
— Patrick McKenzie (@patio11) 3 mai 2025Non-ironically an important milestone for LLMs: can demonstrate at least as much planning and execution ability as a human seven year old.
-

Hugging Face Launches Comprehensive Deep Reinforcement Learning Course
By
–
3. Deep RL Course Deep reinforcement learning is where AI starts to feel alive. Train agents to make decisions and learn from their environment. Ideal for: Game devs, robotics engineers, and those into frontier research. https://
huggingface.co/learn/deep-rl-
course/unit0/introduction
… -
AI Video Authenticity: Real or Deepfake Content?
By
–
Pues o se le cruzó un cable y se salió de control o el vídeo está preparado 🤔
— Juan Merodio (@juanmerodio) 3 mai 2025
Tú qué crees? Real o fake? pic.twitter.com/6JWFX91bhWPues o se le cruzó un cable y se salió de control o el vídeo está preparado Tú qué crees? Real o fake?
-
AI Model Generates Full Sand Simulation Fluidly and Quickly
By
–
5. Génération d'une simulation complète de sable
— VISION IA (@vision_ia) 3 mai 2025
Une vidéo montre le modèle générant une simulation fluide de sable. Impressionnant visuellement et techniquement, surtout en si peu de temps. pic.twitter.com/9ExGZv0a6j5. Génération d'une simulation complète de sable Une vidéo montre le modèle générant une simulation fluide de sable. Impressionnant visuellement et techniquement, surtout en si peu de temps.
-
Gemini 2.5 Pro Reasons Over 500K Token Code Repository
By
–
2. Gemini 2.5 Pro s'attaque à une tâche complexe en raisonnant sur un dépôt de plus de 500 000 tokens
— VISION IA (@vision_ia) 3 mai 2025
C’est du très lourd : lire et raisonner sur un repo géant, c’est un cap dans les capacités de compréhension de code à grande échelle. pic.twitter.com/klHlhf7ag82. Gemini 2.5 Pro s'attaque à une tâche complexe en raisonnant sur un dépôt de plus de 500 000 tokens C’est du très lourd : lire et raisonner sur un repo géant, c’est un cap dans les capacités de compréhension de code à grande échelle.