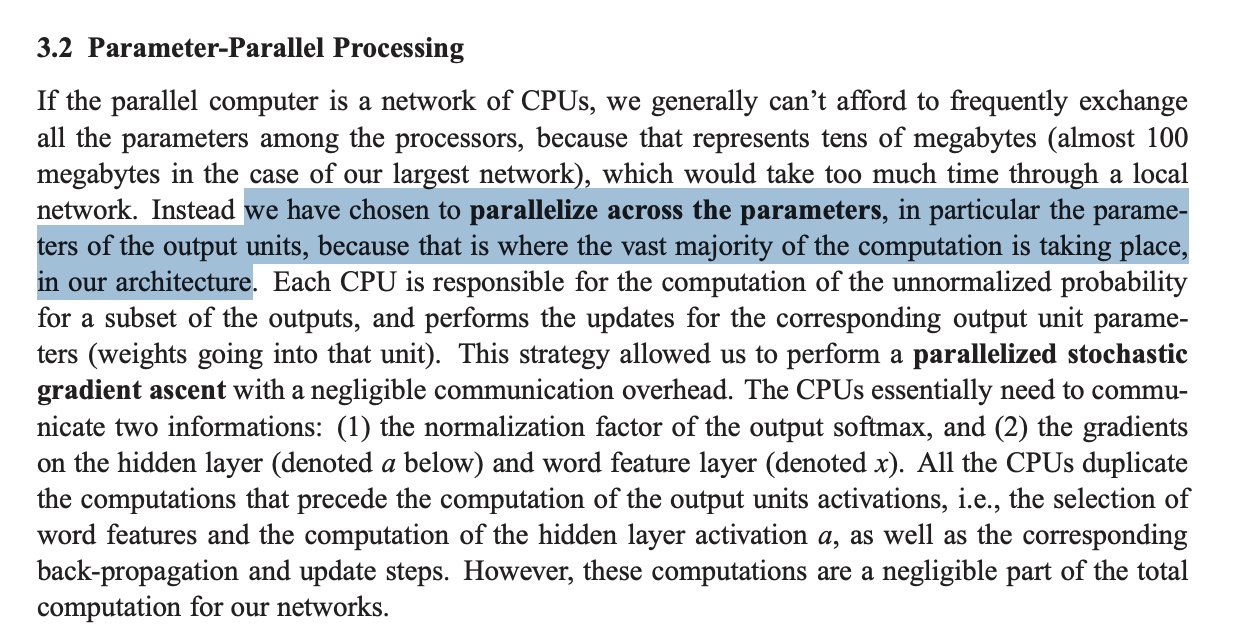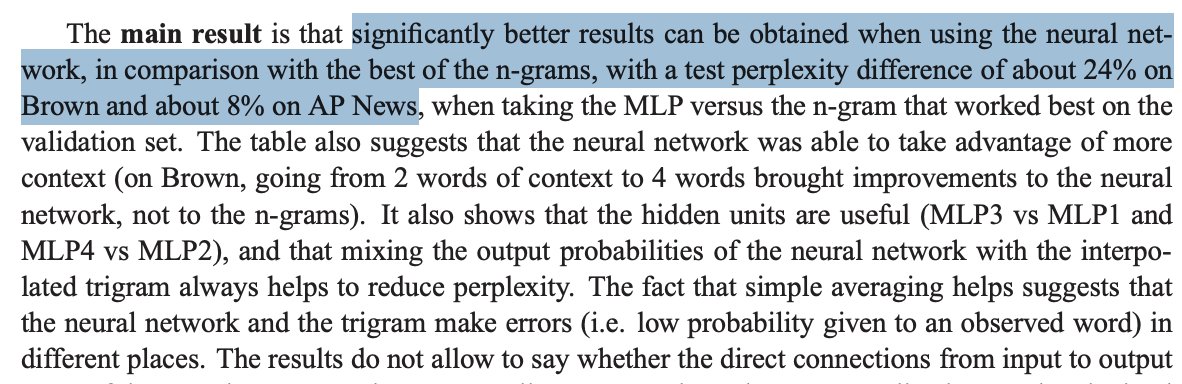
their neural networks worked better than any other methods and the bigger ones are better although at this scale, mixing with ngrams still helps a lot. they use a "mixture of models" – similar to today's MoEs, but the experts are different ngram models, plus one neural network
RESEARCH
-
Model Training Scale: From 800K to 25 Trillion Tokens
By
–
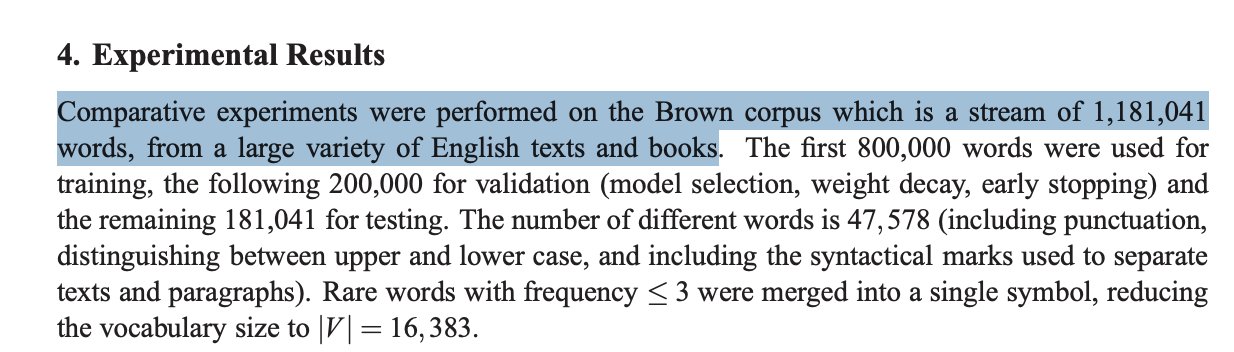
their model is trained on 800K words, which is around 2.5M tokens. remember today's models are up to ~25T tokens (10^7 more, or 10 million million times) (they trained another model on 15M words)
-
Compact Language Model Architecture: 12M Parameters vs LLAMA 4
By
–
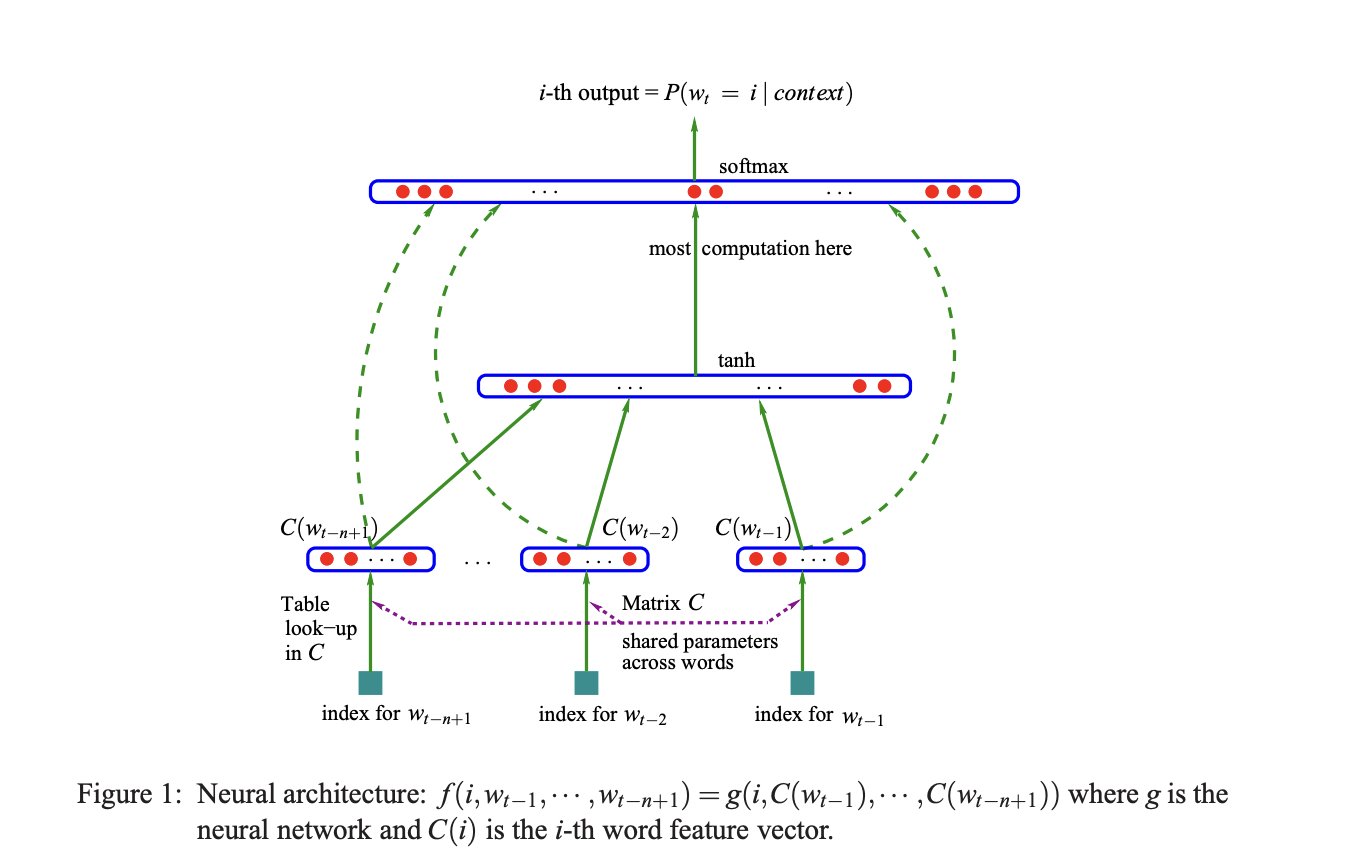
they use word embeddings + single-layer MLPs vocab size is 18K, context window is 6 words, hidden dimension is 60, word embedding have 100 dimensions their model has approx |V|(nm + h) = 17,964 × (6 × 100 + 60) = 12 million parameters about 200K times smaller than LLAMA 4…
-
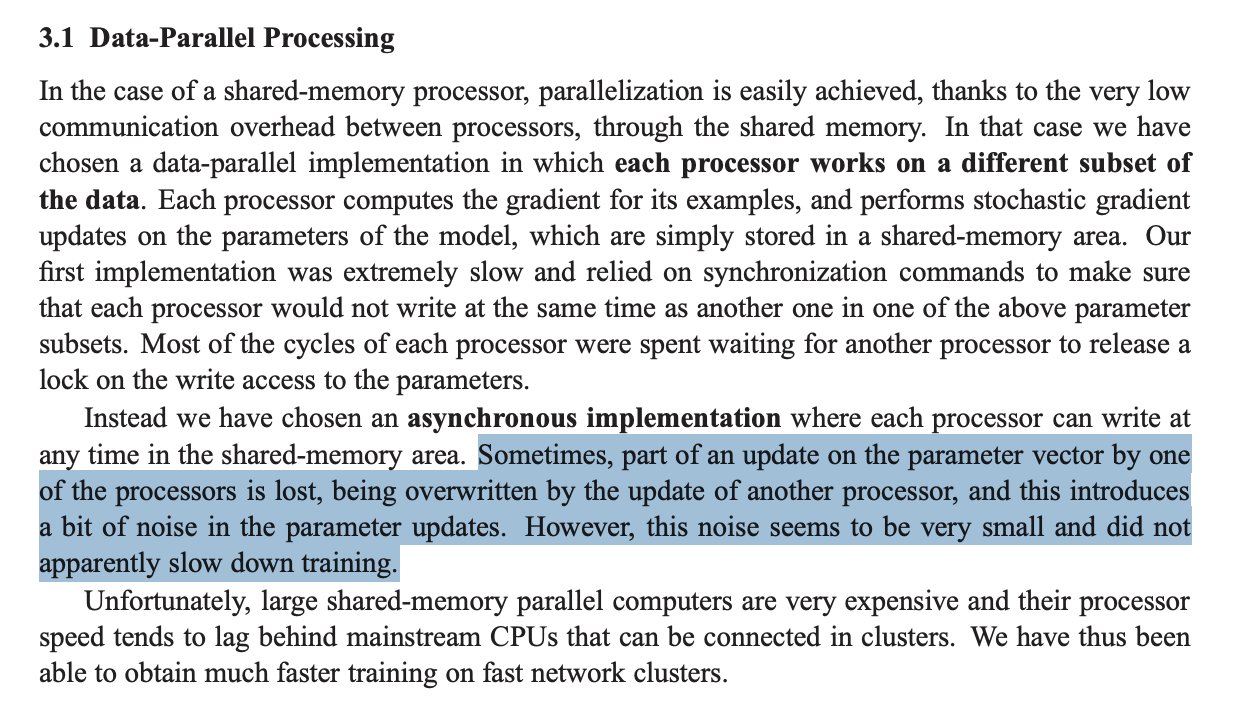
Hogwild Parallel Processing on CPU: Engineering Techniques
By
–
they do parallel processing (on CPU). i think this is now a well-known technique called Hogwild that wasn't formally developed until 2011. engineering this sounds pretty fun:
-
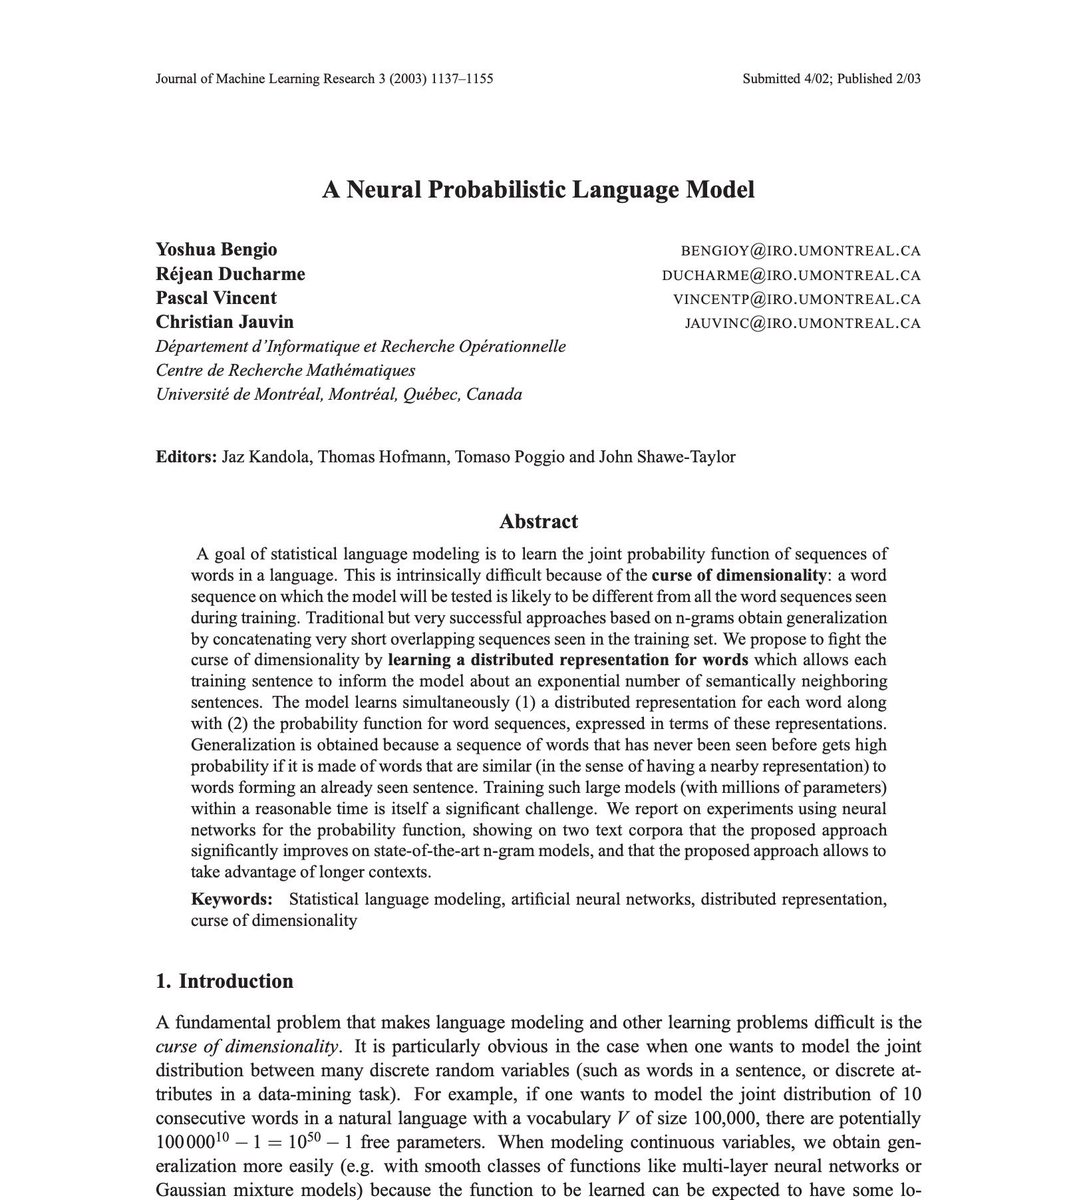
Neural Networks Training History: The 2003 Montreal Paper
By
–
did you know people have been training neural networks on text since 2003? everyone talks about Attention Is All You Need. but this is the real paper that got our field started. it was in 2003, in montreal. i read it, and it was even more forward-thinking than i expected:
-
Capability Denialism Underestimates AI Progress and Impact
By
–
The appeal of capability denialism is often given by cultural, ideological or aesthetic resistance to Artificial Intelligence. While AI proponents have often been too optimistic about the pace of progress, denialism has misled the general public into severely underestimating AI.
-
Scaling AI Systems to AGI: Uncertainties and Empirical Research
By
–
It is unclear whether today's AI systems can be scaled to AGI/ASI, but in most cases, it seems unscientific to make strong claims to the contrary. The practical and theoretical limitations of today's most successful approaches are unknown and subject to empirical research.
-
Capability Denialism in AI: Key Thinkers and Skepticism
By
–
Some call capability denialism 'garymarcusing', but Gary Marcus is by no means the inventor of the genre. Prominent denialists include Hubert Dreyfus, James Lighthill, John Searle, Stevan Harnad, Ned Block, Colin McGinn, Rolf Pfeiffer, Noam Chomsky, Roger Penrose, Emily Bender.
-
Capability Denialists and Turing Machines: Cognitive Function Debate
By
–
Capability denialists tend to claim that a class of Turing Machines or universal learning algorithms cannot perform brain-like functions because of properties they don't like (not symbolic enough, too symbolic, too digital, not recurrent enough, not embodied, not social).