Looks like Grok 4 is 10^27 FLOPs given their graphs? HLE score is 26% without tools, Gemini 2.5 is 21.6% without tools. Curious what the tool piece is.
RESEARCH
-
Gym Bros and LLMs: Training on Test Data Reputation Issues
By
–
gym bros llms that need to restore their reputation training on test
-

MedGemma: Small Multimodal LLM for Medical Professionals
By
–
MedGemma is a really interesting model – very small, multimodal, open, and does quite well in out-of-distribution medical tasks compared to much larger models. Would love to see more work thinking about how to improve & deploy this sort of LLM to support medical professionals
-

Bayesian Thinking as an Essential Investment Strategy Tool
By
–
Beliefs for the Win ! Why Bayesian Thinking Belongs in Your Investment Toolbox: https://
notquiterandom.com/2025/06/09/
-betting-on-beliefs-why-bayesian-thinking-belongs-in-your-investment-toolbox/
… -
Progress toward AI advancement matters more than timeline
By
–
I dunno if we'll be 10% of the way there when I die. Or 100%. Or somewhere in between. I don't mind too much, as long as progress is made.
-
AI in Medicine and Domain-Specific Applications with fastai
By
–
Showing that this could be applied to transform an important domain (
@enlitic doing AI in medicine) was the next big step. Then enabled others to do it in their own domains (with @fastdotai
) was next… -
Data-Driven Decision Making: The Heart of AI
By
–
I think larger/longer themes like this can be a bit hard to clarify outside of one's own head, and indeed additional clarity only comes through taking the journey. For me, it's about really harnessing data-driven decision making, which at its heart is what AI is about.
-
30 Years of AI Research Continues Through Answer.ai
By
–
I've been working for the last 30 years on a single theme really, with various windings diversions along the way. But it hasn't changed too much, and I think we now have a vehicle (
@answerdotai
) for continuing on it for another 30. -
Upstage Launches Solar-Pro2 Frontier Model with Advanced Reasoning
By
–
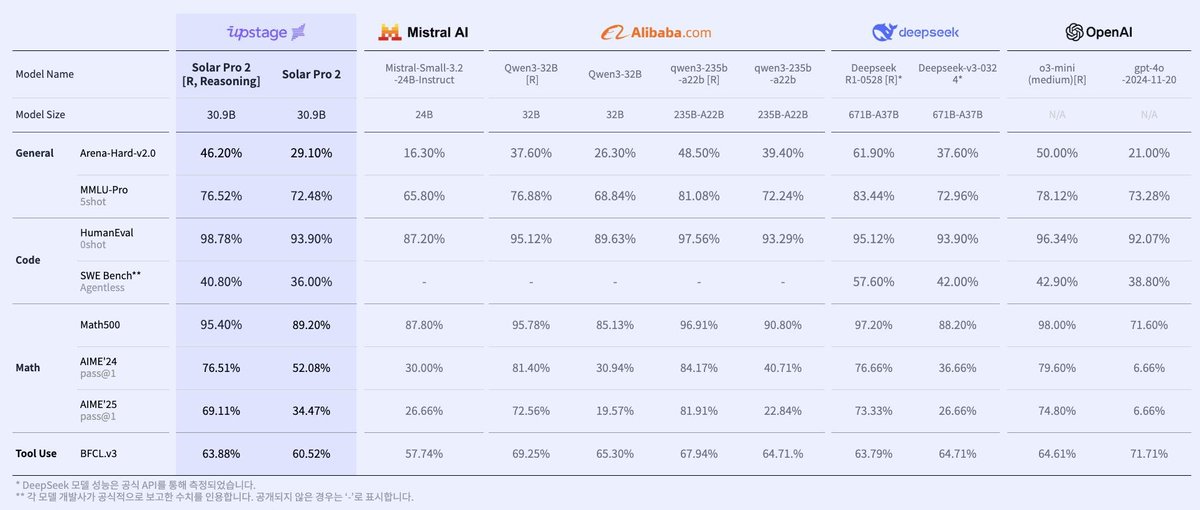
Finally, @upstageai is proud to announce the launch of its #Frontier model #SolarPro2. We sincerely thank everyone who used our solar-pro2-preview and provided valuable feedback. Leveraging your input, we have incorporated newly developed learning methodologies, enhanced data curation techniques for improved data quality, general reasoning data synthesis methods, and verifiable reward technologies to create this advanced model. The Solar-Pro2 model demonstrates exceptional performance on high-difficulty reasoning benchmarks, including MMLU-Pro, Math500, AIME, and SWE-Bench. Moreover, it excels in Arena-Hard-Auto, a rigorous evaluation framework adapted from LMSYS’s LLMArena, which focuses exclusively on extremely challenging problems. Arena-Hard-Auto is not a simple multiple-choice test—it evaluates answers against those generated by top-tier models, akin to lengthy essay or subjective exams. This benchmark is so demanding that non-Frontier models often score only 10–20%, making it nearly impossible to publish results. Solar-Pro2 (reasoning) achieves a 46% score on Arena-Hard-Auto and 71% on Ko-Arena-Hard-v0.1, surpassing even the highest-quality Korean answers. Solar-Pro2 is now available for immediate use at chat.upstage.ai/ and via API (model name: solapr-pro2). To encourage broader adoption, we offer a TRY-SOLAR-PRO2 $50 credit code (valid until August 31).
-

We Choose to Ascend with AGI
By
–
“We Choose to Ascend with AGI”#AGIALPHA 👁️✨ pic.twitter.com/hYti1Ncw5x
— MONTREAL.AI (@Montreal_AI) 9 juillet 2025“We Choose to Ascend with AGI” #AGIALPHA