Giant Poster. #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Books #Programming #Coding #100DaysofCode https://
geni.us/GPWalmartProdu
ct
…
RESEARCH
-

Essential Big Data Analytics and Machine Learning Technologies Stack
By
–
-

90 Machine Learning Resources: Free Books Computer Science Data Science
By
–
90 ML, #ComputerScience, #DataScience, #Books for Free. #BigData #Analytics #IoT #IIoT #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Mathematics #Programming #Coding #100DaysofCode https://
geni.us/90-ML -

Free eBook on Probability Statistics and Machine Learning
By
–
Free eBook: Probability #Statistics and #MachineLearning! @Parajulisaroj16 #BigData #Analytics #DataScience #AI #IoT #IIoT #Python #RStats #TensorFlow ##ReactJS #CloudComputing #Serverless #DataScientist #Linux #Books #Programming #Coding #100DaysofCode https://
geni.us/Prob-Stats -
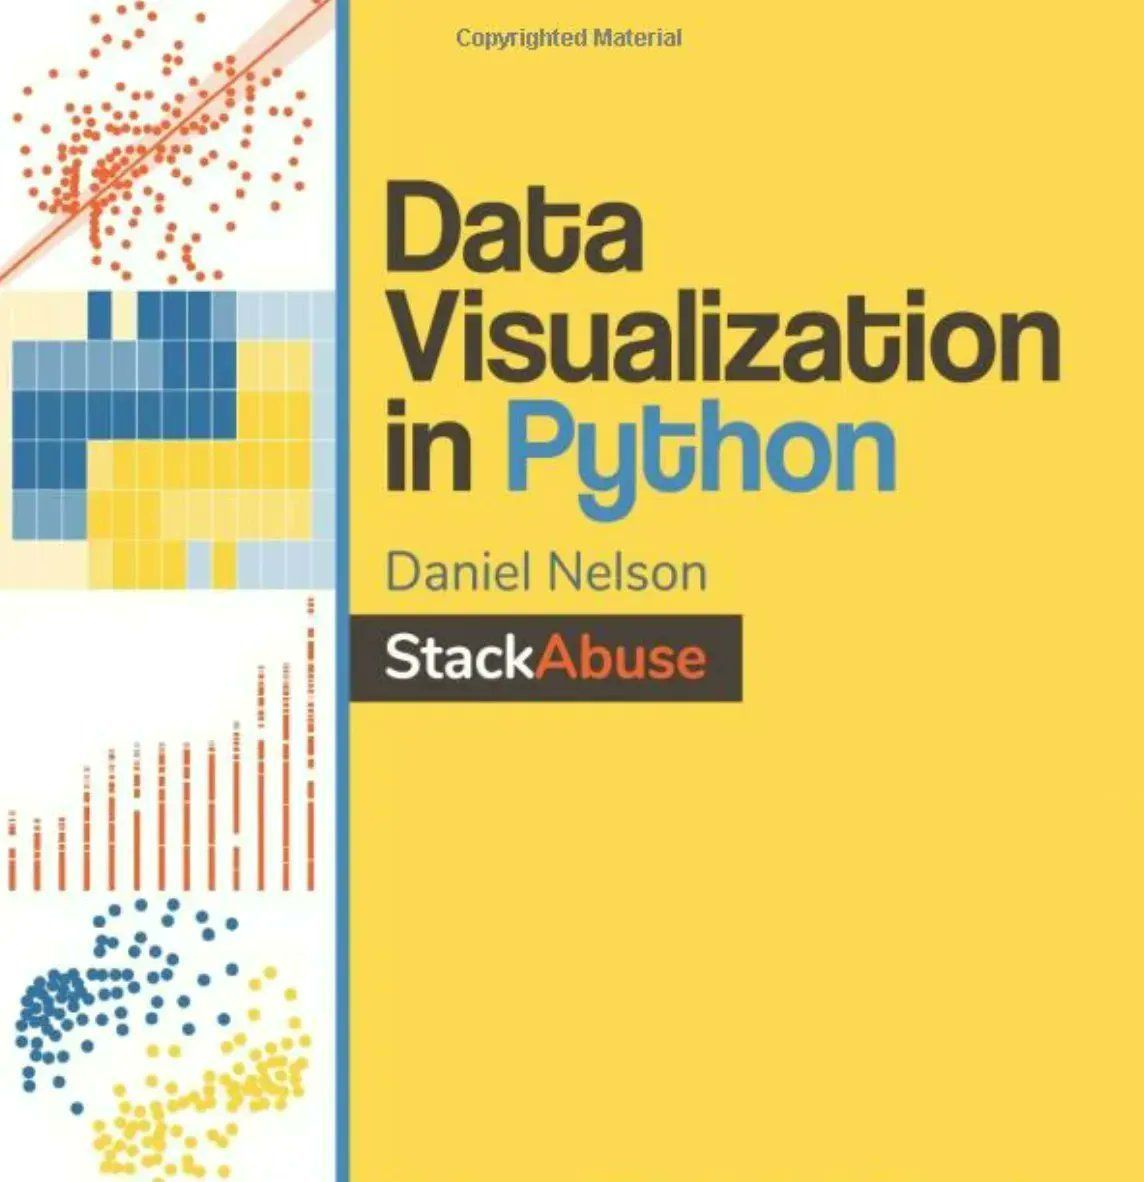
Data Visualization in Python for Analytics and Machine Learning
By
–
Data Visualization in Python! #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Books #Programming #Coding #100DaysofCode https://
geni.us/Nelson-Py -
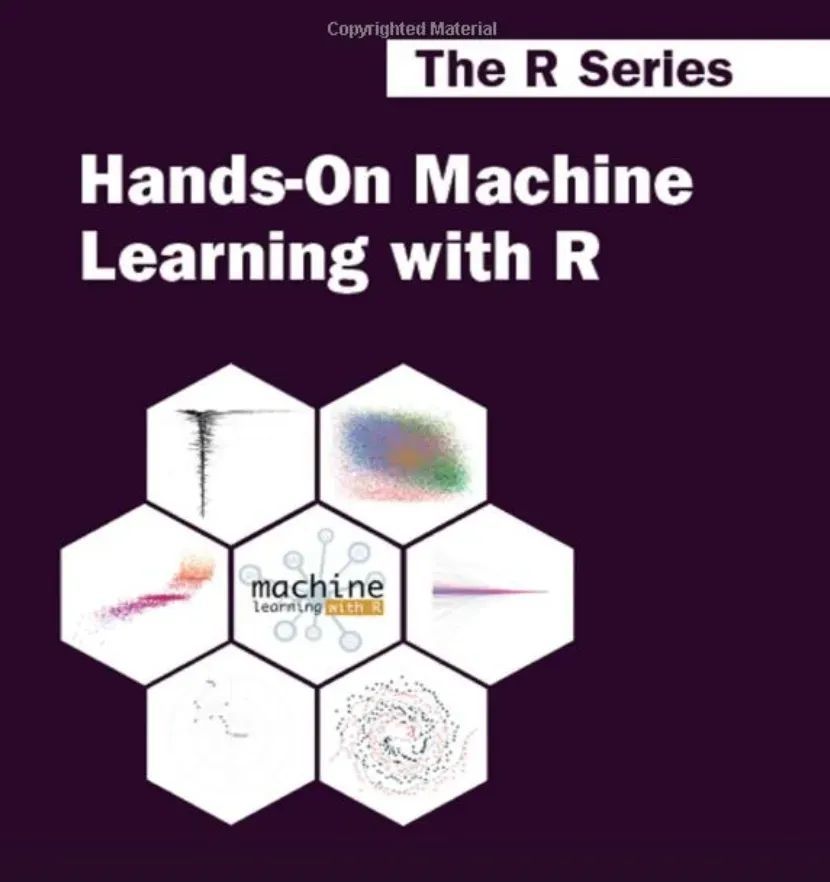
Machine Learning with R: BigData Analytics and DataScience Tools
By
–
Machine Learning with R. #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Books #Programming #Coding #100DaysofCode https://
buff.ly/3Y6vQhn -
Multi-GPU Training Strategies for Deep Learning Models
By
–
By default, deep learning models only utilize a single GPU for training, even if multiple GPUs are available.
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
An ideal way to train models is to distribute the training workload across multiple GPUs.
The graphic depicts four strategies for multi-GPU training👇 pic.twitter.com/rEKkFw3pF3By default, deep learning models only utilize a single GPU for training, even if multiple GPUs are available. An ideal way to train models is to distribute the training workload across multiple GPUs. The graphic depicts four strategies for multi-GPU training
-
Ring Approach for Scalable Model Weight Synchronization Across GPUs
By
–
And there you go! Model weights across GPUs have been synchronized. While the total elements transferred is still the same as we had in the “single-GPU-master” approach, this ring approach is much more scalable since it does not put the entire load on one GPU. Check this
-

Ring-reduce Algorithm: Share-reduce Phase with Gradient Segmentation
By
–
Algorithm 2) Ring-reduce
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
Phase #1) Share-reduce
First, gradients are divided into G segments on every GPU (G = total number of GPUs).
Check this 👇 pic.twitter.com/15v6GIivHoAlgorithm 2) Ring-reduce Phase #1) Share-reduce First, gradients are divided into G segments on every GPU (G = total number of GPUs). Check this
-
All-Reduce Algorithm: High Bandwidth Costs in Distributed Computing
By
–
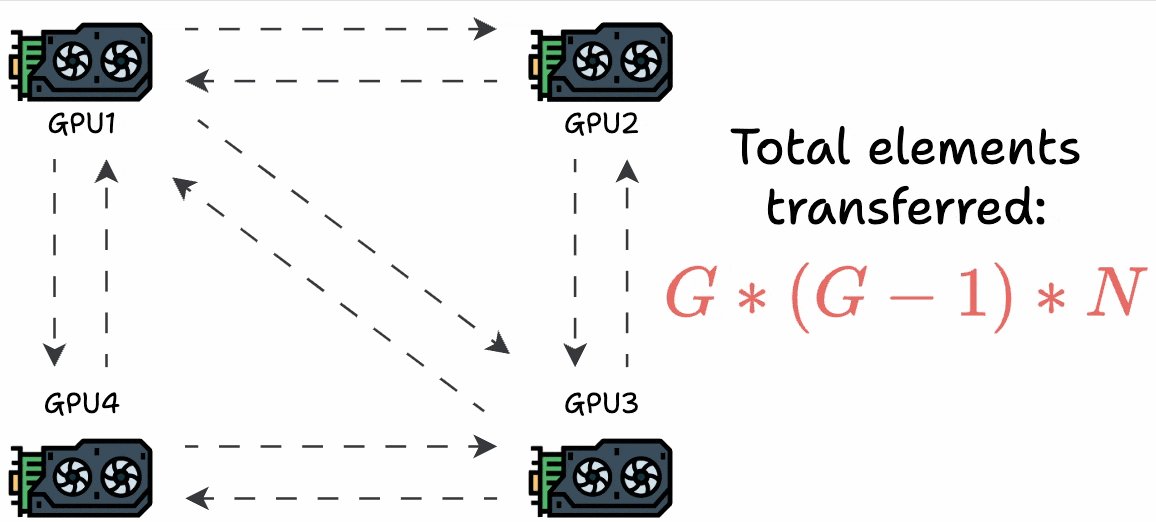
Algorithm 1) All-reduce
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
An obvious way is to send the gradients from one device to all other devices to synchronize them.
But this utilizes high bandwidth.
If every GPU has “N” elements and there are “G” GPUs, it results in a total transfer of G*(G-1)*N elements 👇 pic.twitter.com/cxqdc3PszFAlgorithm 1) All-reduce An obvious way is to send the gradients from one device to all other devices to synchronize them. But this utilizes high bandwidth. If every GPU has “N” elements and there are “G” GPUs, it results in a total transfer of G*(G-1)*N elements
-
GPU Gradient Synchronization Strategies in Distributed Training
By
–
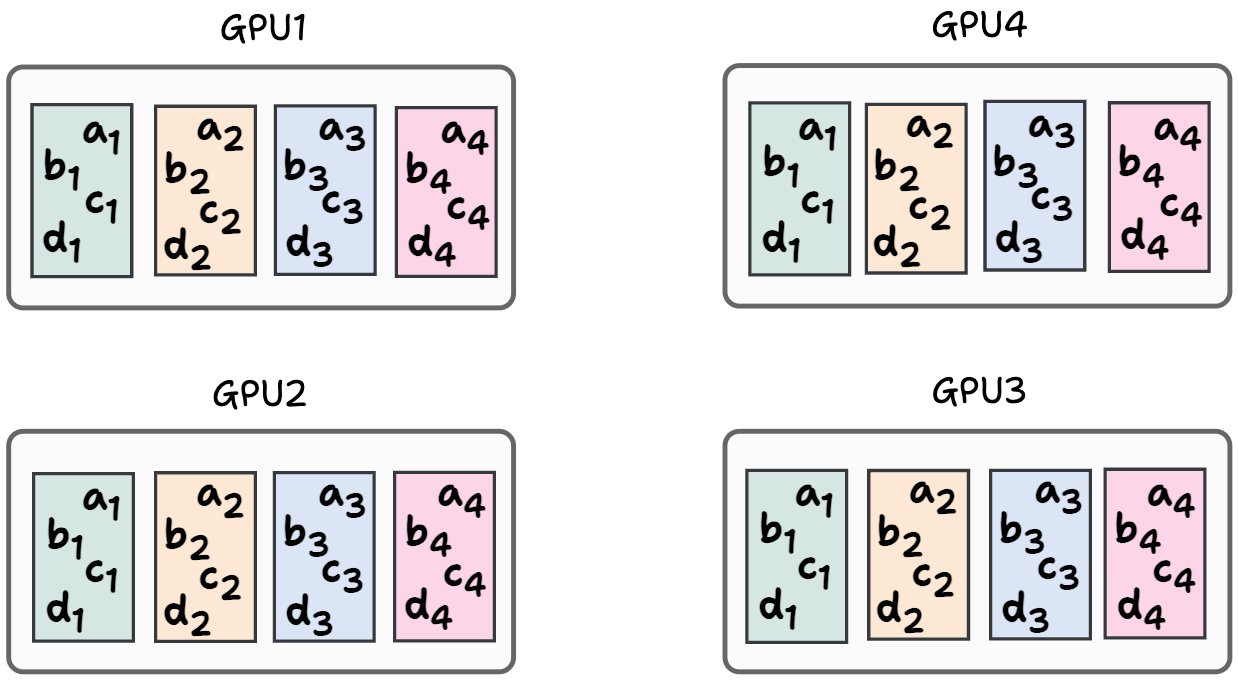
This leads to different gradients across different devices.
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
So, before updating the model parameters on each GPU device, we must communicate the gradients to all other devices to sync them.
Let’s understand 2 common strategies next! pic.twitter.com/cIE4fVR108This leads to different gradients across different devices. So, before updating the model parameters on each GPU device, we must communicate the gradients to all other devices to sync them. Let’s understand 2 common strategies next!