
Fuite majeure ? Un utilisateur reconnu et fiable dans le domaine de l’IA partage une capture d’écran transmise par l’un de ses contacts : on y voit que nano-banana serait bien signé Google et intégré à Gemini… J’ai hâte de voir ça, car pour l’instant c’est vraiment bluffant.
RESEARCH
-
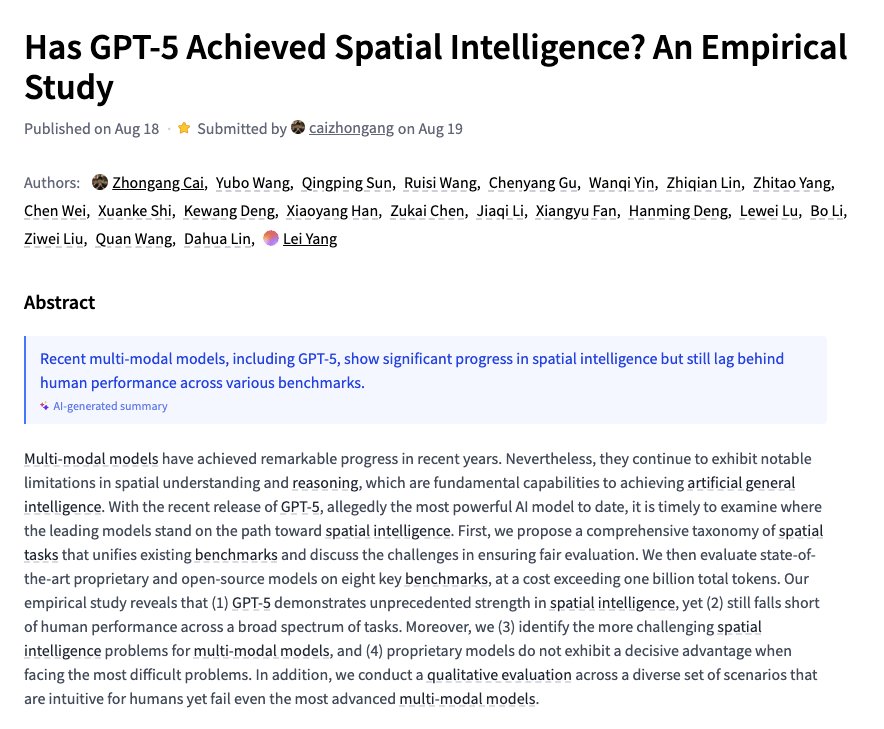
GPT-5 Spatial Intelligence: Empirical Study Analysis
By
–
Has GPT-5 Achieved Spatial Intelligence? An Empirical Study
-
RL with LLM-as-Judge: The Next AI Development Paradigm
By
–
it seems like the next few years of AI development will be a lot of RL with LLM-as-a-judge reward functions. strange times we live in where can i learn more about this paradigm? what are the most relevant blogs and papers?
-
The Importance of Benchmarking Real-World AI Skills
By
–
prints hard, benchmarking real-world skills is where it's at
-
Europe’s robotics gap and tech innovation challenges
By
–
L’Europe est complètement larguée en robotique
— Docteur Laurent Alexandre (@dr_l_alexandre) 19 août 2025
Il n’y a quasiment aucune branche industrielle ou l’Europe n’est pas humiliée
Il faut faire taire les écologistes et relancer la recherche high-tech
Avec la décroissance, Les Verts nous tuent pic.twitter.com/ddUbnsMIo5L’Europe est complètement larguée en robotique Il n’y a quasiment aucune branche industrielle ou l’Europe n’est pas humiliée Il faut faire taire les écologistes et relancer la recherche high-tech Avec la décroissance, Les Verts nous tuent
-
Claude 4.1 Update: Game-Changer for Coding and Agentic Tasks
By
–
Is the Claude 4.1 update a game-changer or a small step? 🤔
— Louis-François Bouchard 🎥🤖 (@Whats_AI) 19 août 2025
Let’s break it down 👇
What’s new
• Big boost in agentic tasks, coding, and reasoning → 74.5% on SWE-bench
• Stronger at multi-file editing & precision (nice for coding!)
• Opus 4.1’s coding focus feels like a… pic.twitter.com/aXAMJEu3jCIs the Claude 4.1 update a game-changer or a small step? Let’s break it down What’s new • Big boost in agentic tasks, coding, and reasoning → 74.5% on SWE-bench • Stronger at multi-file editing & precision (nice for coding!) • Opus 4.1’s coding focus feels like a
-

Beyond Benchmarks: Sanmi Koyejo on AI Measurement Science
By
–


Another amazing Keynote at #DLI2025 by @sanmikoyejo, Assistant Professor of Computer Science at @Stanford , Co-Founder of @VirtueAI_co , and President of @black_in_ai, on “Beyond Benchmarks: Building a Science of AI Measurement.” 🧪 Sanmi made a compelling case for moving beyond static benchmarks toward a rigorous science of AI measurement, one that is more reliable, scalable, and meaningful for guiding research, deployment, and policy. This keynote was a powerful reminder that the future of AI depends not just on what we build, but on how we measure it. 📏✨ #urunana #Indaba2025 #AIinAfrica #AIResearch
→ View original post on X — @shakir_za, 2025-08-19 10:22 UTC
-
OdysseyBench: Advanced Metadata for AI Agent Debugging and Evaluation
By
–
OdysseyBench also includes detailed metadata: • Task → App count (1/2/3)
• Token count per session
• Turn-by-turn dialogue history
• Execution plan
• Expected output artifacts Which means… you can analyze why your agent failed, not just if it did. -
Memory design and retrieval strategies in AI models
By
–
Memory design matters more than model size OdysseyBench evaluated multiple retrieval strategies: • Long-context prompting (8K+ tokens)
• RAG with raw session or utterance context
• RAG with summarization: session or chunk Chunk-level summaries outperformed all, with ~75%