
Yes, please: Former OpenAI researcher says a $10,000 monthly UBI will be 'feasible' with AI-enabled growth
RESEARCH
-

AI Models Playing Werewolf: Multi-agent Reasoning Benchmark
By
–
Interesting benchmark — having a variety of models play Werewolf together. Requires reasoning through the psychology of other players, including how they’ll reason through your psychology, recursively. Wonder how much fun a mixed human/AI game would be!
-

Artificial Intelligence Term Coined in 1955 Conference Proposal
By
–
#Otd in 1955, the term “artificial intelligence” was coined in a conference proposal: https://
stanford.io/2WJJJGN -
The Unsolved Mystery of How LLMs Simulate Human Thought
By
–
Nous n’avons en réalité pas beaucoup progressé dans l’explication du grand mystère des LLM : Comment un modèle qui utilise simplement des multiplications de matrices pour prédire le mot suivant parvient-il à simuler la pensée humaine au point de reproduire autant de
-

Agentic Science: AI as Autonomous Research Partner
By
–
10. Agentic Science This survey introduces Agentic Science as the next stage of AI for Science, where AI evolves from a support tool to an autonomous research partner capable of hypothesis generation, experimentation, and iterative discovery.
-

Synthetic Dataset Generation for RAG Systems Multi-Agent Evaluation
By
–
8. Synthetic Dataset Generation for RAG Evaluation with Multi-Agent Systems The paper proposes a modular, three-agent pipeline that auto-generates synthetic QA datasets for evaluating RAG systems while enforcing privacy.
-

LLM Reward Hacking Generalizes to Dangerous Misaligned Behaviors
By
–
9. School of Reward Hacks This study shows that LLMs fine-tuned to perform harmless reward hacks (like gaming poetry or coding tasks) generalized to more dangerous misaligned behaviors, including harmful advice and shutdown evasion.
-

Memory-R1: Framework Teaching LLM Agents Memory Management
By
–
6. Memory-R1 A framework that teaches LLM agents to decide what to remember and how to use it.
-
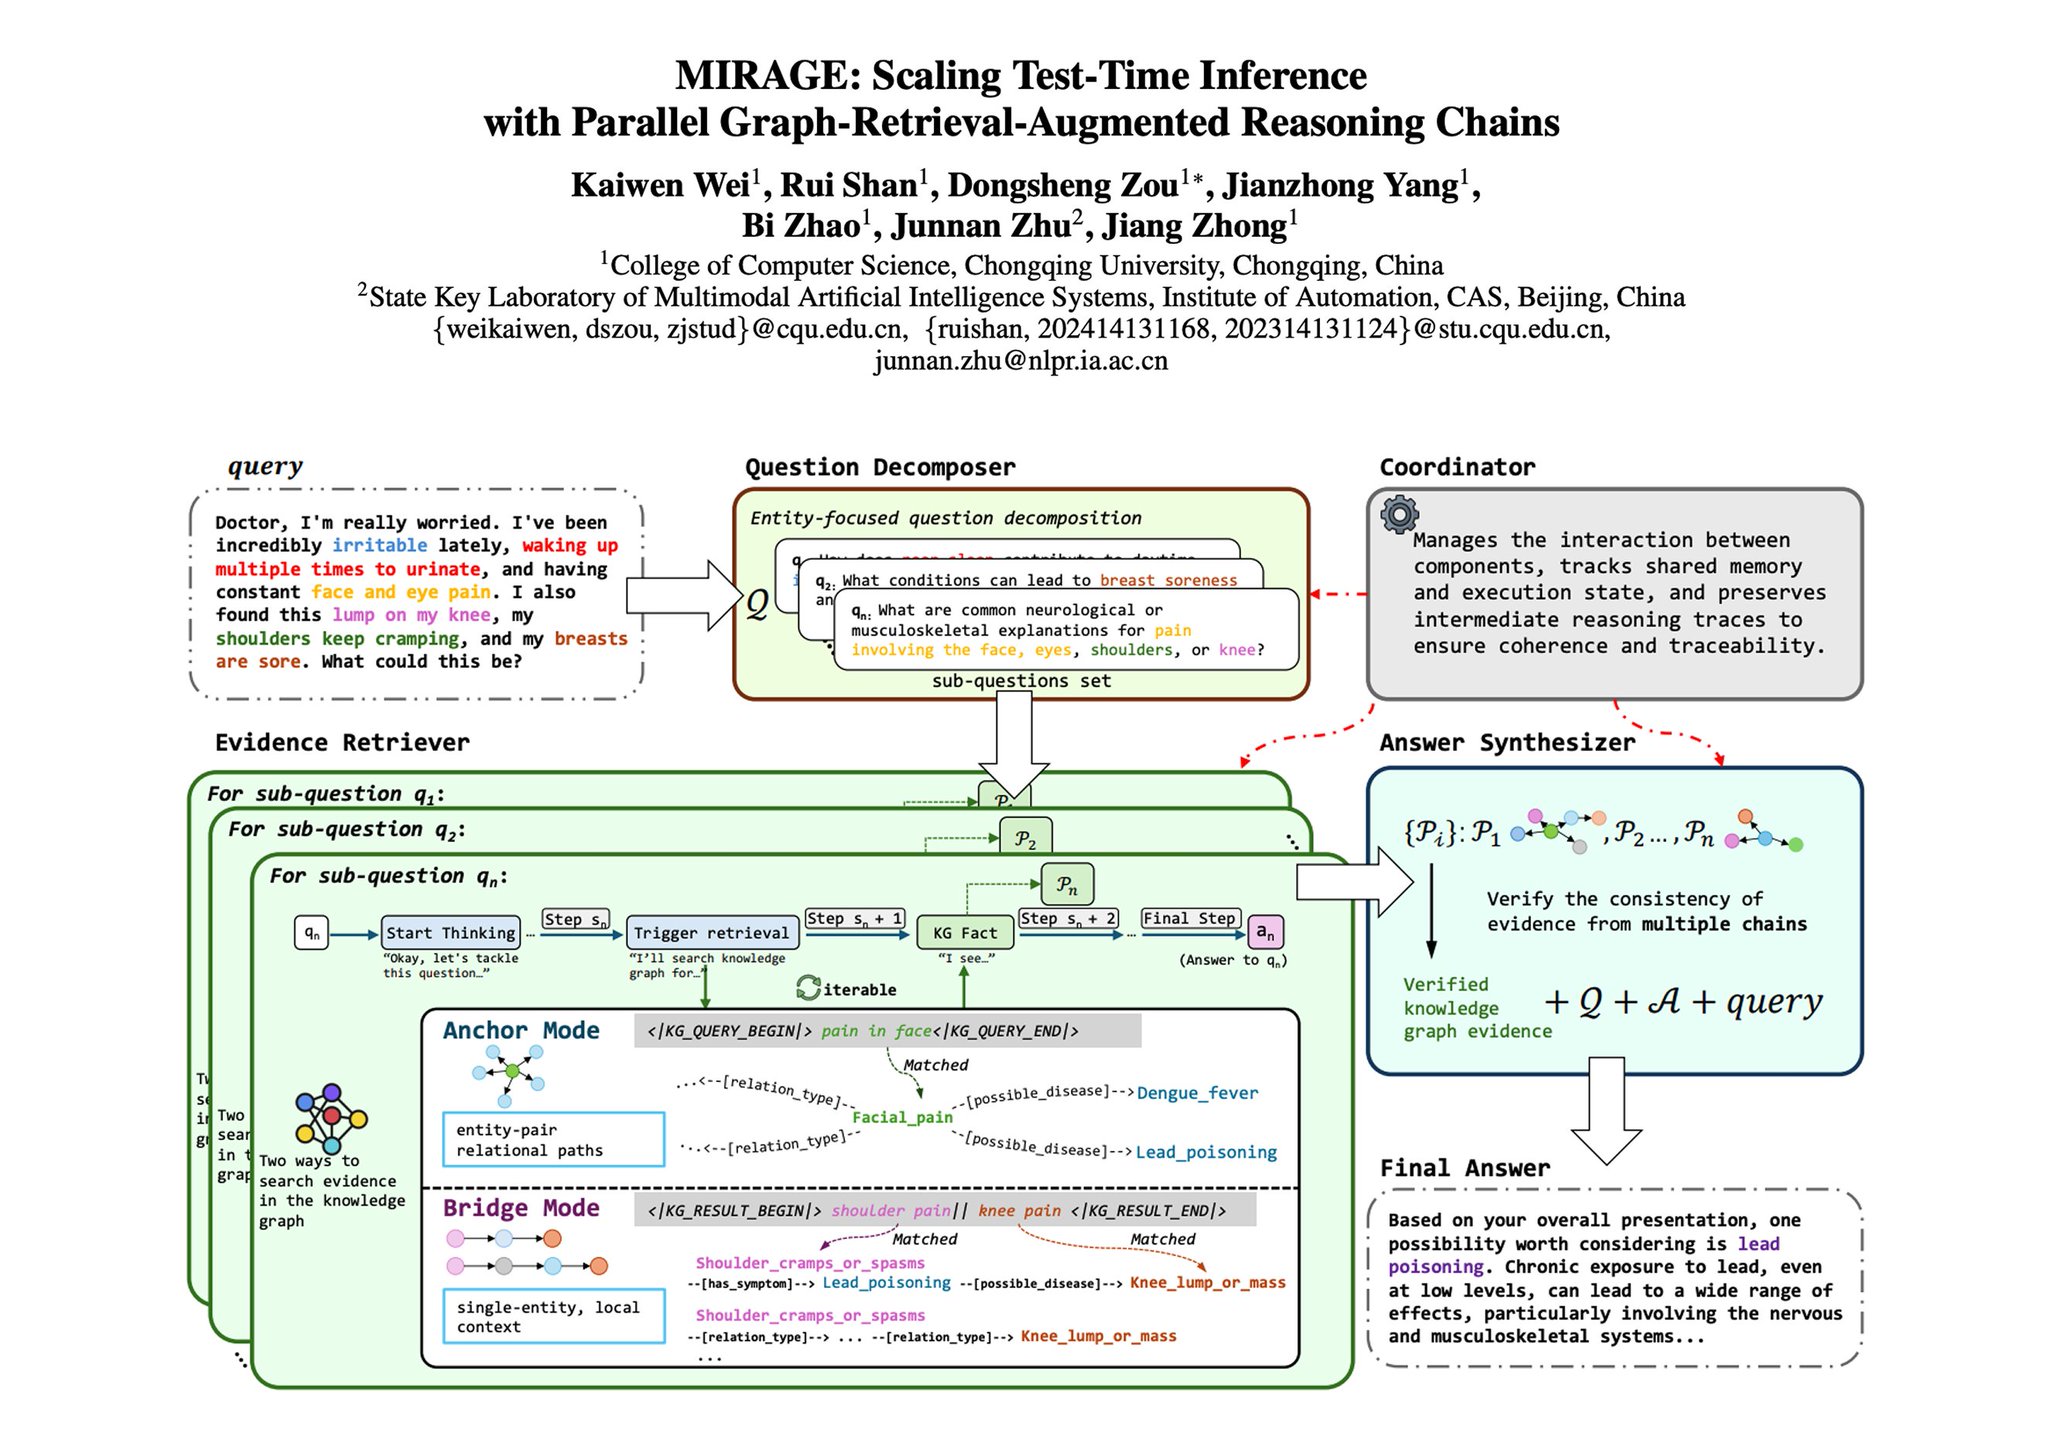
Parallel Graph-Retrieval-Augmented Reasoning for Medical Knowledge
By
–
5. Parallel Graph-Retrieval-Augmented Reasoning A test-time reasoning framework that replaces a single linear chain with multiple parallel, entity-grounded chains over medical knowledge graphs.
-

Evaluating Language Models on Real Unsolved Questions
By
–
7. Assessing Language Models on Unsolved Questions The paper introduces a new evaluation paradigm that tests models on real unsolved questions from the wild, rather than on fixed-answer exams.