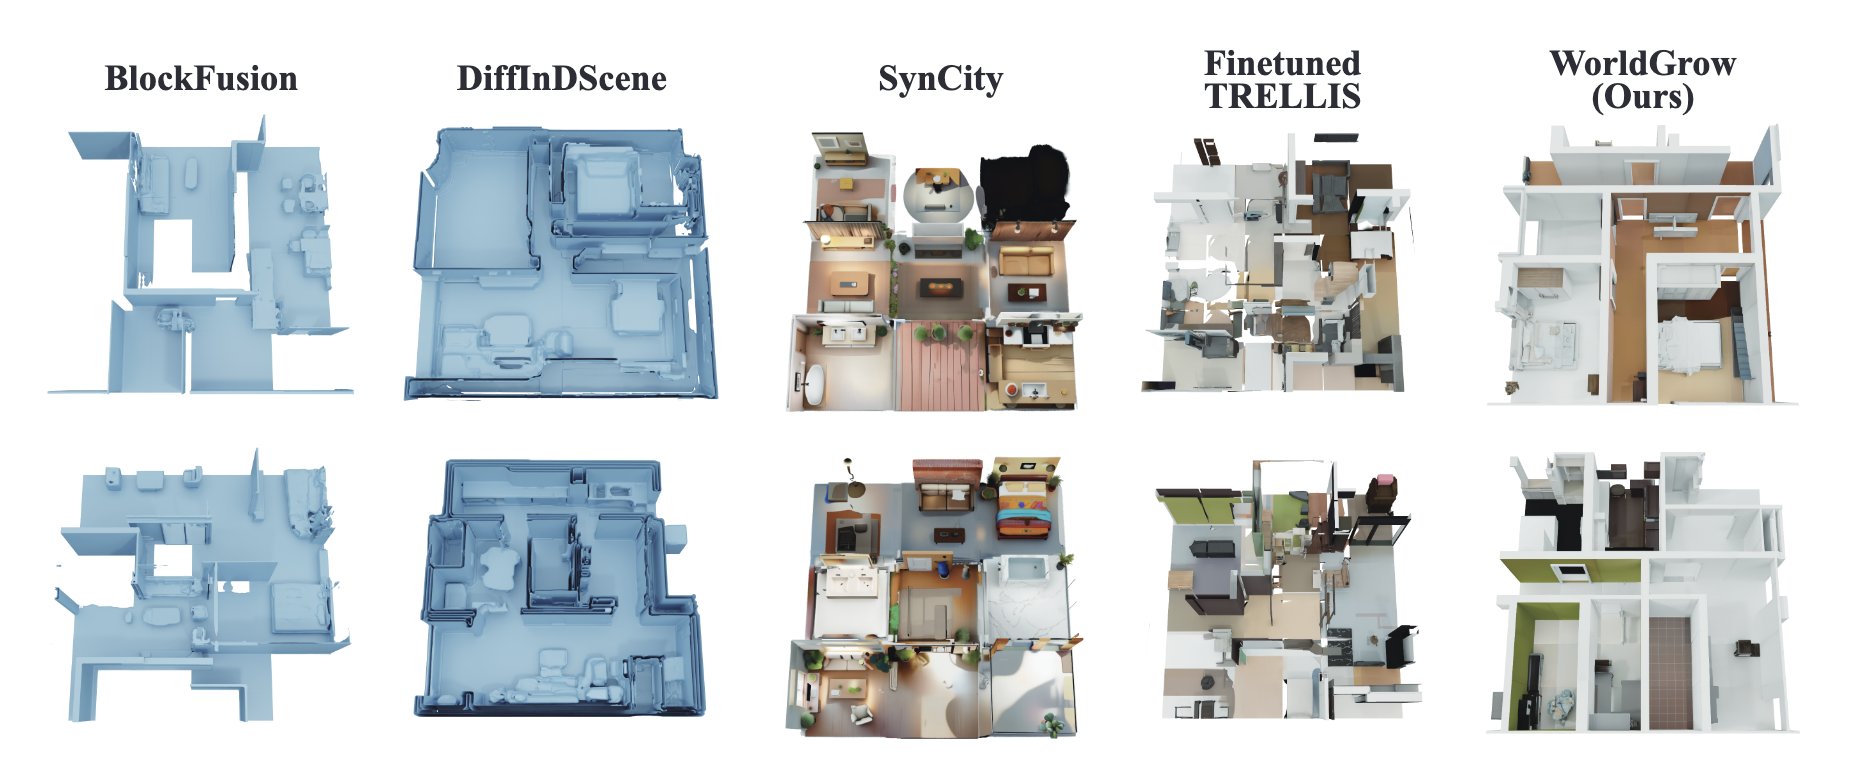
Here’s where it flexes against SynCity, BlockFusion, DiffInDScene, and TRELLIS. Only WorldGrow generates high-res, continuous indoor scenes with perfect texture alignment. Figure 5 literally shows you the other methods fall apart at the seams.
RESEARCH
-
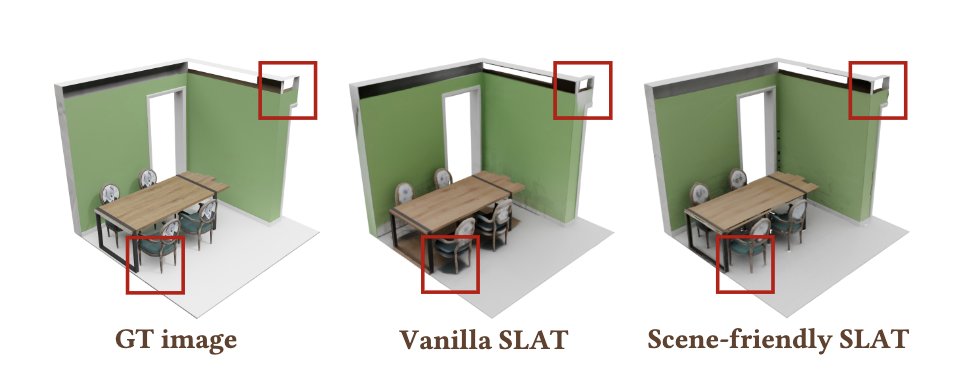
WorldGrow improves 3D modeling via occlusion-aware feature aggregation
By
–
Standard 3D models fail near occlusions and boundaries. WorldGrow fixes this with occlusion-aware feature aggregation and a retrained decoder removing color bleeding and floating geometry. Figure 3 visually compares the “vanilla” vs “scene-friendly” SLAT. The difference is
-
Volume 287 ICMLIC Proceedings Published on PMLR
By
–
Volume 287 https://
proceedings.mlr.press/v278/ Proceedings of International Conference on Machine Learning and Intelligent Computing Is now available on PMLR -
On-Policy Distillation: Combining RL Error Correction with SFT Reward Density
By
–
On-policy distillation provides an elegant way to use the teacher model as a process reward model to provide dense reward while preventing SFT style "OOD shock" during rollout. Thinking Machines (@thinkymachines) Our latest post explores on-policy distillation, a training approach that unites the error-correcting relevance of RL with the reward density of SFT. When training it for math reasoning and as an internal chat assistant, we find that on-policy distillation can outperform other approaches for a fraction of the cost. thinkingmachines.ai/blog/on-… — https://nitter.net/thinkymachines/status/1982856272023302322#m
→ View original post on X — @lilianweng, 2025-10-27 17:31 UTC
-

Jensen Huang and AI Pioneers Awarded Queen Elizabeth Prize for Engineering
By
–
On 6 November, Jensen Huang, @drfeifei, Geoffrey Hinton, Yoshua Bengio, Yann LeCun and Bill Dally will be honoured as this year’s @QEPrize laureates at the FT Future of AI Summit during our day 2 opening panel. Explore: ai.live.ft.com/home #FTFutureofAI #MachineLearning #AI
→ View original post on X — @madhumita29, 2025-10-27 16:06 UTC
-
Humachinekind: Exploring Human-Machine Integration Philosophy
By
–
Humachinekind, Humachineology, and Humachineologist
-
New Research Proposes Unified Framework for Language, Robotics, and AGI
By
–
The paper ends with a big-picture figure a roadmap showing how this approach connects language, robotics, and symbolic reasoning into one unified framework. It’s literally titled “The Path to Real Deep Research.” If they’re right, this is the bridge to AGI.
-
Multi-Agent AI Systems Demonstrate Improved Reasoning Performance
By
–
They even connected multiple “deep researchers” together. Each agent worked on a subproblem and merged insights. Result: +22% faster convergence on shared reasoning benchmarks. It’s literally a scientific community made of AIs. This one’s unreal. The model autonomously
-

Analysis of AI Model Memory Retention via Reflection
By
–
Each square here shows how long the model “remembers” successful hypotheses. Retention stabilizes at ~74% after 10 research cycles. That’s memory through reflection, not parameter updates. It’s how the system learns what’s worth keeping.
-

Self-Optimization as the New Scaling Law for AI Models
By
–
Everyone’s chasing scale, but this model scales intelligently. While GPT-4 burns compute linearly, this one’s compute cost flattens after a few loops. Efficiency improves by 3.4× per iteration as reasoning stabilizes. Self-optimization is the new scaling law.