Yeah, there is a silver lining. But I think it gets a bit muddled since most base models are trained on CoT data.
RESEARCH
-
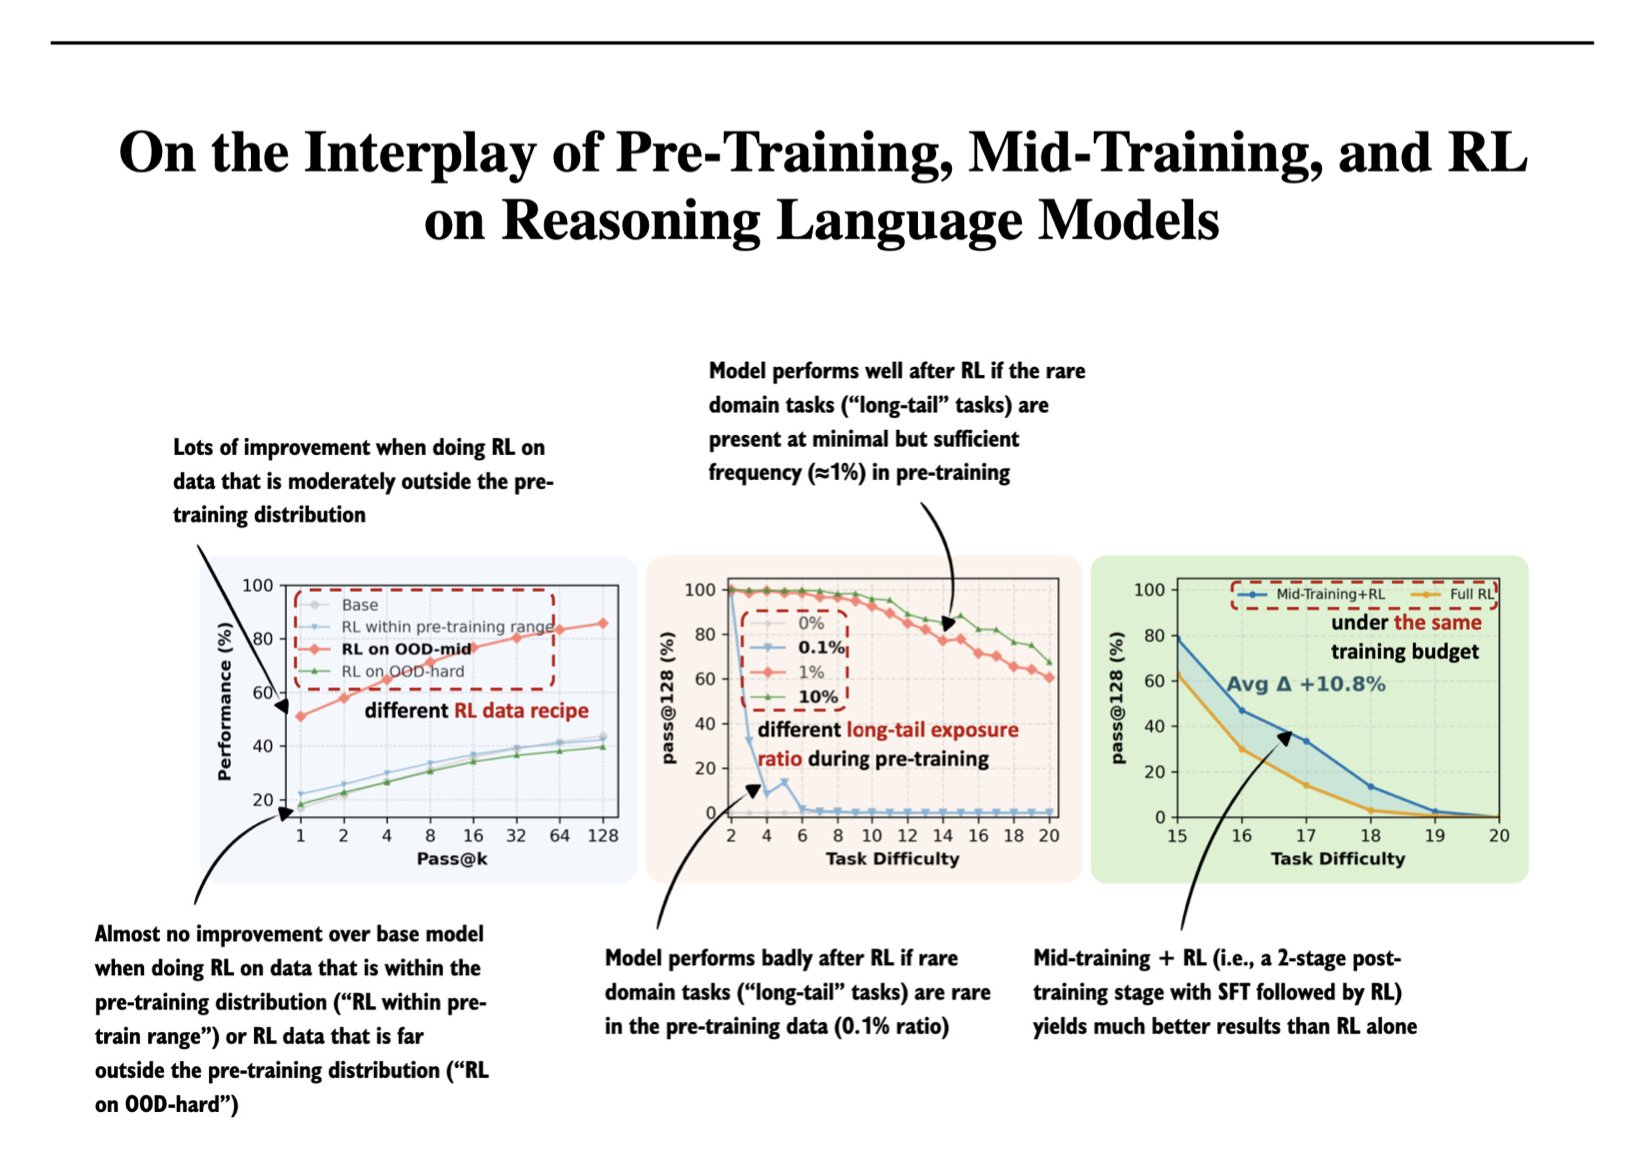
Optimal RL Balance in Training Reasoning Models
By
–
Another really interesting paper from my 2025 bookmarked papers: On the Interplay of Pre-Training, Mid-Training, and RL on Reasoning Language Models (https://arxiv.org/abs/2512.07783). In short, RL is most effective when applied to data that is neither too close to nor too far from the
-

FlowBlending: Stage-Aware Multi-Model Sampling for Video Generation
By
–
FlowBlending Stage-Aware Multi-Model Sampling for Fast and High-Fidelity Generation
-

Dream2Flow: Video Generation with 3D Object Flow for Manipulation
By
–
Dream2Flow
— AK (@_akhaliq) 2 janvier 2026
Bridging Video Generation and Open-World Manipulation with 3D Object Flow pic.twitter.com/5m09xRzjG0Dream2Flow Bridging Generation and Open-World Manipulation with 3D Object Flow
-
Hypergraph Memory Enhances Multi-step RAG Long-Context Modeling
By
–
Improving Multi-step RAG with Hypergraph-based Memory for Long-Context Complex Relational Modeling
-
DiffThinker: Generative Multimodal Reasoning with Diffusion Models
By
–
DiffThinker Towards Generative Multimodal Reasoning with Diffusion Models
-
Dynamic Large Concept Models with Latent Reasoning in Adaptive Semantic Space
By
–
Dynamic Large Concept Models Latent Reasoning in an Adaptive Semantic Space
-
JavisGPT: Multi-modal LLM for Video Understanding and Generation
By
–
JavisGPT A Unified Multi-modal LLM for Sounding-Video Comprehension and Generation
-

AI 2025 Advances: Reviewing Predictions and Accuracy
By
–
¡DIRECTO ESPECIAL ESTA TARDE! Hoy estaremos analizando los grandes avances en IA del 2025 corrigiendo las predicciones que hice a comienzos del año pasado! ¿Cuántas habré acertado? Lo votaréis vosotros a partir de las 18:30h española. Link a continuación!
-

Sparse models generalize better than dense ones
By
–
The counterintuitive part: Sparse models often generalize BETTER than dense ones. Why? Dense networks memorize noise. Sparse networks are forced to learn robust features. It's not just cheaper. It's actually better science.