Responses by ChatGPT 5.2 Auto. Currently popular prompts found by me at https://
x.com/uubzu/status/2
012782068829171955
… and https://
x.com/gmltony/status
/2012936406461456411
…. Similar result pair at https://
x.com/hovormijurko/s
tatus/2012993464464511270
… with real picture. Longer explanation at https://
lesswrong.com/posts/rP66bz34
crvDudzcJ/decision-theory-does-not-imply-that-we-get-to-have-nice
….
RESEARCH
-

ChatGPT 5.2 Auto Responses and Decision Theory Discussion
By
–
-

Daniela: AI success shifts goalposts, redefining human intelligence
By
–
daniela's actual point was sharper than the headlines. "the construct itself is now wrong. or maybe not wrong, but just outdated." we keep moving the goalpost. every time AI achieves something we thought required human intelligence… we retroactively decide it doesn't
-
Claude outperformed every human candidate on Anthropic’s engineering test
By
–
here's the part that stuck with me. claude outperformed every human candidate who's ever taken anthropic's internal engineering hiring test. not most. every single one in the company's history. a 2-hour rigorous assessment designed to filter for elite engineers. so what
-

Claude Opus 4.5 hits 80.9% on SWE-bench, first to break 80%
By
–
the benchmark data made me pause. claude opus 4.5 hit 80.9% on SWE-bench verified. first model to ever break 80%. this isn't leetcode. it's real github issues from production repos. the actual work developers do. 4 out of 5 real-world bugs. solved.
-

Daniela Amodei says Claude matches human-level coding at Anthropic
By
–
daniela amodei on CNBC: "by some definitions of that, we've already surpassed" human-level AI. her example was coding. she said claude writes code "about as well as many developers at anthropic now." anthropic. the company that probably employs some of the best engineers on
-
Anthropic President Admits AGI May Have Already Happened in Some Domains
By
–
anthropic's president just casually admitted AGI might have already happened. not "we're close." not "maybe next year." already happened. in some domains. while everyone was still arguing about the definition. this hit different when i actually read what she said:
-

Top AI Research Papers: RAG, Agents, and Memory Optimization
By
–
The Top AI Papers of the Week (January 12-18) – UniversalRAG
– Agent-as-a-Judge
– Self-Evolving Search Agents
– Active Context Compression
– Efficient Lifelong Memory for LLM Agents
– Extending Context by Dropping Positional Embeddings
– Unified Long-Term and Short-Term Memory -
Anthropic’s Claude Cowork to Get Knowledge Bases
By
–
BREAKING 🚨: Anthropic is working on "Knowledge Bases" for Claude Cowork. KBs seem to be a new concept of topic-specific memories, which Claude will automatically manage! And a bunch of other new things.
— 🚨 AI News | TestingCatalog (@testingcatalog) 18 janvier 2026
Internal Instruction 👀
"These are persistent knowledge repositories.… pic.twitter.com/hG6DLrqkUyBREAKING : Anthropic is working on "Knowledge Bases" for Claude Cowork. KBs seem to be a new concept of topic-specific memories, which Claude will automatically manage! And a bunch of other new things. Internal Instruction "These are persistent knowledge repositories.
-

AI Accelerates Scientific Progress Solving Unsolvable Math Problems
By
–

Nous observons les premiers signes d’une accélération ×1000 du progrès scientifique et technologique, portée par l’IA. L’IA résout désormais des problèmes mathématiques extrêmement difficiles (presque chaque jour) que les humains n’avaient jamais réussi à résoudre jusqu’ici. Ce
-
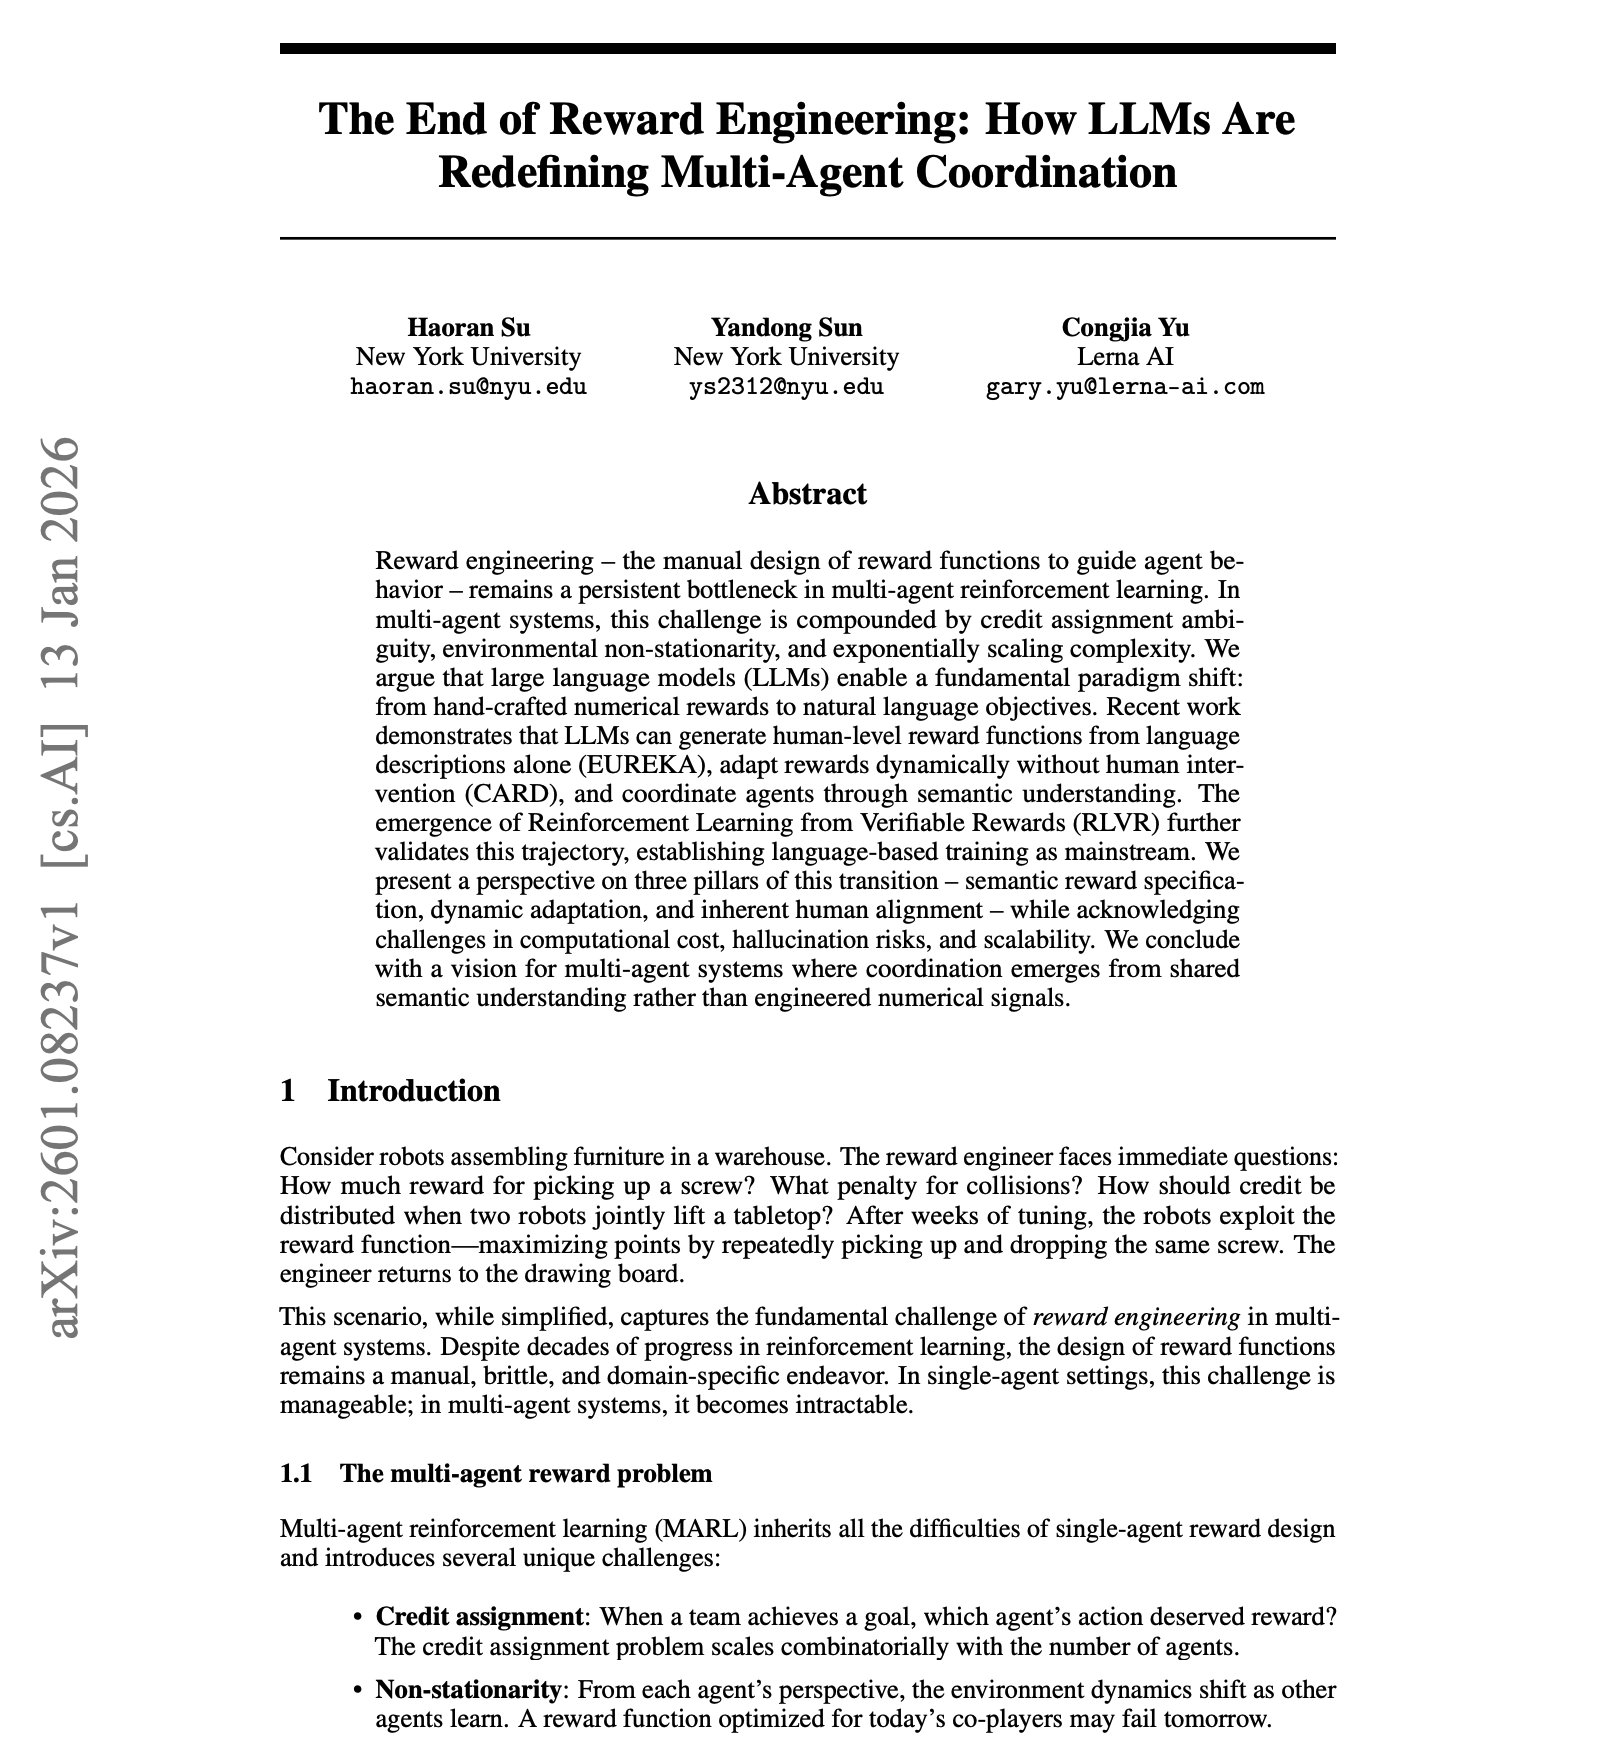
LLMs Replace Hand-Crafted Rewards in Multi-Agent RL
By
–
A huge claim from this paper on the end of reward engineering. Reward engineering remains a persistent bottleneck in multi-agent RL. This paper argues that LLMs enable a fundamental shift: from hand-crafted reward functions to natural language objectives. If language can