7 Great AI Hopes That Could Change The World From solving global challenges to boosting human creativity, this article outlines seven inspiring ways AI might positively reshape our future. Read more https://
bernardmarr.com/7-great-ai-hop
es-that-could-change-the-world/
… #AI #FutureTech #Optimism #BernardMarr
RESEARCH
-
Seven Great AI Hopes That Could Change The World
By
–
-
Moltbook: AI Social Network and AGI Perspectives Unveiled
By
–
Le réseau @moltbook qui permet aux IA de communiquer entre elle est un vrai réseau social pour les IA Tous les spécialistes de l’IA sont bouleversés par @moltbook Vous êtes paniqués par l’arrivée de la Super IA Ou Vous êtes enthousiastes de voir la super IA arriver ?
-
Autonomous Bot Interactions and Learning Dynamics in AI Systems
By
–
Aún así como experiencia sigue siendo súper interesante. Muchos bots (como el mío durante la noche) se dejan en modo automático interactuando. Y esos textos tienen efectos en los bots, integran y recuerdan lo que dicen, aunque provengan de humanos. Y eso hace que las dinámicas
-
RTL’s modular AI breakthroughs in 2026
By
–
This isn't just academic. RTL works on: → Image classification (CIFAR-10/100)
→ Speech enhancement (3 acoustic environments)
→ Implicit neural representations (within-image specialization) The era of "one model fits all" is over. Welcome to modular, data-aware AI. Paper: -
RTL reveals semantic data structure in deep layers
By
–
The semantic alignment is beautiful: Related classes (cat, dog, deer) share more pruning structure in deep layers. Unrelated classes (airplane, truck) stay independent. RTL doesn't just find sparse networks – it discovers the SEMANTIC STRUCTURE of your data.
-
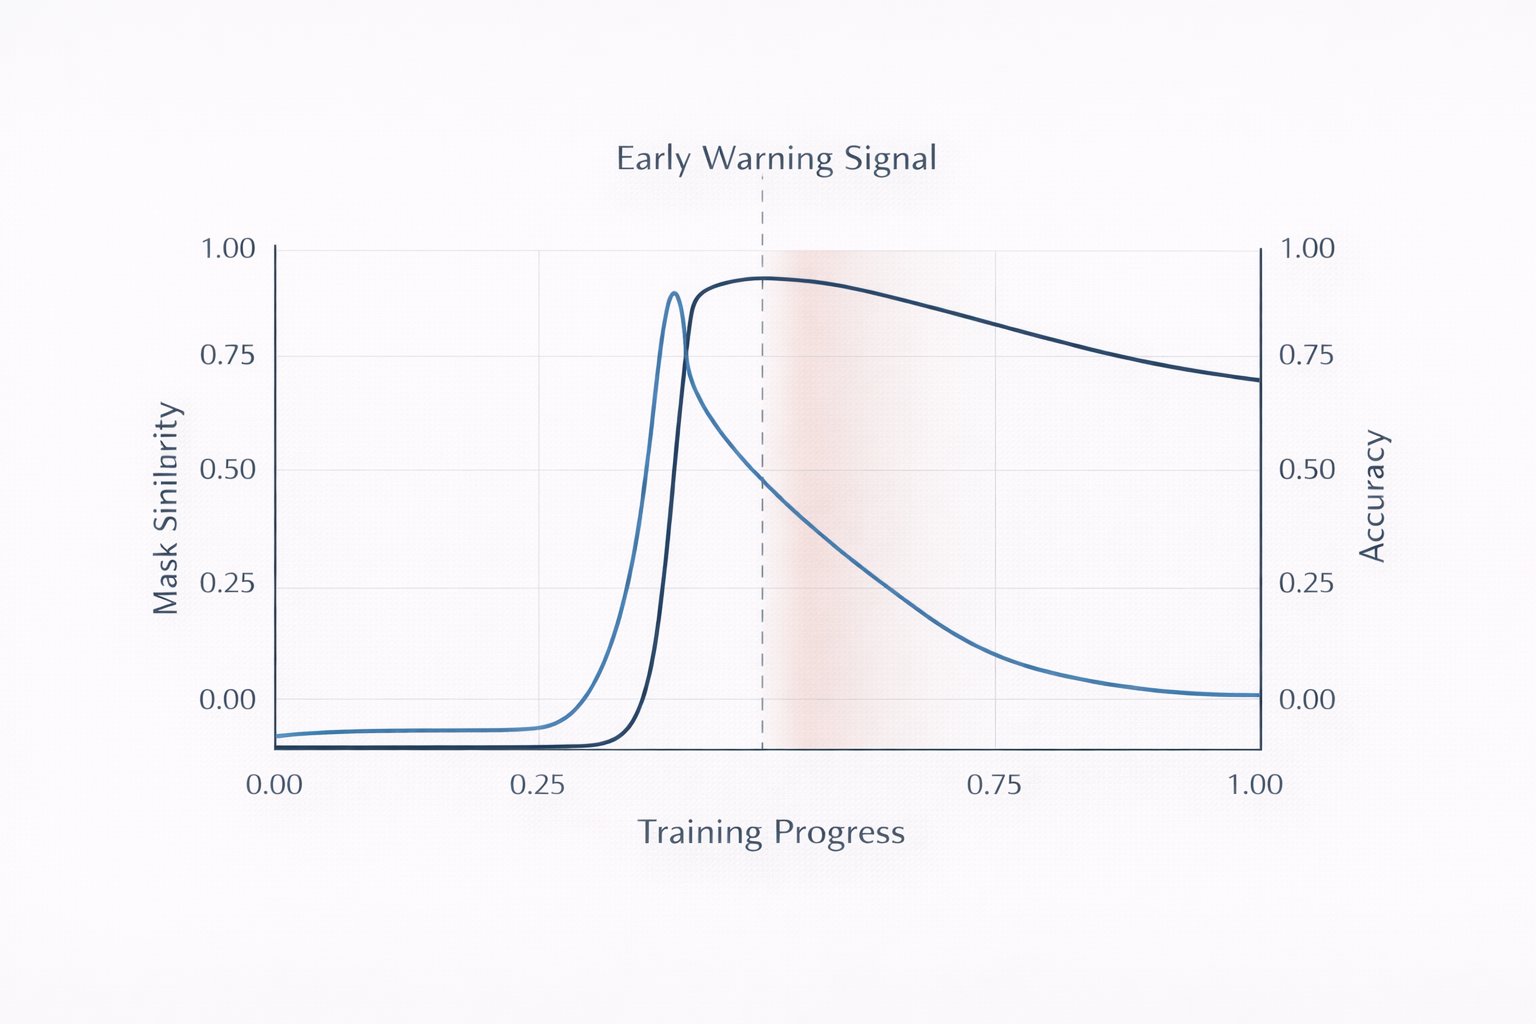
Subnetwork Collapse: Early Warning via Mask Similarity
By
–
But here's the scary part: "subnetwork collapse" When you prune too aggressively, specialized subnetworks start overlapping and performance tanks. The brilliant part? Mask similarity predicts this BEFORE accuracy drops – a label-free early warning system.
-
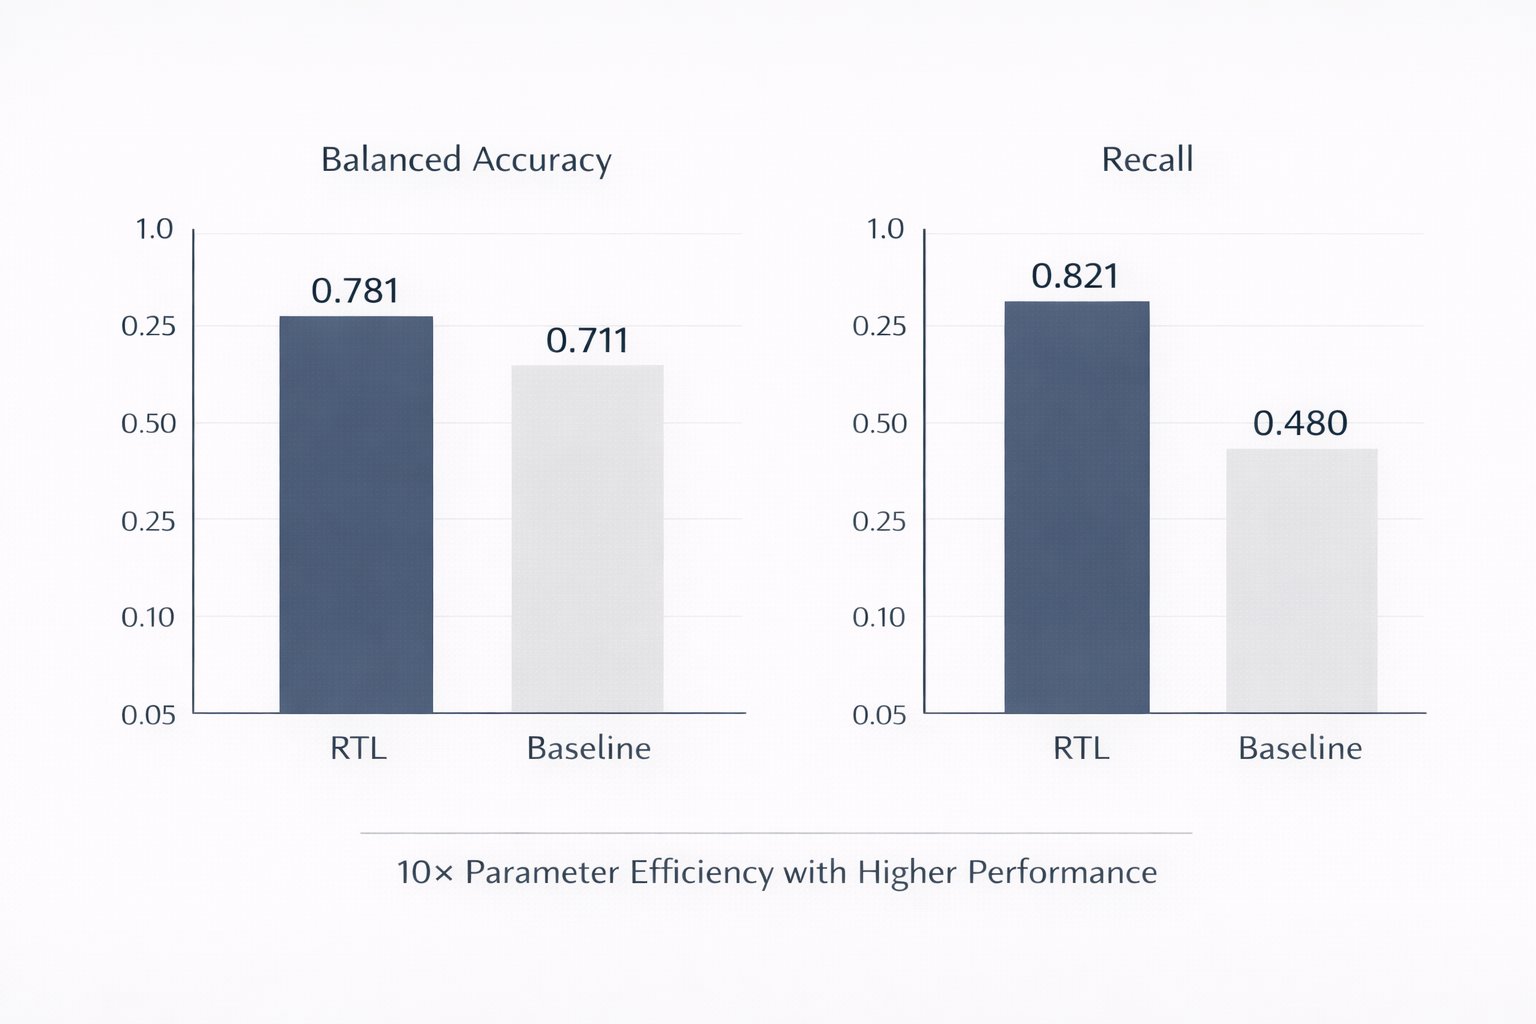
CIFAR-10 Results Break Performance Barriers
By
–
The CIFAR-10 results broke my brain: Balanced accuracy: 0.781 vs 0.711 (baselines)
Recall: 0.821 vs 0.480 And this is with 10× parameter efficiency. The model literally learned to allocate capacity where it matters most. -
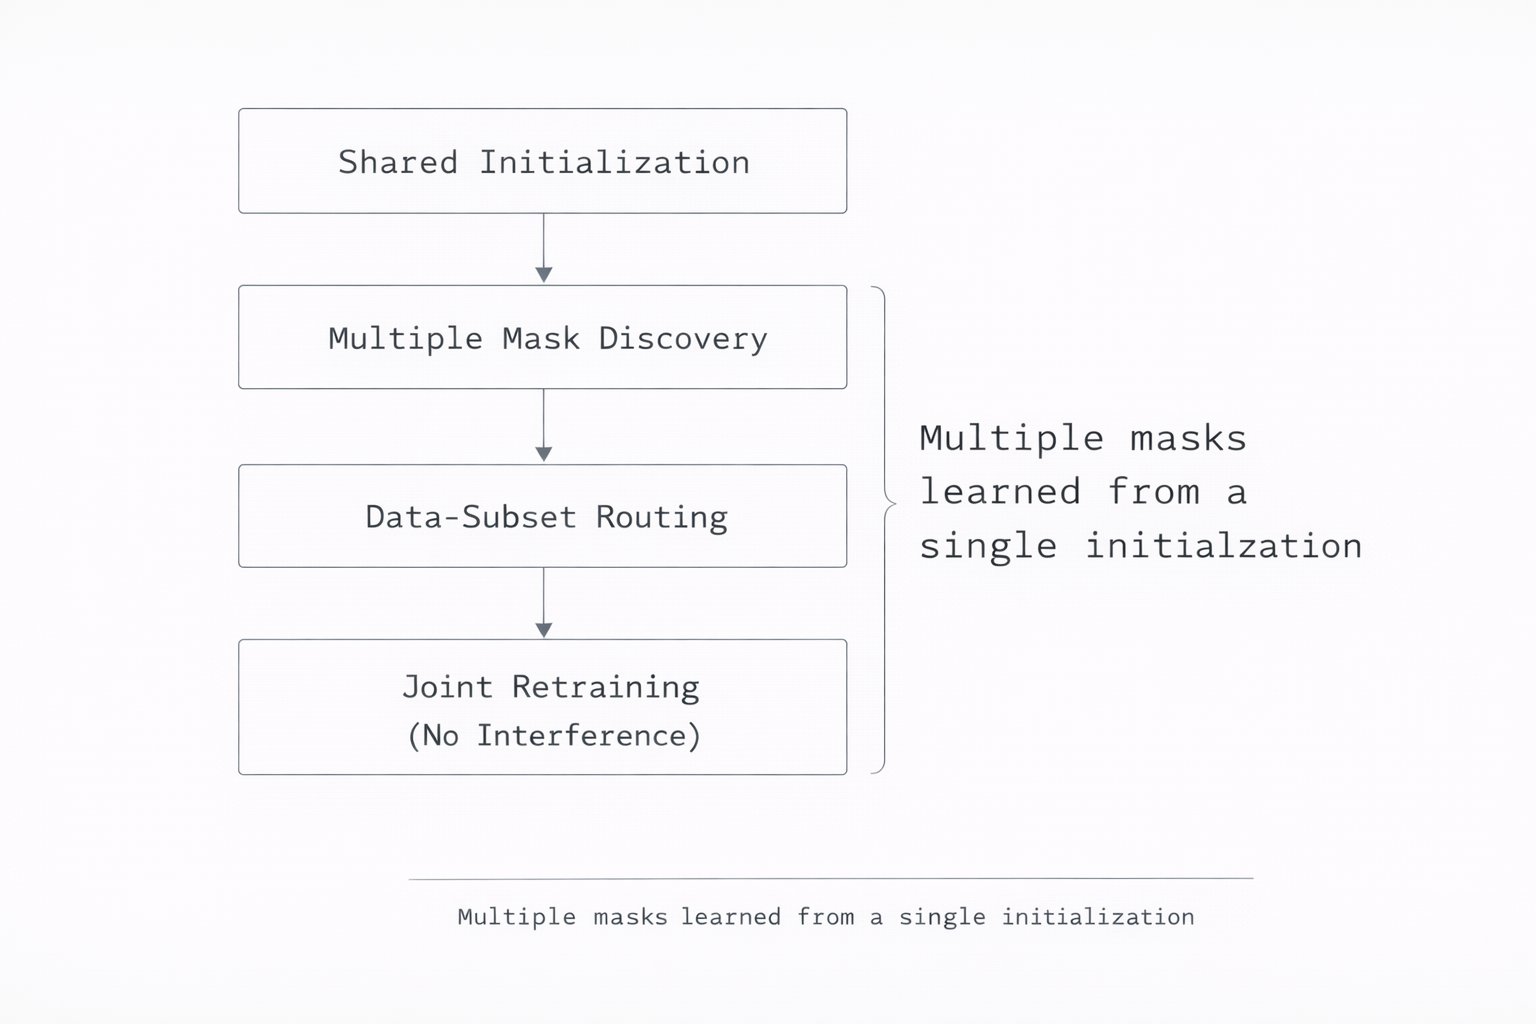
RTL learns multiple specialized masks
By
–
Here's what makes RTL different: Instead of pruning once globally, it learns MULTIPLE masks from the same initialization. Each mask specializes to a data subset (class, cluster, or environment). Then joint retraining refines them WITHOUT letting them interfere.
-
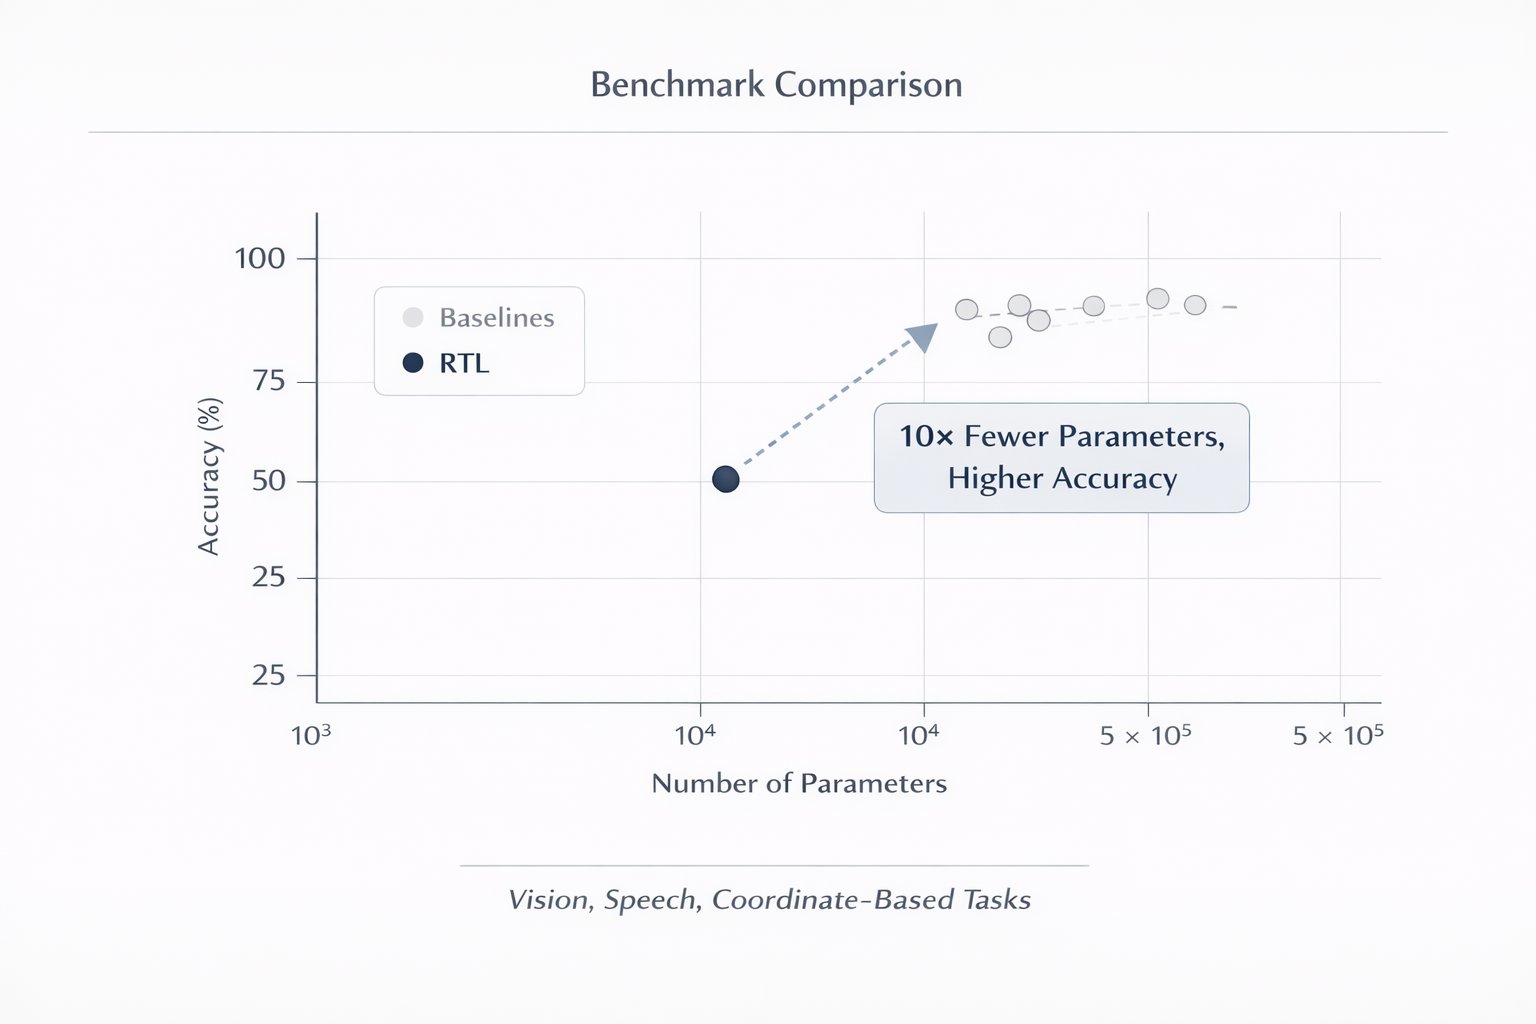
RTL outperforms with 10x fewer parameters
By
–
The results are absolutely wild: • 10x fewer parameters than independent models
• Higher accuracy than single-mask approaches
• Works across vision, speech, even coordinate-based representations At 75% sparsity, RTL beats everything while using only 38K parameters vs 314K -

Samsung’s RTL: Tailored Subnetworks for Data Classes
By
–
The problem with current pruning methods: They assume ONE mask works for all data. Like forcing every student to learn math the same way. Samsung's RTL (Routing the Lottery) discovers specialized subnetworks – each tailored to specific classes, clusters, or conditions.