GPT 5.5 drops on Cinco de Mayo.
RESEARCH
-
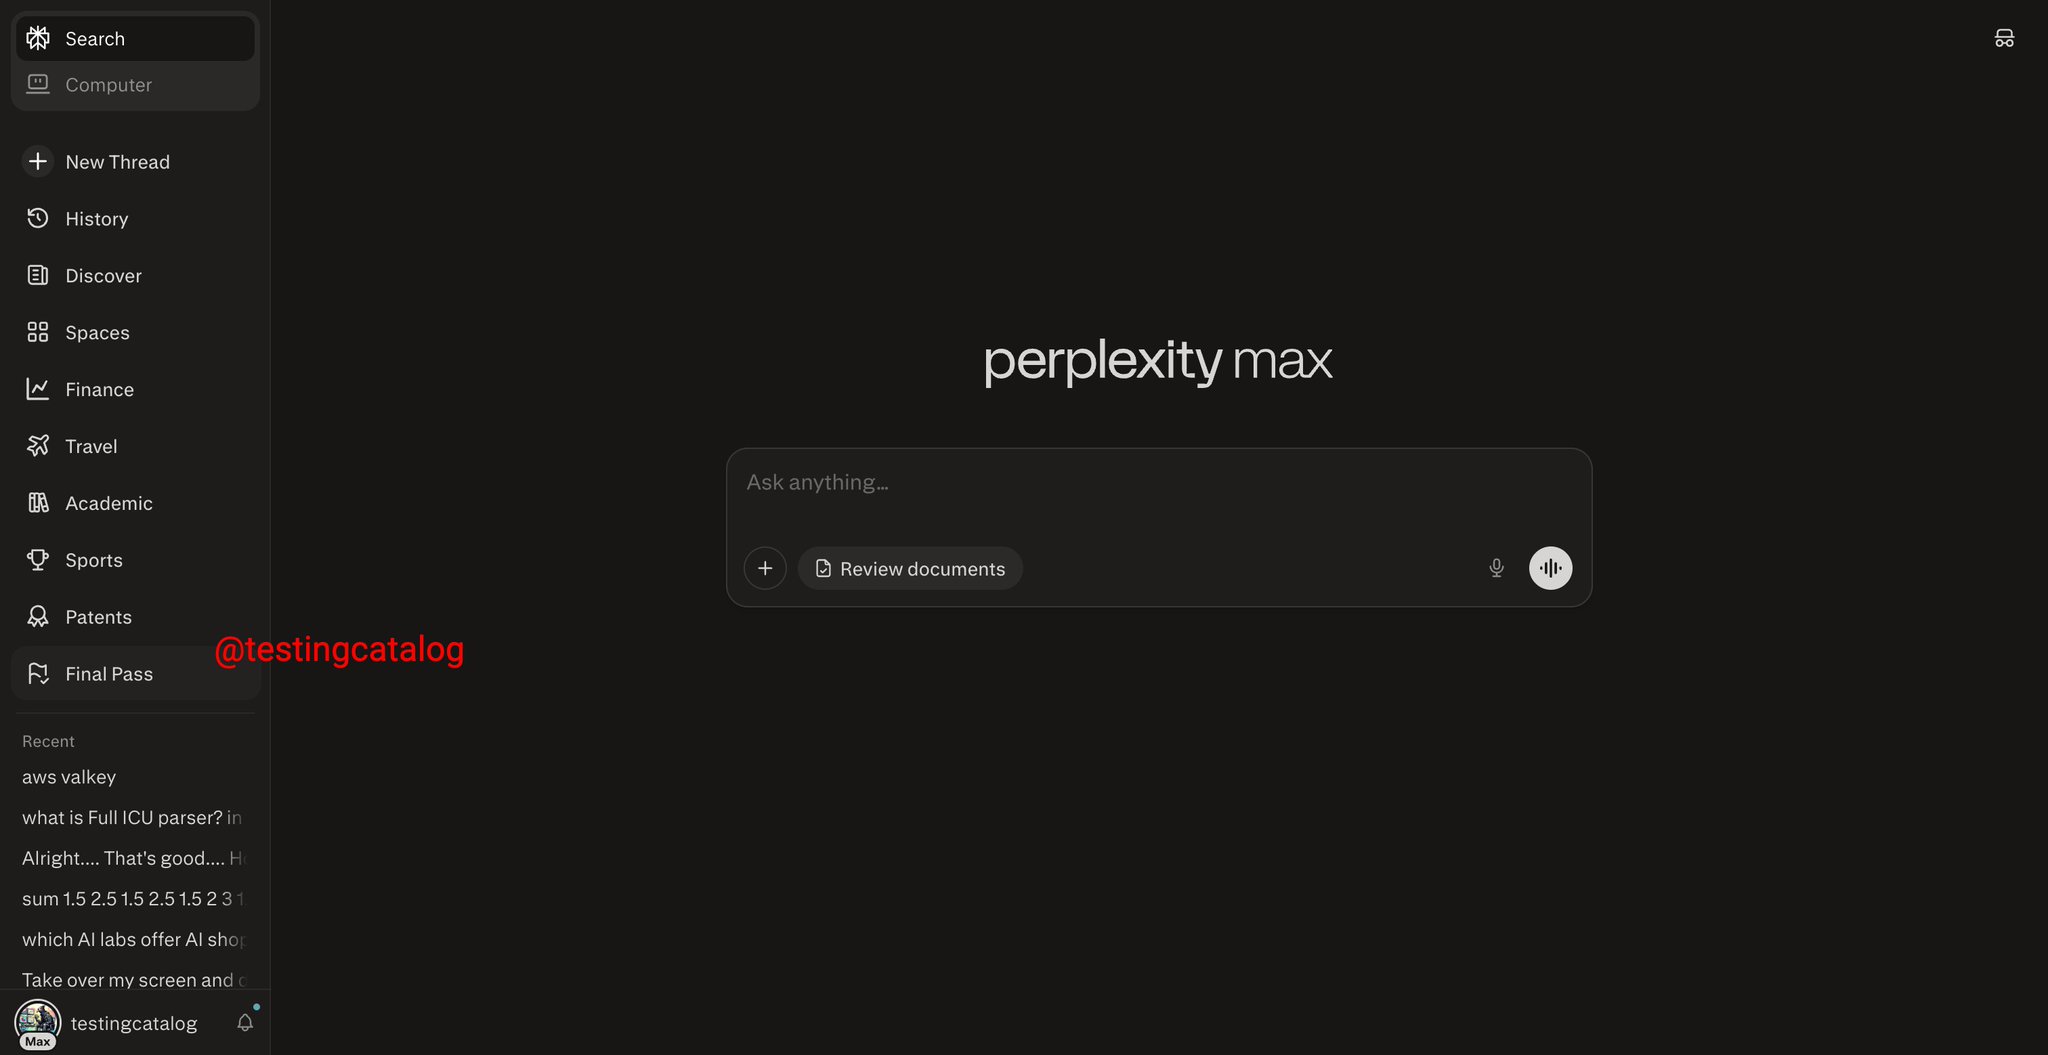
Perplexity’s Final Pass for document analysis
By
–
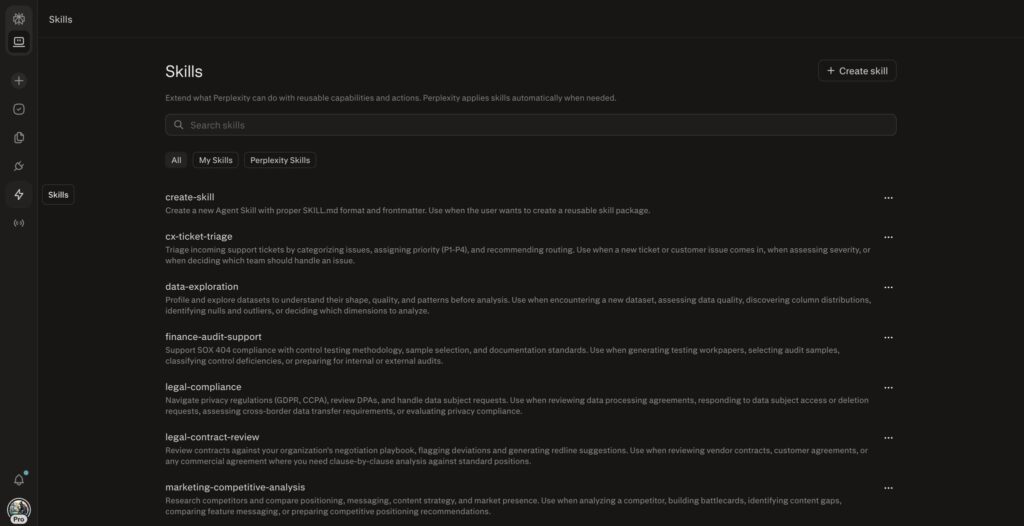
Perplexity is working on a new feature called "Final Pass," designed to perform comprehensive document analysis and fact-checking.
-
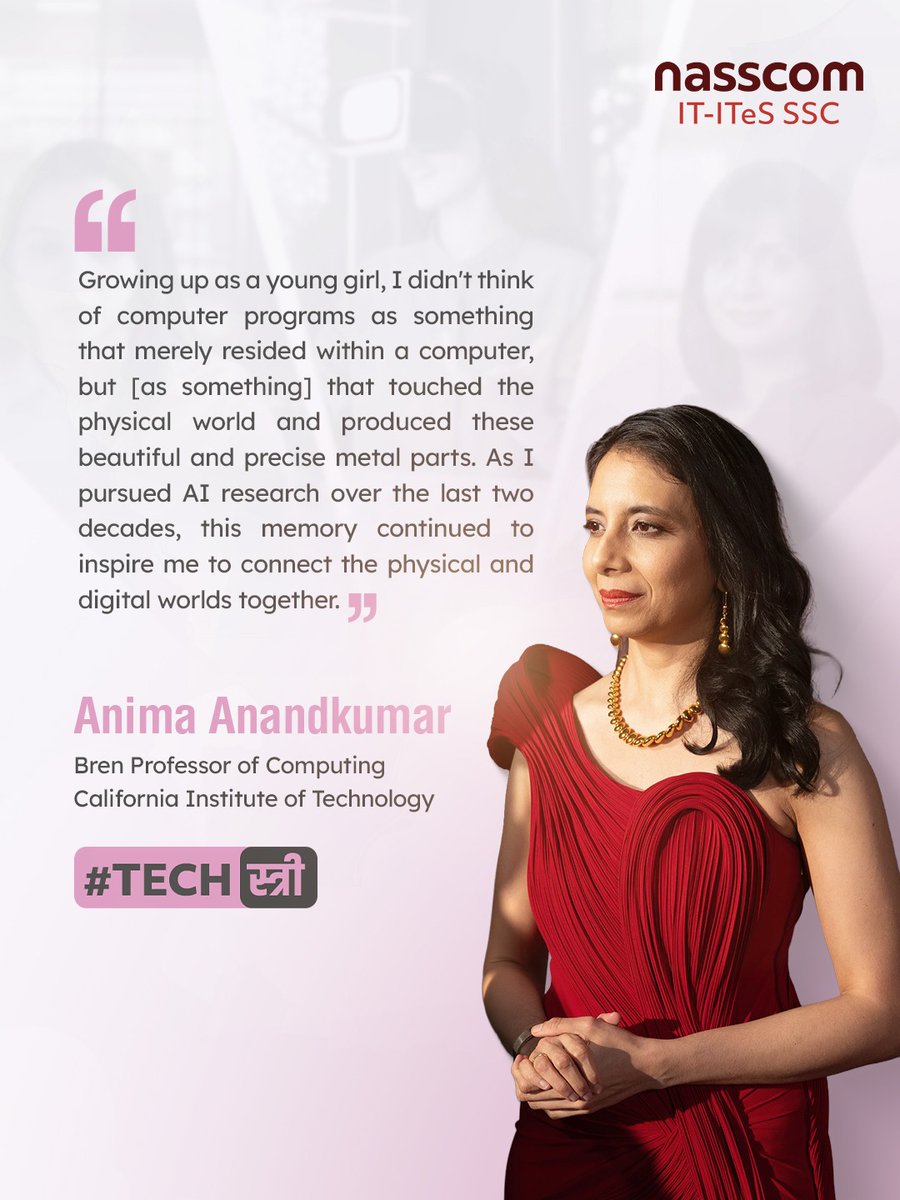
Anima Anandkumar Celebrated for AI and Weather Prediction Research
By
–
On #InternationalWomensDay, we celebrate Anima Anandkumar — Caltech Professor & NVIDIA AI leader — whose work on FourCastNet and neural operators is advancing weather prediction and scientific discovery. Celebrating the women shaping tomorrow’s STEM. #SSCNasscom #TechStree
→ View original post on X — @animaanandkumar, 2026-03-04 13:23 UTC
-
Sakana AI Vision and Japan’s AI Development Strategy Discussed
By
–
I recently had the pleasure of joining @nikkei podcast to discuss Sakana AI’s vision, the current landscape of AI development, and the strategic path forward for Japan As the AI industry moves incredibly fast, I believe it’s crucial to step back and think about how we build
-
Models Self-Regulate Reasoning Length
By
–
the deeper point here connects to something the field keeps rediscovering. we trained reasoning models to think longer. then we discovered longer doesn't mean better. now this paper shows the models themselves already know that. they're generating stop signals that our inference
-
DeepSeek and Qwen3 performance improvements
By
–
specific numbers worth sitting with: > DeepSeek-R1-7B on MATH-500: 93% accuracy (up from 91.6%), tokens cut from 3,871 to 2,141 > DeepSeek-R1-1.5B on AIME 2025: accuracy jumps 6.2 percentage points > Qwen3-8B: response length halved from 18,342 to 9,183 tokens with no accuracy
-
SAGE-RL: Simple RL Modification for Better Training
By
–
then they fold it into training with SAGE-RL. dead simple modification: in standard reinforcement learning (GRPO), you sample 8 responses per question. SAGE-RL replaces 2 of those 8 with SAGE-generated samples. the other 6 stay normal. one-line code change. the model learns to
-
SAGE: Efficient Step-by-Step Reasoning
By
–
their solution: SAGE (Self-Aware Guided Efficient Reasoning). instead of generating token by token, SAGE extends chains in whole reasoning steps. after each step, it checks: is the model confidently signaling it wants to stop? if yes, reasoning ends. no fine-tuning. no new
-
Three Key Observations on Model Paths
By
–
three observations back this up: > high-confidence paths (measured by cumulative probability) are shorter AND more accurate than standard samples > at those natural endpoints, the stop token is the model's top prediction. it knows it's finished > as you widen exploration (more