Illustrated Guide to Neural Networks and AI — With hands-on examples in PyTorch: http://
amzn.to/4tdA2dc
RESEARCH
-

Illustrated Guide to Neural Networks and AI with PyTorch Examples
By
–
-

Feature Engineering for Modern Machine Learning with Scikit-Learn
By
–
Feature Engineering for Modern Machine Learning with Scikit-Learn: Advanced Data Science and Practical Applications (Advanced Data Analysis Series) Available at http://
amzn.to/4dJAxav -

Platform and Model Design for Responsible AI Systems
By
–
Platform and Model Design for Responsible AI — Design and build resilient, private, fair, and transparent machine learning models: http://
amzn.to/3PToSvP -

Machine Learning and Artificial Intelligence: Concepts, Algorithms and Models
By
–
Machine Learning and Artificial Intelligence: Concepts, Algorithms and Models Available at http://
amzn.to/4v0rzw2 -

Classic Text on Outlier Detection in Temporal Data Streams
By
–
Classic text on Outlier Detection in Temporal Data: http://
amzn.to/2NZ64cQ … including financial, business, medical, credit, sensor network (IoT / IIoT) time series data streams, plus spatiotemporal data, network data, etc. -

Analytical Skills for AI and Data Science in Enterprise
By
–
Analytical Skills for AI and Data Science — Building Skills for an AI-Driven Enterprise: http://
amzn.to/4b6fufu …helps practitioners to create value from AI and data science using an analytical skillset — each chapter illustrates how each skill works across a collection of use -
Learn Probability Through Problems with Exercises and Solutions
By
–
Learn Probability Through Problems (exercises, hints, and solutions provided): http://
amzn.to/3vZed8W
—————
#Statistics #DataScience #Mathematics -
Current AI lacks fundamental theory of intelligence
By
–
Current AI is based on the simplest possible theory of intelligence: none. Unfortunately that means it’s 100% hacks.
→ View original post on X — @pmddomingos, 2026-04-04 03:34 UTC
-
Read more on alphaxiv.org/abs/2603.14389
By
–
read more:
alphaxiv.org/abs/2603.14389 [Translated from EN to English]→ View original post on X — @askalphaxiv, 2026-04-04 02:27 UTC
-
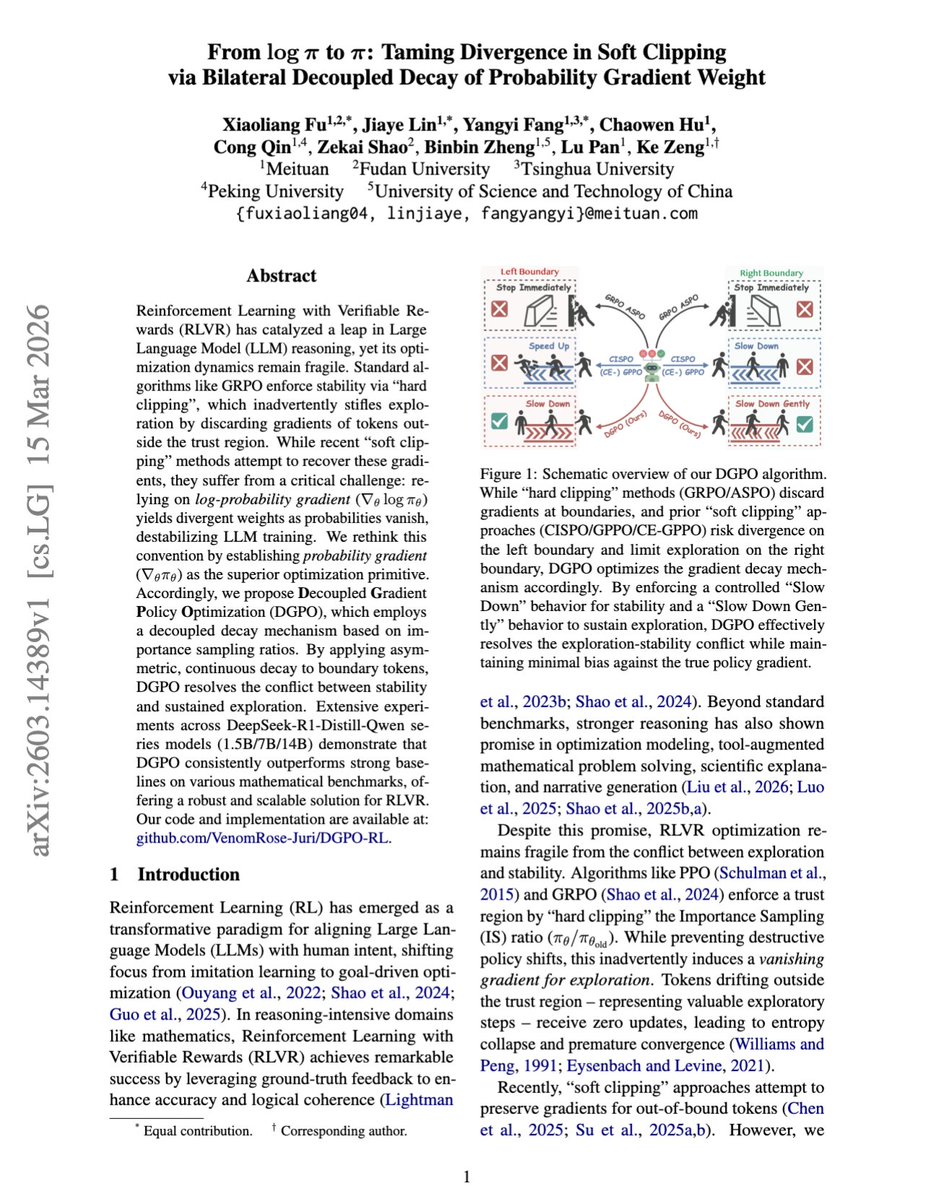
DGPO: Stable Soft-Clipping via Bilateral Decoupled Probability Gradient Decay
By
–
"From log π to π: Taming Divergence in Soft Clipping via Bilateral Decoupled Decay of Probability Gradient Weight" This paper argues that RLVR should optimize probability gradients, not log-probability gradients. So they proposed, DGPO, which applies decoupled decay at the clipping boundaries to preserve exploration while preventing gradient divergence. This results in a more stable soft-clipping objective that consistently outperforms GRPO and prior variants on mathematical reasoning benchmarks.
→ View original post on X — @askalphaxiv, 2026-04-04 02:27 UTC