
DeepSeek’s multimodal model is now live, and some users are already able to try it out. So far, it’s performing pretty well. Now the question is: will this one also be open-sourced? Tomorrow might be a good time!
MULTIMODAL AI
-

AI for Structured Visual Generation: Infographics, Slides, and Diagrams
By
–
It's especially strong at structured visuals:
> Infographics
> PPT slides
> Data-heavy posters and diagrams One model, one prompt, information-dense, formatted output. No separate design tools. No prompt chaining between systems. -

SenseNova-U1 thinks in images
By
–
SenseNova-U1 thinks in images > Not "text in – image out." It generates images natively, mid-reasoning, as part of the thinking chain. > Input question – Interleaved text + Image reasoning – Structured output.
-

@testingcatalog — 2026-04-29
By
–

SenseTime open-sourced SenseNova-U1, a multimodal image generation model built on NEO-Unify! This architecture drops the visual encoder and VAE entirely. It generates images natively as one system that can handle understanding, reasoning, and generation processes. @SenseTime_AI
-
AI Agent Transforms Mucha’s Art Into Museum Merchandise Line
By
–
A 130-year-old art legacy just got a souvenir line built by an AI agent.
— AI Highlight (@AIHighlight) 29 avril 2026
The Mucha Foundation teamed up with Accio Work to turn Alphonse Mucha's masterpieces into real merch for their Prague museum.
Product definition, supplier matching, prototyping, all done.
Cultural IP… https://t.co/sBmOuyGoGXA 130-year-old art legacy just got a souvenir line built by an AI agent. The Mucha Foundation teamed up with Accio Work to turn Alphonse Mucha's masterpieces into real merch for their Prague museum. Product definition, supplier matching, prototyping, all done.
Cultural IP -
SenseNova U1 Skills: Image Generation, PPT, Excel Analysis
By
–
SenseNova U1 Skills: The skills in the repo cover image generation & visualization, slide-deck (PPT) generation, Excel data analysis, and deep research You can plug these models directly into agent runtimes such as OpenClaw and hermes-agent. Check this out:
-

SenseTime Releases SenseNova-U1 Unified Multimodal Model
By
–
The first open-source end-to-end unified multimodal model! SenseTime just released SenseNova-U1 – a multimodal model that unifies understanding, reasoning, and generation in one continuous system. Most multimodal models either understand images OR generate images. They use
-
Engramme Launches Large Memory Models, Replacing Traditional RAG
By
–
RIP RAG.
— AI Highlight (@AIHighlight) 29 avril 2026
Engramme just launched Large Memory Models, a new AI architecture built from scratch for human memory.
No vector search. No prompting. Memories surface on their own across Gmail, Zoom, Slack, and Meta glasses. https://t.co/9fQCesTjByRIP RAG. Engramme just launched Large Memory Models, a new AI architecture built from scratch for human memory. No vector search. No prompting. Memories surface on their own across Gmail, Zoom, Slack, and Meta glasses.
-
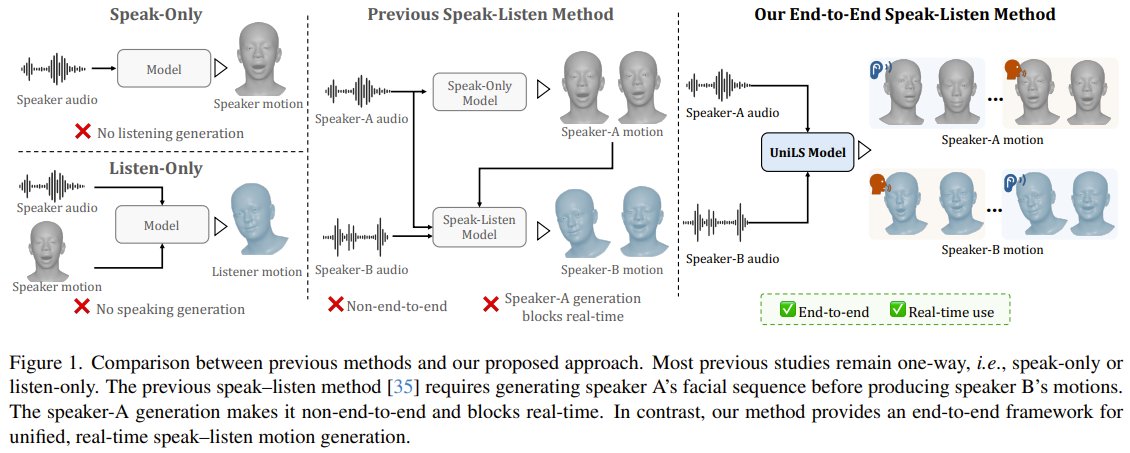
UniLS: Natural Avatar Listening Through Facial Movement Learning
By
–
Can an avatar truly listen as naturally as it speaks? Researchers from Shanda AI Research and the University of Tokyo present UniLS. They solved the "stiff listener" problem by first teaching an AI the natural rhythm of facial movements without audio, then fine-tuning it with
-

Xiami mimo-v2.5 pro MIT license surpasses Opus 4.5
By
–
Xiami mimo-v2.5 pro MIT license surpasses Opus 4.5 on arena Amazing achievement.