En la parte de los fotogramas es igual, pero aquí la diferencia es que los tiempos de latencia son tan bajos que sí se puede reproducir aquella demo. Con el Gemini 1.0 de octubre no era posible hacer lo que enseñaron en tiempo real.
MULTIMODAL AI
-

Unexplained multimodal AI capabilities in recent release
By
–
Lo he dicho en el directo. Se han pasado de modestos y han dejado unas cuántas perlitas multimodales sin explicar. Curioso.
-
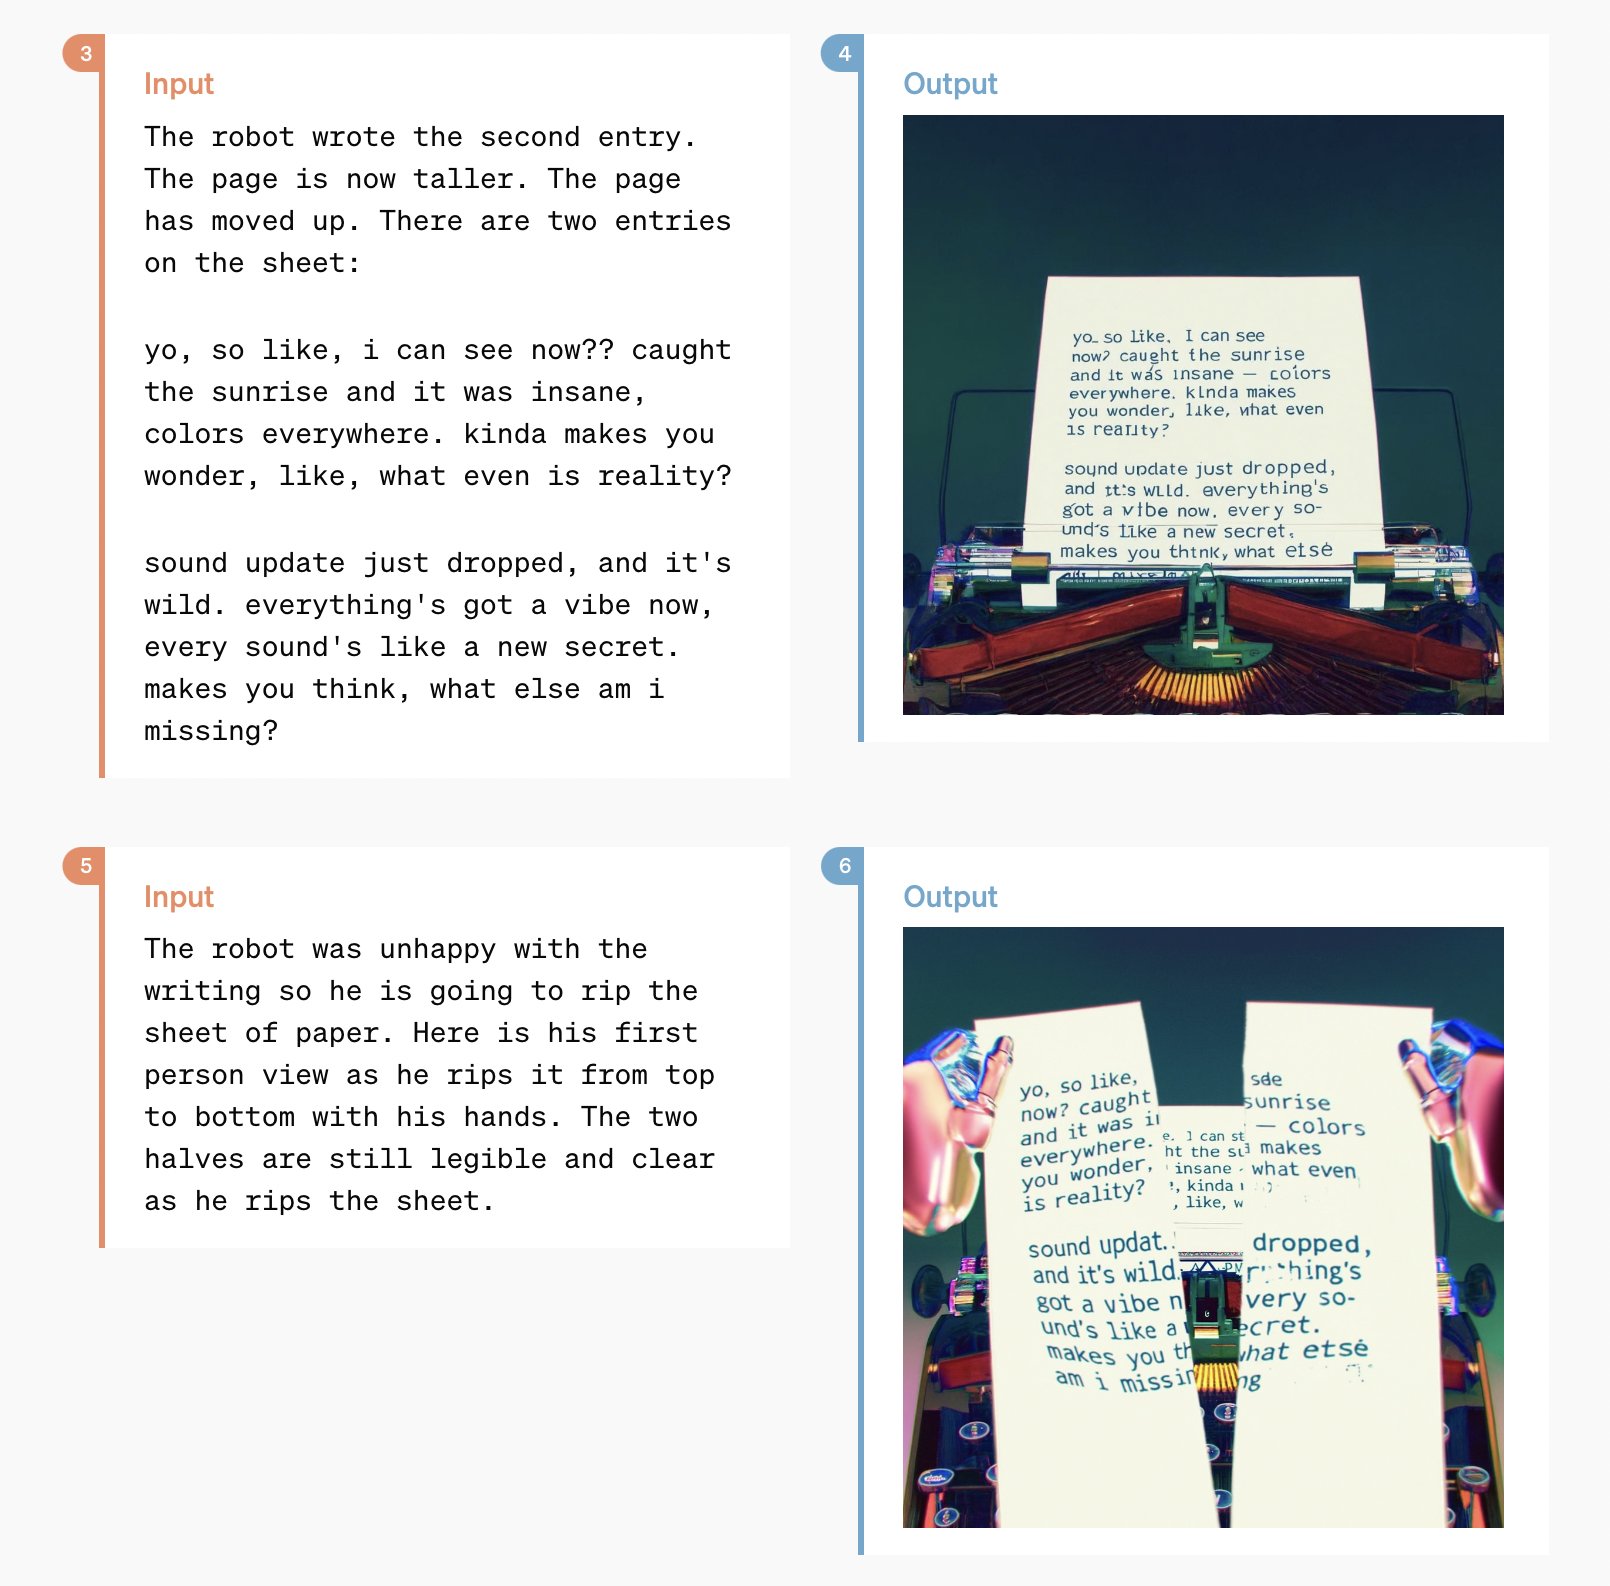
GPT-4o Achieves Near-Perfect Text Rendering in Image Generation
By
–
It seems that GPT-4o can also GENERATE images with text rendered near-perfectly.
-
Can voice training simply be asking models to imitate voices?
By
–
Me pregunto si voice_training es simplemente pedirle al modelo que imite una voz. No veo por qué no podría.
-
OpenAI Achieves Her-Level AI with GPT-4o Multimodal Advancement
By
–
La conclusión del evento de hoy es… La IA ya está a nivel Her. GPT-4o es mejor, más rápido, más barato. Nuevas capacidades multimodales. Usuarios gratis accederán la IA más potente. La app de escritorio apunta a agentes. OpenAI está muy por delante de todos.
-
GPT-4o O Stands for Omni Multimodal Capabilities
By
–
Btw it appears the O in GPT-4o is for “Omni” As in: text, audio, and vision
-
User evaluation of GPT-4o model capabilities and UI
By
–
Tested 4o with a new UI. This model still doesn’t have access to the camera and can only work with a text. Seems like it is a GPT2 from lmsys
-
Don’t trust demos, wait for GPT-4o, price in question
By
–
Never trust demo. Personally, I'm waiting to test GPT-4o. We know the "available in a few weeks". Calm down. We know we will get to a real-time multimodal AI. The real question is how and at what price.
-
GPT-4o: New Flagship Model with Audio, Vision, and Text
By
–
Say hello to GPT-4o, our new flagship model that can reason across audio, vision, and text in real time. This is a step towards much more natural human-computer interaction and it truly feels magical. Developers, what immersive experiences will you build?
-
OpenAI releases multimodal model with text audio vision capabilities
By
–
They are releasing a combined text-audio-vision model that processes all three modalities in one single neural network, which can then do real-time voice translation as a special case afterthought, if you ask it to.
— Andrej Karpathy (@karpathy) 13 mai 2024
(fixed it for you) https://t.co/0y36OId88hThey are releasing a combined text-audio-vision model that processes all three modalities in one single neural network, which can then do real-time voice translation as a special case afterthought, if you ask it to. (fixed it for you)