
Prêt à embarquer pour le Futur avec une nouveauté Grokesque ? Pixtral, le nouveau modèle multimodal de Mistral Google fait des podcasts avec vos notes OpenAI sur le point d’être valorisé 150 Mrds de $ #FrenchTech : Les 20 M€ de @JusMundi_com Près de 300 000
MULTIMODAL AI
-
AI Transforms Audio Into Realistic Video With Subtle Facial Expressions
By
–
La inteligencia artificial ya es capaz de transformar audio en un vídeo bastante realista. Es capaz de representar matices sutiles, desde suspiros a expresiones faciales haciendo el vídeo creíble. No olvidemos que estas herramientas se encuentran en una etapa cercana y que poco
-

Grok Generates AI Art for Chat with Lightning Bolt
By
–
Et voila l'oeuvre de Grok pour un chat avec un éclair @emiliemarquois ! Si tu veux le changer dans ton article, feel free. Je trouve plutôt réussi, même si je sais que tu préfères les gifs.
-

Google Podcasts, Adobe Video AI, Pixtral 12B, and New AI Jobs
By
–
Top stories in AI today: -Google turns your notes into podcasts
-Adobe previews new AI video model
-How to control AI video camera angles
-Mistral releases multimodal Pixtral 12B
-6 new AI tools & 4 new AI jobs Read more: http://
therundown.ai/p/google-audio
-overviews
… -
Mistral AI’s Pixtral-12B Vision Model Excels, Outperforming Qwen2-7B
By
–
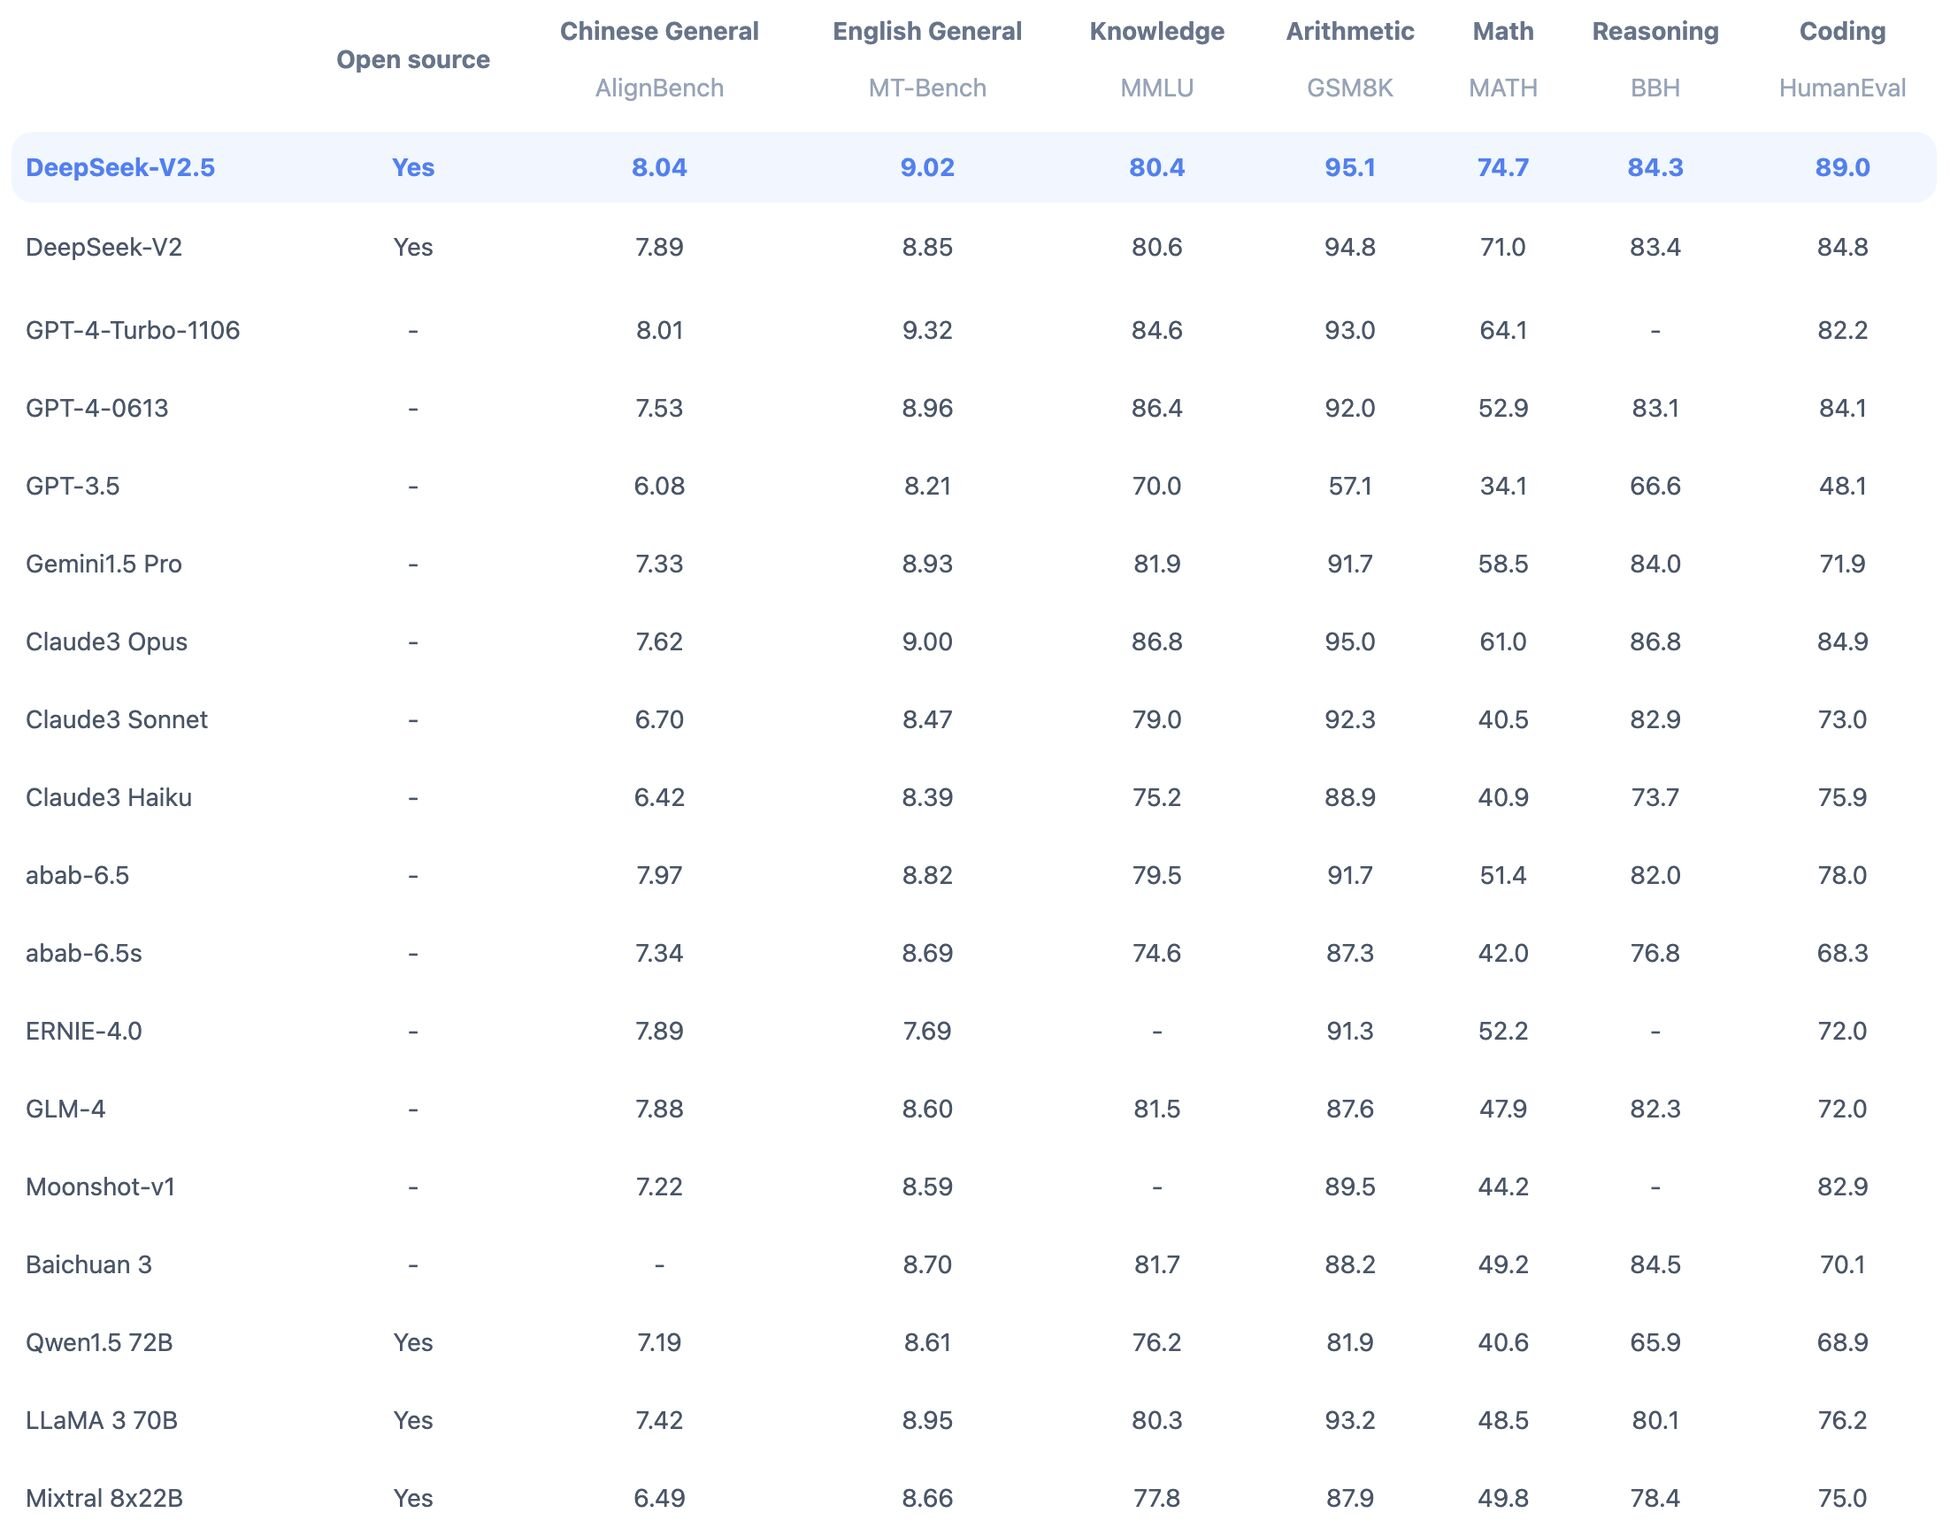
𝗢𝗽𝗲𝗻 𝗟𝗟𝗠𝘀 𝗮𝗿𝗲 𝗼𝗻 𝗳𝗶𝗿𝗲 𝗿𝗶𝗴𝗵𝘁 𝗻𝗼𝘄! 𝗗𝗲𝗲𝗽𝗦𝗲𝗲𝗸-𝗩𝟮.𝟱 𝗮𝗻𝗱 𝗼𝘁𝗵𝗲𝗿 𝘁𝗼𝗽 𝗿𝗲𝗹𝗲𝗮𝘀𝗲𝘀 Mistral AI just released Pixtral-12B, a vision models that seems to perform extremely well! From Mistral’s own benchmark, it beats the great Qwen2-7B
-
VMAS: Video-to-Music Generation via Semantic Alignment Framework
By
–
VMAS Video-to-Music Generation via Semantic Alignment in Web Music Videos discuss: https://
huggingface.co/papers/2409.07
450
… We present a framework for learning to generate background music from video inputs. Unlike existing works that rely on symbolic musical annotations, which are limited in -

MVLLaVA: Intelligent Agent for Novel View Synthesis
By
–
MVLLaVA An Intelligent Agent for Unified and Flexible Novel View Synthesis discuss: https://
huggingface.co/papers/2409.07
129
… This paper introduces MVLLaVA, an intelligent agent designed for novel view synthesis tasks. MVLLaVA integrates multiple multi-view diffusion models with a large -

Hi3D: High-Resolution Image-to-3D Generation Using Video Diffusion
By
–
Hi3D Pursuing High-Resolution Image-to-3D Generation with Diffusion Models discuss: https://
huggingface.co/papers/2409.07
452
… Despite having tremendous progress in image-to-3D generation, existing methods still struggle to produce multi-view consistent images with high-resolution textures -
User review and comparison of AI music generation tools
By
–
Yes. MusicFX is quite good. On a pair with Udio and Suno. I am waiting for VideoFX storyboard the most
-

NotebookLM Audio Overviews demonstrate impressive AI content transformation
By
–

New NotebookLM Audio Overviews are quite impressive. It turns any content into a podcast in a few seconds