Progress towards real-time generation from multimodal models:
MULTIMODAL AI
-
ElevenLabs Introduces Voice Design for Text-to-Voice Generation
By
–
BREAKING 🚨: ElevenLabs released Voice Design 🔥
— 🚨 AI News | TestingCatalog (@testingcatalog) 23 octobre 2024
It allows you to generate any voice from a text prompt.
It has been never that simple to create a video of a speaking character with all the AI tools available today! https://t.co/m74dlEsASW pic.twitter.com/3T2bU1VWNsBREAKING : ElevenLabs released Voice Design It allows you to generate any voice from a text prompt. It has been never that simple to create a video of a speaking character with all the AI tools available today!
-

Google Releases MusicFX DJ AI Music Generation Tool
By
–

BREAKING : Google released MusicFX DJ – a new ai generated music experiment on AI Test Kitchen. This tool lets you generate music themes via text prompts and remix them via various UI controls.
-

Meta Movie Gen Research Paper and Media Foundation Models Breakdown
By
–
That’s all for now, but we’re excited to share more. You can see even more breakdowns and examples of what Meta Movie Gen can do in the full research paper https://
ai.meta.com/research/publi
cations/movie-gen-a-cast-of-media-foundation-models/?utm_source=twitter&utm_medium=organic_social&utm_content=thread&utm_campaign=moviegen
… -

Movie Gen Audio Output Demo Walk Through
By
–
Walk with us (and turn up your volume to hear the output from Movie Gen Audio in the last clip!) pic.twitter.com/w1rmLlDP6E
— AI at Meta (@AIatMeta) 23 octobre 2024Walk with us (and turn up your volume to hear the output from Movie Gen Audio in the last clip!)
-
Meta Movie Gen Models Deliver Impressive Results in Latest Examples
By
–
We’re continuing to see exciting results as we work with our Meta Movie Gen models, here are some more examples of what they can do 🧵 pic.twitter.com/Prswvvcc6v
— AI at Meta (@AIatMeta) 23 octobre 2024We’re continuing to see exciting results as we work with our Meta Movie Gen models, here are some more examples of what they can do
-
Mochi-1 Preview Model Now Available on Hugging Face
By
–
Don’t worry, we got ya! 😉 https://
huggingface.co/genmo/mochi-1-
preview
… -

New SoTA Models Released: Text-to-Image and Video Boom
By
–
chat wtf – I take a week off and y’all out here dropping SoTA models all in a day!? jokes aside, quite psyched to see text to image/ video booming looking forward to reading more about them when I’m back next week be good 😉
-
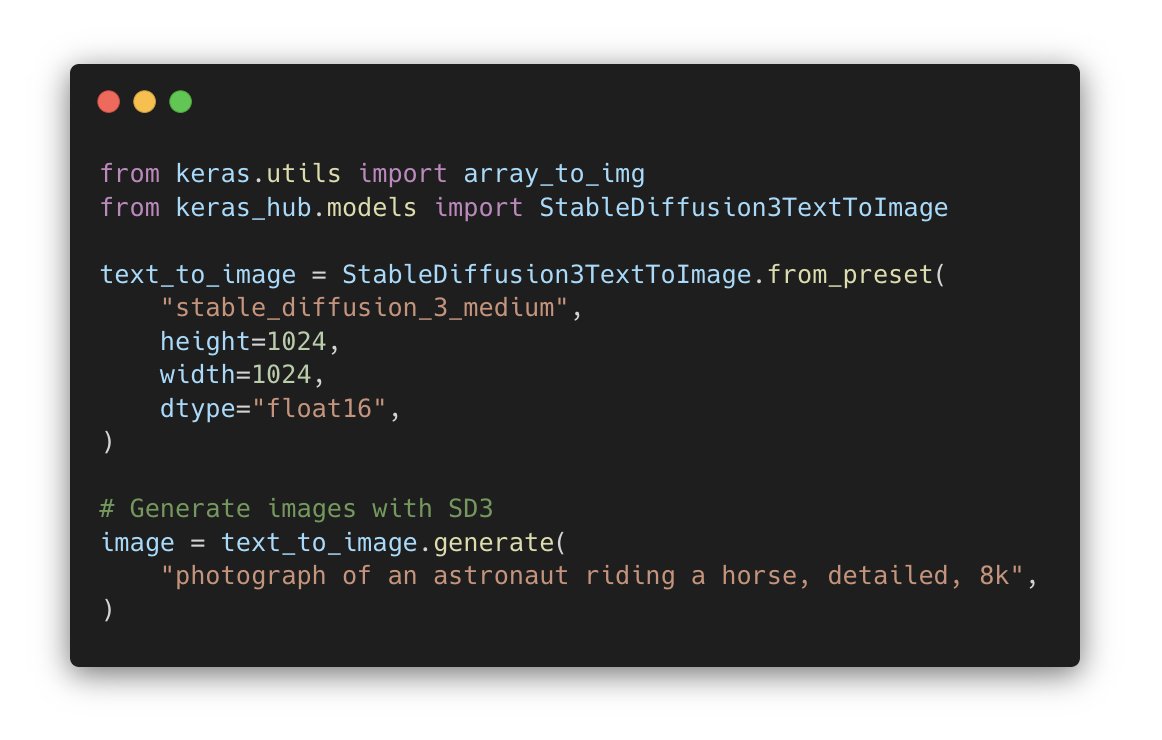
StableDiffusion 3 Image Generation with KerasHub Float16 Inference
By
–
Generating a 1024×1024 image with StableDiffusion 3 in KerasHub, using float16 inference. The `generate` method is compiled, and compilation happens on the first call. The next time you call the model again you will reuse the same compiled function and it will be super fast.
-

Getting Started with Meta’s SAM2 on Databricks
By
–
Get started with Meta’s Segment-Anything-Model 2 (SAM2) on Databricks! This #DatabricksCommunity technical post covers experimentation with SAM2 in a Databricks Notebook, expanding on the default examples by using custom notebook cells for visualization. https://
dbricks.co/4hcABPw