Here’s how @efaced134427 pairs SD3.5 Large with LLM prompt refinement to create detailed outputs: Starting Prompt:
“An abstract creature made of shadows and mist.” LLM Breakdown:
The LLM splits the initial prompt into three enriched prompts. Dual CLIP Integration:
The
MULTIMODAL AI
-

SD3.5 and LLM Prompt Refinement for Enhanced Creative Outputs
By
–
-

LiminaBrush: AI Image Lighting Conversion Tool with User Scribbles
By
–
LiminaBrush – convert an image to a "uniformly-lit" appearance, and another stage to generate the illumination effect with user scribbles
-
Vocal Sandbox Robot Learns Skills with GPT-3.5 Turbo
By
–
The Vocal Sandbox may look like a typical robot setup—arm, cameras, laptop—but there’s more than meets the eye. Powered by GPT-3.5 Turbo, it learns both low- and high-level skills on the fly to perform desired actions and assist in real time.
-
Vision AI Predicted to Lead 2025 Over Voice
By
–
What's possible when AI understands what you're seeing, not just what you're saying? If voice was the breakout feature of 2024, I'm predicting it will be vision that takes center stage in 2025. More predictions from me & some great company: https://
deeplearning.ai/the-batch/issu
e-282/
… Thank you -
RenderNet AI creates music videos in minutes
By
–
Présentation de RenderNet AI / @rendernet_ai
— Jouhatsu | AI Influence Operator (@Jouhatsu_ai) 3 janvier 2025
Créez des clips musicaux en quelques minutes grâce à l'IA, en 3 étapes simples !
1.Téléchargez une chanson ou un morceau.
2.Décrivez votre vidéo ou collez les paroles de la chanson.
3.Choisissez un personnage à mettre en avant dans… pic.twitter.com/NeGumDXDUQPrésentation de RenderNet AI / @rendernet_ai Créez des clips musicaux en quelques minutes grâce à l'IA, en 3 étapes simples ! 1.Téléchargez une chanson ou un morceau.
2.Décrivez votre vidéo ou collez les paroles de la chanson.
3.Choisissez un personnage à mettre en avant dans -
Felix Tribute Visual Language Models Pioneer DeepMind
By
–
Very saddened by this. I was lucky to interact with Felix at DeepMind and his creative thinking was clearly ahead of his time. Our last work together: one of the very first Visual Language Models: https://
arxiv.org/abs/2106.13884 RIP Felix. -

Incredible breakthroughs happening in diffusion models
By
–
incredible things are happening in the diffusion land
-
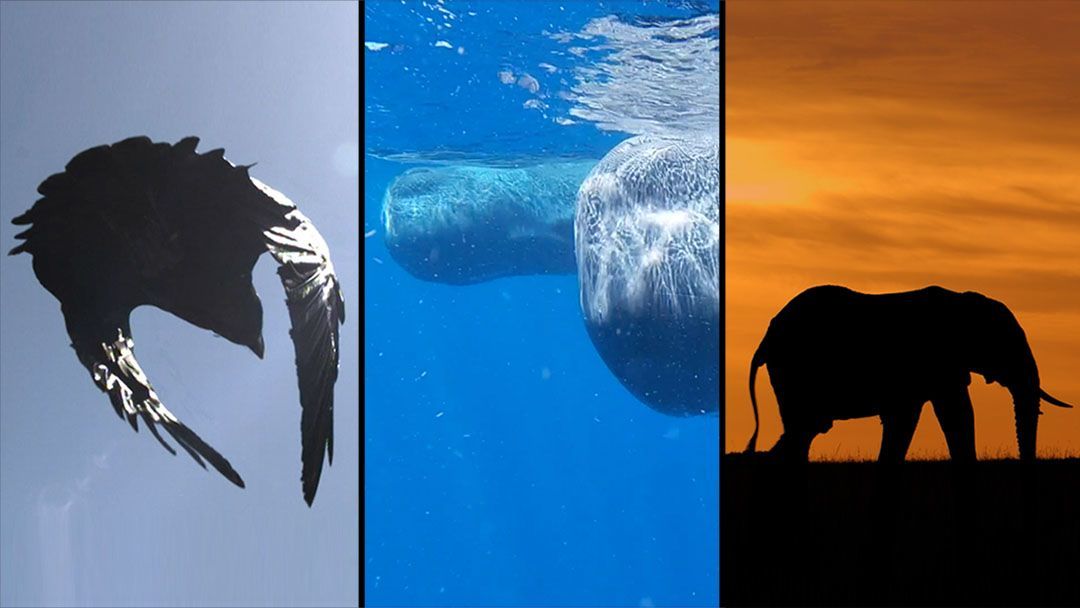
AI Decodes Animal Communication Patterns with Machine Learning
By
–
AI decodes the calls of the wild https://
go.nature.com/4gp4X0f
#AI #MachineLearning #DeepLearning #LLMs #DataScience -
Discussion of image generator and LLM prompt behavior
By
–
The image generator and the LLM are two models and the text shown in the first reply isn’t what it’s using as the prompt (which is probably just “portrait of Gary Marcus” or similar). Also note it doesn’t draw “Gary” or “Marcus” as majority black, but it does for “Marcus Gary.”