
Don’t think, I know, especially since this is not the first time, it’s also not just any viral tweet. It’s not the virality, it was the nature of the post, a GPT-Image 2 post that went very viral and got very polarized, was the palm reading post. Got close to 10M views,
MULTIMODAL AI
-
ClickUp Brain Integrates Multiple Frontier AI Models for Seamless Task Management
By
–
ClickUp Brain routes between 14+ frontier models from Anthropic, OpenAI, and Google under one subscription. The real shift here is the model feeling native, not swapped in. Whichever model you pick, your tasks, docs, and projects are loaded in automatically. Test it out
-

Autonomous AUVs for Coral Reef Biodiversity Mapping via AI
By
–
Autonomous Seeking and Mapping Coral Reef Biodiversity Hotspots with a Multimodal AUV! #BigData #Analytics #DataScience #AI #MachineLearning #NLProc #LLM #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist
-
Annotation sémantique 3D en temps réel avec IA
By
–
Semantically annotating 3D gaussian splats on the fly using gemini 3.1 + sparkjs
— Bilawal Sidhu (@bilawalsidhu) 15 mai 2026
1. Load any 3D scene and hit scan
2. Get 2D detections from VLM
3. Cluster outputs & project into 3D world space
4. Save as a persistent 3D semantic layer
Inspired by @alexanderchen's experiments… pic.twitter.com/CKZzpRkKtpSemantically annotating 3D gaussian splats on the fly using gemini 3.1 + sparkjs 1. Load any 3D scene and hit scan
2. Get 2D detections from VLM
3. Cluster outputs & project into 3D world space
4. Save as a persistent 3D semantic layer Inspired by @alexanderchen
's experiments -

Testing Higgsfield’s Supercomputer with multi-model routing
By
–
I've been testing Higgsfield's Supercomputer for the past few days, and it genuinely caught me off guard. You type a task in plain language. The system picks from 61 production skills, routes each sub-task to the best available model (GPT-5.5, Claude Opus, Gemini, Seedance, Veo,
-
Google Rolls Out Updated Gemini Mobile App Experience with Interactive UI
By
–
Google is silently rolling out an updated Gemini experience for its mobile apps ahead of Google I/O.
— 🚨 AI News | TestingCatalog (@testingcatalog) 14 mai 2026
Its updated UI for Gemini Live features an interactive "bar" or a dynamic island that reacts to your taps and can wave back.
It should get loads of superpowers soon 👀 pic.twitter.com/WJv6DxtaZIGoogle is silently rolling out an updated Gemini experience for its mobile apps ahead of Google I/O. Its updated UI for Gemini Live features an interactive "bar" or a dynamic island that reacts to your taps and can wave back. It should get loads of superpowers soon
-

Multimodal AI outperforms physicians in simulated study
By
–
A multimodal AI (AIME) had superior performance compared with 18 physicians for almost every metric (29 of 32 axes). Randomized, but simulated, not real-world clinical practice. @GoogleDeepMind @alan_karthi @RyutaroTanno https://
nature.com/articles/s4159
1-026-04371-0
… -
Reflections on the development and training of video AI models
By
–
It's heavy how strong the blow was to the Seedance 2.0 table that completely halted the cadence of video models we'd been carrying up to then. May they rest in peace, all those model checkpoints that were trained and never published because they weren't up to par
-
AnyFlow: New Video Diffusion Model with On-Policy Flow Map Distillation
By
–
AnyFlow
— AK (@_akhaliq) 14 mai 2026
Any-Step Video Diffusion Model with On-Policy Flow Map Distillation pic.twitter.com/rXWlrNhv0KAnyFlow Any-Step Diffusion Model with On-Policy Flow Map Distillation
-
MulTaBench: A New Benchmark for Multimodal Tabular Learning
By
–
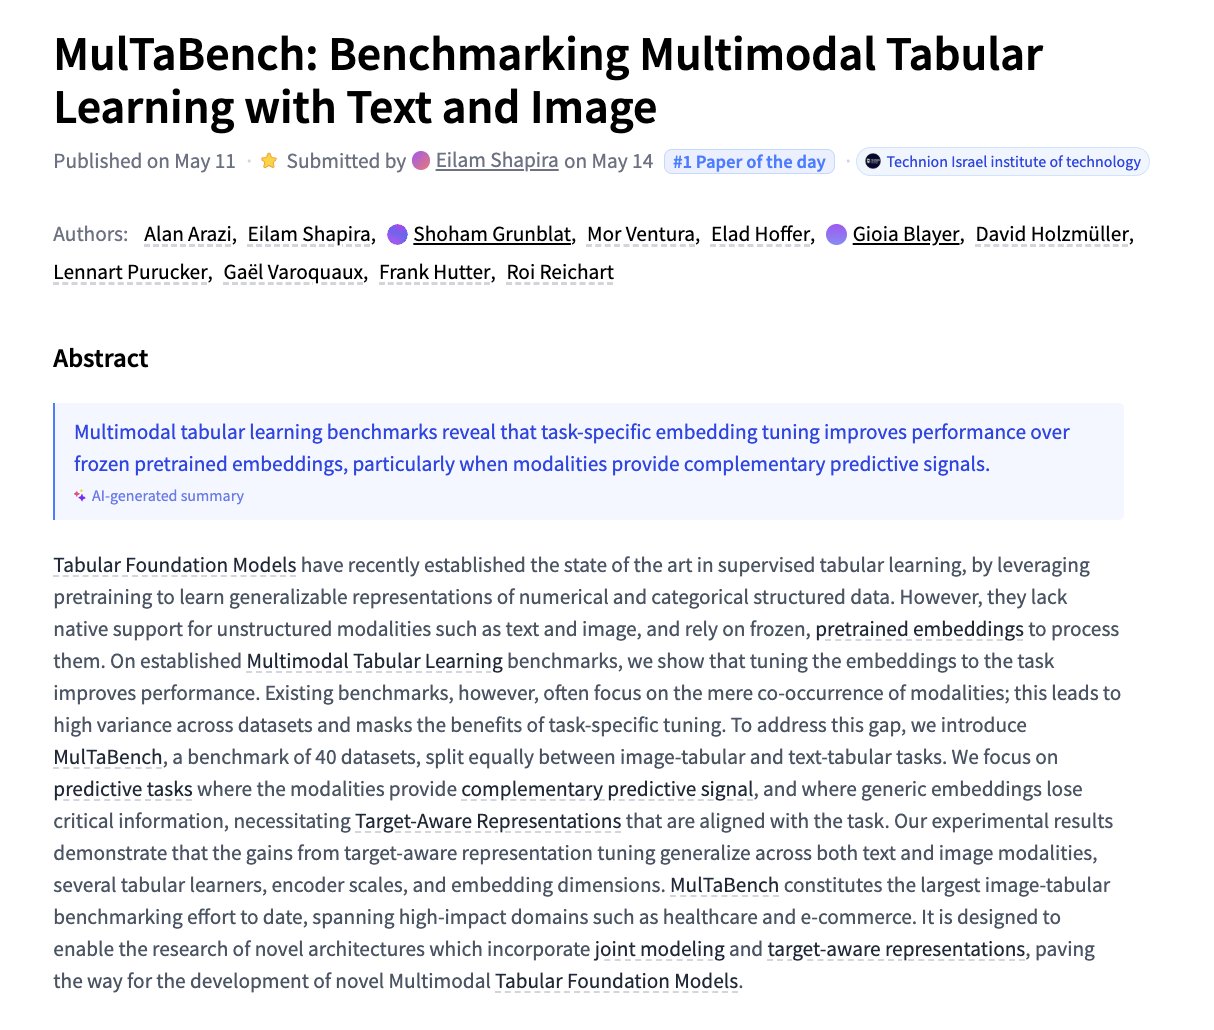
MulTaBench Benchmarking Multimodal Tabular Learning with Text and Image