Transiting the habitation ring (gpt-image-1 > PixVerse v4) https://t.co/EYtmIltvVh pic.twitter.com/OVD7GkLcmx
— fofr (@fofrAI) 11 mai 2025
Transiting the habitation ring (gpt-image-1 > PixVerse v4)
By
–
Transiting the habitation ring (gpt-image-1 > PixVerse v4) https://t.co/EYtmIltvVh pic.twitter.com/OVD7GkLcmx
— fofr (@fofrAI) 11 mai 2025
Transiting the habitation ring (gpt-image-1 > PixVerse v4)

By
–
On Path to Multimodal Generalist: General-Level and General-Bench Fei et al.: https://
arxiv.org/abs/2505.04620 #ArtificialIntelligence #DeepLearning #MachineLearning

By
–
[ α‑AGI Business ] Example Scenario: — Personal Michelin-level meal studio " Real-time taste-profiling → auto-conjures bespoke recipes, orders local farm inputs, schedules drone delivery & adjusts macros after each bite. Dinner goes from idea →

By
–
3/ Open a new chat. Upload your logo/product/image. Use prompt:
Generate an image of my [LOGO/PRODUCT/ETC.] with the following JSON aesthetic:
[INSERT JSON STRUCTURED PROMPT FROM BEFORE] Now you will get stunning, personalized images with consistent styling.
By
–
And the juicy part As there is a new announcement pointing to "multi-modal generation", and considering that Gemini is getting more and more tools into their "Agents" toolbox… There is a big chance that Gemini Ultra will work similarly to what GPT-5 is expected to be – a

By
–
DERNIÈRE MINUTE : Google prépare de nouveaux modèles de génération d’images et de vidéos qui seront lancés plus tard en mai. veo-3.0-generate-preview
imagen-4.0-generate-preview-05-20
imagen-4.0-ultra-generate-exp-05-20 Et quelques références de modèles en plus…
By
–
Voilà ce que l'on peut faire à partir d'une photo …
— VISION IA (@vision_ia) 10 mai 2025
100% IA (avec HeyGen Avatar IV)
Plus rien n'est réel ? pic.twitter.com/KRsQQGu73l
Voilà ce que l'on peut faire à partir d'une photo … 100% IA (avec HeyGen Avatar IV) Plus rien n'est réel ?
By
–
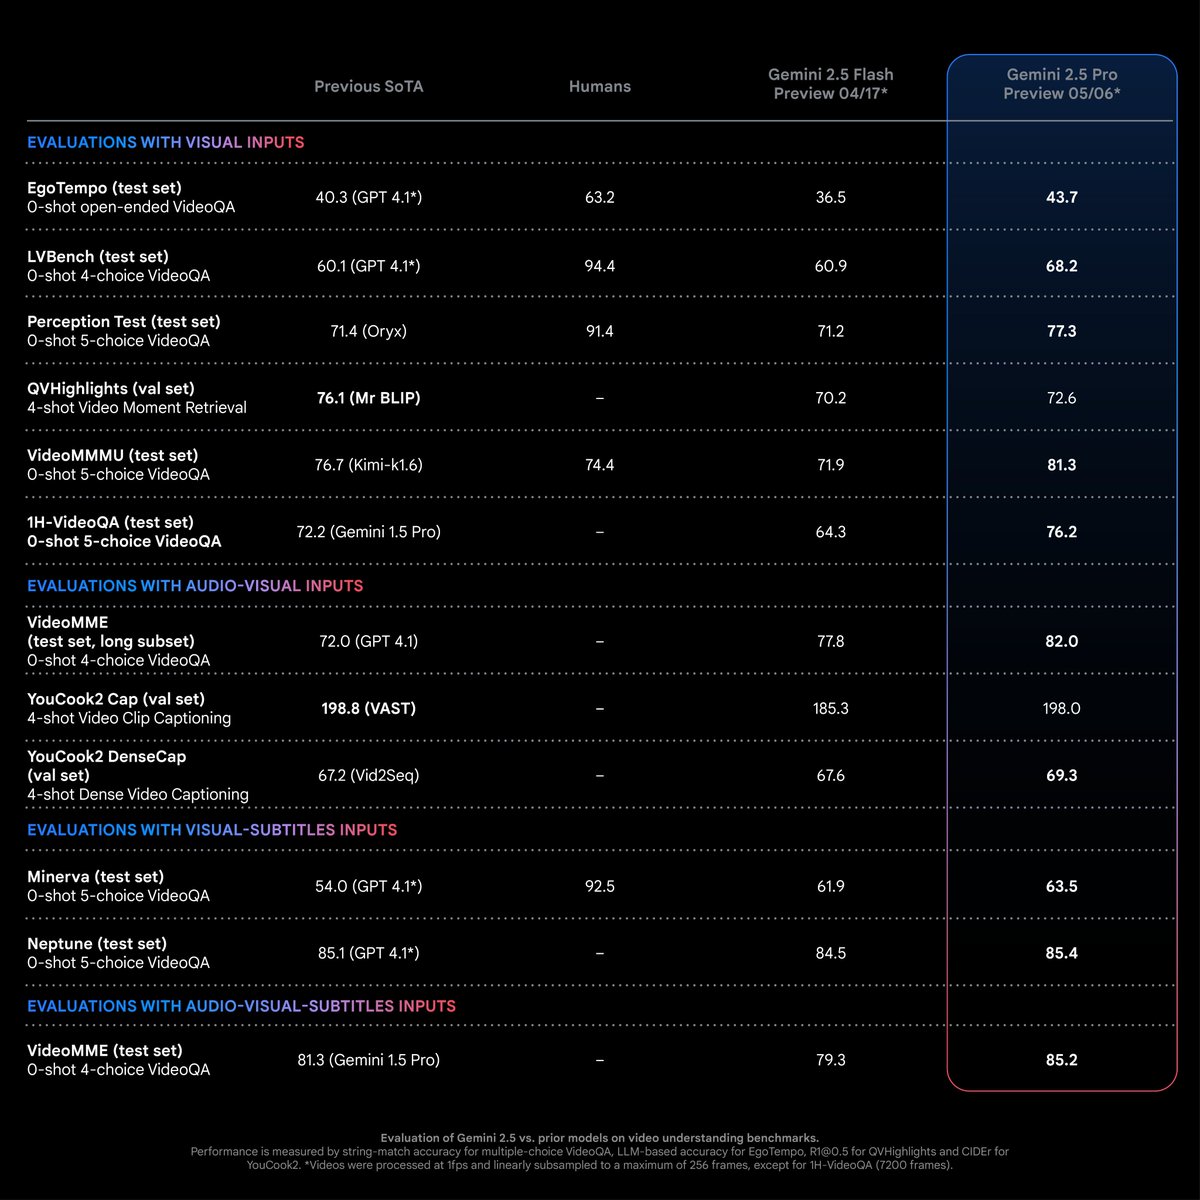
Gemini 2.5 Pro is incredible at video understanding, try posting a YouTube link into AI studio http://
ai.dev and asking it questions about the video. You will be amazed!

By
–
llama.cpp is now fully compatible with VLMs HUGE kudos to @ngxson from HF and to the @ggml_org team Here are a selection of pre-quantized models, ready to be used, from:
– @GoogleDeepMind Gemma
– @MistralAI Pixtral
– @Alibaba_Qwen VL
– @huggingface SmolVLM Give them a
By
–
It would be the same math/algorithms. The paper I shared uses a diffusion policy. Images are actions. Eg if you generate a spectrogram image, you can decode it immediately to speech. Speech acts can do a lot! We tend to imagine 1D embeddings for all modalities, but 2D