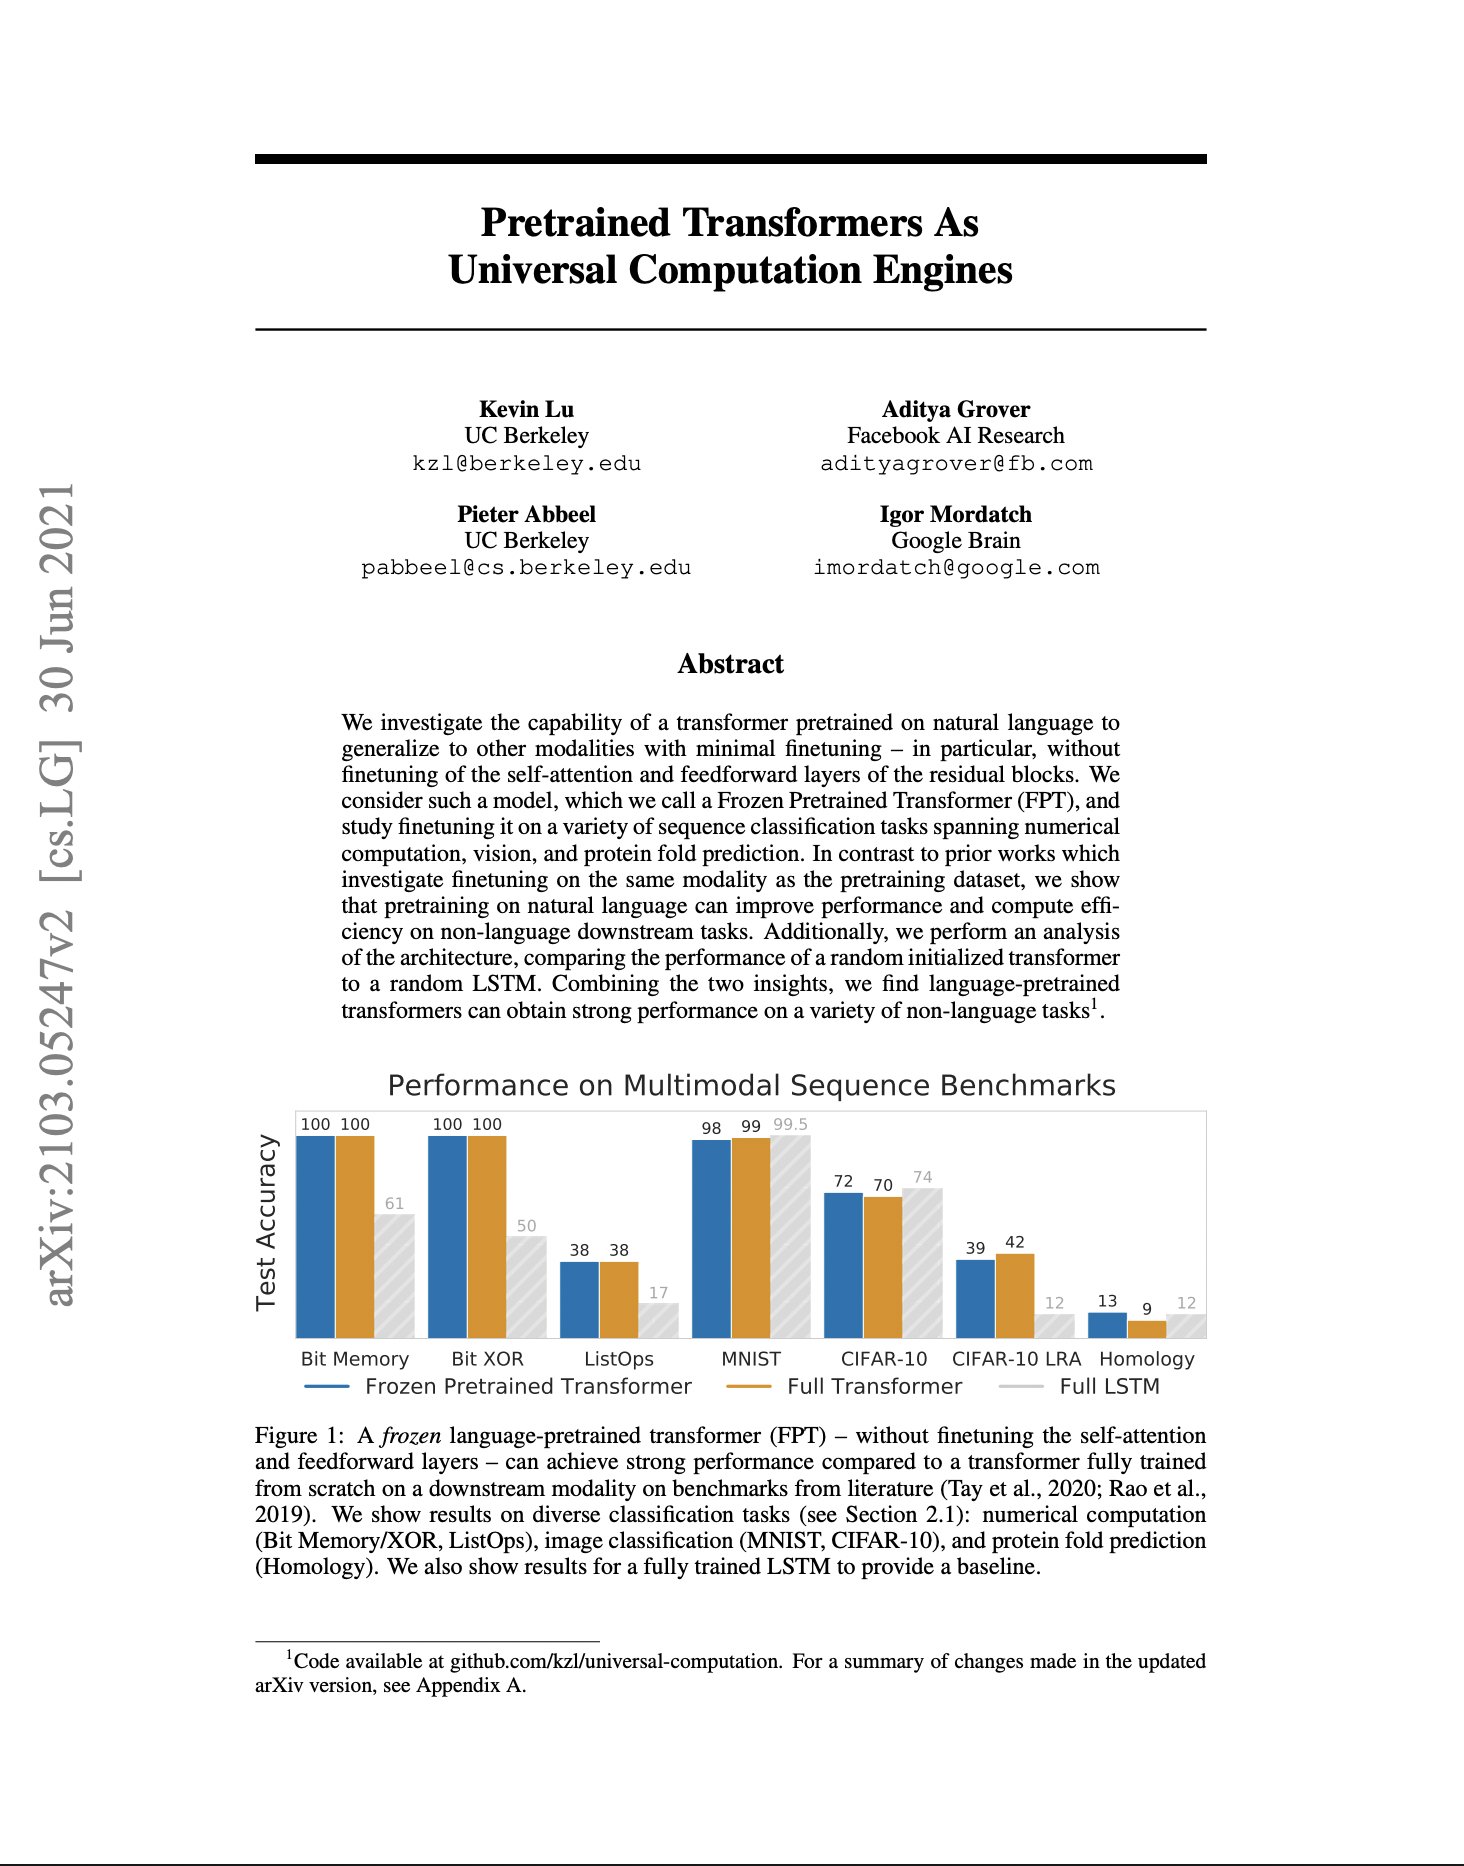
this paper blew my mind when i read it four years ago. it blew my mind again when i reread it this morning basic finding is that transformers pretrained on TEXT are also useful for IMAGES (and proteins, and numerical operations)…. i think the term "Universal Computation
MULTIMODAL AI
-
Alibaba Launches Qwen-VLo: GPT-4o-Style Image Generation AI
By
–
Alibaba dropped Qwen-VLo, a GPT-4o-style image AI
— Rowan Cheung (@rowancheung) 30 juin 2025
It shows its creative process through “progressive generation,” with text-to-image and editing via natural language.
Also supports multi-image inputs, multilingual text generation, and dynamic resolutionpic.twitter.com/bnvqIRwbniAlibaba dropped Qwen-VLo, a GPT-4o-style image AI It shows its creative process through “progressive generation,” with text-to-image and editing via natural language. Also supports multi-image inputs, multilingual text generation, and dynamic resolution
-
Google Launches Doppl AI Try-On and Gemma 3n Mobile Models
By
–
Google dropped two new products:
— Rowan Cheung (@rowancheung) 30 juin 2025
—Doppl: A new Labs experiment to create AI-generated try-on videos from a photo and a product
—Gemma 3n: New open AI models (2B and 4B options) to bring multimodality to mobilepic.twitter.com/LGvM7eWvMdGoogle dropped two new products: —Doppl: A new Labs experiment to create AI-generated try-on videos from a photo and a product
—Gemma 3n: New open AI models (2B and 4B options) to bring multimodality to mobile -

MMaDA: Multimodal Large Diffusion Language Models
By
–
MMaDA: Multimodal Large Diffusion Language Models Yang et al.: https://
arxiv.org/abs/2505.15809 #ArtificialIntelligence #DeepLearning #MachineLearning -

Training AI Models for Retro Video Game Live Action Conversion
By
–
I've tried a few trainings since in the attempt to get a more natural old video game look, but nothing has paid off, yet. For my second pass I took video game screenshots, and asked 4o to make them live action. Then switched them for training (left/start > right/end, "make it an
-
PEVA: Egocentric Video Prediction from 3D Body Motion
By
–
10. Whole-Body Conditioned Egocentric Video Prediction
— DAIR.AI (@dair_ai) 29 juin 2025
This paper introduces PEVA, a conditional diffusion transformer that predicts egocentric video conditioned on 3D human body motion.https://t.co/CnDXcQHUqy10. Whole-Body Conditioned Egocentric Prediction This paper introduces PEVA, a conditional diffusion transformer that predicts egocentric video conditioned on 3D human body motion.
-
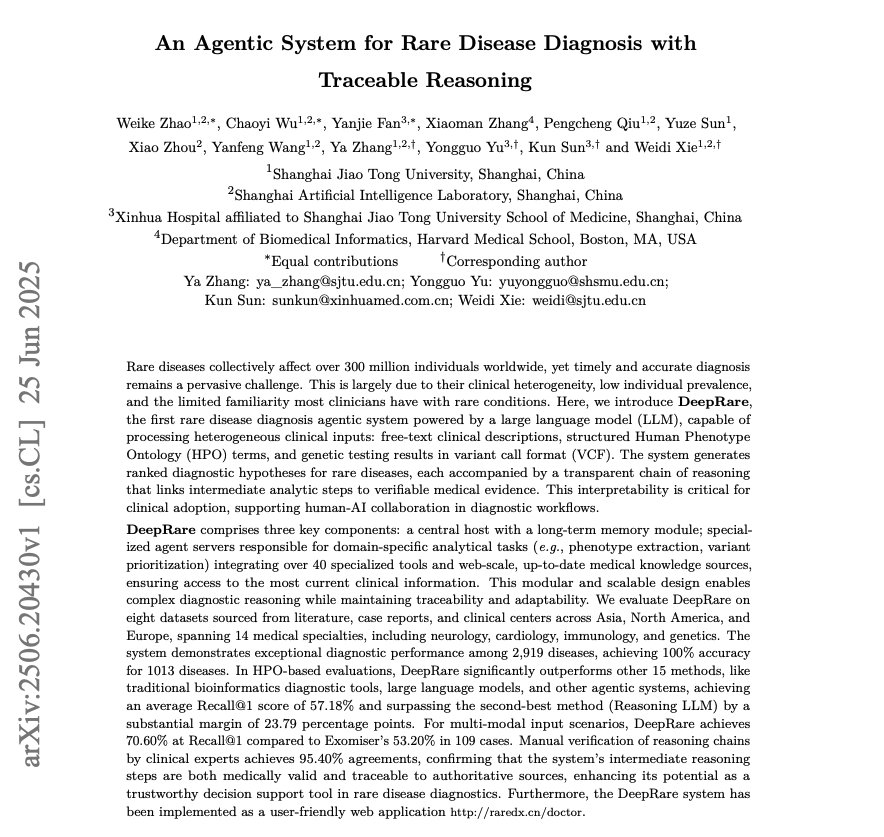
DeepRare: LLM Agentic System for Rare Disease Diagnosis
By
–
5. DeepRare Introduces DeepRare, a modular agentic system powered by LLMs to aid rare disease diagnosis from multimodal clinical inputs (text, HPO terms, VCFs).
-
Ghibli-Style AI Video Transformation Now Becoming Possible
By
–
Vous vous souvenez de la tendance où l'on transformait nos photos en dessins Ghibli avec ChatGPT ?
— VISION IA (@vision_ia) 29 juin 2025
Eh bien, cela commence à devenir possible aussi pour les vidéos. pic.twitter.com/GPL4BuxRa2Vous vous souvenez de la tendance où l'on transformait nos photos en dessins Ghibli avec ChatGPT ? Eh bien, cela commence à devenir possible aussi pour les vidéos.
-
AI Design Workflow From Concept to UI With Four Tools
By
–
— VISION IA (@vision_ia) 29 juin 2025
Use case for all designers who want to speed up their workflow: Reve → Midjourney → Topaz Astra → Figma
From concept to final UI in record time. All prompts are in this thread — save it for later! -
AI-Powered Landing Page Workflow: Midjourney to Figma
By
–
Exemple de landing page 100% IA
— VISION IA (@vision_ia) 29 juin 2025
Cas d’usage pour tous les designers qui veulent accélérer leur workflow :
Midjourney → Topaz Astra → Figma
Du concept à l’interface finale en un temps record.
Credit : @Kerroudjm pic.twitter.com/9bLZwQSvlxExemple de landing page 100% IA Cas d’usage pour tous les designers qui veulent accélérer leur workflow : Midjourney → Topaz Astra → Figma Du concept à l’interface finale en un temps record. Credit : @Kerroudjm