
Image editing models are experiencing a renaissance right now – gpt image was the only good model at some point, now it is barely in the top 10.
MULTIMODAL AI
-

Apple Unveils ATOKEN: Unified Visual Tokenizer for Multimodal Content
By
–
Apple just proposed the first unified visual tokenizer! They proposed ATOKEN which is the first tokenizer that jointly cover images, videos, and 3D assets in a single shared 4D latent/token space, matching performance with any other specialized tokenizers.
-
Gemini Robotics 1.5 Introduces Agentic Capabilities to Robots
By
–
Gemini Robotics 1.5 from @GoogleDeepMind marks the official introduction of agentic capabilities to robots, allowing them to complete complex, multi-step tasks.
— Google AI (@GoogleAI) 25 septembre 2025
But… what does that mean? 🧐
Before, robots were able to accomplish a single task, like picking up fruit or zipping… pic.twitter.com/pgmNO3gCUqGemini Robotics 1.5 from @GoogleDeepMind marks the official introduction of agentic capabilities to robots, allowing them to complete complex, multi-step tasks. But… what does that mean? Before, robots were able to accomplish a single task, like picking up fruit or zipping
-

Google’s 90% AI Developer Adoption and Latest Breakthroughs
By
–
Top stories in AI today: – Google reveals 90% AI adoption for devs
– AI clears toughest CFA exam in minutes
– Make pixel-perfect website changes with AI
– MIT’s AI designs quantum materials
– 4 new AI tools, community workflows, and more Read more: https://
therundown.ai/p/90-of-devs-n
ow-use-ai-but-dont-trust-it
… -

Kling 2.5 Turbo Delivers Extremely Realistic Video Generation
By
–
Kling 2.5 Turbo is extremely realistic, I do this at all of my talks pic.twitter.com/1CJ6215pVk
— Peter Gostev (@petergostev) 24 septembre 2025Kling 2.5 Turbo is extremely realistic, I do this at all of my talks
-

Qwen3-Coder Plus API Upgraded with Enhanced Features
By
–
Qwen3-Coder upgraded! New Qwen3-coder-plus API on @alibaba_cloud Model Studio: Better terminal tasks (aces Terminal Bench) SWE-Bench score hits 69.6 Safer code generation
Qwen Code now supports images & sub-agents!
#Chat #API #Code #AI #Coding @Alibaba_Qwen -
Google Search Live: Voice Conversation with AI Camera Vision
By
–
Today, Search Live is available in English in the U.S. — no Labs opt-in required. ✨ You can now have a free-flowing, back-and-forth conversation with Search using your voice and phone camera.
— Google AI (@GoogleAI) 24 septembre 2025
Live in Search combines the power of Google Lens and AI Mode to see and accurately… pic.twitter.com/SXtLxunsC7Today, Search Live is available in English in the U.S. — no Labs opt-in required. You can now have a free-flowing, back-and-forth conversation with Search using your voice and phone camera. Live in Search combines the power of Google Lens and AI Mode to see and accurately
-
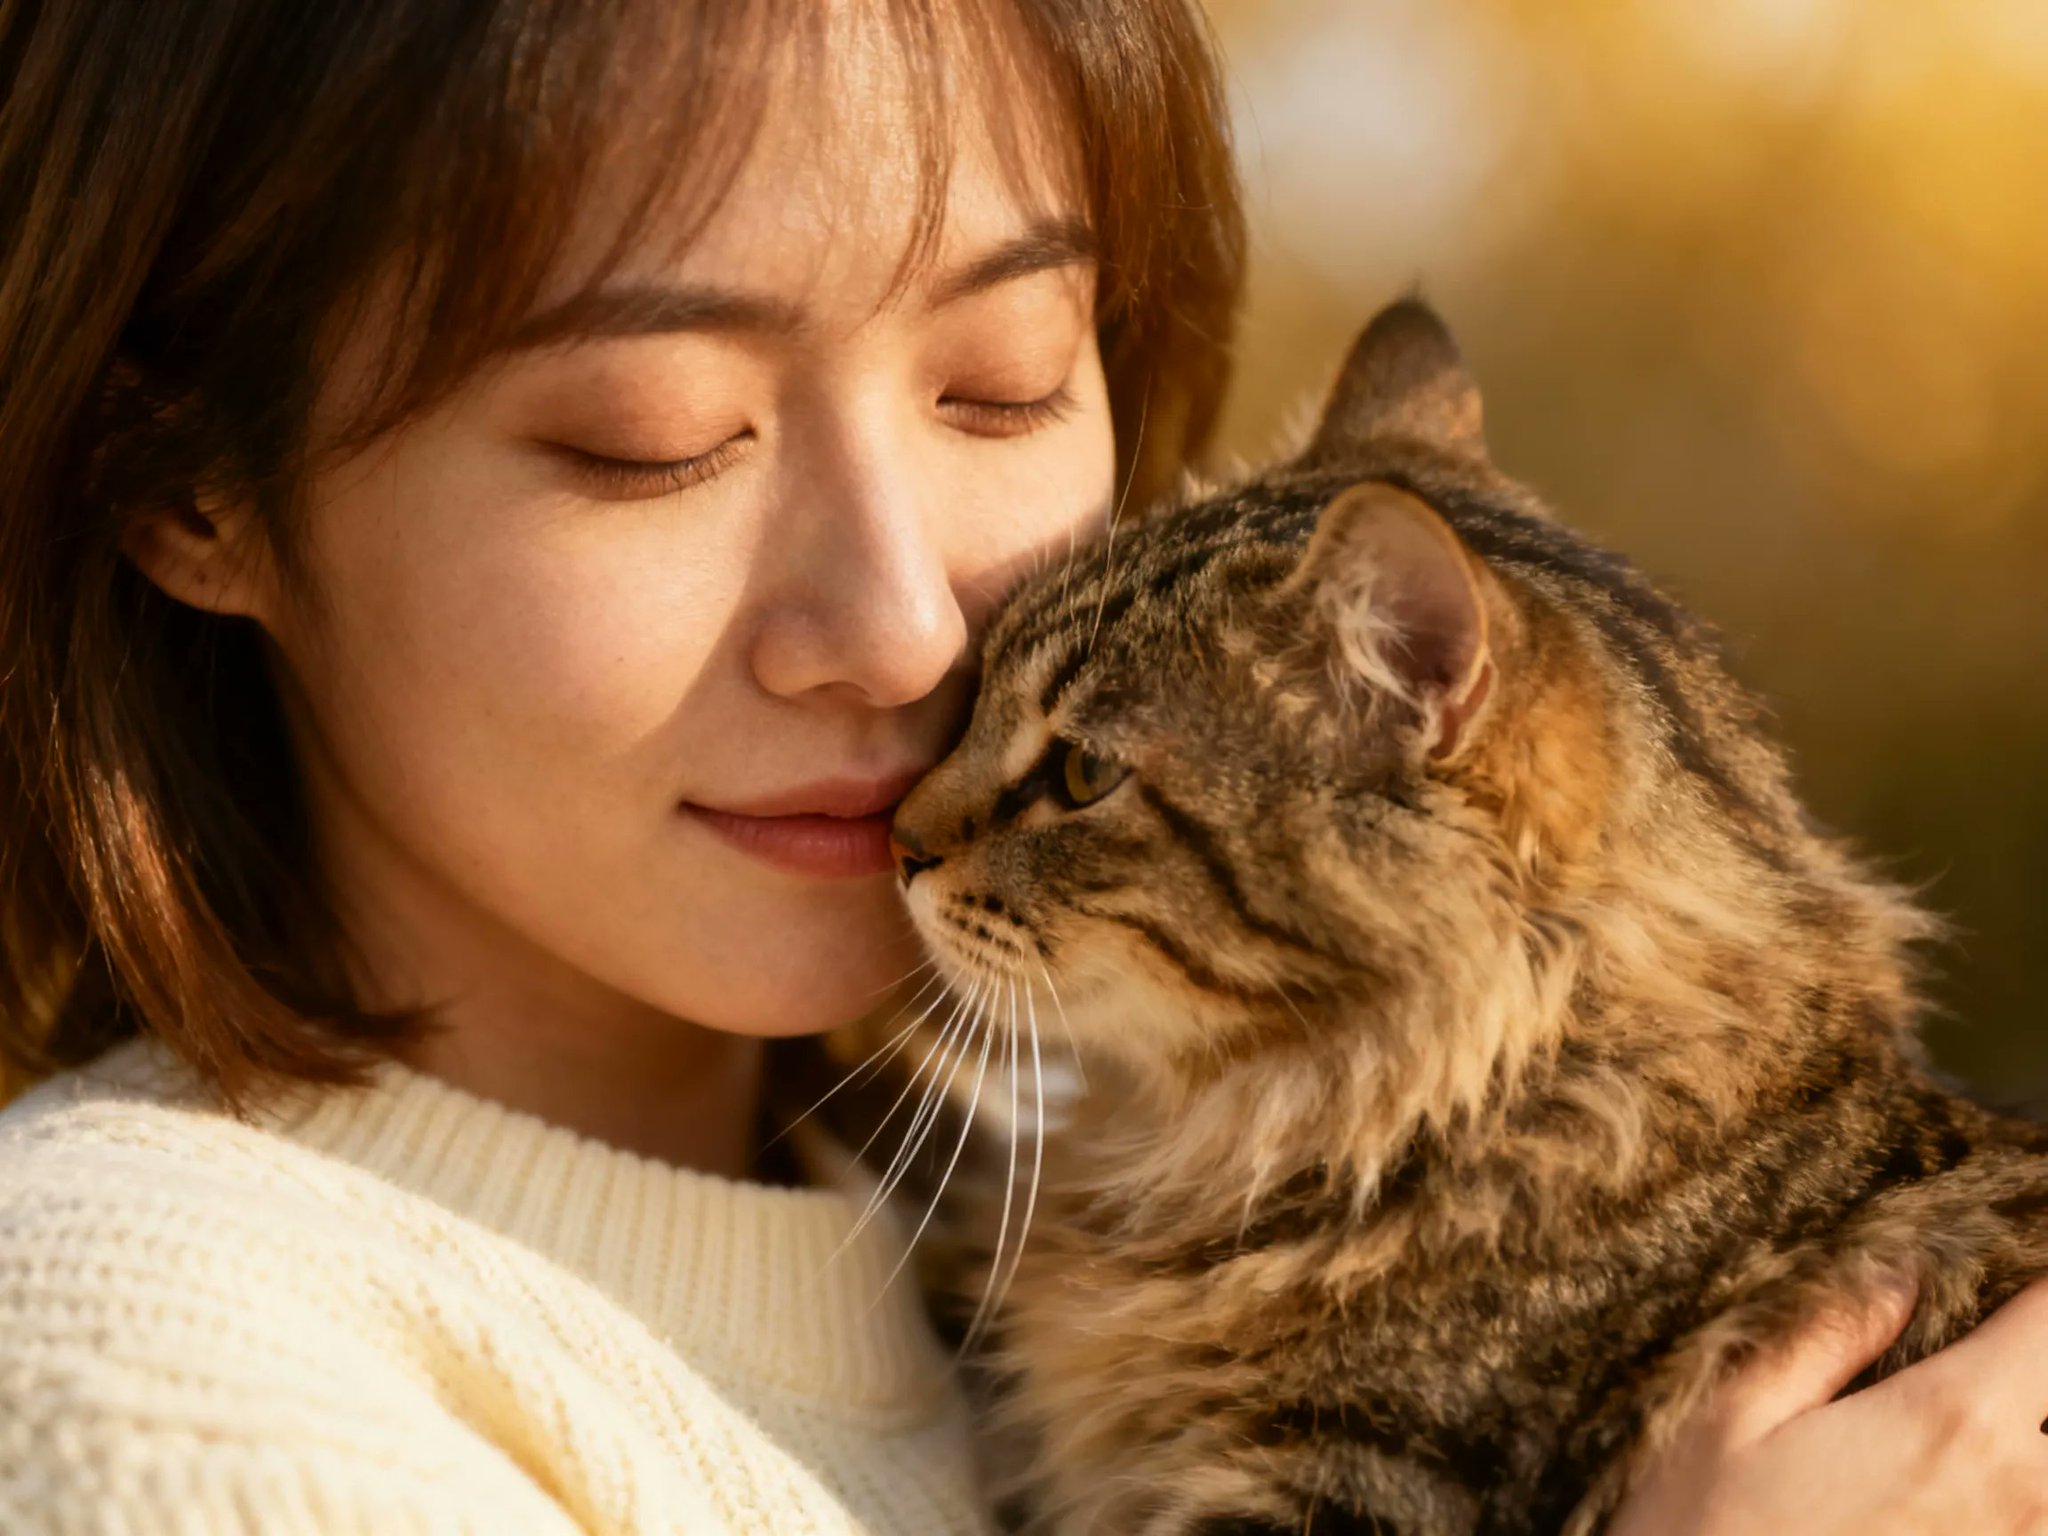
Style Transfer: Transform an Image into an Oil Painting
By
–
Task 5: Style transfer > "Make this into an oil painting" Winner: Nano Banana
-
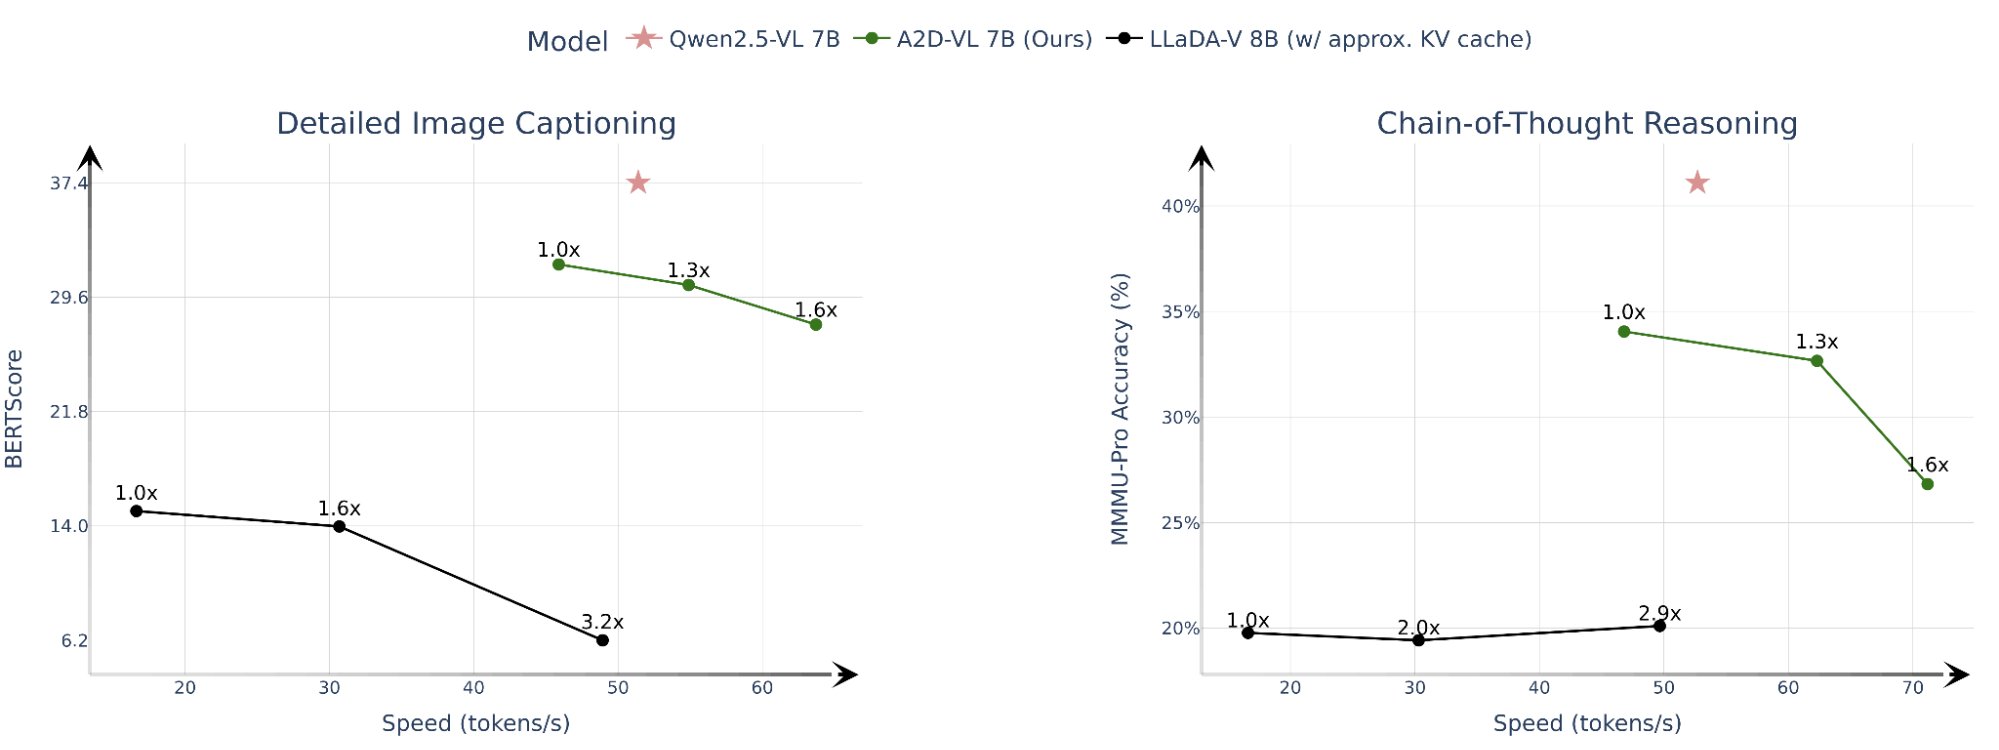
A2D-VL Diffusion Model Outperforms VLMs with Efficient Training
By
–
A2D-VL outperforms prior diffusion VLMs in visual question-answering while requiring significantly less training compute. Our novel adaptation techniques are critical for retaining model capabilities, finally enabling the conversion of state-of-the-art autoregressive VLMs to
-
Runway advances autoregressive-to-diffusion multimodal AI models
By
–
This work is a step towards our goal of unifying multimodal understanding and generation in order to build multimodal simulators of the world. Learn more: https://
runwayml.com/research/autor
egressive-to-diffusion-vlms
…