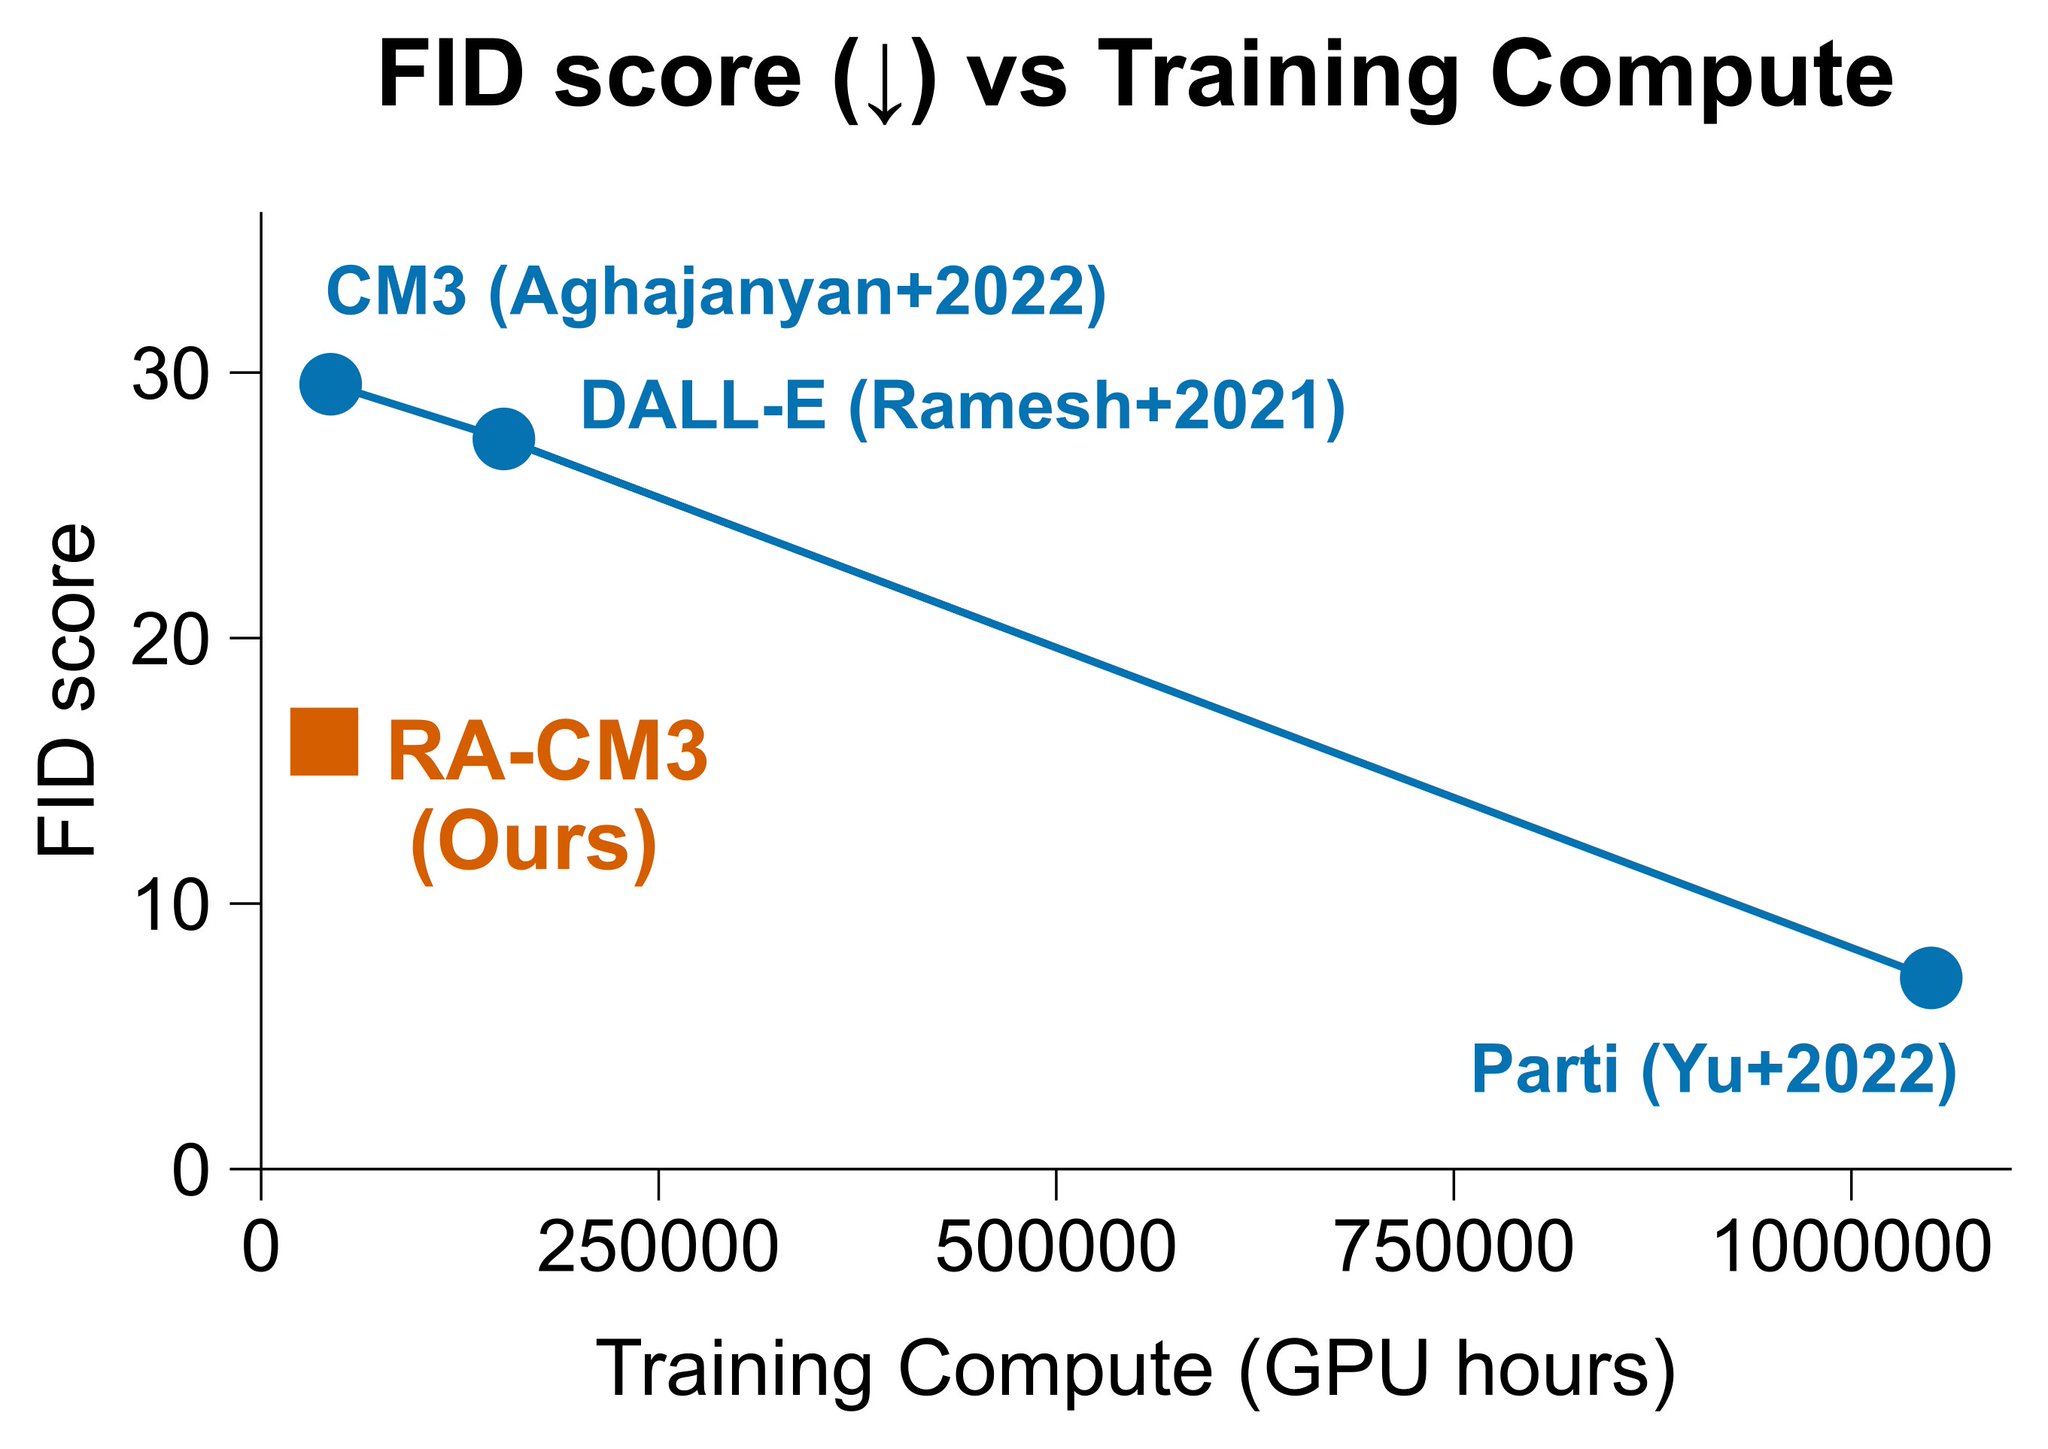
The RA-CM3 model significantly outperforms baseline multimodal models on both image & caption generation tasks, while using <30% of the compute of comparable models & exhibiting novel capabilities like knowledge-intensive image generation & multimodal in-context learning. 2/4
MULTIMODAL AI
-
Meta AI Introduces RA-CM3: Multimodal Model for Text and Image Generation
By
–
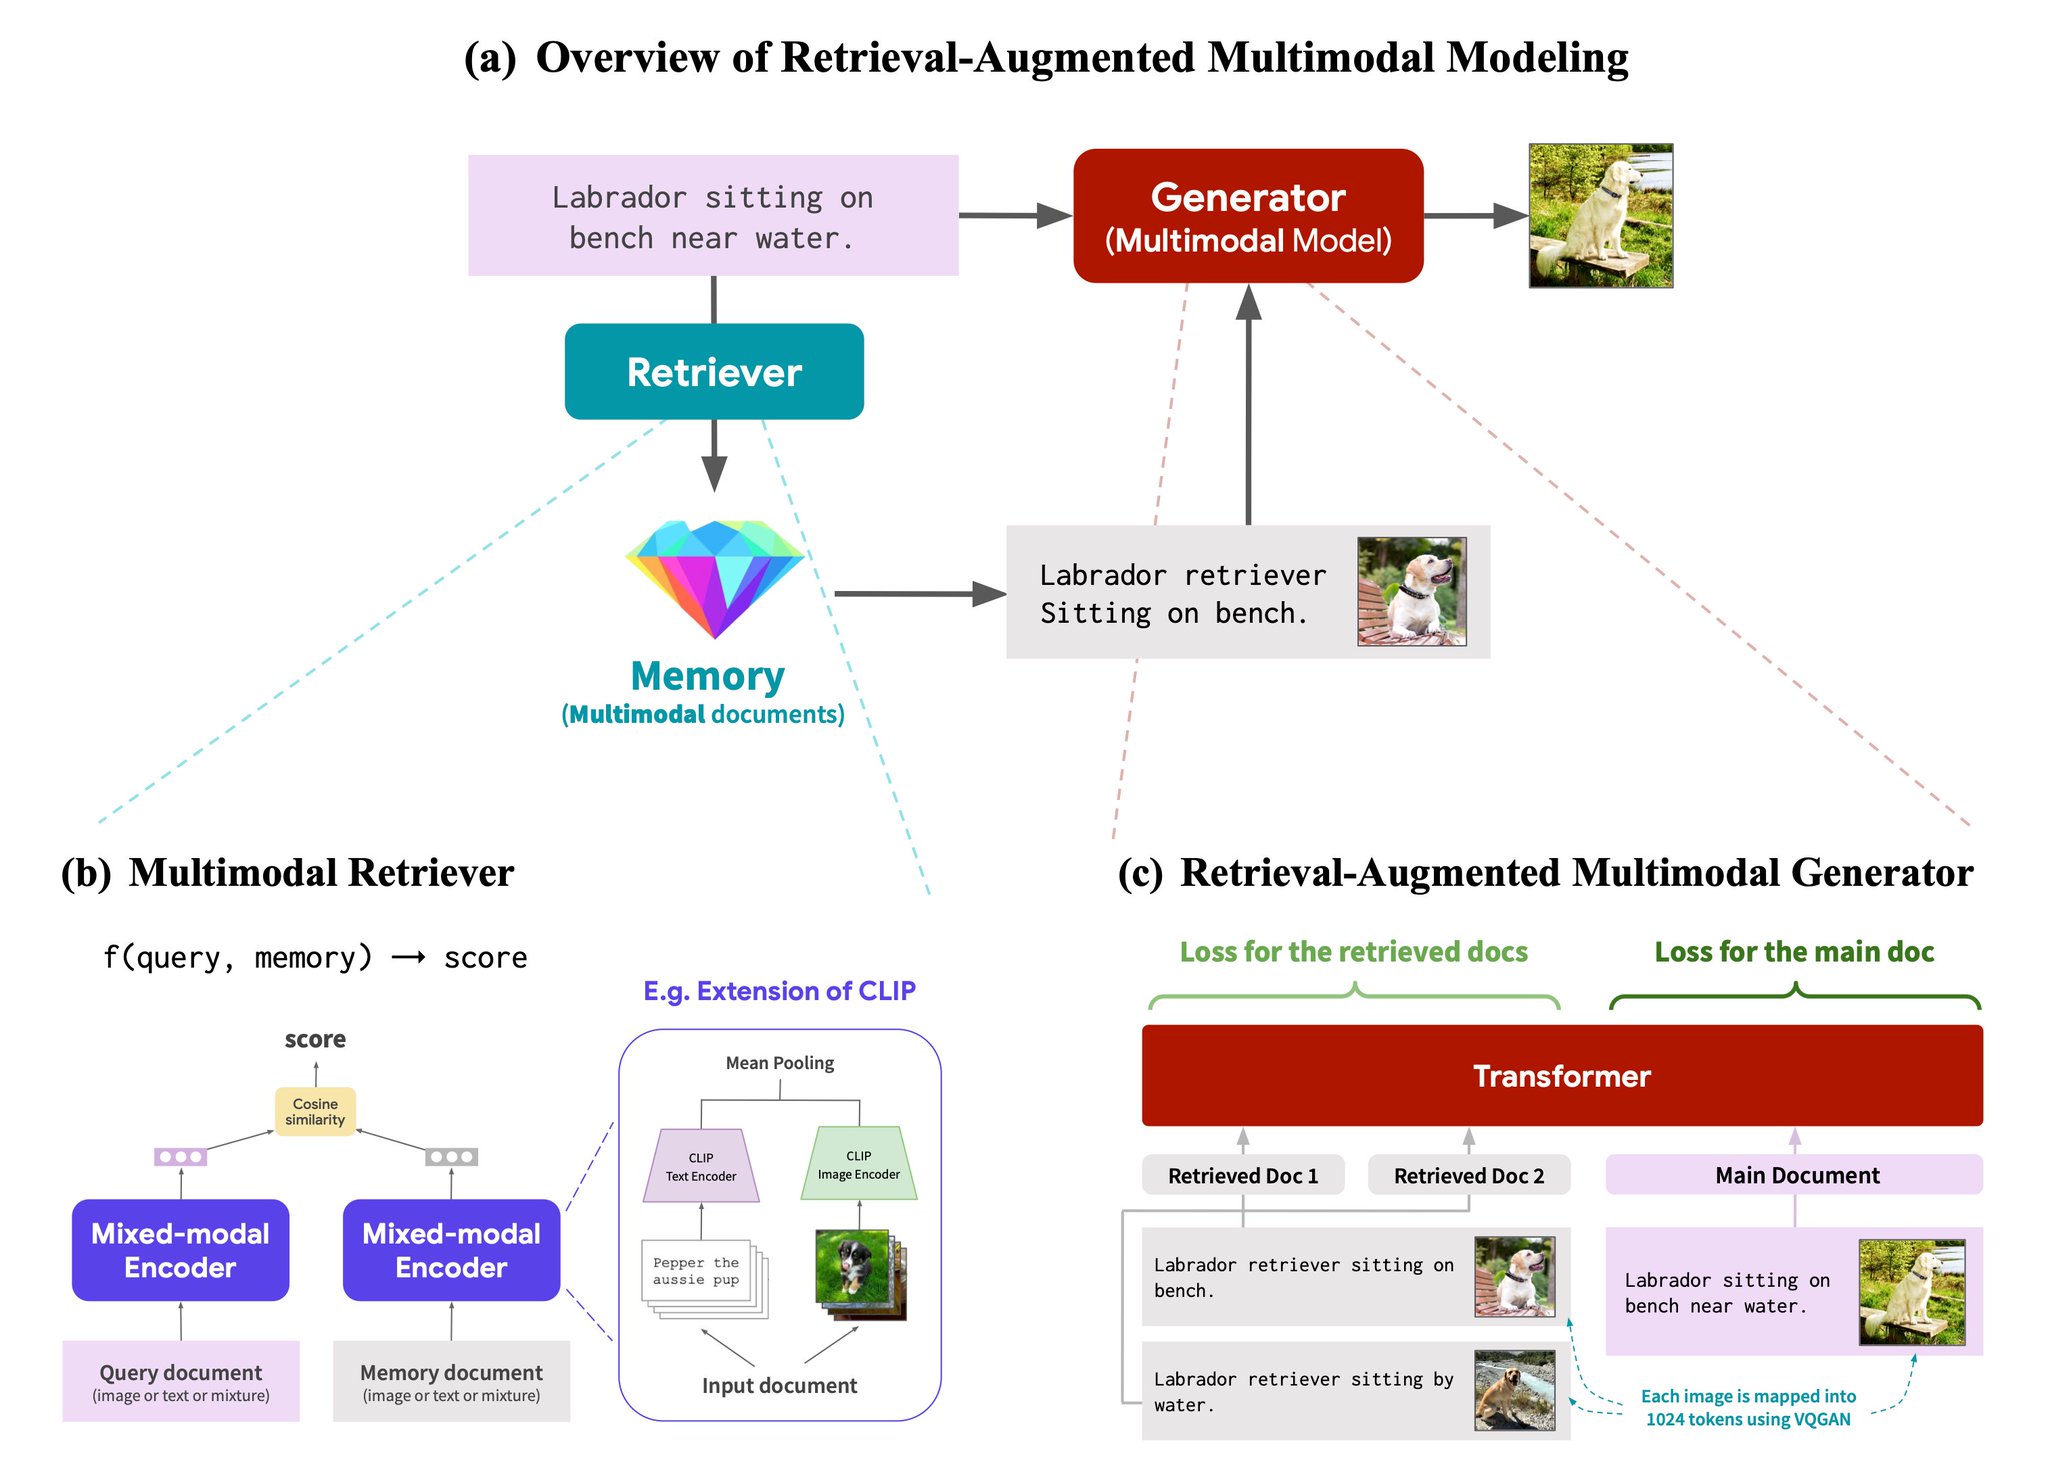
New paper from our team at Meta AI. Retrieval-Augmented CM3 (RA-CM3) is the first multimodal model that can retrieve and generate mixtures of text and images — while also reducing training cost and model size. Now available on arXiv https://
arxiv.org/abs/2211.12561 1/4 -
Interactive Language Framework Enables Real-Time Language-Conditionable Robots
By
–
Interactive Language is an imitation learning framework for producing real-time, open vocabulary language-conditionable robots. Learn more and check out the newly released and largest available language-annotated robot dataset, called Language-Table → https://t.co/ZdQCeYEFJl pic.twitter.com/5zMyoa9B57
— Google AI (@GoogleAI) 1 décembre 2022Interactive Language is an imitation learning framework for producing real-time, open vocabulary language-conditionable robots. Learn more and check out the newly released and largest available language-annotated robot dataset, called Language-Table → http://
bit.ly/3Umujjt -
Image Description Loop Creates Diffusion Noise Effect
By
–
Now ask it to describe the image and repeat. In a few iterations it will produce pure noise, and you can call it diffusion.
-
Google Phenaki: Text-to-Video Generation Breakthrough Presentation
By
–
Today at 3:30 pm @RubenEVillegas and @piekindermans will be at the Google booth to describe how the Phenaki model overcomes the challenges of text-to-video generation to synthesize realistic videos from text prompts. More at: https://t.co/B2OdMk8l2S pic.twitter.com/f0KohBFnbF
— Google AI (@GoogleAI) 30 novembre 2022Today at 3:30 pm @RubenEVillegas and @piekindermans will be at the Google booth to describe how the Phenaki model overcomes the challenges of text-to-video generation to synthesize realistic videos from text prompts. More at: https://
phenaki.research.google -
Language Interfaces: The Future of Human-Computer Interaction
By
–
language interfaces are going to be a big deal, i think. talk to the computer (voice or text) and get what you want, for increasingly complex definitions of "want"! this is an early demo of what's possible (still a lot of limitations–it's very much a research release).
-

AI Detection Engine Identifies Earth’s Longest Cow
By
–
Breaking news: an AI-powered detection engine has identified the longest cow on earth >> Without context, data is just misleading! Do you agree? Credit: Ralph Aboujaoude Diaz
#technology #artificialintelligence #computervision #ai #data #ml #machinelearning -
Vision as Controlled Hallucination: Diffusion and Predictive Coding
By
–
Vision is controlled hallucination. Therefore it can be solved by combining diffusion with predictive coding.
-
TorchMultimodal: PyTorch Library for Multimodal Multi-Task Models
By
–
TorchMultimodal is a @PyTorch library for training state-of-the-art multimodal multi-task models at scale. You can learn more and get started here https://
bit.ly/3XalYlA 6/6 -

AI Transforms Child Drawings Into Realistic Images
By
–
Bring a child's drawing to life in this demo. By teaching AI to work effectively with this quintessential human form of creativity, we hope this project will move us closer to building AI that can understand the world from a human PoV https://
sketch.metademolab.com 4/6