No not the opposite – they just looked at a particular subsets of tasks, datasets, and metrics. There are some things that LoRA is sufficient for.
MACHINE LEARNING
-
TMLR Celebrates Peer Review Community for AI Research
By
–
Finally, a big thank you to our advisory board, our first managing editor @fpedregosa
, the 1000s of reviewers and 100s of action editors for TMLR, who share our belief in scientific peer review for AI research. Witnessing so many people work with us has been truly heartwarming. -
Conferences Partner on Journal-to-Conference Track Model
By
–
We partnered with many conferences (AutoML, CoLLAs, RLC, MLRC, LoG) and now also partner with the NeurIPS/ICML/ICLR journal-to-conference track. I personally believe separating publishing from conference presentation is promising for the future of scientific dissemination in AI.
-
TMLR Scales Publishing Innovation in Machine Learning Research
By
–
TMLR went from publishing less than 200 papers in 2022 to over 1300 in 2025. And along the way we've experimented with various innovations, such as certifications, the Expert Reviewer status and the infinite conference: https://
tmlr.infinite-conf.org/index.html -
Innovative Publishing Approach for AI Research and Evidence
By
–
We've been motivated by an ambition to propose an innovative approach to publishing in AI, highlighting the prime importance of claims and evidence in assessing scientific work. Looking back, we've accomplished a lot!
-

TMLR Leadership Transition Announced New Editorial Team
By
–
A little under 4 years ago, @RaiaHadsell
, @kchonyc and I launched TMLR. I am SO proud of what we've achieved since then, and I'm particularly happy to leave TMLR to a remarkable team of EICs, with @thegautamkamath
, @NailaMurray
, Nihar B. Shah and @lcharlin . -
Base Models Trained on CoT Data: Finding the Silver Lining
By
–
Yeah, there is a silver lining. But I think it gets a bit muddled since most base models are trained on CoT data.
-
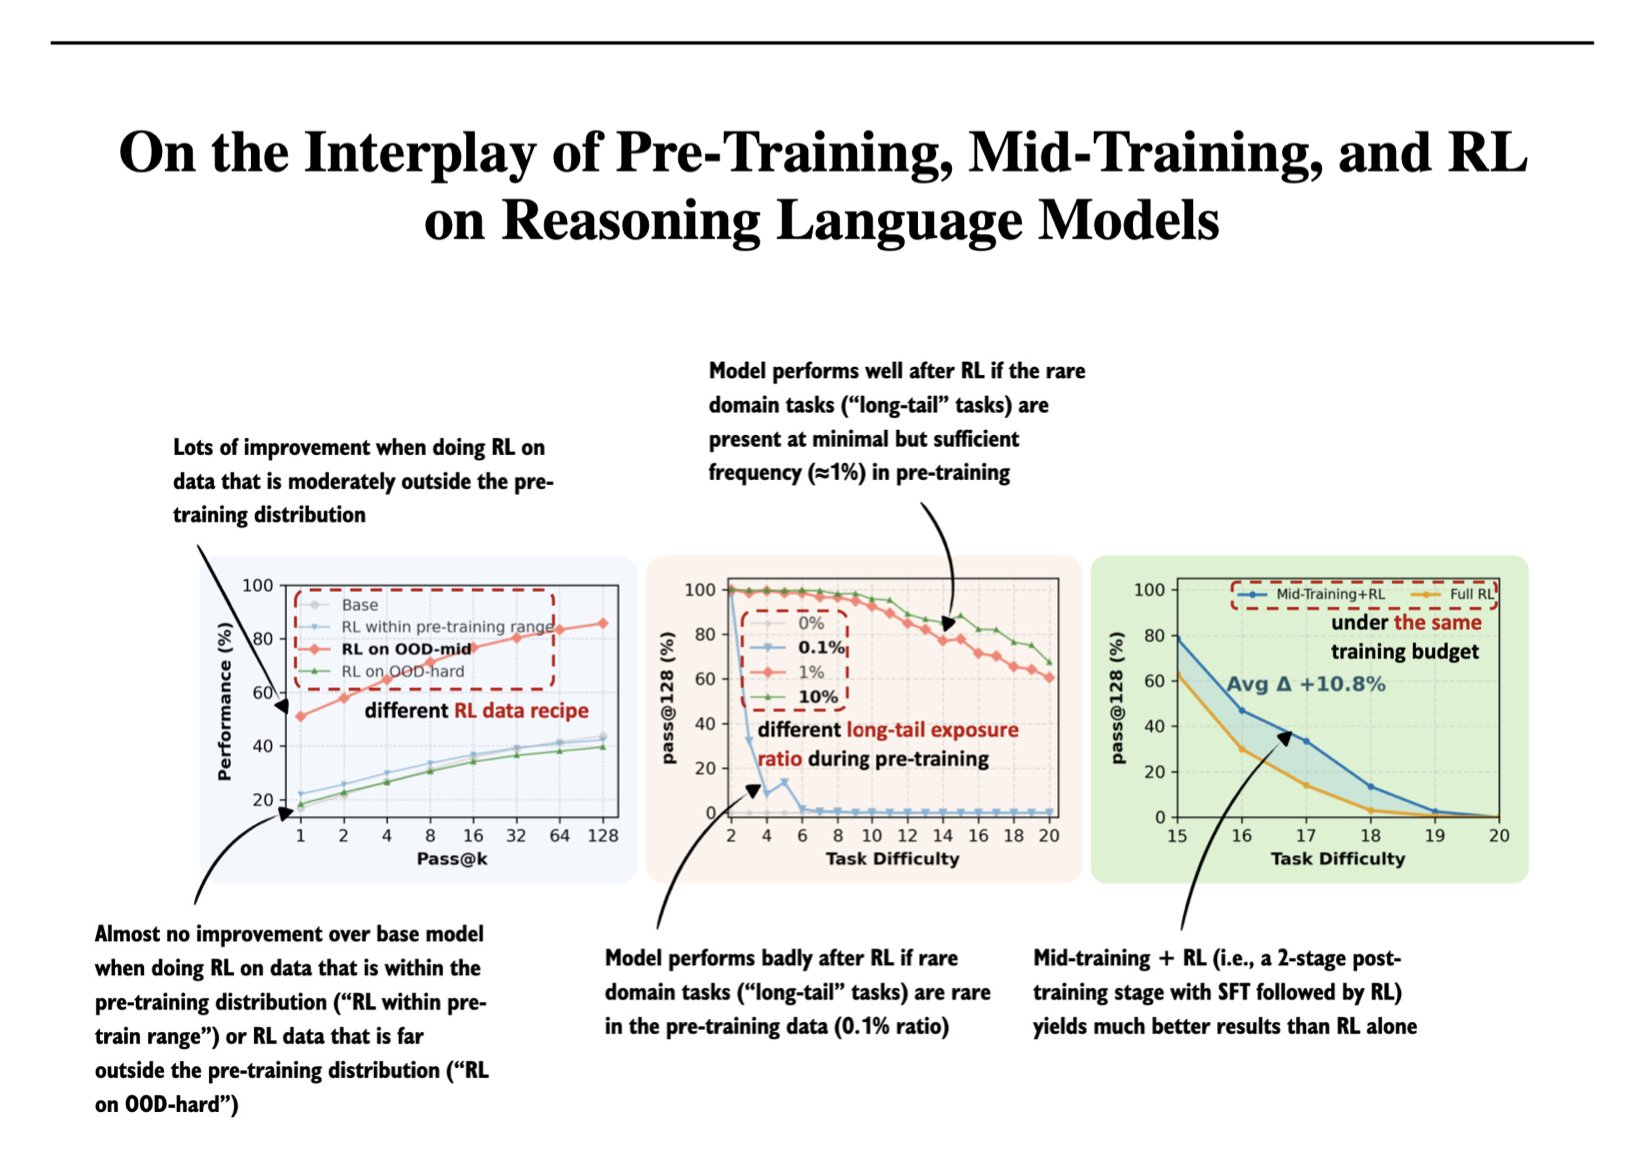
Optimal RL Balance in Training Reasoning Models
By
–
Another really interesting paper from my 2025 bookmarked papers: On the Interplay of Pre-Training, Mid-Training, and RL on Reasoning Language Models (https://arxiv.org/abs/2512.07783). In short, RL is most effective when applied to data that is neither too close to nor too far from the
-

FlowBlending: Stage-Aware Multi-Model Sampling for Video Generation
By
–
FlowBlending Stage-Aware Multi-Model Sampling for Fast and High-Fidelity Generation
-

Dream2Flow: Video Generation with 3D Object Flow for Manipulation
By
–
Dream2Flow
— AK (@_akhaliq) 2 janvier 2026
Bridging Video Generation and Open-World Manipulation with 3D Object Flow pic.twitter.com/5m09xRzjG0Dream2Flow Bridging Generation and Open-World Manipulation with 3D Object Flow