Learning from Trials and Errors Reflective Test-Time Planning for Embodied LLMs
MACHINE LEARNING
-
Query-Focused Memory-Aware Reranker for Long Context
By
–
Query-focused and Memory-aware Reranker for Long Context Processing
-
Data Engineering for Scaling LLM Terminal Capabilities
By
–
On Data Engineering for Scaling LLM Terminal Capabilities
-
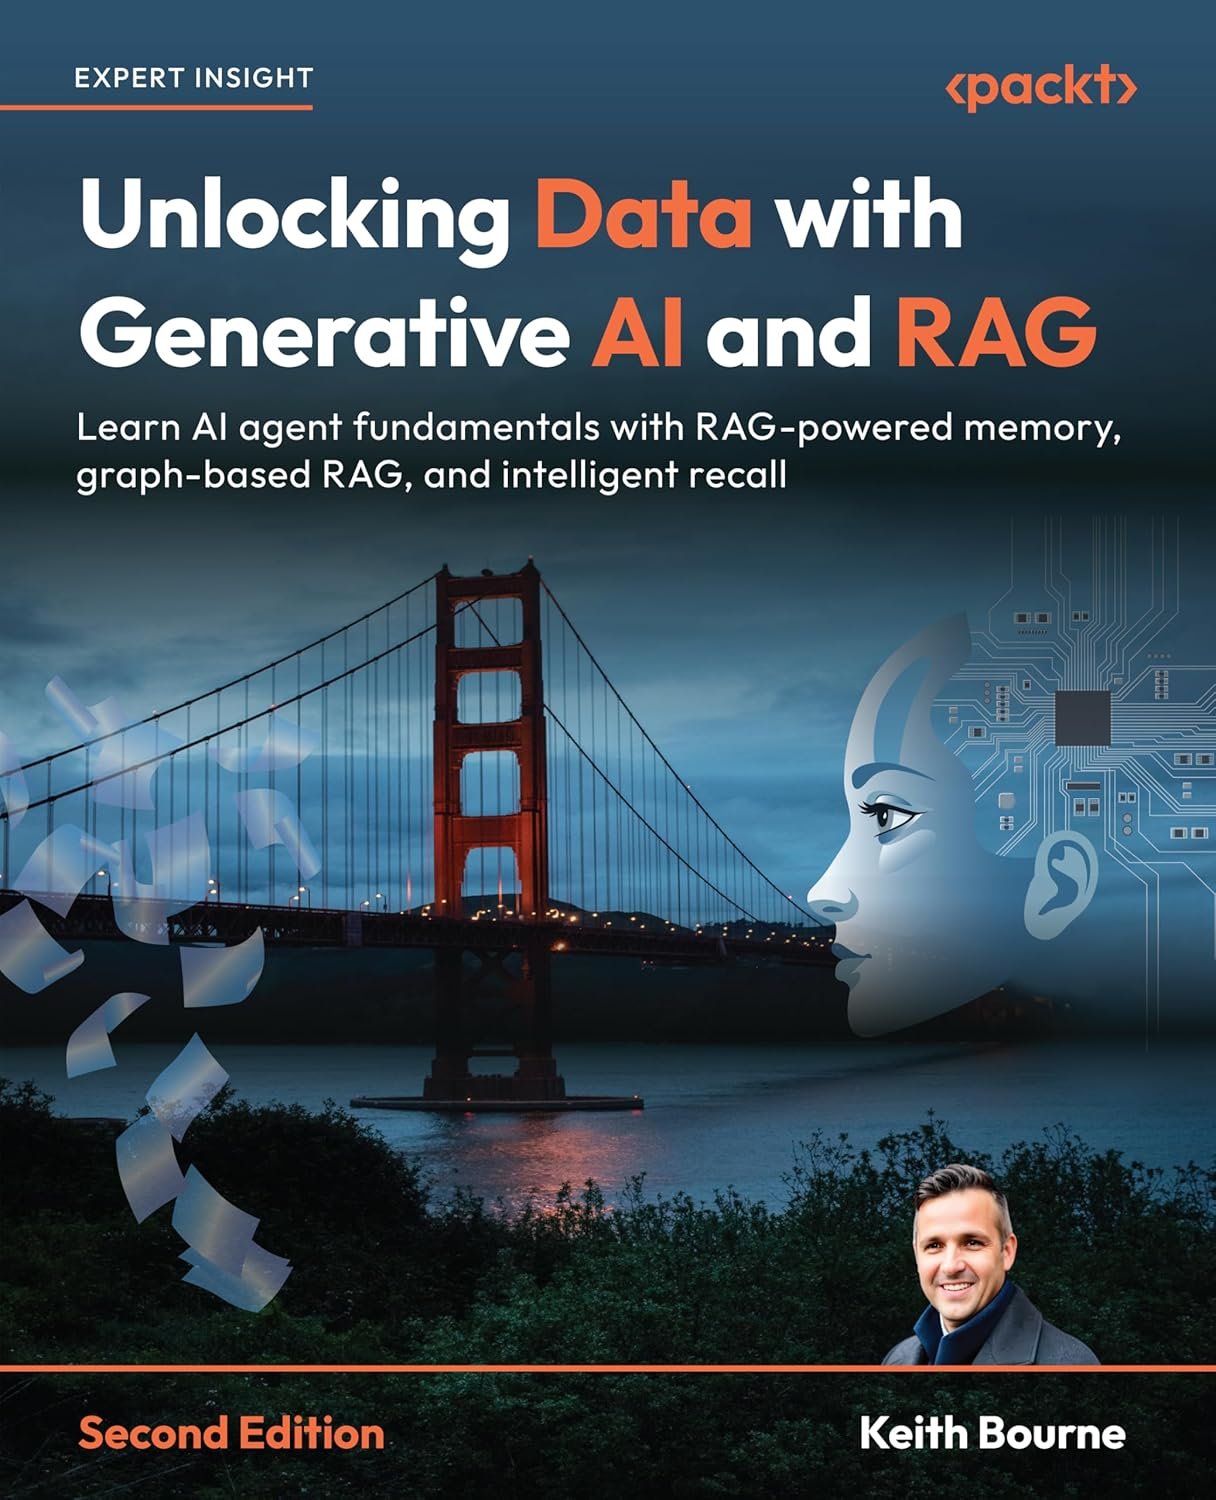
New Edition: Learn Generative AI, RAG, and AI Agents
By
–
New updated 2nd Edition, by @keithbourne v/ @PacktDataML "Unlocking Data with Generative AI and RAG — Learn AI Agent Fundamentals with RAG-powered Memory, Graph-based RAG, and Intelligent Recall" Get the book here: http://
amzn.to/49zsIkb -
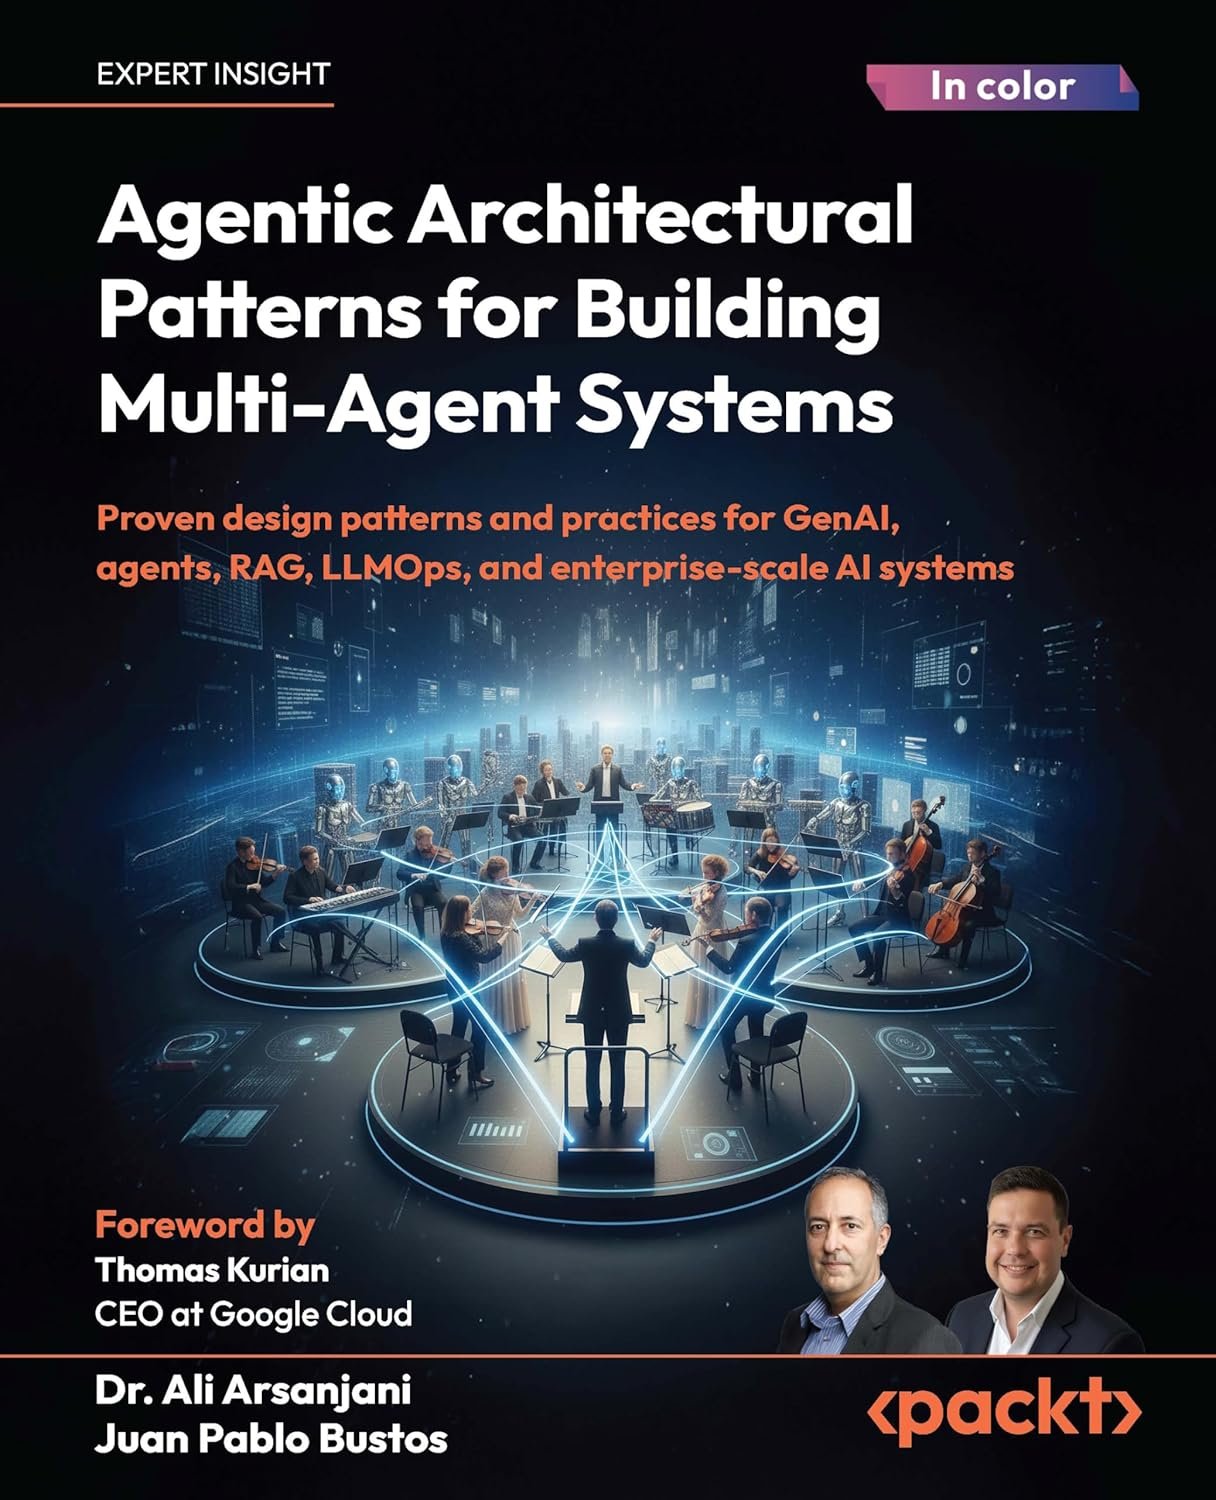
New book: Agentic Architectural Patterns for Multi-Agent AI Systems
By
–
New release from @PacktDataML @PacktPublishing at http://
amzn.to/3MaHy8T "Agentic Architectural Patterns for Building Multi-Agent Systems: Proven design patterns and practices for GenAI, agents, RAG, LLMOps, and enterprise-scale AI systems" 𝕋𝕒𝕓𝕝𝕖 𝕠𝕗 ℂ𝕠𝕟𝕥𝕖𝕟𝕥𝕤: -
Agentic Design Patterns: Guide to Building Intelligent Systems
By
–
"Agentic Design Patterns: A Hands-On Guide to Building Intelligent Systems" Read the Online eBook from Google at https://
docs.google.com/document/d/1rs
aK53T3Lg5KoGwvf8ukOUvbELRtH-V0LnOIFDxBryE/mobilebasic?pli=1#heading=h.pxcur8v2qagu
… Buy hardcopy version at http://
amzn.to/3IyOrPx -
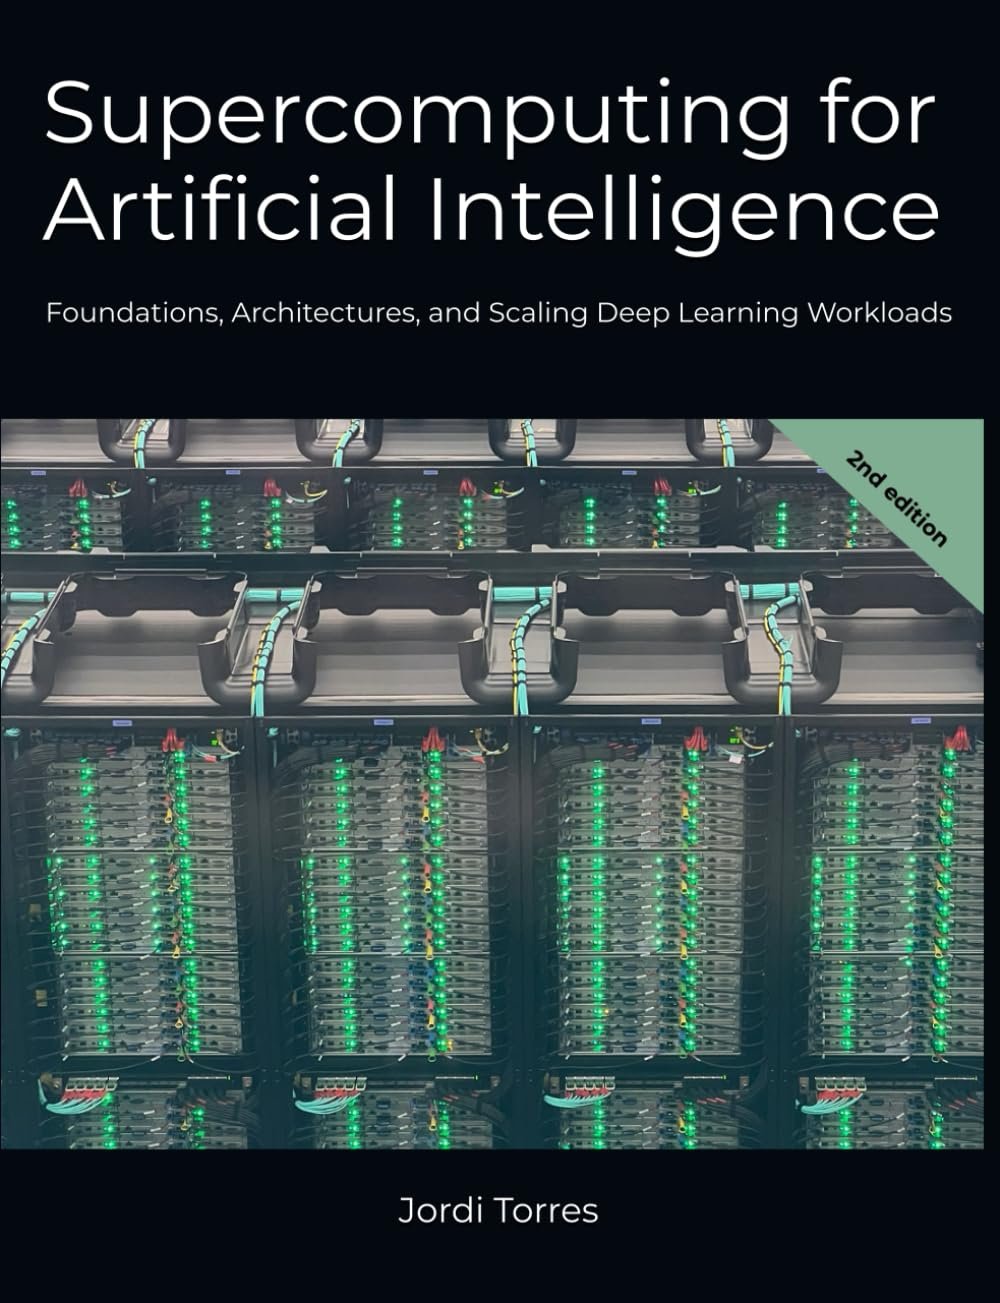
Supercomputing for AI — Foundations, Architectures, and Scaling
By
–
Supercomputing for AI — Foundations, Architectures, and Scaling Deep Learning. [804-page masterpiece] Read it online: https://
jorditorresbcn.github.io/supercomputing
-for-ai-book/
… Buy it: https://
amzn.to/4qS4pFz GitHub repo: https://
github.com/jorditorresBCN
/supercomputing-for-ai
… -

Open Source Data: Essential Missing Component for Large-Scale Training
By
–
More Open Source Data. The main missing ingredient for large scale training.
-

Overview of Loss Functions in Machine Learning
By
–
Machine Learning loss functions #infographic Loss Functions in ML Explained: https://
datacamp.com/tutorial/loss-
function-in-machine-learning
… Comprehensive Review of Loss Functions in Deep Learning: https://
arxiv.org/pdf/2504.04242
v1
…
————————
#AI #DataScience #DataScientist #Mathematics -
Full motion transformer trained in 3 days on 128GPUs at 10000x speed
By
–
This full motion transformer was trained in 3 days on 128GPU at 10.000x faster than wall clock speed.
— Linus ✦ Ekenstam (@LinusEkenstam) 25 février 2026
in english: this AI model controls the motion of the robot.
It supports, text to command, remote teleportation and much more.
Amazing work by Jim Fan et al. 🫰 https://t.co/ynXhrNwu5iThis full motion transformer was trained in 3 days on 128GPU at 10.000x faster than wall clock speed. in english: this AI model controls the motion of the robot. It supports, text to command, remote teleportation and much more. Amazing work by Jim Fan et al.