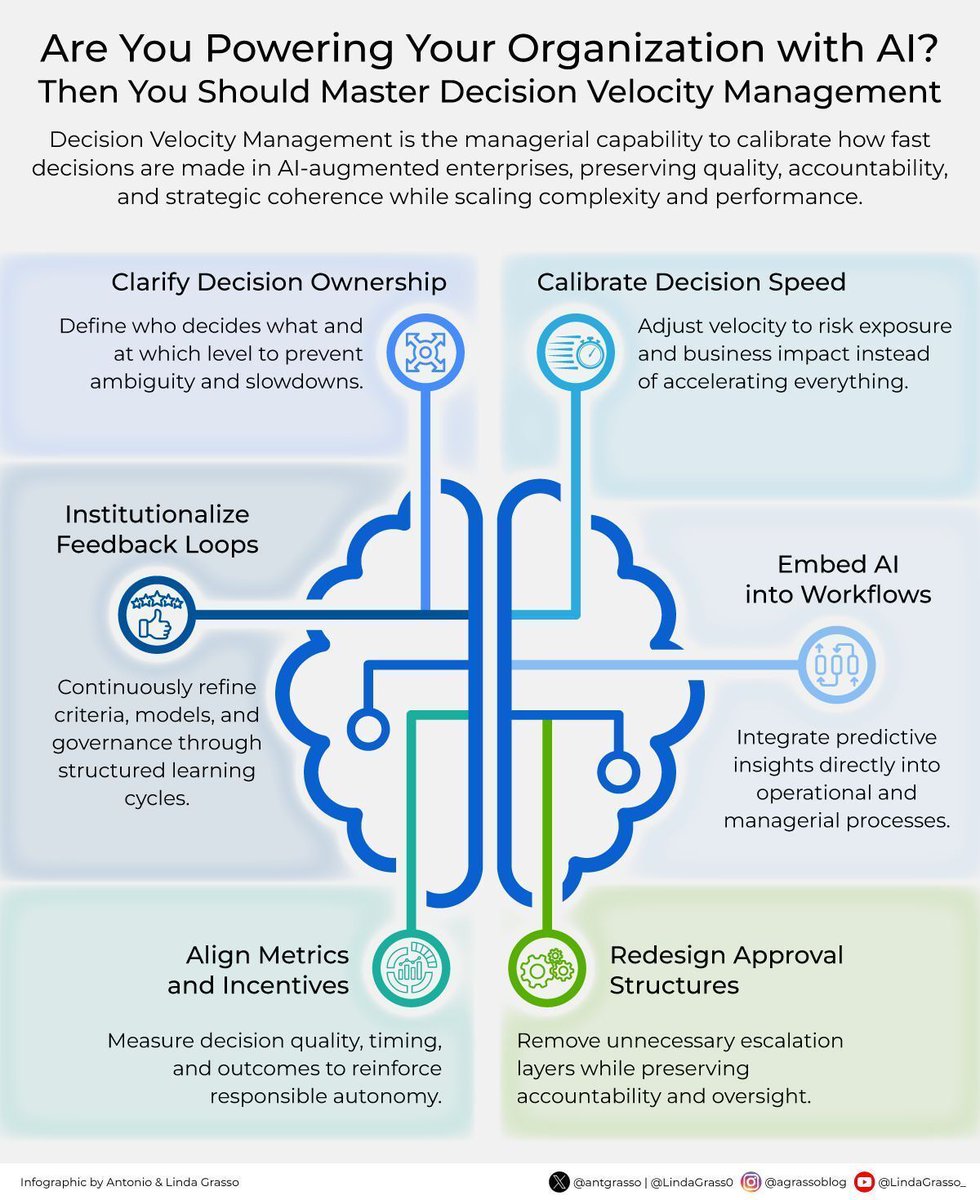
Are You Powering Your Organization with #AI? by @antgrasso #MachineLearning #ArtificialIntelligence #ML
→ View original post on X — @ronald_vanloon, 2026-04-08 08:45 UTC
By
–
Are You Powering Your Organization with #AI? by @antgrasso #MachineLearning #ArtificialIntelligence #ML
→ View original post on X — @ronald_vanloon, 2026-04-08 08:45 UTC
By
–
Steel Meets Shaolin: Humanoid #Robots Take on Kung Fu
— Ronald van Loon (@Ronald_vanLoon) 8 avril 2026
by @reborn_agi
#AI #MachineLearning #Robotics #ArtificialIntelligence #Innovation #ML #Technology pic.twitter.com/5zrLCPMTWi
Steel Meets Shaolin: Humanoid #Robots Take on Kung Fu by @reborn_agi #AI #MachineLearning #Robotics #ArtificialIntelligence #Innovation #ML #Technology
→ View original post on X — @ronald_vanloon, 2026-04-08 08:27 UTC
By
–
Great I still do not believe it is as good as capturing people manipulating the real world with their hands. How can simulated data figure out everything humans need to do? Self driving cars are same. Simulated data might get you 99% of the way there but the 1% is still a big
By
–
AI could understand and generate images from a single, efficient model!
— 机器之心 JIQIZHIXIN (@jiqizhixin) 8 avril 2026
Tsinghua University, Xi'an Jiaotong University, and University of Chinese Academy of Sciences present Cheers!
This unified multimodal model decouples fine image details from their core semantic meaning.… pic.twitter.com/s0MgsejA97
AI could understand and generate images from a single, efficient model! Tsinghua University, Xi'an Jiaotong University, and University of Chinese Academy of Sciences present Cheers! This unified multimodal model decouples fine image details from their core semantic meaning. This new architecture stabilizes AI's understanding while boosting image generation fidelity by selectively re-injecting those details. Cheers matches or outperforms advanced unified multimodal models in both visual understanding and generation. It notably beats Tar-1.5B on GenEval and MMBench, using only 20% of the training cost and achieving 4x token compression. Breakthrough efficiency! Cheers: Decoupling Patch Details from Semantic Representations Enables Unified Multimodal Comprehension and Generation Project: github.com/AI9Stars/Cheers Model: huggingface.co/ai9stars/Chee… Paper: arxiv.org/abs/2603.12793 Our report: mp.weixin.qq.com/s/EK6cyCJz5… 📬 #PapersAccepted by Jiqizhixin
By
–
Still waiting for DeepSeek?
— 机器之心 JIQIZHIXIN (@jiqizhixin) 8 avril 2026
Here comes WideSeek-R1.
Researchers from Tsinghua University and Infinigence AI introduce "width scaling," an innovative lead-agent and subagent framework.
Instead of a single powerful AI working through a problem sequentially, WideSeek-R1… pic.twitter.com/OOb3Azq6G3
Still waiting for DeepSeek? Here comes WideSeek-R1. Researchers from Tsinghua University and Infinigence AI introduce "width scaling," an innovative lead-agent and subagent framework. Instead of a single powerful AI working through a problem sequentially, WideSeek-R1 orchestrates multiple smaller AIs to work in parallel. This system is trained with multi-agent reinforcement learning, allowing for scalable coordination and simultaneous execution using a shared large language model, but with each sub-agent having specialized tools and isolated contexts. WideSeek-R1-4B achieves an item F1 score of 40.0% on the WideSearch benchmark, a performance comparable to the much larger, single-agent DeepSeek-R1-671B. WideSeek-R1: Exploring Width Scaling for Broad Information Seeking via Multi-Agent Reinforcement Learning Paper: arxiv.org/abs/2602.04634 Project: wideseek-r1.github.io Our report: mp.weixin.qq.com/s/qgGe51Rcw… 📬 #PapersAccepted by Jiqizhixin
By
–
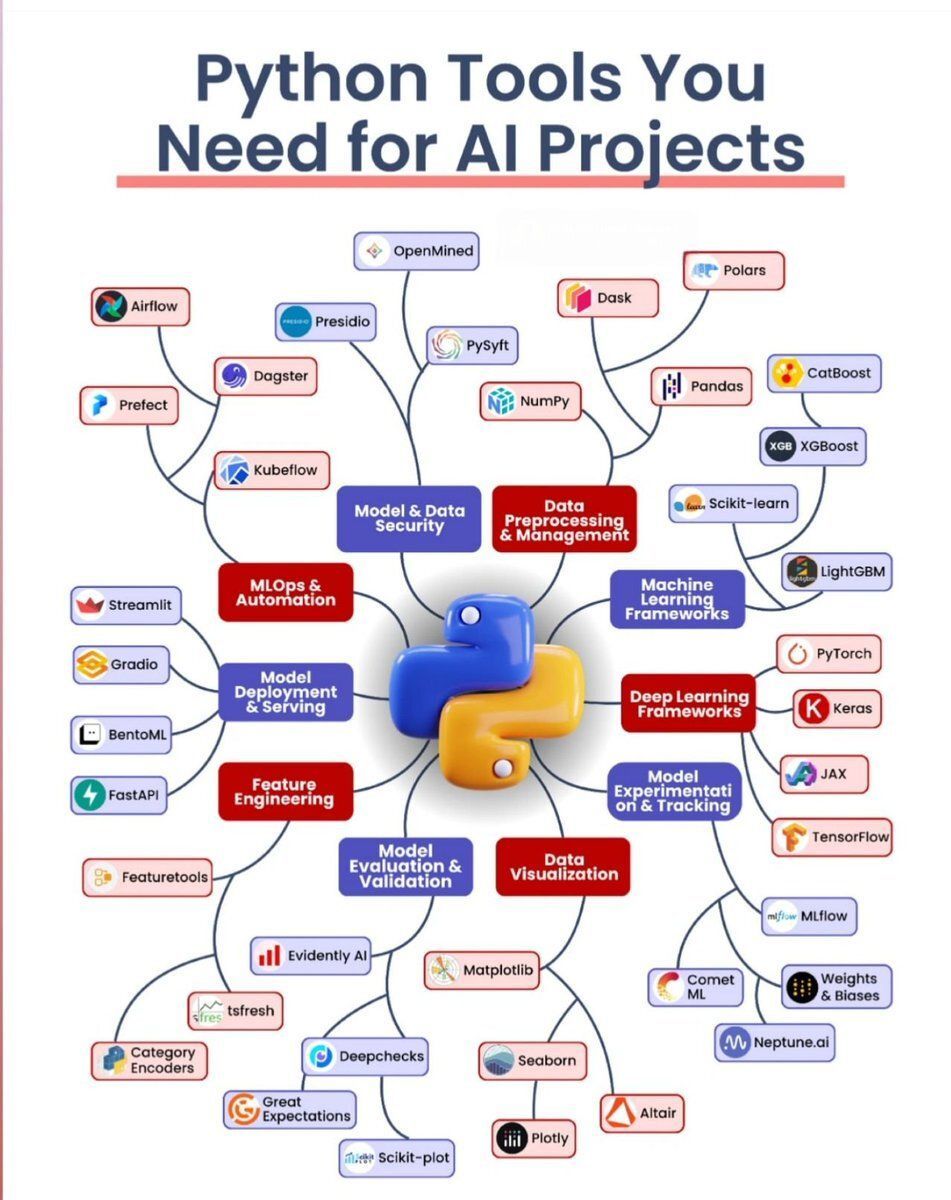
Python Tools You Need for #AI Projects by @Python_Dv #ArtificialIntelligence #MachineLearning #ML #MI
→ View original post on X — @ronald_vanloon, 2026-04-08 07:48 UTC
By
–
One of the reasons I haven't been doing a whole lot of videos here is I've been meeting with companies behind the scenes in the robotics world, particularly those who are collecting data (video data from glasses, from sensor arrays, and stuff like that). Eddie is one of the most impressive people I've met in this journey. He's 18 years old. He built 1,000 glasses and collected tens of thousands of hours of video data from workers who were in factories wearing his glasses. That's stunning entrepreneurship. I've been studying his competitors and him (having dinner with most of them for a lunch meeting), and Eddie is right on point. There's a big hunger for robot training data, and it's coming with a holodeck training data need too. They're really the same thing. In other words, there's a big fucking market, and people who are collecting data like Eddie are at the forefront. You're right on point for being excited about Eddie. He's real impressive. Roy (@im_roy_lee) eddy xu is the single founder i’d refer more highly than anyone in the entire world i truly don’t know enough about robotic training data to understand if his bet on egocentric video data is correct but boy is he swinging for the fucking fences genuine G — https://nitter.net/im_roy_lee/status/2041763727725232343#m
→ View original post on X — @scobleizer, 2026-04-08 07:19 UTC
By
–
Vero: An Open RL Recipe for General Visual Reasoning Paper: arxiv.org/abs/2604.04917v1
By
–
How do we build a visual AI that truly understands everything from charts to complex science?
— 机器之心 JIQIZHIXIN (@jiqizhixin) 8 avril 2026
Researchers at Princeton University present Vero.
Vero is a family of fully open-source vision-language models trained with a massive 600K sample dataset (Vero-600K) from 59 diverse… pic.twitter.com/nXMfBWfijM
How do we build a visual AI that truly understands everything from charts to complex science? Researchers at Princeton University present Vero. Vero is a family of fully open-source vision-language models trained with a massive 600K sample dataset (Vero-600K) from 59 diverse datasets, along with a novel reward system. This fully open recipe makes powerful visual reasoning accessible. Vero achieves SOTA performance for open-weight models, improving 3.7-5.5 points across 30 benchmarks on average. It even outperforms Qwen3-VL-8B-Thinking on 23 benchmarks without proprietary thinking data, excelling in spatial reasoning, STEM, chart interpretation, and more.