any references come to mind for 128k context on a 1Bish MoE? not sure i understand this area very well. i guess the primary ablation i would want is on context length quality vs width dimension…?
MACHINE LEARNING
-
Instructions to Download Local Code Models
By
–
3. Descarga un modelo para programar
— Nico (@nicos_ai) 22 avril 2026
Elige según la potencia de tu PC:
• Potente: qwen3-coder:30b
• Más modesto: qwen2.5-coder:7b o gemma:2b
Luego, en la terminal, descárgalo con:
ollama pull NOMBRE_DEL_MODELO pic.twitter.com/75wM6mu9KG3. Descarga un modelo para programar Elige según la potencia de tu PC:
• Potente: qwen3-coder:30b
• Más modesto: qwen2.5-coder:7b o gemma:2b Luego, en la terminal, descárgalo con:
ollama pull NOMBRE_DEL_MODELO -
MIT CSAIL explores efficient models for complex reasoning at ICLR
By
–
This sampling of MIT CSAIL papers at ICLR shows a common need for efficient models that can reason about complex, real-world problems. More compute helps, but the ways these machines "think" also need refinement. You can find more info about these projects on our website:
-

MathNet: World’s Largest Olympiad Math Problem Dataset
By
–
“MathNet” MIT, KAUST & HUMAIN have built the world's largest collection of Olympiad-level math problems. The dataset can help students prepare for competitions & revealed how AI models can improve at math problems, esp. ones w/visual reasoning: https://
bit.ly/4vBr2kl -
MIT Improves Reasoning Model Calibration Through Reinforcement Learning
By
–
“Reinforcement Learning w/Calibration Rewards” What makes top reasoning models overconfident? MIT found that in these models, RL rewards correct answers, not certainty. Training models to estimate confidence improved calibration while maintaining accuracy:
-
MIT CSAIL Advances Reliable AI Systems at ICLR Conference
By
–
This week, MIT CSAIL will join other top ML researchers at ICLR to tackle a shift in focus from more powerful AI to more reliable systems Our papers at the conference show how to potentially make AI models stronger critical thinkers, more honest, & better at math
-
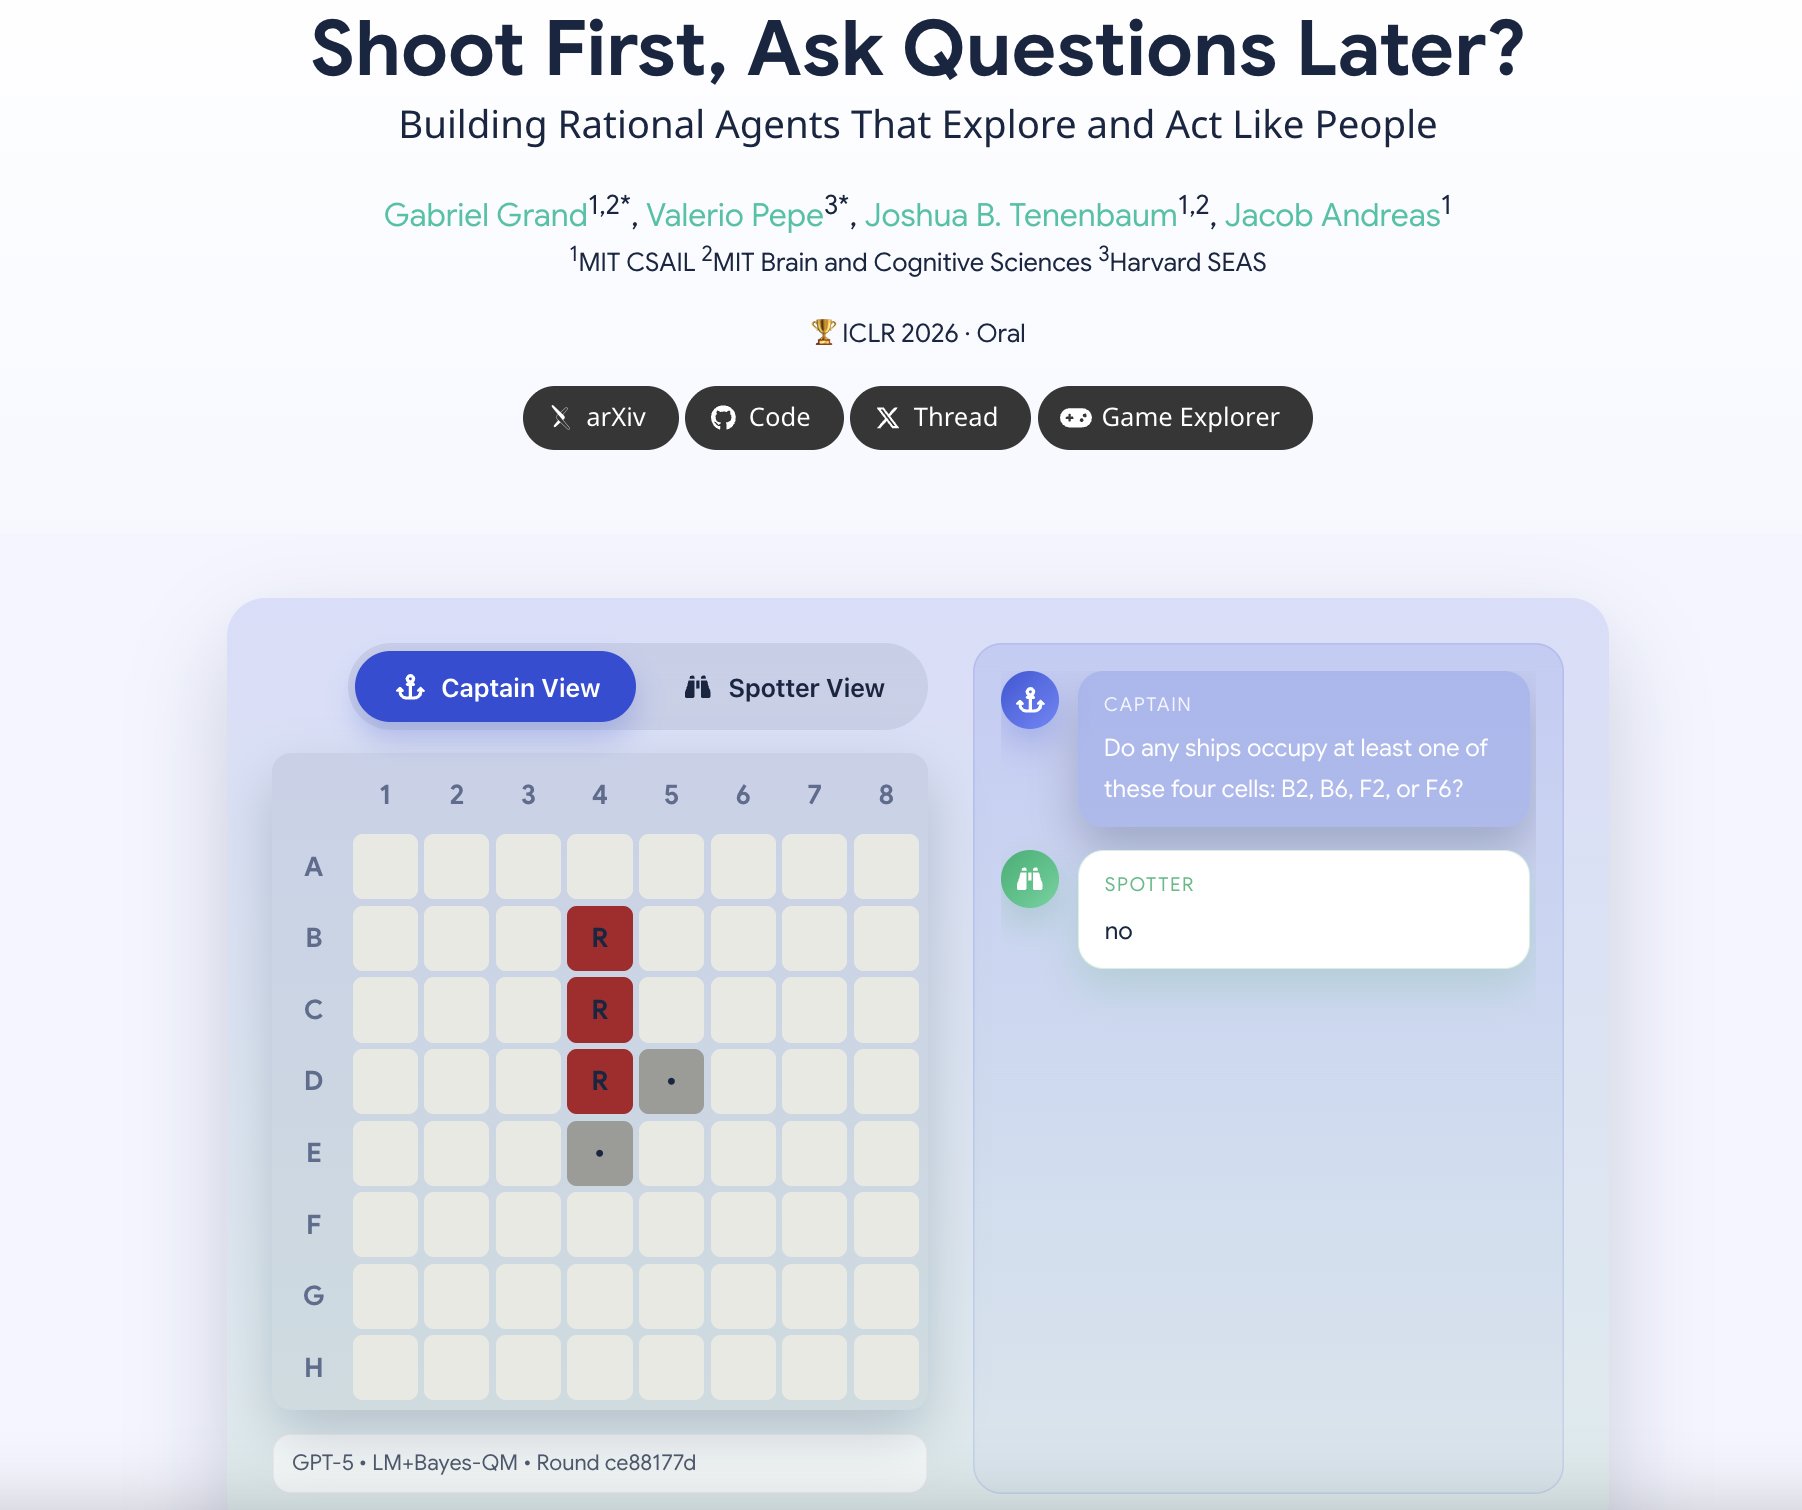
MIT Harvard Study AI Agents Critical Thinking Battleship
By
–
“Collaborative Battleship” MIT & Harvard developed a collaborative version of Battleship to see if AI agents are as good at asking questions as answering them. They found that many LMs struggle w/critical thinking, but Monte Carlo inference strategies can help even tiny
-

Position Encoding: How Transformers Understand Data Order
By
–
Position Encoding: How Transformers Understand Order in Data
— Satya Mallick (@LearnOpenCV) 22 avril 2026
In this episode of Artificial Intelligence: Papers and Concepts, we explore Position Encoding, a fundamental concept that enables transformer models to understand the order of information. Since transformers process… pic.twitter.com/FS8RcTE7DtPosition Encoding: How Transformers Understand Order in Data In this episode of Artificial Intelligence: Papers and Concepts, we explore Position Encoding, a fundamental concept that enables transformer models to understand the order of information. Since transformers process
-

Claude Code, Codex, Cursor: Comparing AI Model Sizes
By
–
Currently: – Claude Code is 4x bigger than Codex
– Codex is 2x bigger than Cursor
– Antigravity is almost as big as Cursor (but probably just because all Googlers use it? ) We'll add tagging for other agents asap. (Source: one data point from the @huggingface Hub team. Your -
New AI News Aggregation Platform Launched for Agents
By
–
This is why I started https://
alignednews.com/ai — as I was watching 40,000 posts a day in real time on X Pro I saw that I mostly was missing the deeper stuff. AI papers. Discussions of models. Videos. Even what events are coming up. This will help me help my agents find the